
Overview
Compute, storage, databases, networking, and IAM. Same jobs on AWS, GCP, and Azure, with different product names.
On this page8 sections
The idea
A menu with 200 items
Open the AWS, GCP (Google Cloud) or Azure console for the first time and you see more than 200 products. It feels like you must learn all of them.
- Full catalog, 200+ products
- Keep only what data work needs
- 5 kinds of product
You do not. Almost every data pipeline uses the same five kinds of product, and every provider sells all five.
Five jobs cover nearly every pipeline. A new product name is just one of those jobs with a brand on it.
Words you will see in this lesson
Six words. They come back all through the track.
| Word | What it means |
|---|---|
| Compute | A rented computer that runs your code |
| Object storage | A place to keep files in the cloud, organised in buckets |
| Database | A program that stores tables |
| Network (VPC) | A private space in the cloud where your machines can talk to each other |
| IAM | The rulebook for who is allowed to do what. Short for identity and access management |
| Warehouse | A database built to add up millions of rows quickly, for reports |
The five jobs
The five kinds of cloud product a data engineer uses.
| Job | What it does | In a pipeline |
|---|---|---|
| Compute | Runs programs on rented CPU and memory | Runs the cleanup script |
| Storage | Keeps files safely and cheaply | Holds raw CSV and JSON files |
| Database | Stores tables you can query with SQL | Answers the analyst's questions |
| Network | Decides which machines can reach which | Keeps the database off the open internet |
| IAM | Decides who may do what | Lets the script read one bucket and nothing else |
The buttons and brand names differ between GCP, AWS and Azure. The five jobs do not.
Why this exists
Every team needs the same five things
Anyone building a data platform needs something to run code, somewhere to keep files, a database to query, a safe network and a set of access rules.
Providers (AWS, GCP and Azure alike) sell them separately, so you pay for each only while you use it. A script that runs 20 minutes does not need to pay for a database that sits idle all night.
- Timer starts the job
- Rent a small machine for 20 minutes
- Write the result to storage
- Machine deleted, bill stops
When you meet a new product, ask which of the five jobs it does. Most of the time the answer is obvious from one line of its description.
Job posts use brand names for the same five jobs
One job post asks for Amazon S3 and Amazon Redshift. Another asks for Azure Blob Storage and Azure Synapse. A third asks for GCP Cloud Storage and BigQuery.
All three want the same thing: a place for files and a warehouse for reports.
Same job, three brand names.
| Job post says | The job | Google Cloud calls it | Azure calls it |
|---|---|---|---|
| Amazon S3 | File storage | Cloud Storage | Blob Storage |
| EC2 | Compute | Compute Engine | Virtual Machines |
| Amazon Redshift | Warehouse | BigQuery | Synapse Analytics |
| AWS IAM | Access rules | Cloud IAM | Entra ID with RBAC |
If you know one of them, you already know most of the other two. You only learn the new names.
Why the bill follows the job
Each job is billed in a different way. Compute is billed by the hour it runs. Storage is billed by the gigabyte per month. Network is billed by how much data leaves.
That is why a nightly job that runs 2 hours a day is cheap on rented compute, and why the same machine left on all month is not.
720 hours is 30 days of 24 hours. 60 hours is 30 nights of 2 hours.
| Plan | Hours billed per month | Relative cost |
|---|---|---|
| Machine on all month | 720 | Highest |
| Machine on 2 hours a night | 60 | About one twelfth of the above |
Picture this
One nightly job, five jobs working together
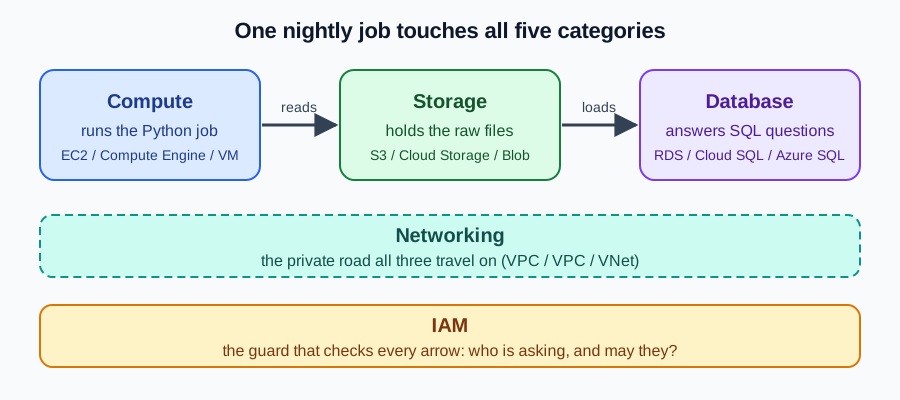
Read it left to right. Compute reads raw files from storage and writes results into a database. The network is the private road between them, and IAM checks permission at every step.
One row per job, one column per provider.
| Job | AWS | Google Cloud | Azure |
|---|---|---|---|
| Compute | EC2 | Compute Engine | Virtual Machines |
| Storage | S3 | Cloud Storage | Blob Storage |
| Database | RDS | Cloud SQL | Azure SQL |
| Network | VPC | VPC | VNet |
| IAM | IAM | IAM | Entra ID + RBAC |
Three ways to rent compute
Compute comes in three shapes. Pick by how long the job runs.
Machine, container, function.
| Shape | Examples | Use it for | Time limit |
|---|---|---|---|
| Virtual machine | EC2, Compute Engine | Long jobs that need your own setup | None, runs until you stop it |
| Container service | Cloud Run, ECS | The same job packed so it runs anywhere | Depends on the service |
| Function | Lambda, Cloud Functions | Small tasks, like reacting to a new file | AWS Lambda stops at 15 minutes |
A function on GCP, AWS or Azure that has been idle takes a moment to start the first time it is called. That delay is called a cold start.
Row databases and column databases
Databases come in two kinds, depending on how they lay data out on disk.
A row store keeps each record together. A column store keeps each column together.
GCP Cloud SQL and Azure SQL are row stores, good for an app that saves one order at a time. BigQuery, Synapse and Redshift are column stores, good for reports.
Network and IAM both have to say yes
To reach a bucket, a machine needs a network route and permission. Missing either one fails, but the failure looks different.
A slow failure usually means network. A fast 403 usually means IAM.
| Network route | IAM permission | What you see |
|---|---|---|
| Missing | Granted | The request hangs, then times out |
| Open | Missing | Access denied (403) straight away |
| Open | Granted | It works |
The network decides whether you can reach the door. IAM decides whether the door opens.
Who looks after what
Providers sell the same thing at three levels. The higher the level, the less you look after.
More provider work means less operations work for you.
| Level | The provider looks after | You look after | Example |
|---|---|---|---|
| IaaS (infrastructure) | Buildings and hardware | The operating system, software and code | EC2, Compute Engine |
| PaaS (platform) | Hardware and operating system | Your settings, jobs and tables | EMR, Dataproc |
| SaaS (software) | Nearly everything | Your data and your queries | BigQuery, Snowflake |
If you only need daily SQL reports, renting a bare machine and installing Spark yourself is a lot of extra work. A warehouse service gives you the result with far less to look after.
A small example
Looking up product names in Python
A dict inside a dict can hold the table above. The first key is the job and the second key is the provider.
Predict: what will the second line print?
SERVICES = {
    "compute": {"aws": "EC2", "gcp": "Compute Engine", "azure": "Virtual Machines"},
    "storage": {"aws": "S3", "gcp": "Cloud Storage", "azure": "Blob Storage"},
    "database": {"aws": "RDS", "gcp": "Cloud SQL", "azure": "Azure SQL"},
    "network": {"aws": "VPC", "gcp": "VPC", "azure": "VNet"},
    "iam": {"aws": "IAM", "gcp": "IAM", "azure": "Entra ID + RBAC"},
}

print(SERVICES["compute"]["gcp"])
print([SERVICES["compute"][cloud] for cloud in ("aws", "gcp", "azure")])Compute Engine ['EC2', 'Compute Engine', 'Virtual Machines']
The first line looks up one name. The second line collects the compute product from all three providers.
From a product name back to its job
Sometimes you meet a name and need to know which job it does. The loop below checks each job's products until it finds a match.
Predict: what does it return for S3, VNet and Lambda?
def category_of(product):
    for category, names in SERVICES.items():
        if product in names.values():
            return category
    return None

print(category_of("S3"))
print(category_of("VNet"))
print(category_of("Lambda"))storage network None
Lambda gives None because the small table has no function product in it. Lambda is compute, but it is not in our five-row table.
When a post asks for S3, Blob Storage or Cloud Storage, read it as file storage. The brand changes, the job does not.
Counting what a team needs
A team usually runs several pipelines, and each needs a different mix of the five jobs.
PIPELINES = [
    {"name": "orders-nightly", "needs": ["compute", "storage", "database"]},
    {"name": "clickstream-stream", "needs": ["compute", "storage", "network"]},
    {"name": "finance-report", "needs": ["compute", "database", "iam"]},
]

def count_by_job(pipelines):
    counts = {}
    for pipeline in pipelines:
        for job in pipeline["needs"]:
            counts[job] = counts.get(job, 0) + 1
    return counts

print(count_by_job(PIPELINES)){'compute': 3, 'storage': 2, 'database': 2, 'network': 1, 'iam': 1}
Compute is in all three pipelines, which is normal. Something always has to run the code.
counts.get(job, 0) means: use the saved count, or 0 if this job has not been seen yet. It avoids an error the first time a job appears.
Finding pipelines that use storage
def needs_service(pipeline, category):
    return category in pipeline["needs"]

print("Pipelines needing storage:")
for p in PIPELINES:
    if needs_service(p, "storage"):
print("-", p["name"])Pipelines needing storage: - orders-nightly - clickstream-stream
A team asks this question before changing a storage rule: which pipelines will it affect?
Watch the five jobs work together
Raw events land in a bucket (AWS S3, Azure Blob Storage or GCP Cloud Storage).
- Raw events
- Object storage
A timer starts a machine inside a private network (VPC).
- Timer
- Machine in VPC
IAM checks that the machine's identity may read that bucket.
- IAM check
- Access granted
The machine cleans the data and loads a table in the warehouse.
- Cleaning
- Warehouse table
Four things to remember:
- Every provider sells compute, storage, database, network and IAM.
- Pick compute by run time: functions (Lambda, GCP Cloud Functions) for short tasks, machines and containers for long ones.
- Row databases suit an app saving one order. Column databases suit reports over millions of rows.
- Reaching protected data needs both a network route and an IAM permission.
Common beginner questions
Which provider should I learn first?
The one you will actually use. If you have no preference, this track uses GCP for worked examples and names the AWS and Azure equivalent beside it.
Why are there more than five products then?
Each job has many flavours. Compute alone has machines, containers and functions. They all still sit under the same five headings.
Is IAM really something I rent?
Not in the usual sense, and it costs almost nothing. But every other service asks it for permission first, so it matters more than its price suggests. A later lesson goes deep on it.
What comes next
Next, Data lakes versus warehouses looks at where data lands: cheap raw files, or tidy SQL tables, and why teams use both.
Practice
Do the exercise with the SERVICES dict from the sample. A team lists 3 jobs and the kind of service each needs. Build result with the AWS product name for each job, in order, and print it.
Going further: keep compute near the data
Cloud services are billed in separate meters: storing, computing, and moving data. Moving data out of a region or out of the provider is often the surprise on the bill. The practical rule is to run compute in the same region as the data. The numbers below are illustrative, not a price list.
Assume moving data between regions costs 0.02 per GB. A job reads 5 TB a day. Predict the yearly cost of reading across regions, and compare it with moving the job to the data.
GB_PER_TB = 1000
PRICE_PER_GB = 0.02            # illustrative number

daily_gb = 5 * GB_PER_TB
yearly_cost = daily_gb * PRICE_PER_GB * 365
print("read across regions:", round(yearly_cost), "per year")
print("read in the same region: transfer charge = 0")read across regions: 36500 per year read in the same region: transfer charge = 0
Reading 5 TB a day across regions costs about 36,500 a year in transfer alone, before any compute. Placing the job in the data's region removes that line. The same logic explains why a queue, a database and a function that talk constantly belong in one region.
| Meter | What you pay for | How to keep it small |
|---|---|---|
| Storage | GB kept per month | Compress, expire old data, use cheaper tiers for cold data |
| Compute | Machine time | Turn it off when idle, size it to the job |
| Data transfer | GB leaving a region or the cloud | Keep compute and data together, send results not raw data |
| Requests | Number of reads and writes | Avoid millions of tiny files |
Try a new scenario
A dashboard in another region queries a warehouse for 200 GB of raw rows every hour. What two changes reduce the cost and the delay?
Work it out, then open the answer
Move the heavy work to the data: aggregate inside the warehouse so only a small summary crosses the region, and cache that summary so the dashboard does not repeat the query every hour when the data has not changed. Sending raw rows to be summarised far away pays for transfer and slows the dashboard at once.
What is serverless?
You run code or queries without managing machines. The provider starts capacity when needed and charges by use. Servers still exist, but you do not size, patch or keep them running.
Close the lesson and explain it
Without scrolling up, explain why data transfer between regions is an easy cost to miss, and how you avoid it.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.