
Overview
A run is green or red, the log says why, and an alert tells a person without making them look. Here you only count the failures.
On this page8 sections
Goal
Triage under morning pressure
Your pipeline runs at 2 AM. At 8 AM someone asks if the dashboard is right. By the end of this lesson you can answer in minutes whether last night's run worked and know where to look first.
Pipeline monitoring turns morning panic into a predictable diagnostic checklist.
A single execution of a pipeline is a run. Every step inside it is a task that ends in a state, such as success or failed. The run turns red if a required task fails and green if they all finish.
From alert to resolution
A log captures text a task prints while working, including requests, file paths, and errors. An alert is an automated message that notifies engineers without requiring manual dashboard checks.
The order a person follows when an alert arrives.
The alert is only the trigger. Everything after it is a methodical triage procedure, taking you from symptom to root cause and final data verification.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Run | One attempt of the whole pipeline |
| Task | One step inside the pipeline |
| Log | The text a task writes while it runs |
| Alert | A message that tells a person something broke |
| Triage | Quickly deciding what to look at first |
| Retry | Running a failed task again |
Why this order
Checking overall run status first
Look at the overall colour before you read any log. A run can contain dozens of tasks, and one red square immediately shows which task needs attention.
Scanning logs from the top without checking task states wastes valuable triage time.
Opening raw server logs from the top without isolating the failed task can burn hours tracing irrelevant debug messages from tasks that finished cleanly.
Isolating the earliest failed task
Find the first red task, not the last. When extract fails, downstream tasks never start. They display states like upstream_failed or skipped, which are secondary consequences rather than root causes.
- extract_ordersFailed due to API timeout (root cause)
- load_ordersUpstream failed, never executed
- build_goldUpstream failed, never executed
The log you need belongs strictly to the earliest failure. Downstream tasks never ran and will contain no actionable error information.
Reading logs before retrying
Read the log before you trigger a manual re-run. If a task failed because of an invalid input schema or malformed JSON, retrying without a fix produces the exact same error.
| Failure cause | Immediate retry outcome | Correct remediation |
|---|---|---|
| Source API timeout | May succeed if transient | Verify API status then rerun |
| Bad schema format | Fails again immediately | Fix parser or upstream schema |
| Non-idempotent write | Duplicates partial records | Clear partial staging batch first |
A task that crashed halfway through writing may duplicate rows on a blind retry. The log indicates whether a clean retry is safe or if state cleanup is required first.
Data verification as the final step
Check the data last, because a green status only confirms that the worker completed its process. It says nothing about whether the computed numbers are accurate.
Green status proves code execution finished, not that warehouse values are correct.
A script that reads an empty file without raising an exception exits cleanly with status zero. Verifying row counts and date bounds catches silent data loss.
The checklist
The incident triage checklist
Follow this standard sequence whenever an alert notifies on-call engineers.
- Open the run list and note the colour of last night's run for the pipeline you own.
- If it is green, verify the delivery promise: did the gold table land before the deadline?
- If it is red, click into the run and find the earliest task that failed. Ignore tasks marked upstream_failed.
- Open that task's log. Read from the bottom up until you reach the first error line.
- Identify the cause: source down, bad input format, a code bug, or disk limits.
- Fix the cause, then re-run only the failed task and downstream dependencies.
- Confirm the data: check row count in the destination table, verify the latest date, and confirm nothing duplicated.
During a live morning issue, following an established procedure prevents panicked mistakes.
The order matters. Step 3 says to find the earliest failure because one broken task turns everything after it red, and those later tasks are only victims. Fixing a victim changes nothing. Step 7 matters because a pipeline that reruns can double-load rows, so you check the counts before you tell anyone it is fixed.
Visual recovery workflow
This visual flow illustrates the branch between a successful deadline check and a failure triage loop.
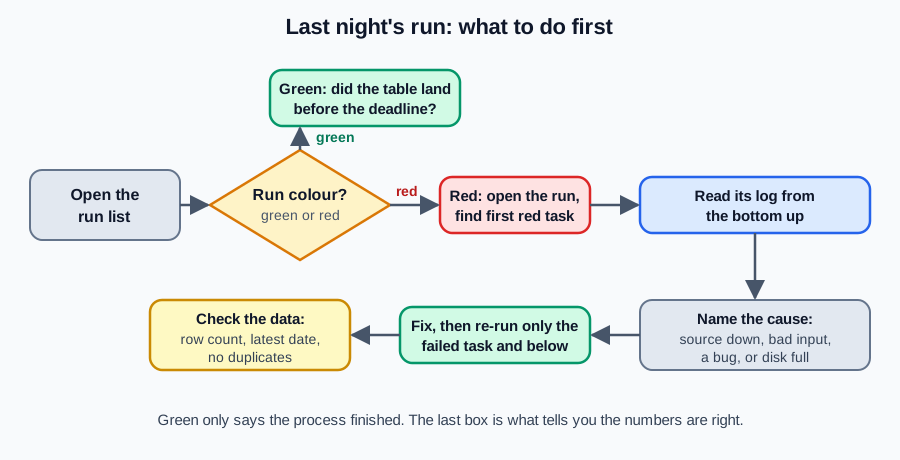
The green path verifies delivery timeliness, while the red path isolates the failure, inspects logs, applies fixes, and verifies data integrity.
Task states in orchestrators
Orchestrators track execution through distinct lifecycle states.
Airflow's task states, which most other orchestrators mirror in some form.
| State | What it means |
|---|---|
| success | The task finished without an error |
| failed | The task raised an error and has no retries left |
| up_for_retry | The task failed, and the scheduler will try again after a wait |
| upstream_failed | A prerequisite task failed, so this task never started |
| skipped | The task was deliberately not run |
| running | The task is currently executing |
Notice the distinction between failed and up_for_retry. A task in up_for_retry is waiting for its scheduled backoff timer before re-executing.
Service Level Agreements and alert hygiene
A Service Level Agreement (SLA) is the agreed business delivery deadline. For example, yesterday's gold reporting table must be ready by 08:00.
The promise is the right-most point. Everything before it is the pipeline's own time budget.
The actual measured duration is the Service Level Indicator (SLI). Alerts fire when the SLI breaches the agreed SLA threshold, even if tasks eventually finish green.
Filter alerts carefully. Notify engineers when runs fail or deadlines breach. Avoid paging for single transient retries that recover automatically, preventing notification fatigue.
Worked pass
Root cause isolation
Consider last night's run for a food-delivery pipeline with three sequential tasks. The overall run status is red.
Only the first task is the real failure. The other two never started.
| Task | State |
|---|---|
| extract_orders | failed |
| load_orders | upstream_failed |
| build_gold | upstream_failed |
Although 2 tasks report failure markers, extract_orders is the sole root cause. The downstream tasks simply never received permission to execute.
Reading logs from the bottom up
Following the checklist, open the extract_orders task and read its log output from the bottom up.
[02:03:11] extract_orders: GET /v2/orders?date=2026-10-05
[02:03:41] extract_orders: ReadTimeout after 30s
[02:03:41] extract_orders: task failed, 0 retries left
The error reveals a source API timeout. Once the upstream endpoint stabilizes, re-running extract_orders allows load_orders and build_gold to trigger automatically.
Counting failed runs in Python
In Python, you can inspect run records using list comprehensions to identify runs requiring attention.
RUNS = [
    {"id": 1, "ok": True},
    {"id": 2, "ok": False},
    {"id": 3, "ok": True},
    {"id": 4, "ok": False},
]

failed = [r["id"] for r in RUNS if not r["ok"]]
print(failed)
print(len(failed))
Predict which IDs appear in the failed list.
[2, 4]
2
The list comprehension filters records where ok is False. Monitoring dashboards apply the same filtering logic over historical database run records.
A green run says every task finished. If the source quietly sent an empty file, load happily writes zero rows and the run is still green. This is why you check a row count and a latest date after a fix.
Before you retry anything, write down the first error line from the log in the ticket or team chat. It takes 10 seconds, and when the same task fails again next month you will have searchable context.
Morning: At 2 AM the pipeline runs. At 8 AM someone asks if the dashboard is right.
- 02:00 run
- 08:00 question
Colour: Open the run and inspect the colour first. One red task among dozens shows where to start.
- red run
- first red task
Root cause: Find the first failed task, not the last. Downstream tasks show upstream_failed and contain no root cause error.
- extract fails
- load skipped
- gold skipped
Log: Read the log before you retry. A timeout may pass on a rerun, but a bad schema fails the same way again.
- timeout: retry
- schema: fix
Verify: After the rerun, check the data itself: how fresh is the newest row and is the row count normal? A green job can still hide stale data.
- freshness
- row count
Alerts: An alert is worth keeping only if it specifies who acts and what they do.
- owner
- action
Common beginner questions
Why look at the first failure and not the last?
Tasks after a failure never start, so they show errors that have nothing to do with their own code. The earliest red task is the one that encountered the root failure.
Can a run be green and still wrong?
Yes. Monitoring covers whether the process finished without error. Whether the data values are accurate is a separate question, covered in the data quality track.
Who receives the alert?
Whoever owns the pipeline. In practice that is an email list, a chat channel, or an on-call rotation chosen when the pipeline is configured. An alert without an owner gets ignored.
What comes next
You know how pipeline runs report status, how to triage logs, and how alerts notify teams. The next module begins with why orchestrators exist: examining the limitations of standalone scripts and exploring how directed acyclic graphs turn ordering rules into automated execution.
Practice
The exercise gives you 2 run records, one succeeded and one failed. Count the failed runs and print the total.
Going further: alert on what changed, not on what is odd
A pipeline can succeed and still deliver nothing useful. The checks that catch this compare today with what is normal: how fresh is the newest row, and is the row count close to usual? The risk is the opposite problem, too many alerts, which teaches people to ignore all of them.
Below, the last 7 days of row counts and two possible new values. Predict which new value should alert.
from statistics import mean, pstdev

last_week = [1000, 1040, 980, 1010, 1025, 990, 1015]
average = mean(last_week)
spread = pstdev(last_week)

def check(today):
    z = (today - average) / spread
    return "ALERT" if abs(z) > 3 else "ok"

print("average", round(average), "spread", round(spread, 1))
for today in [1060, 400]:
print(today, "->", check(today))average 1009 spread 19.0 1060 -> ok 400 -> ALERT
A count of 1,060 is higher than every recent day but inside the normal range, so it passes. 400 is far outside, so it alerts. A fixed rule such as 'alert below 900' would break the first week of a new product and every holiday. Comparing with the recent past adapts to the data.
| Check | Catches | Typical problem |
|---|---|---|
| Freshness (age of the newest row) | A job that stopped or a source that went quiet | Alerting on a slow Sunday when quiet is normal |
| Volume (row count versus recent) | Partial loads, doubled loads | A threshold that is too tight and fires daily |
| Values (nulls, ranges) | A broken upstream field | Too many checks nobody reads |
Alert fatigue is a design failure, not a people failure. Every alert should say who acts and what they do. An alert nobody acts on should be deleted or turned into a report.
Try a new scenario
A job runs hourly. It was green for 20 hours but the newest row in the table is 20 hours old. Which check would have caught it, and why did monitoring the job status alone miss it?
Work it out, then open the answer
A freshness check on the newest timestamp would have caught it. Job status only says the job ran without error. If the source stopped sending data, the job can succeed every hour while loading zero new rows. Alert on the data, not just on the process.
What is the difference between monitoring and alerting?
Monitoring records measurements such as freshness, row counts and run times so you can look at them. Alerting decides which measurements should interrupt a person. Collect many metrics, alert on few.
Close the lesson and explain it
Without scrolling up, explain why a green job can still hide stale data, and what makes an alert worth keeping.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.