
Overview
A DAG is tasks joined by one-way arrows with no loops. The runner works out a safe order from them.
On this page8 sections
The picture
A ShopKart pipeline in Bengaluru has 3 steps: extract, load, and transform. Written down in a plain script or function calls, nothing forces transform to wait for load. If extract stalls or load fails halfway, transform can start anyway on an empty table.
Drawing the steps as boxes and arrows turns that sequence into rules the machine can validate and enforce.
Boxes and arrows as execution rules
An arrow means "must finish before".
Each box represents a discrete task, and each arrow defines an execution rule. Extract must finish before load starts, and load must finish before transform starts.
Drawing pipelines as graphs turns vague procedural instructions into rules that machines can validate and enforce.
Directed and acyclic graphs
The graph is a DAG, short for directed acyclic graph. Directed means every edge has a direction from prerequisite to dependent task.
In an acyclic graph, no task waits on itself, directly or through other tasks.
Acyclic means you cannot follow edges and return to a task you already visited. A graph is a set of nodes joined by directed lines.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| DAG | Tasks drawn as boxes with arrows and no loops |
| Node | One box in the graph, which is one task |
| Edge | An arrow showing which task comes first |
| Dependency | A task that must finish before another starts |
| Cycle | A loop of arrows that can never finish |
| Indegree | How many arrows point into a task |
Why this shape
Concurrent branches on a graph
A flat sequential list assumes every step depends strictly on the task immediately preceding it. In real platforms, extract tasks can run concurrently.
Nothing connects the two extract boxes, so the scheduler is free to run them together.
The extract boxes share no connecting edge, so the scheduler runs them simultaneously. The join node waits for both extractions to complete before beginning.
Isolating failure recovery
Graph edges tell the runner where to resume when failures happen. If load fails, you retry only load and downstream transforms without re-pulling raw orders.
| Execution model | How failure recovers | Blast radius |
|---|---|---|
| Single flat script | Re-executes entire script from line 1 | High: redundant API calls and duplicate writes |
| DAG orchestrator | Retries only failed node and downstream dependents | Low: upstream nodes preserve earned success status |
Isolating failure recovery saves warehouse compute and avoids duplicate side effects on external services.
Why circular dependencies deadlock
If task A waits for task B, and task B waits for task A, neither task can ever start. Because cycles cause permanent deadlocks, orchestrators reject them during static DAG parsing.
A real-life version: you cannot get a job without experience, and you cannot get experience without a job. Nobody can take the first step.
A DAG is short for directed acyclic graph, and acyclic simply means there is no such loop. The scheduler checks this when it reads your file, so you see the error at once and not at 2 a.m.
Calling three functions in a row in main() works until you need to retry only the middle one, or run two of them at once. Write the dependencies as edges and the scheduler can do both.
Tracing an overnight task failure
See the arrows first, then a timeout at 02:14. Predict which task the scheduler clicks to next before it moves.
Walk the boxes
Nodes, edges, and dependencies
Each box in a DAG represents a node or task, and each directed arrow represents an edge.
| Term | Meaning | Example |
|---|---|---|
| Node | A task in the pipeline | join |
| Edge | A must-finish-before rule | extract_orders to join |
| Indegree | Number of arrows coming in | join has 2 |
| Topological order | A safe order to run everything | extract_customers, extract_orders, join, report |
| Cycle | A loop of waiting tasks, which is not allowed | A waits for B, B waits for A |
Tasks preceding an arrow are upstream dependencies, while tasks following an arrow are downstream dependents.
Using indegree to find ready tasks
The number of directed arrows entering a node is its indegree. The join has indegree 2. The two extracts have indegree 0, meaning no prerequisites block them.
EDGES = {
    "extract_orders": ["join"],
    "extract_customers": ["join"],
    "join": ["report"],
    "report": [],
}

def compute_indegree(edges):
    indegree = {task: 0 for task in edges}
    for task, downstreams in edges.items():
        for d in downstreams:
            indegree[d] += 1
    return indegree

print(compute_indegree(EDGES)){'extract_orders': 0, 'extract_customers': 0, 'join': 2, 'report': 1}Any task with indegree 0 can execute immediately. When a task finishes, the scheduler decrements the indegree of all downstream tasks by 1.
Kahn's algorithm step by step
A topological order lists tasks so every task appears only after all of its upstream dependencies finish.
- Make a list of the tasks whose indegree is 0. Here that is extract_customers and extract_orders.
- Take one off the list, add it to the order, and lower the indegree of every task it points at by 1.
- Any task whose indegree just hit 0 joins the list.
- Repeat until the list is empty.
Order produced: extract_customers, extract_orders, join, report. The two extracts could swap and the order would still be valid.
| Step | Take | Indegrees afterwards | Now free |
|---|---|---|---|
| start | none | orders 0, customers 0, join 2, report 1 | extract_customers, extract_orders |
| 1 | extract_customers | join 1, report 1 | extract_orders |
| 2 | extract_orders | join 0, report 1 | join |
| 3 | join | report 0 | report |
| 4 | report | all 0 | nothing left |
If a cycle exists, some tasks never reach indegree 0. The scheduler detects this condition when the output list contains fewer tasks than the DAG.
Resolving multi-branch graphs
This larger graph demonstrates how the algorithm navigates multiple parallel paths and convergence points.
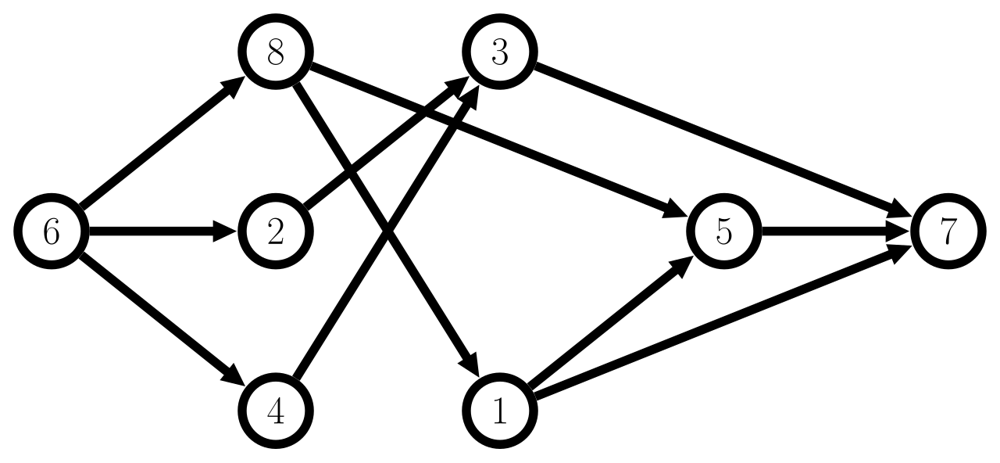
Node 6 starts with indegree 0. Completing node 6 frees nodes 8, 2, and 4. As intermediate branches finish, dependent nodes unlock until final node 7 completes.
Trigger rules for conditional paths
By default, every Airflow task uses trigger_rule='all_success'. Real pipelines also require branching, cleanup, and incident alerting.
A plain example: a pipeline loads three regional files, then builds one report. With the default rule, one failed region stops the report. With a different rule, the report can still run on the regions that worked, and a final cleanup task can run no matter what happened.
- all_success (default): Task executes only when all upstream parents completed successfully.
- all_failed: Task executes only when all upstream parents failed. Useful for triggering emergency rollback jobs or incident management alerts.
- one_success: Task executes as soon as at least one parent succeeds. Does not wait for all parents to finish.
- none_failed: Task executes if all parents succeeded or were skipped. Ideal for branch merging where alternate branches are intentionally skipped.
- none_failed_min_one_success: Similar to none_failed, but requires at least one parent to have actually succeeded (not all skipped).
- all_done: Task executes regardless of upstream status once all parents finish running (whether successful, failed, or skipped). This is the standard rule for teardown tasks, such as terminating an ephemeral EMR or Databricks cluster.
Trigger rules govern when a task wakes up, allowing conditional paths like cleanup hooks that run even if upstream steps crash.
Testing DAGs in continuous integration
Automated CI tests prevent syntax errors, broken imports, and accidental dependency cycles from deploying to production.
# tests/test_dags.py - Fast static validation with DagBag
from airflow.models import DagBag

def test_dagbag_no_import_errors():
    dagbag = DagBag(dag_folder="dags/", include_examples=False)
    # Asserts that all DAG files parse cleanly with zero Python syntax or import errors
    assert len(dagbag.import_errors) == 0, f"DAG import errors: {dagbag.import_errors}"

def test_dag_has_no_cycles():
    dagbag = DagBag(dag_folder="dags/", include_examples=False)
    for dag_id, dag in dagbag.dags.items():
        # Verifies that every graph is strictly acyclic
        assert len(dag.cycle_check()) == 0, f"Cycle detected in {dag_id}"
Airflow also provides dag.test(), allowing you to execute an entire DAG sequentially in your local terminal without launching full scheduler infrastructure.
A matching example
Checking which tasks start immediately
Consider a checkout reporting pipeline with orders, payments, and a daily revenue calculation. Orders and payments can run concurrently, while revenue waits for both.
EDGES = {
    "extract_orders": ["revenue"],
    "extract_payments": ["revenue"],
    "revenue": [],
}

indegree = {task: 0 for task in EDGES}
for downstreams in EDGES.values():
    for d in downstreams:
        indegree[d] += 1

ready = [t for t, n in indegree.items() if n == 0]
print("can start now:", ready)can start now: ['extract_orders', 'extract_payments']
Extracting orders and payments begins in parallel because both have indegree 0. Daily revenue waits until both feeds finish.
Every scheduler question here (what can start now, what is free after this finishes, is there a loop) is answered by one number per task: how many unfinished tasks it still waits for.
From the SQL track you know a join needs both tables to exist. In a DAG that is a task with two arrows coming in.
Dependency resolution summary
DAGs provide predictable execution ordering, enabling safe parallelization and isolated failure remediation.
Model individual pipeline steps as distinct graph nodes.
- graph
- nodes
Declare directed edges to enforce prerequisite completion rules.
- dependencies
- directed edges
Identify tasks with indegree zero to initiate parallel execution.
- scheduling
- indegree zero
Use cycle checks during CI to prevent infinite waiting deadlocks.
- validation
- cycle detection
- Represent tasks as nodes and dependencies as directed edges.
- Run independent tasks with indegree zero concurrently across available workers.
- Decrement downstream indegrees as upstream nodes complete successfully.
- Enforce acyclic properties to prevent deadlocks and infinite loops.
- Use specialized trigger rules for conditional branching and resource cleanup.
Common beginner questions
Can 2 tasks really run at the same time?
Yes, whenever there's no path of arrows between them. extract_orders and extract_customers above have none, so both can start at once as long as the machine has room.
Is there only one correct order?
No. Any order that respects every arrow is correct. The two extracts can swap and both orders are fine.
What happens if I add a cycle by accident?
The orchestrator refuses to load the DAG and shows a cycle error. It never reaches a run.
What comes next
A DAG gives you the boxes and arrows. The next lesson names the kinds of boxes Airflow gives you to fill them: operators that do work, sensors that wait, and XCom for passing a small value between tasks.
Practice
The exercise gives you the chain extract, load, transform as a dict and asks for a function, topo_order, that returns the tasks in a safe order. The numbered steps in the walkthrough above describe the method.
Going further: which chain decides the total time?
A DAG lets independent tasks run at the same time, so the total runtime is not the sum of all tasks. It is the length of the longest chain of dependent tasks, called the critical path. Speeding up a task that is not on that path does nothing for the finish time.
Tasks and minutes: extract 10, clean_a 5, clean_b 20, join 8, report 2. clean_a and clean_b both wait for extract, join waits for both, report waits for join. Predict the total time.
minutes = {"extract": 10, "clean_a": 5, "clean_b": 20, "join": 8, "report": 2}
needs = {"extract": [], "clean_a": ["extract"], "clean_b": ["extract"],
         "join": ["clean_a", "clean_b"], "report": ["join"]}

finish = {}
for task in ["extract", "clean_a", "clean_b", "join", "report"]:     # dependency order
    start = max((finish[d] for d in needs[task]), default=0)
    finish[task] = start + minutes[task]

print("finish times:", finish)
print("total:", max(finish.values()), "minutes; if run one after another:", sum(minutes.values()))finish times: {'extract': 10, 'clean_a': 15, 'clean_b': 30, 'join': 38, 'report': 40}
total: 40 minutes; if run one after another: 45The total is 40 minutes, not 45: clean_a runs alongside clean_b and finishes early. The slow chain is extract, clean_b, join, report (10 + 20 + 8 + 2). Making clean_a twice as fast saves nothing. Making clean_b faster saves time until it stops being the slowest branch.
This shape, where one task fans out into several and they join again, is called a diamond. It is common and safe, as long as the join waits for every branch.
Try a new scenario
You halve clean_b to 10 minutes. What is the new total, and which branch is now the critical one?
Work it out, then open the answer
The new total is 30 minutes. clean_b (10) is still longer than clean_a (5), so it remains the critical branch, and the saving is 10 minutes. Halving it again would stop helping once it drops below clean_a's 5 minutes.
What does acyclic mean, and why does it matter?
Acyclic means no task can eventually depend on itself. If A waited for B and B waited for A, neither could start. The scheduler checks for cycles when it loads the DAG and refuses a graph that has one.
Close the lesson and explain it
Without scrolling up, explain what the critical path is and why speeding up other tasks does not shorten the run.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.