
Overview
Airflow's names for "do this", "wait until that exists" and "hand a small value to the next task". No Airflow runs here.
On this page8 sections
The idea
A ShopKart DAG has arrows between tasks, but arrows only specify execution order. They do not say what each task is supposed to do.
One task must execute Python code, another must wait for an S3 file to land, and a third needs a small piece of metadata from the step before it.
Airflow gives each kind of job a clear name: operators execute actions, sensors wait for external conditions, and XCom passes tiny metadata values between tasks.
3 core primitives
A DAG tells the scheduler what depends on what, but does not define what each box does. Some boxes execute code, some wait for external files, and some pass small facts.
Airflow separates pipeline coordination into operators that act, sensors that wait, and XCom for communication.
Apache Airflow is an open-source orchestrator where pipelines are defined as DAGs in Python code. It translates declared graph structures into scheduled machine execution.
Instead of writing manual cron scripts that hope preceding steps succeeded, with Airflow's default trigger rule, a task runs only after all of its upstream tasks succeed.
Division of duties
Airflow organizes task responsibilities into three distinct primitives.
| Primitive | Operational duty | Example in production |
|---|---|---|
| Operator | Executes an action or code | PythonOperator running transform logic, BashOperator, SQLExecuteQueryOperator |
| Sensor | Waits for a condition to become true | FileSensor checking for S3 object landing, ExternalTaskSensor |
| XCom | Shares tiny metadata messages between tasks | Passing partition dates, row counts, or table paths |
Airflow was created at Airbnb in 2014 and became an Apache top-level project. Its three primitives form the foundational vocabulary of modern data orchestration.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Airflow | A popular tool for scheduling and watching pipelines |
| Operator | A ready-made kind of task, like run SQL |
| Sensor | A task that waits for something to appear |
| XCom | A small message one task leaves for the next |
| Scheduler | The part that decides what runs when |
| Worker | The machine process that actually runs the task |
Why this exists
Waiting for data to arrive
Data does not always arrive on a strict schedule. An external partner might deliver a daily CSV file at 2:20 AM on Monday and 3:05 AM on Tuesday.
- 02:00 Schedule firesDAG run initiates
- FileSensor waitsPokes storage bucket periodically
- File arrives at 02:45Sensor condition satisfied
- Operator loads dataReads newly landed file safely
If the loading task started blindly at 2:00 AM, it would process an empty directory or read stale records from yesterday. A sensor waits until data is physically present.
Why XCom is strictly for small metadata
Tasks execute in isolated processes across different worker machines, so they cannot share in-memory Python variables. When a task finishes, Airflow serializes its return value into the metadata database.
| Permitted in XCom | Forbidden in XCom | Consequence of violation |
|---|---|---|
| Row counts, table paths, date bounds, execution IDs | Pandas DataFrames, PyArrow tables, raw CSV/JSON blobs | Bloats PostgreSQL metadata DB, degrades the webserver, can destabilise the scheduler |
A filename, a row count or a date is fine. A whole dataframe is not. Put big data in the lake or the warehouse and pass its path through XCom instead.
Because XCom writes directly to the metadata database, storing large datasets strains database memory and slows the scheduler down for all DAGs on the cluster.
Picture this
Visualizing sensor and operator flow
This diagram visualizes how the three primitives coordinate during a production warehouse ingestion run.
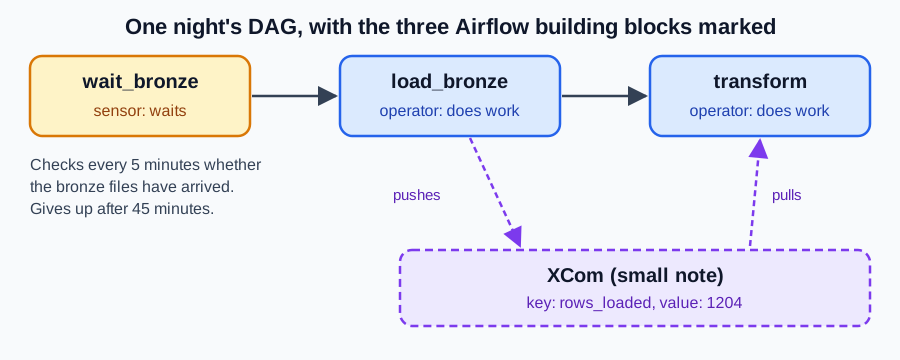
Follow the solid arrows: wait_bronze waits for input, load_bronze ingests raw rows, and transform builds final aggregations. The dashed line shows XCom carrying the row count between operators.
Airflow architecture components
A production Airflow deployment distributes work across several specialized server components.
The scheduler determines which tasks are ready, workers execute task code, and the central metadata database synchronizes state across the cluster.
Roles of scheduler, webserver, and workers
Airflow splits responsibilities across the scheduler, webserver, executors, and the metadata database.
| Component | Primary role | Production consideration |
|---|---|---|
| Scheduler | Reparses DAGs and queues ready tasks | Must be kept fast; avoid top-level network calls |
| Webserver | Flask/React UI for logs, DAG views, and triggers | Read-only access to metadata database |
| Executor & Workers | Runs operator code across compute nodes | Celery or Kubernetes executors for distributed scaling |
| Metadata Database | Single source of truth for task states and XCom | PostgreSQL or MySQL backend; needs regular cleanup |
LocalExecutor runs tasks as local child processes for development, while CeleryExecutor and KubernetesExecutor distribute workloads across large multi-node worker fleets.
Dynamic task mapping at runtime
Before dynamic task mapping was added in Airflow 2.3, every task had to be statically declared in Python. If your pipeline processed 50 customer tenants, you had to loop and define 50 static tasks.
@task
def get_active_tenants():
    return ["tenant_a", "tenant_b", "tenant_c"]

@task
def sync_tenant_data(tenant_id: str):
    print(f"Syncing partition for {tenant_id}")

# Dynamically maps sync_tenant_data across all returned tenants
tenants = get_active_tenants()
sync_tenant_data.expand(tenant_id=tenants)
Airflow 2.3 introduced Dynamic Task Mapping using expand(). An upstream task queries an API or database, and downstream tasks spawn dynamically at runtime based on the list length.
This mapping behavior mirrors a distributed map operation, executing instances concurrently across cluster worker nodes without requiring code changes as workloads grow.
Protecting credentials with connections
Hardcoding database passwords, API keys, or cloud access tokens inside DAG code is a severe security vulnerability.
- DAG calls conn_idRequests 'postgres_warehouse'
- Secrets BackendVault or AWS Secrets Manager
- Dynamic credential fetchRetrieved on demand at task runtime
- Log maskingSensitive values masked as '***'
Airflow stores credentials under Connection IDs. In production cloud deployments, Airflow integrates with external secrets backends like AWS Secrets Manager or HashiCorp Vault to fetch secrets dynamically.
Why top-level DAG code must stay fast
The Airflow scheduler continuously reparses every Python file in the dags folder every 30 seconds to detect schedule changes.
Any code outside of operator execution functions runs repeatedly inside the scheduler process.
Placing database queries or external API calls at the top level causes the scheduler to pause and run network requests on every parse cycle, causing CPU starvation and scheduling delays.
Timeouts, SLAs, and failure callbacks
Production tasks must never hang indefinitely on stalled database locks or frozen network sockets.
| Safety setting | Configuration syntax | Operational benefit |
|---|---|---|
| Task timeout | execution_timeout=timedelta(hours=2) | Kills stalled tasks automatically and triggers retry |
| SLA deadline | sla=timedelta(hours=4), sla_miss_callback=pager | Alerts engineers when pipeline breaches time budget |
| Failure callback | on_failure_callback=send_slack_alert | Pings on-call channel immediately when task fails |
Similarly, configure failure callbacks and SLA misses to immediately inform on-call engineers when core reporting pipelines breach delivery agreements.
A small example
Filtering sensors in Python
To model task types in Python, each task dictionary includes a kind attribute declaring whether it acts as a sensor or an operator.
The 3 tasks from the picture.
| id | kind | extra |
|---|---|---|
| wait_bronze | sensor | gives up after 45 minutes |
| load_bronze | operator | pushes a note |
| transform | operator | pulls load_bronze's note |
TASKS = [
    {"id": "wait_bronze", "kind": "sensor", "timeout_min": 45},
    {"id": "load_bronze", "kind": "operator", "xcom_push": None},
    {"id": "transform", "kind": "operator", "xcom_pull": "load_bronze"},
]

def sensors(tasks):
    return [row["id"] for row in tasks if row["kind"] == "sensor"]

print(sensors(TASKS))['wait_bronze']
The list comprehension filters tasks where kind equals sensor, mirroring how the scheduler identifies polling tasks.
Exchanging metadata via simulated XCom
In Python, XCom behaves like a shared dictionary where producers push values and consumers pull them by key.
xcom = {}

def load_bronze():
    rows_loaded = 1204
    xcom["rows_loaded"] = rows_loaded

def transform():
    rows = xcom["rows_loaded"]
    if rows == 0:
        raise ValueError("load wrote zero rows")
    print("transforming", rows, "rows")

load_bronze()
transform()transforming 1204 rows
The load task writes its row count into the dictionary, and transform validates the count before executing warehouse calculations.
Mismatched XCom keys
A common production mistake occurs when the upstream task pushes under one key name, but the downstream task requests a different key.
xcom = {}

def load_bronze():
    rows_loaded = 1204
    xcom["row_count"] = rows_loaded

def transform():
    rows = xcom["rows_loaded"]
    if rows == 0:
        raise ValueError("load wrote zero rows")
    print("transforming", rows, "rows")

load_bronze()
transform()KeyError: 'rows_loaded'
The downstream task crashes with a KeyError. The upstream task worked perfectly; the error is entirely caused by mismatched key strings across files.
A generic key like "result" invites two unrelated tasks in the same DAG to push under the same name, each silently overwriting the other. Name the key after what it holds, like "orders_loaded", and the mismatch above becomes much harder to create by accident.
A complete Airflow DAG in Python
Here is how the complete sensor and operator sequence translates into declarative Airflow DAG syntax.
with DAG("orders_nightly", schedule="0 2 * * *", catchup=False) as dag:
    wait_bronze = FileSensor(
        task_id="wait_bronze",
        filepath="/data/bronze/orders/_SUCCESS",
        poke_interval=300,   # check every 5 minutes
        timeout=2700,        # give up after 45 minutes
    )
    load_bronze = PythonOperator(task_id="load_bronze", python_callable=load_fn)
    transform = PythonOperator(task_id="transform", python_callable=transform_fn)

    wait_bronze >> load_bronze >> transform
The schedule uses cron syntax, the sensor pins polling intervals, and the >> bitshift operators draw the directed graph edges.
Notice that tasks instantiate operators directly rather than calling functions. The orchestrator manages execution timing, failure retries, and worker assignment behind the scenes.
Poke mode versus reschedule mode
By default, sensors wait in poke mode, holding worker slots occupied while sleeping between checks.
| Sensor mode | Worker slot behavior | Best for |
|---|---|---|
| mode='poke' | Holds worker slot continuously during sleep intervals | Short waits under 2 minutes |
| mode='reschedule' | Releases worker slot back to pool between check intervals | Long waits over 5 minutes (prevents starvation) |
If 16 sensors wait on delayed partner files in poke mode, all worker slots lock up, starving independent pipelines. Using mode='reschedule' releases the slot between checks.
Without a timeout, a file that never arrives leaves the DAG stuck for days with no error, and you find out when someone asks where the report is.
Prefect calls them tasks, Dagster calls them ops, Temporal calls them activities. In all of them something does the work, something waits, and a small value gets passed along.
Task instance lifecycle states
Every task instance moves through predictable states as it runs. Most debugging starts by reading this state progression in the UI.
- noneInitial unqueued state
- scheduledPrerequisites satisfied
- queuedHanded to executor queue
- runningWorker executing code
- success / failedFinal state or up_for_retry
If execution finishes cleanly, the task turns green with success. If it raises an unhandled exception, it transitions to up_for_retry or failed.
Production pipeline discipline
Designing stable Airflow pipelines requires discipline across task granularity, sensor modes, and credential management.
Use mode='reschedule' on long-polling sensors to prevent worker slot starvation.
- sensors
- reschedule mode
Keep XCom restricted to tiny metadata strings and reference paths.
- xcom
- no dataframes
Keep top-level DAG code free of database queries and network calls.
- scheduler
- fast parsing
Store secrets in external vaults rather than hardcoding in DAG scripts.
- security
- secrets backend
- Use operators to perform compute work and sensors to poll for external prerequisites.
- Configure sensors with mode='reschedule' and explicit timeouts to prevent worker starvation.
- Limit XCom payloads to small metadata items and pass bulk datasets via warehouse tables.
- Keep top-level DAG code free of heavy database queries to protect scheduler responsiveness.
- Retrieve credentials dynamically through Connections and cloud secrets managers.
Common beginner questions
What's the difference between an operator and a sensor?
An operator does something and finishes. A sensor does nothing except check a condition again and again until it's true or its timeout runs out. Both are tasks and both sit in the DAG.
Why can't a task just hand a variable to the next one?
Tasks usually run in separate processes, sometimes on separate machines, so they don't share memory. XCom is the shared place for tiny values, and the lake or warehouse is the shared place for data.
Do Prefect, Dagster or Azure Data Factory have these?
They use other names, but the same 3 jobs exist: do work, wait for something, and pass a small value along.
What comes next
You now have the vocabulary: a clock, a graph, and three kinds of building block. The next module is about what happens when a task fails halfway: retries, and why re-running a task has to be safe.
Practice
The exercise gives you a list of task dicts and asks for a function that returns the ids of the sensors. Run it on the list and print the result.
Going deeper: what each task does when things go wrong
The lesson above separated operators (do work), sensors (wait) and XCom (small notes between tasks). The harder question is what Airflow does when a task fails or a file is late. This section follows a 4-task pipeline through a normal run and two failures.
Operator, task and task instance
A failure belongs to a task instance, not to the task.
| Word | Meaning | Example |
|---|---|---|
| Operator | A template for one kind of work | PythonOperator, a SQL operator, FileSensor |
| Task | An operator configured inside a DAG | extract = PythonOperator(task_id='extract', ...) |
| Task instance | One task for one DAG run, with its own state and retry count | extract for the 2026-09-01 data interval |
The pipeline
from datetime import datetime, timedelta
from airflow import DAG
from airflow.operators.python import PythonOperator
from airflow.sensors.filesystem import FileSensor
from airflow.utils.trigger_rule import TriggerRule

def extract():
    path = "s3://shop-lake/raw/orders/2026-09-01/part-0000.parquet"   # the data stays in the lake
    return {"path": path, "rows": 48210}                              # only this small note is stored

def load(ti):
    note = ti.xcom_pull(task_ids="extract")
    print("loading", note["path"], "expecting", note["rows"], "rows")

def alert():
    print("send a message to the on-call channel")

with DAG(
    "orders_nightly",
    start_date=datetime(2026, 9, 1),
    schedule="0 2 * * *",
    catchup=False,
    default_args={"retries": 1, "retry_delay": timedelta(minutes=5)},
) as dag:
    wait_file = FileSensor(task_id="wait_file", filepath="/data/orders.done",
                           mode="reschedule", poke_interval=300, timeout=60 * 60 * 3)
    extract_t = PythonOperator(task_id="extract", python_callable=extract)
    load_t = PythonOperator(task_id="load", python_callable=load)
    notify = PythonOperator(task_id="notify_failure", python_callable=alert,
                            trigger_rule=TriggerRule.ONE_FAILED)
    cleanup = PythonOperator(task_id="cleanup", python_callable=lambda: None,
                             trigger_rule=TriggerRule.ALL_DONE)

    wait_file >> extract_t >> load_t >> [notify, cleanup]
Read it as a story. The sensor waits for the done-marker without holding a worker slot (reschedule mode) and gives up after 3 hours. extract returns a small dictionary, which Airflow stores as an XCom. load reads that note and fetches the real data from the lake.
Every task may retry once after 5 minutes. notify_failure runs only if something upstream failed. cleanup runs whenever upstream finished, passed or failed.
Trigger rules decide who runs
| Rule | Runs when | Typical use |
|---|---|---|
| all_success (default) | Every upstream task succeeded | Normal pipeline steps |
| all_done | Every upstream task finished, in any state | Cleanup that must always happen |
| one_failed | At least one upstream failed | Alerting |
| none_failed | No upstream failed (skips are allowed) | Joining branches after an optional step |
Now two nights. In night A, extract fails once and succeeds on retry. In night B, extract fails on both attempts. Predict each task's final state before you open the output. This is a simplified model of the rules above, not Airflow's own code.
# A simplified model of how Airflow decides what to do with each task. Not Airflow's own code.
UPSTREAM = {"wait_file": [], "extract": ["wait_file"], "load": ["extract"],
            "notify_failure": ["load"], "cleanup": ["load"]}
RULE = {"notify_failure": "one_failed", "cleanup": "all_done"}      # everything else: all_success
FINISHED = {"success", "failed", "upstream_failed"}

def should_run(task, state):
    ups = [state[u] for u in UPSTREAM[task]]
    rule = RULE.get(task, "all_success")
    if rule == "all_success": return all(u == "success" for u in ups)
    if rule == "all_done":    return all(u in FINISHED for u in ups)
    if rule == "one_failed":  return any(u in ("failed", "upstream_failed") for u in ups)

def run_dag(extract_failures, retries):
    state = {}
    for task in UPSTREAM:                      # already in dependency order
        if not should_run(task, state):
            state[task] = "upstream_failed" if task not in RULE else "skipped"
            continue
        attempts = 0
        while True:
            attempts += 1
            if task == "extract" and attempts <= extract_failures:
                if attempts > retries: state[task] = "failed"; break
                continue                       # up_for_retry, try again
            state[task] = "success"; break
        if attempts > 1:
            print(f"  {task}: {state[task]} after {attempts} attempt(s)")
    return state

for failures in (1, 2):
    print(f"extract fails {failures} time(s), retries=1")
print(" ", run_dag(failures, retries=1))extract fails 1 time(s), retries=1
extract: success after 2 attempt(s)
{'wait_file': 'success', 'extract': 'success', 'load': 'success', 'notify_failure': 'skipped', 'cleanup': 'success'}
extract fails 2 time(s), retries=1
extract: failed after 2 attempt(s)
{'wait_file': 'success', 'extract': 'failed', 'load': 'upstream_failed', 'notify_failure': 'success', 'cleanup': 'success'}In night A the retry hides the failure: everything succeeds, and notify_failure is skipped because no upstream failed. In night B, extract is failed, load never starts and is marked upstream_failed, the alert fires, and cleanup still runs.
A skipped alert is not a bug; it is the trigger rule saying there was nothing to report.
XCom is a note, not storage
- XCom values live in Airflow's metadata database, the same database the scheduler needs. Large values slow it down for every DAG.
- A value is tied to one task instance of one run. Re-running that task replaces its note.
- Old values are removed by cleanup of the metadata database, so nothing you need long term should rely on XCom surviving.
- The pattern that scales: write data to the lake or warehouse, and pass only its path, row count or date through XCom, as the example does.
Which date is this run for?
With a daily schedule, a run is named after the interval of data it covers, not the moment it starts. In Airflow 2.x with a cron string, the run for the 2026-09-01 interval starts after that interval ends, at 02:00 on 2026-09-02.
Airflow 3 changed some defaults for cron schedules, so check your version. Either way, write tasks against data_interval_start and data_interval_end instead of calling now(), so a retry or a backfill processes the same day again.
A retry runs the whole task again. If extract appends rows to a table, the retry appends them twice. Make each task safe to run twice for the same interval: overwrite that day's partition, or use an upsert.
Try a new scenario
A DAG has 3 tasks in a line: download, transform, publish. download takes 15 minutes, retries 3 times, and returns the 800 MB file as its return value so that transform can read it. Find the problems and fix them.
Work it out, then open the answer
Returning 800 MB puts a huge value in the metadata database. Write the file to object storage and return its path. The retries are fine only if download is idempotent: if each attempt writes a new file name, make the name depend on the data interval so a retry overwrites the same file. Add a retry_delay so a failing remote system is not hit repeatedly, an execution_timeout so a stalled download cannot hold a slot forever, and an alert on failure.
A sensor is stuck for 2 hours. Is that a failure?
Not until its timeout. A sensor in poke mode that keeps waiting holds a worker slot, which can starve other tasks. Use reschedule mode for long waits, set a timeout, and decide whether a timeout should fail the run or skip it.
Close the lesson and explain it
Without scrolling up, explain why load can be upstream_failed even though load itself never ran, and what a trigger rule changes about that.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.