
Overview
Batch closes a time slice after it ends. Stream processes events as they land. The brief's SLA and lateness pick the clock.
On this page8 sections
The decision
You have the brief. Finance wants yesterday's revenue by 08:00. The ops team wants a map that updates within 5 seconds. Both read the same stream of order events. Do you build one pipeline or two, and what kind?
That is the batch versus stream choice. Batch processing waits until a slice of time is over, say all of yesterday, then runs one job over the whole slice.
Stream processing handles events continuously as they arrive, within seconds, without waiting for the day to end.
Batch waits for a slice to close, then works. Stream works while events are still coming in.
A stream reads from a queue, a holding area where producers drop events and consumers pick them up in order.
A batch job usually reads files or a dated table. The picture shows the practical difference: every batch run has an end, and a stream doesn't.
Two more words. A watermark is a stream's rule for when to stop waiting for late events: "nothing older than 10 minutes counts anymore, so close the window." A micro-batch is a batch job on a tiny slice, say 5 minutes, run over and over.
It sits between the two clocks, and we will come back to it.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Batch | Process a chunk of data on a schedule |
| Stream | Process each event as it arrives |
| Watermark | A stream's rule for when to stop waiting for late events |
| Micro-batch | A batch job run over and over on a tiny slice, say 5 minutes |
| Late data | An event that arrives long after it happened |
| Worker | One machine process doing the work |
What is at stake
The wrong clock fails in two ways. Pick stream when batch was enough and you pay for machines that run all day, plus extra work for duplicates and late events.
Pick batch when someone needed seconds and the reader just gets old data, which no tuning fixes.
Cost is the easiest to put numbers on. We use the ShopKart workload brief from [Requirements to numbers](/learn/system-design/design-req): about 46 MB/s at the peak, totaling 1 TB per day. The prices below are assumptions for illustration. A worker is one machine, at ₹20 per hour.
- Stream: one worker can handle about 6 MB/s (assumed). Peak is 46.3 MB/s, and 46.3 / 6 = 7.7, so you need 8 workers. They run around the clock, 24 x 30 = 720 hours a month each. That is 8 x 720 = 5,760 worker-hours, and 5,760 x ₹20 = ₹1,15,200 a month.
- Batch: a nightly job over 1 TB uses 20 workers for about 1.5 hours (assumed). That is 20 x 1.5 = 30 worker-hours a night, 30 x 30 = 900 a month, and 900 x ₹20 = ₹18,000 a month.
Assumed prices. The stream is sized for the peak hour but has to stay on all day, even at 04:00.
The always-on stream costs 1,15,200 / 18,000 = 6.4 times more here. It isn't careless. It has to be ready for the peak at every hour of the day, while the nightly job rents machines for 1.5 hours and hands them back.
Whether 6.4 times is worth paying depends on whether some reader truly needs the 5-second answer.
A truck leaves once a night, carries everything in one trip and sits in the garage the rest of the time. A pipe is always connected and always carrying a little. The truck is cheaper per item. Only the pipe can deliver at 3 in the afternoon.
Option A vs Option B
Here is a table you can use on any brief. For each row, say which side is true for your reader. If every row leans the same way you're done. If they split, you probably need two paths.
Read 1 row at a time and note which column your brief points to.
| If this is true | Lean batch | Lean stream |
|---|---|---|
| Source is a nightly or hourly file | Yes. Read the file on a schedule. | Only if you convert every file into messages first |
| Reader's deadline is a morning report | Yes. A job with some spare time before the deadline. | Overkill |
| Reader's deadline is seconds | Cannot meet it | Yes |
| Late data shows up hours after the event | Wait for it, or rerun the day | Needs a watermark and a plan for stragglers |
| You must count each order exactly once | Easier. You can rerun the whole slice. | Harder. Queues can deliver the same event twice. |
| Events must stay in order per customer | Sort inside the job | Partition the queue by customer id |
The same logic as a flowchart. Start at the top with one reader, because each reader gets their own answer, and follow the arrows.
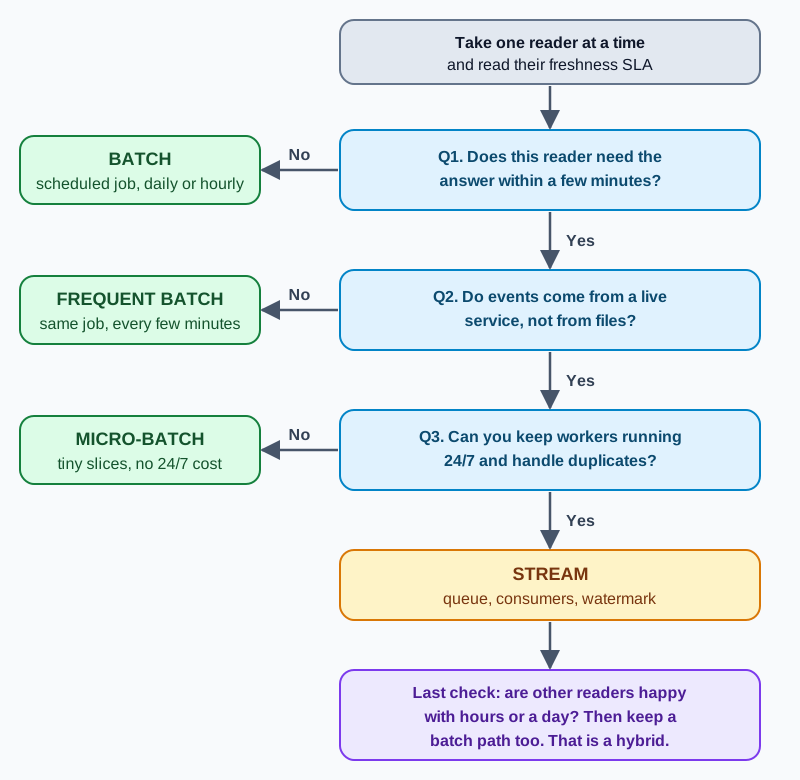
Count how many exits lead to some kind of batch. Stream is the last stop, reached only when a reader needs minutes or less, the source is live, and you can run workers 24/7 and handle duplicates.
The purple box at the bottom is a reminder to check your other readers, since one stream reader rarely turns everything into a stream.
When not to pick each
- Do not pick batch when a reader's deadline is shorter than your job's runtime plus its start delay. No schedule can fix that.
- Do not pick stream because the job description mentions it. If every source is a file and every deadline is in hours, a queue adds cost and nothing else.
- Do not call a job a stream if it just runs every hour. That is a nightly job with more moving parts.
You have practised both halves already. Schedulers, reruns of one date and loads that don't insert twice are batch skills from the orchestration track.
Queues, partitions and messages that may arrive more than once are stream skills from the streaming track. This lesson just decides which a brief needs.
Watch the two clocks
Read the brief in the trace below and guess batch or stream before you step through it, then see whether the trace agrees.
A worked comparison
Back to the food delivery app. Three readers, and we decide the clock for each. Every number comes from the workload brief established in [Requirements to numbers](/learn/system-design/design-req).
Finance: yesterday by 08:00
Late data can arrive up to 6 hours after the event, so a day that ends at 00:00 is not really finished until 06:00. Our nightly job takes about 1.5 hours. Compare two start times.
Starting at 06:00 is the first time that waits for all late data and still meets the deadline.
| Job starts | Finishes | Misses | Spare time before 08:00 |
|---|---|---|---|
| 02:00 | 03:30 | Anything that arrives from 02:00 to 06:00 | 4.5 hours |
| 06:00 | 07:30 | Nothing within the 6 hour bound | 30 minutes |
Starting early looks safer because it leaves more spare time, but it quietly misses late events, and the finance number then shifts when the next night's job merges them in. Starting at 06:00 leaves a 30 minute buffer and counts everything.
The rule: start time must be at or after the moment late data stops, and start time plus run time must be at or before the deadline. If both can't hold, the brief contradicts itself, and you go back to the reader before building anything.
def run_batch_pipeline(execution_date: str):
    """Process one closed day, then stop."""
    raw = read_files(f"bronze/events/dt={execution_date}/")
    silver = dedupe(raw, key="event_id")
    silver.merge_into("silver.events", key="event_id")
    gold = silver.group_by("dt").sum("order_value")
    gold.overwrite_partition("gold.fct_daily_gmv", dt=execution_date)

# the scheduler calls this at 06:00 with execution_date = yesterday
The job rewrites exactly one date, so rerunning it after a fix gives the same answer instead of a double count. That is why finance can trust the batch path.
Ops map: within 5 seconds
No schedule gets a 5 second answer from a job that takes 1.5 hours. Even a job run every minute would add a minute of delay and leave you managing 1,440 runs a day.
This reader needs a stream, and the stream needs one extra rule because queues can deliver an event twice: remember which events you have seen.
def stream_consumer():
    """Read events as they arrive and keep the map current."""
    seen = set()
    for message in queue.poll(topic="delivery_pings"):
        event = parse(message.value)
        if event.event_id in seen:
            continue            # duplicate delivery, skip it
        seen.add(event.event_id)
        update_map(event.delivery_id, event.lat, event.lon)
In production the set of seen ids would live in a store that expires old entries, but the idea is the same. That bookkeeping is part of the stream's price, next to the always-on workers from the cost sum.
Vendor file: hourly gzip
The vendor drops one compressed file an hour, so the data can't update faster than hourly however you read it. A batch job that runs when the file lands fits. Turning each file into queue messages would add a queue that no reader benefits from.
Three readers, three decisions, with the reason written next to each.
| Reader | Deadline | Clock | Why |
|---|---|---|---|
| Finance | 08:00 next day | Batch, starts 06:00 | Waits for the 6 hour lateness bound, 1.5 h run, 30 min spare |
| Ops map | 5 seconds | Stream | No schedule can meet 5 seconds |
| Vendor hourly file | Hours | Batch, hourly | Source arrives hourly, nothing faster is possible |
Two readers need the batch clock and one needs the stream clock, so this brief ends in a hybrid. Both paths start from the same events and both carry the order id, so finance and the map can be checked against each other.
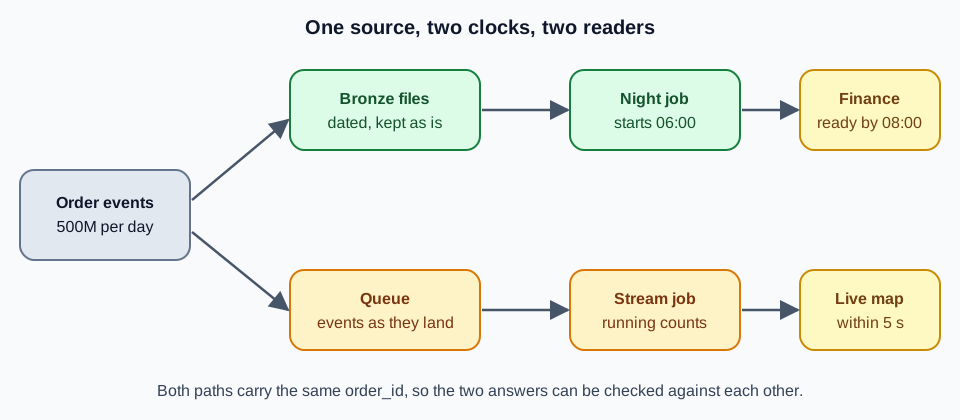
The top lane is the cheap, exact one. The bottom lane costs more and is allowed to be a little approximate. Draw both lanes only when two readers really need different clocks, because every extra lane is something you have to run and fix.
This two-lane shape is old enough to have a name. It is often called the Lambda architecture, and here is how it is usually drawn.
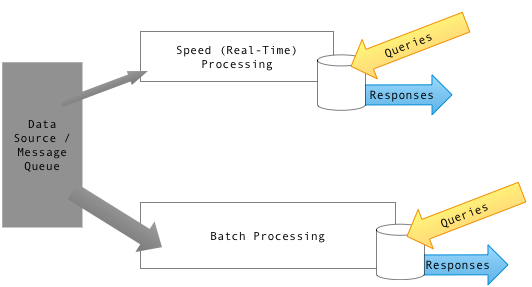
Compare it with our hybrid. Same source on the left, two lanes, and a store at the end of each.
The cost people complain about with this design is the one we just named: you now run two systems, and the two answers have to agree.
A job that runs every hour is still a batch job, just with more moving parts than a nightly one. Add a queue when a named reader is paying for the freshness, and not before.
Beginners often start the nightly job just after midnight because the day has ended. If events can arrive 6 hours late, the day has ended but its data hasn't. Check the lateness bound before you set the clock.
Don't pick one clock for the whole company. Ask each reader how old their answer may be, and let the readers who disagree get two paths.
Common beginner questions
Can I start with batch and add a stream later?
Yes, and it is usually the cheaper order. Land raw events in dated files first. When one reader proves they need seconds, add a queue for that reader alone. The batch path keeps working the whole time.
Where does micro-batch fit?
A batch job on tiny slices, say every 5 minutes. You get answers within minutes without the always-on machines of a true stream. It suits a reader who says "real time" but is happy with data 5 or 10 minutes old.
What happens if the data gets 10 times bigger?
A batch job needs more workers or runs longer, so check that start time plus run time still beats the deadline. A stream needs more partitions and more consumers. Redo the brief's arithmetic with the new numbers, because about 460 MB/s calls for a very different plan from about 46 MB/s.
Brief: Finance wants yesterday's revenue by 08:00. Ops wants a map that updates within 5 seconds. Same event data, two very different deadlines.
- finance: 08:00
- ops: 5 seconds
Choices: Batch waits for a slice to close and runs one job. Stream works on events as they arrive. Micro-batch runs a tiny batch again and again.
- batch
- micro-batch
- stream
Cost: Cost check: a nightly batch costs about 18,000 rupees a month. An always-on stream costs about 1,15,200, which is 6.4 times more, because it must be ready for the peak hour all day.
- 18,000
- 1,15,200
- 6.4x
Finance: Finance gets a batch job at 06:00, after the 6 hour lateness bound, so it counts everything and still finishes by 07:30. It rewrites one date, so reruns are safe.
- 06:00 start
- 07:30 done
- rerun safe
Ops map: Ops needs a stream. No schedule gives 5 seconds. The consumer skips duplicate event ids because queues can deliver a message twice.
- queue
- dedupe by id
- update map
Design: The answer to one brief is often two paths, each justified by its reader's deadline.
- batch path
- stream path
What comes next
The next lesson sizes the front door for 500 million events a day: where events land and how a queue or a file prefix absorbs the 23,148 per second peak. Which front door you need depends on the batch or stream choice you just made.
Practice
Take the workload brief you calculated in [Requirements to numbers](/learn/system-design/design-req). For each reader, answer the 3 questions in the flowchart and write down the clock you picked.
For any batch reader, check that start time is after your lateness bound and start plus run time is before the deadline. Then say which readers force a second path.
Going further: what happens when the logic changes
Choosing batch or stream is not only about speed. It is also about what you do when you discover your logic was wrong. A batch pipeline over files recomputes the past by simply running again. A stream keeps running totals, so a fix needs the original events to be replayed through the corrected logic.
Below, a running revenue total counts cancelled orders by mistake. The fix is to exclude them. Predict the corrected total, and what you need to get it.
events = [
    {"id": 1, "status": "paid", "amount": 100},
    {"id": 2, "status": "cancelled", "amount": 40},
    {"id": 3, "status": "paid", "amount": 60},
    {"id": 4, "status": "cancelled", "amount": 25},
]

def old_logic(total, e):
    return total + e["amount"]                     # bug: counts cancelled orders

def new_logic(total, e):
    return total + e["amount"] if e["status"] == "paid" else total

old_total = new_total = 0
for e in events:
    old_total = old_logic(old_total, e)
    new_total = new_logic(new_total, e)

print("running total with the bug:", old_total)
print("replayed with the fix :", new_total)running total with the bug: 225 replayed with the fix : 160
The buggy total is 225 and the corrected total is 160. You can only get the correct one if you still have the events. If the stream kept only the running total and the raw events expired, the history cannot be corrected, and the old number is permanently wrong.
That is why a replayable log (or raw files kept in the lake) is the safety net of a streaming design.
| Batch over stored data | Streaming with running state | |
|---|---|---|
| Fix a logic bug | Run the job again over the stored data | Replay the retained events, or rebuild from raw files |
| Freshness | As often as you schedule it | Seconds to minutes |
| Complexity | Lower | Higher: state, late data, restarts |
| Needs to keep | The input data | The input data as well, for replay |
Many designs use both: a stream for fresh approximate numbers, and a batch job that recomputes the exact numbers from stored data, which also corrects any drift in the stream. This is the idea behind hybrid designs, and its main cost is maintaining two code paths that must agree.
Try a new scenario
A dashboard needs revenue within 5 minutes, but finance needs exactly correct end-of-day numbers. Which parts do you stream, which do you batch, and how do you avoid the two disagreeing?
Work it out, then open the answer
Stream a simple running total for the 5-minute dashboard and label it provisional. Run a batch job each night over the stored events to produce the final numbers for finance, and let the batch result replace the streamed one for that day. To keep the two from drifting apart, share the business rules (what counts as revenue) in one place, and reconcile the stream's total with the batch's total every day, alerting on a gap.
Interview: what is a lambda architecture?
It runs a batch path for exact, complete results and a streaming path for fast approximate results, and combines them. It gives both freshness and correctness, at the cost of two code paths that must stay in agreement.
Close the lesson and explain it
Without scrolling up, explain why replay matters for a streaming design, and what you keep so that a logic bug can be repaired.
Finished this lesson?
Mark it as read when you could explain it to someone else.