
Overview
Volume, SLA, late data, and who reads gold decide the architecture. Name them all before you draw a box.
On this page8 sections
Goal
Someone gives you a paragraph like this: "We get a lot of order events, finance wants the numbers in the morning, and the ops team wants a live map." It sounds like a brief.
It isn't one yet, because you can't check a design against "a lot" or "the morning".
This lesson turns a paragraph like that into a short list of numbers.
By the end you can write a one-page brief and do the arithmetic on paper: events per second, terabytes per day, what it costs to keep them, and the time each reader needs their answer by.
That page is the design brief, the numbers and deadlines a pipeline has to meet. You write it before you draw a single box, and every later choice (batch or stream, how many workers, where to store things) gets checked against it.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Checklist | Five questions to ask before you design anything |
| Latency | How long the answer takes to arrive |
| Freshness | How recent the data is when someone reads it |
| Volume | How much data there is |
| Late data | Rows that arrive after their day |
| Cost | What the system costs to run |
Why this order
Here is what happens without one. A team hears "real time" in a meeting, picks a streaming stack because it sounds modern, and builds it.
3 months in, someone notices the only source is a file a vendor drops once a night and the only reader is a finance report opened at 09:00.
The streaming system works fine and does nothing useful, and it costs about 6 times what a nightly job would (the arithmetic is in the next lesson).
So ask the boring questions first, in a fixed order, because each answer depends on the one before.
- Who reads the result, and what do they do with it? Every deadline belongs to a person or a system, so you need the readers before you can talk about deadlines.
- How fresh must it be for each reader? That is the deadline, and it can differ a lot between readers.
- How late can the data itself arrive? You can only judge lateness against a deadline, so this comes after step 2.
- How much data is it, per day and per second? Size matters last because it only tells you how big the pipes need to be, not what kind of pipe.
- What does it cost? A rough price check on the numbers from step 4 tells you if the idea is sane before anyone writes code.
Step 2 can't swap with step 1, because "fresh by when?" has no answer until you know who is asking. Step 4 can't go first either.
500 million events a day sounds scary, but if the only reader looks once a day it just means a big nightly job.
The checklist
Ask them left to right. Each answer narrows the next one.
That figure is the whole checklist in one line. We will run it on one made-up company, a food delivery app that records 500 million order and delivery events per day, and 3 groups care about that data.
1. Who reads it
A consumer is anyone or anything that reads what your pipeline produces: a person with a dashboard, a report, another system. For each one, write down what they do with the data and how wrong it is allowed to be.
Three readers of the same events, with three different needs.
| Consumer | What they do with it | Row they expect | How wrong is OK? |
|---|---|---|---|
| Finance | Reconcile revenue with the bank | 1 row per order | Not at all. Every order counted once. |
| Ops team | Watch live deliveries on a map | 1 row per active delivery | A few seconds old is fine, one missed ping is fine |
| Growth | Funnel from visit to purchase | 1 row per session | Small errors are fine, trends matter |
The third column is what the SQL track called grain, what 1 row of the output stands for. Finance counts orders and growth counts sessions, so they can't share one table. The brief has to say which is which.
2. How fresh
2 words get mixed up here. Latency is how long 1 event takes to travel from the moment it happens to the moment it shows up in the output.
Freshness is the age of the newest data in the table at the moment someone reads it. An SLA (service level agreement) is the promise you write down about it, for example "the finance table is complete for yesterday by 08:00".
A delivery event at 18:00 reaches the ops map within seconds, but the finance table only has to be ready 14 hours later, at 08:00 the next morning.
Read it left to right. The ops map is the fast reader and the finance table is the slow one. Neither is wrong. They are two promises about the same event, and the brief keeps them apart.
3. How late can data arrive
An event has 2 times. Event time is when it happened and arrival time is when your system received it. They are usually seconds apart. A phone that loses signal in a tunnel sends everything when it reconnects.
Three delivery pings. Row e-103 came from a phone that was offline all night.
| event_id | event_time | arrival_time | How late |
|---|---|---|---|
| e-101 | 18:02 | 18:02 | 0 minutes |
| e-102 | 18:10 | 20:40 | 2 h 30 min |
| e-103 | 22:15 | 04:00 (next day) | 5 h 45 min |
The biggest gap here is 5 hours 45 minutes, so the brief says late data can arrive up to 6 hours after it happened. That bound is a policy you choose. Without a number, nobody can say when yesterday's data is "finished".
4. How much
"500 million a day" is a total, and pipes and workers are sized by a rate, so convert: a day has 86,400 seconds. Traffic is never even, though.
Dinner can be several times busier than 04:00, so write down a peak multiplier too. Then multiply by the size of 1 event to get bytes.
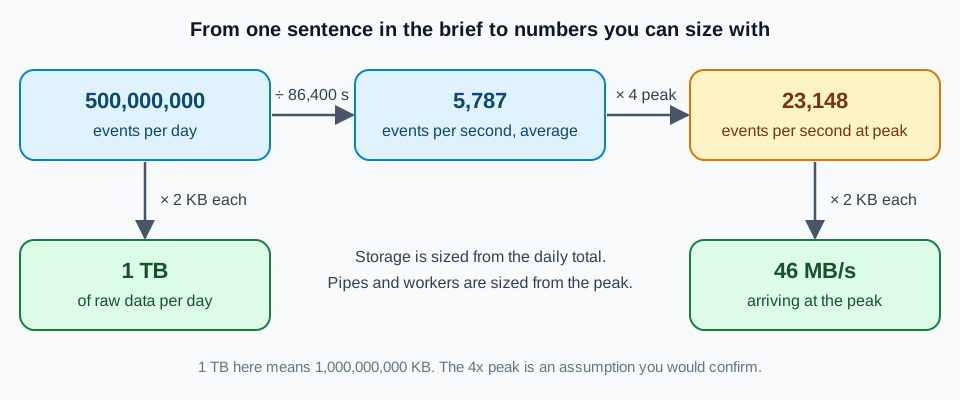
Every number in the picture comes from the one before it, so you can redo it on a napkin. The peak multiplier of 4 and the event size of 2 KB are assumptions.
In an interview you say them out loud and call them guesses. At work you read them off a dashboard.
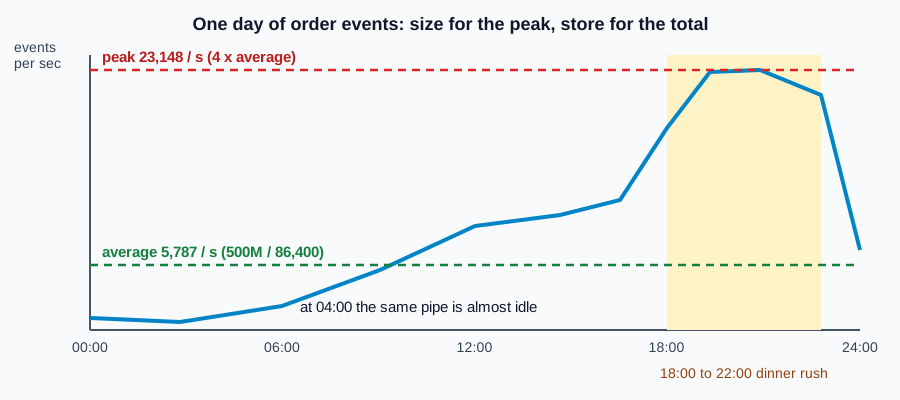
A pipe sized for the green line falls over at dinner. A pipe sized for the red line is nearly idle at 04:00.
Storage doesn't care about the shape, because it only fills with the daily total, so you use the total for storage and the red line for workers and network.
Turn each vague answer into something you could put on a chart.
| Ask | Weak answer | Usable answer |
|---|---|---|
| How many? | A lot of events | 500M events/day, about 2 KB each, about 1 TB raw |
| How bursty? | Pretty spiky | 4x the average between 18:00 and 22:00 local |
| What is an event? | User activity | An order, a GPS ping or a click, as JSON |
| Where from? | The app | Checkout service, a web pixel, one vendor file drop |
5. What it costs
You don't need an exact bill, just the order of magnitude. Say you keep the raw data for 30 days and object storage costs about ₹2 per GB per month. That price is an assumption, so look up the real one before you quote it.
One terabyte a day for 30 days is 30 TB, or 30,000 GB. At ₹2 per GB that is 30,000 x 2 = ₹60,000 a month.
If it had come out at ₹60,00,000 a month, you would have caught a problem before building anything, which is why this step exists.
Worked pass
Now the whole checklist once, start to finish, for the food delivery app. First the brief as a table, so it all sits on one page.
The finished brief. Notice it already says which readers are fast and which are slow.
| Question | Answer for this app |
|---|---|
| Who reads it | Finance (1 row per order), ops map (1 row per active delivery), growth (1 row per session) |
| How fresh | Finance: yesterday complete by 08:00 UTC. Ops map: within 5 seconds. Growth: within 15 minutes. |
| How late | Up to 6 hours after the event |
| How much | 500M events/day, about 2 KB each, 4x peak at dinner. Sources: checkout service, web pixel, vendor file. |
| What it costs | About ₹60,000 a month to keep 30 days of raw data, at an assumed ₹2 per GB-month |
The same brief fits in a Python dictionary, handy if you want it to live next to the code.
design_brief = {
    "consumers": [
        {"team": "finance", "grain": "order_id", "tolerance": "exact"},
        {"team": "ops_map", "grain": "delivery_id", "tolerance": "seconds old, a miss is fine"},
        {"team": "growth", "grain": "session_id", "tolerance": "approximate"},
    ],
    "freshness": {
        "finance": "yesterday complete by 08:00 UTC",
        "ops_map": "within 5 seconds",
        "growth": "within 15 minutes",
    },
    "lateness": {"bound_hours": 6},
    "volume": {
        "events_per_day": 500_000_000,
        "avg_event_kb": 2,
        "peak_multiplier": 4,
        "sources": ["checkout_service", "pixel", "vendor_file"],
    },
}
Steps 4 and 5 as code, so you can change a number and watch the rest move.
events_per_day = 500_000_000
seconds_per_day = 86_400
event_kb = 2
peak_multiplier = 4

avg_rate = events_per_day / seconds_per_day
peak_rate = avg_rate * peak_multiplier
peak_mb_per_s = peak_rate * event_kb / 1000
raw_tb_per_day = events_per_day * event_kb / 1_000_000_000

# assumption: 30 days kept, ₹2 per GB-month
monthly_storage_inr = raw_tb_per_day * 30 * 1000 * 2

print(f"Average: {avg_rate:.0f} events/sec")
print(f"Peak: {peak_rate:.0f} events/sec")
print(f"Peak throughput: {peak_mb_per_s:.1f} MB/s")
print(f"Raw per day: {raw_tb_per_day:.1f} TB")
print(f"Storage: ₹{monthly_storage_inr:,.0f} a month")Average: 5787 events/sec Peak: 23148 events/sec Peak throughput: 46.3 MB/s Raw per day: 1.0 TB Storage: ₹60,000 a month
Nobody gave you the peak multiplier? Say "I'm assuming 4x" and keep going. A labelled guess is useful. A silent one passes for a fact and sinks the design later.
Finance's 08:00 and the ops map's 5 seconds are different deadlines. Average them into "fairly fresh" and you build something too slow for one and too expensive for the other.
Common beginner questions
What if nobody tells me the numbers?
Ask first. If nobody knows, say your assumption out loud and label it, which is what an interviewer expects. At work you can usually find real volumes on a monitoring dashboard or by counting rows in last week's table.
Do I need to know product names like Kafka or BigQuery to write a brief?
No. A brief has no product names in it. It holds numbers and deadlines, and those stay the same whichever tool you end up choosing.
What if the numbers change after I have started building?
They will, so keep the brief where the team can see it. When volume doubles or a new reader shows up, update the page and re-check the design against it. That way the change is a decision people saw, not a surprise outage.
Vague brief: Someone says: we get a lot of order events, finance wants numbers in the morning, and ops wants a live map. It sounds like a brief but cannot be checked.
- a lot
- the morning
You: Ask 5 questions in order: who reads it, how fresh, how late can data arrive, how much, and what it costs.
- who
- fresh
- late
- how much
- cost
Readers: Finance needs exact numbers by 08:00. Ops needs a map within seconds. Growth is happy with approximate. Three readers, three promises.
- finance: 08:00
- ops: seconds
- growth: approx
Lateness: Phones in tunnels send events late. The biggest gap seen is 5 hours 45 minutes, so the brief allows data to arrive up to 6 hours late.
- gap 5h45m
- bound 6h
Rate: 500 million events a day is 5,787 a second on average. At a 4x dinner peak it is 23,148 a second, or about 46 MB/s at 2 KB each (decimal units: 1 KB is 1,000 bytes).
- 5,787/s
- x4
- 23,148/s
Cost: That is about 1 TB a day. Kept for 30 days at about 2 rupees per GB-month, storage is roughly 60,000 rupees a month, so nothing is scary yet.
- 1 TB/day
- 30 days
- 60,000/month
What comes next
The next lesson uses the freshness and lateness answers from this brief to choose between batch and stream. Later lessons size the front door for 500 million events a day, so hold on to 5,787 and 23,148 events per second.
Practice
Open the editor on this page to spot a missing question in a short brief. For deeper practice, take a blank page and write the full brief for a ride-hailing app that records 200 million trip events a day.
Pick the readers yourself, give each a freshness deadline, set a lateness bound, and run the same rate and storage arithmetic with your own numbers. Label every assumption.
Going further: turn a vague brief into numbers you can design against
A brief such as 'a dashboard that is always up to date for 1 million orders a day' sounds clear and is not. Each phrase hides a number you can ask for.
Functional requirements say what the system does. Non-functional requirements say how well: how fresh, how available, how large, how expensive. The design follows from the numbers.
Take the brief: 1 million orders a day, dashboard fresh within 15 minutes, available 99.9% of the time. Predict the average rate and the downtime allowed per month.
orders_per_day = 1_000_000
per_second = orders_per_day / 86_400

availability = 0.999
minutes_per_month = 30 * 24 * 60
downtime_minutes = (1 - availability) * minutes_per_month

print("average orders per second:", round(per_second, 1))
print("peak at 5x average        :", round(per_second * 5, 1))
print("downtime allowed per month:", round(downtime_minutes, 1), "minutes")average orders per second: 11.6 peak at 5x average : 57.9 downtime allowed per month: 43.2 minutes
An average of about 12 orders a second, 58 at an assumed peak of 5 times, and 43 minutes of downtime a month. Notice what the numbers tell you. 12 per second is small: a simple pipeline is enough, and there is no case yet for a distributed system.
The 15-minute freshness suggests a micro-batch every few minutes rather than real-time streaming. The 43-minute budget means one bad deploy can use up most of the month.
| Vague phrase | Question to ask | Why it changes the design |
|---|---|---|
| Always up to date | How old can the data be before it is useless? | Batch or stream, and the cost |
| 1 million orders | Per day? Peak? Growth in a year? | Sizing and storage |
| Highly available | What percentage, and what happens during an outage? | Redundancy and recovery |
| Fast dashboard | How many users, how many seconds? | Caching and pre-aggregation |
| Cheap | What monthly budget? | Managed service or build |
Write the assumptions down. A design that states 'peak is 5 times average' can be checked and corrected. A design with hidden assumptions fails quietly when they turn out wrong.
Try a new scenario
A brief says: 'sensors send a reading every 10 seconds from 20,000 devices, alerts must reach the on-call person within a minute'. Compute the events per second, and say whether the 1-minute rule changes the choice between batch and stream.
Work it out, then open the answer
20,000 devices each sending every 10 seconds is 2000.0 readings per second on average. The 1-minute alert rule is the deciding requirement: a nightly or hourly batch cannot meet it, so you need a stream or a micro-batch that runs every few seconds with a threshold check. The rate itself (2,000 per second) is modest, so complexity should come from the latency rule, not the volume.
Interview: what do you ask before designing a pipeline?
Who uses it and for what decision, how fresh it must be, how much data and how fast it grows, how correct it must be, what the budget is, and what happens when it is wrong. The answers choose the design.
Close the lesson and explain it
Without scrolling up, explain why a design starts with numbers, and give two vague phrases with the question that makes each concrete.
Finished this lesson?
Mark it as read when you could explain it to someone else.