
Overview
order_id is the crate label. order_total is the weight. Run the same expectation on both before finance trusts GMV.
On this page8 sections
The table we keep using
Six orders have arrived. Before anyone adds up revenue or handles refunds, we want to know if every important cell is filled in.
Every example in this lesson uses these six rows. There are two kinds of gap. Row 2 has no order_id. Rows 1 and 4 have no order_total.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Null | An empty cell. No value was recorded |
| Key | A column that identifies a row, like order_id |
| Measure | A number you add up or average, like order_total |
| Boolean | A value that is only True or False |
| Column | One field of the table |
| Quarantine | A separate table for rows that failed a check |
Row 2 has no order_id. Rows 1 and 4 have no order_total. Rows 0, 3 and 5 are complete.
Look at the NULL cells. Row 2 has an amount, 31.00, but we do not know which order it belongs to. Rows 1 and 4 have an order, but no amount.
What we need from it
Columns do different jobs. order_id is a key. It says which row this is, like a barcode on a parcel.
Without a key you cannot join tables, link a refund or settle a dispute. order_total is a measure. It is a number that gets added up in reports.
A missing key and a missing measure cause different problems. But we find both with the same question: how many cells in this column are empty?
No ID: you do not know which parcel it is. No total: you know the parcel but cannot bill it. Both fail a not-null check. The column name tells you which problem you have.
Because the check is the same, one function can test any column. You just pass the column name.
Trace it step by step
We start with the key, order_id. The first step is isna(). It looks at each cell and answers True if it is empty and False if it is not.
Step 1: one True or False flag for each row.
| row | order_id | isna() |
|---|---|---|
| 0 | ORD-101 | False |
| 1 | ORD-102 | False |
| 2 | NULL | True |
| 3 | ORD-104 | False |
| 4 | ORD-105 | False |
| 5 | ORD-106 | False |
Predict: what will the second line print, the total number of flags that are True?
import pandas as pd

batch = pd.DataFrame({
    "order_id": ["ORD-101", "ORD-102", None, "ORD-104", "ORD-105", "ORD-106"],
    "order_total": [84.50, None, 31.00, 12.50, None, 20.00],
    "status": ["paid", "paid", "paid", "cancelled", "paid", "paid"],
})

flags = batch["order_id"].isna()
print(flags.tolist())
print(int(flags.sum()))[False, False, True, False, False, False] 1
Step 2 is sum(). In Python, True counts as 1 and False counts as 0. Adding the flags gives the number of empty cells, which is 1.
Step 3 is the rule: success means failed_rows is 0. Here it is 1, so the check fails.
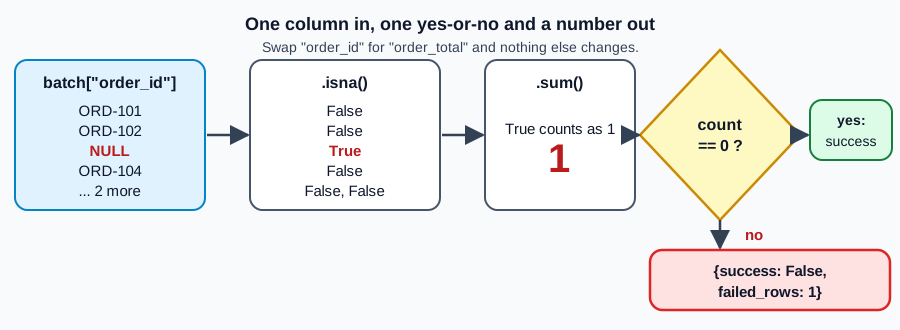
Swap order_id for order_total and nothing else changes. The same three steps work on any column.
An empty string "" or a string of spaces is not null, so isna() says False for it. To catch those you must check the length or strip the spaces. Missing numbers in a CSV, on the other hand, do come in as NaN.
Same table, next cut
Now run the same three steps on the measure column, order_total.
Step 1 on order_total: rows 1 and 4 are flagged.
| row | order_total | isna() |
|---|---|---|
| 0 | 84.50 | False |
| 1 | NULL | True |
| 2 | 31.00 | False |
| 3 | 12.50 | False |
| 4 | NULL | True |
| 5 | 20.00 | False |
Two rows are missing a measure. This loop checks both columns and prints a result for each.
for col in ["order_id", "order_total"]:
    failed = int(batch[col].isna().sum())
print(col, {"success": failed == 0, "failed_rows": failed})order_id {'success': False, 'failed_rows': 1}
order_total {'success': False, 'failed_rows': 2}Both checks fail. At the gate, the bad rows (1, 2 and 4) go to quarantine. The good rows (0, 3 and 5) go to the gold table.
Published gold rows: every required value is filled in.
| row | order_id | order_total | status |
|---|---|---|---|
| 0 | ORD-101 | 84.50 | paid |
| 3 | ORD-104 | 12.50 | cancelled |
| 5 | ORD-106 | 20.00 | paid |
Quarantined rows: held back for someone to look at.
| row | order_id | order_total | status |
|---|---|---|---|
| 1 | ORD-102 | NULL | paid |
| 2 | NULL | 31.00 | paid |
| 4 | ORD-105 | NULL | paid |
If you only have time for one not-null check, put it on the key. An empty measure makes a total a little wrong. An empty key means you no longer know which row is which, and joins break.
Common beginner questions
Should a not-null check drop the rows by itself?
No. A check should only report. Deciding to drop the rows, quarantine them or ask the source team to fix them is a separate choice made by the pipeline.
Can some columns be empty on purpose?
Yes. A column like cancelled_at or discount_code is empty for most orders, and that is fine. Only check not-null on columns that must always have a value.
Why not fill missing numbers with 0?
Because 0 is a real value and a missing value is unknown. An order with no recorded price is not a free gift. Filling with 0 hides the gap and makes totals look more certain than they are.
Batch: A batch of 6 orders arrives with gaps in both a key and a measure.
- 6 incoming rows
- 3 rows with gaps
Key check: isna() goes through order_id cell by cell and flags row 2 as True.
- flags: [F, F, T, F, F, F]
- failed_rows = 1
Measure check: The same check on order_total flags rows 1 and 4, so failed_rows is 2.
- flags: [F, T, F, F, T, F]
- failed_rows = 2
Quarantine: The gate keeps rows 1, 2 and 4 in quarantine and publishes rows 0, 3 and 5.
- 3 rows to gold
- 3 rows to quarantine
What comes next
Next lesson, Uniqueness on the grain, checks that a key appears exactly once. That catches the duplicate rows that double revenue.
Practice
In the exercise, write expect_column_not_null(df, col) and run it on df_orders_dirty. It will fail, because 2 order IDs are missing. Then filter df_orders_dirty to the rows where order_id is missing and assign that frame to result.
Going further: a value can be present and still be empty
A not-null check looks for missing values. Text columns have another way to be empty: a blank string or a few spaces. These are not null, so they sail through the check. Predict how many of the four names a plain not-null check accepts.
import pandas as pd

names = pd.Series(["Asha", "", "   ", None])

print("notna     :", names.notna().tolist())
cleaned = names.str.strip()
print("non-blank :", (cleaned.notna() & (cleaned != "")).tolist())notna : [True, True, True, False] non-blank : [True, False, False, False]
The plain check accepts three of four, including the empty string and the three spaces. After stripping the spaces and also rejecting the empty string, only 'Asha' passes. If these names feed a join or a report, the blank rows behave like real values: they group together under a blank label and never match anything.
Where to fix it: turn blanks into proper missing values early, in the cleaning step, so every later check and every join sees the same thing.
import pandas as pd

names = pd.Series(["Asha", "", "   ", None])
cleaned = names.str.strip().replace("", None)
print(cleaned.isna().tolist(), int(cleaned.isna().sum()), "missing")[False, True, True, True] 3 missing
Try a new scenario
A required column amount is read as text and contains '0', 'N/A' and ''. Which values count as missing, and which one is a real value that must not be treated as missing?
Work it out, then open the answer
'N/A' and the empty string both mean no value and should become missing. '0' is a real amount and must stay. Treating 0 as missing is a classic mistake that quietly removes genuine zero-value rows from averages and counts. Decide the list of missing markers explicitly instead of testing for 'falsy' values.
Should every column be NOT NULL?
No. Require values that must exist for a row to make sense, such as keys and amounts. Optional facts, like a second phone number, are legitimately missing, and forcing a placeholder only hides the gap.
Close the lesson and explain it
Without scrolling up, explain why a not-null check can pass blank text, and where you convert blanks into real missing values.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.