
Overview
Unit, integration, and contract tests catch different failures. A tiny suite of 2 checks prints whether both not-null and unique passed.
On this page8 sections
The idea
Say your pipeline has one automated check: order_id must never be empty. It passes every morning.
Then a join quietly drops a quarter of your orders because of a key mismatch. Every row that is left has a valid order_id, so the check stays green. Revenue is too low and no alert fires.
One check cannot catch every problem. Real pipelines use checks at three levels: unit, integration and contract.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Unit check | A check on one column or one small step |
| Integration check | A check on the result of joining or combining tables |
| Contract check | A check that a table still has the columns and types you promised to others |
| Join | Combining two tables using a shared key, like order_id |
| Suite | A group of checks that run together |
| Blocking check | A check that stops the pipeline when it fails |
Three levels of checking
The same idea as testing in software, applied to tables.
| Level | What it looks at | A plain example |
|---|---|---|
| Unit check | One column or one small step | order_id has no empty cells |
| Integration check | The result of a join, a total, or several steps | After joining payments we still have as many orders as before |
| Contract check | The columns and types you promised to others | The table still has a numeric column called order_total |
The word contract means the promise a table makes to the people who use it. If a job renames order_total to total, every number is still valid, but every dashboard that asks for order_total breaks.
Why this exists
Each level misses something
Every level has blind spots that the others cover. A unit check on order_id cannot see rows lost in a join, because the join happens after it.
An integration check can pass even when a column was dropped, as long as the join itself worked. Here is what each level catches.
No single column catches everything. That is why checks are layered.
| What went wrong | Unit check | Integration check | Contract check |
|---|---|---|---|
| Some order_id values are empty | catches it | may miss it | misses it |
| A join dropped a quarter of the orders | misses it | catches it | misses it |
| order_total was renamed to total | misses it | may fail with an error | catches it |
| status has an unknown code | catches it (with allowed values) | misses it | catches it |
The levels also differ in how easy they are to debug. A failing unit check points to one column in one table.
A failing integration check means you must look at the join keys, the letter case and the filters across several tables.
A unit check tastes one ingredient. An integration check follows a whole order from the grill to the table. A contract check confirms that the meal matches the allergy label on the menu.
Picture this
Unit checks sit on early tables, integration checks sit after joins, and contract checks sit on the published table.
Read the pipeline from left to right. After the cleaning step, unit checks make sure the key is filled in and unique.
After joining orders with payments, an integration check compares the number of rows going in with the number coming out.
At the final table, a contract check confirms the column names, types and value ranges are what the users expect.
In Python tests, an assert stops the script at the first failure. For data checks, it is more useful to return a dictionary of results. Then all checks run and you see every failure at once.
A small example
A join that quietly loses a row
Take four orders and four payments. One payment key is written in lowercase: ord-2 instead of ORD-2.
orders: 4 rows
| order_id | order_total |
|---|---|
| ORD-1 | 84.50 |
| ORD-2 | 31.00 |
| ORD-3 | 12.50 |
| ORD-4 | 20.00 |
payments: 4 rows, one key spelled in lowercase
| order_id | paid |
|---|---|
| ORD-1 | 84.50 |
| ord-2 | 31.00 |
| ORD-3 | 12.50 |
| ORD-4 | 20.00 |
An inner join keeps only the rows whose key matches on both sides. "ord-2" does not match "ORD-2", so that order drops out.
Predict: how many rows will the joined table have?
import pandas as pd

orders = pd.DataFrame({
    "order_id": ["ORD-1", "ORD-2", "ORD-3", "ORD-4"],
    "order_total": [84.50, 31.00, 12.50, 20.00],
})
payments = pd.DataFrame({
    "order_id": ["ORD-1", "ord-2", "ORD-3", "ORD-4"],
    "paid": [84.50, 31.00, 12.50, 20.00],
})

joined = orders.merge(payments, on="order_id", how="inner")
print(len(joined))3
joined: ORD-2 dropped out silently, with no warning
| order_id | order_total | paid |
|---|---|---|
| ORD-1 | 84.50 | 84.50 |
| ORD-3 | 12.50 | 12.50 |
| ORD-4 | 20.00 | 20.00 |
Three checks on the joined table
Now run a suite of three checks. Two are unit checks on order_id. The third is an integration check that compares row counts.
suite = {
    "not_null": int(joined["order_id"].isna().sum()) == 0,
    "unique": int(joined["order_id"].duplicated().sum()) == 0,
    "same_row_count": len(joined) == len(orders),
}
print(all(suite.values()))
print(suite)False
{'not_null': True, 'unique': True, 'same_row_count': False}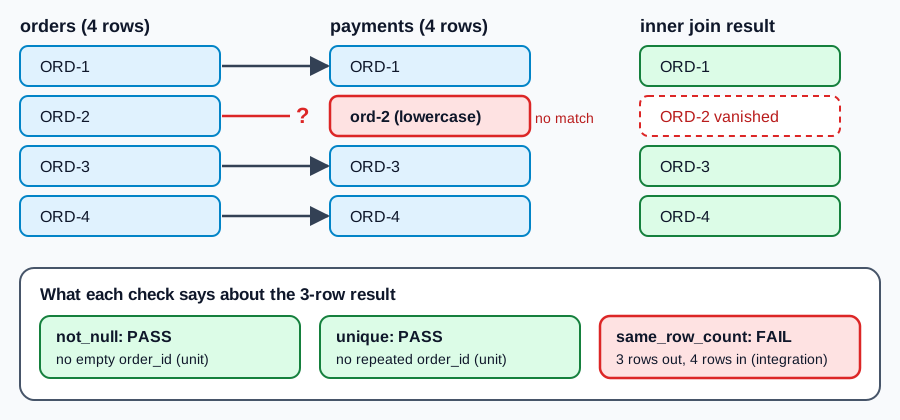
Both unit checks pass. Only the row-count check sees that a row is missing.
In pandas, duplicated(subset=["order_id"]) checks the key. Calling duplicated() with no columns checks whole rows, and would miss two rows that share an order_id but differ in another column.
Not-null plus unique together make a primary key check. A column can be unique but have gaps, or be full but have repeats. You need both.
One failing check makes all(suite.values()) False. That gives the scheduler a clear signal to stop the job.
A not-null check passes even when a join drops half your rows. A single-column check only finds single-column problems. After a join, always compare row counts.
Which check do you write first
Start with the cheapest check that would have caught your last real problem. For most tables that is a unit check on the key.
Then add one integration check for each join. A good habit is to compare the row count and the total of one money column before and after the join. If either changes, something was lost or doubled.
Add contract checks last, on the tables that other teams read. Each new check should answer a real question: what would hurt if this broke?
If you cannot name the answer, skip the check. Too many checks that nobody reads is its own kind of noise.
Contract checks on published tables
A contract check makes sure the promised columns exist before anyone queries them.
Real contracts also check types. A number like order_total must not arrive as text, or every dashboard that adds it up will break.
expected = ["order_id", "order_total", "status"]
delivered = pd.DataFrame({"order_id": ["ORD-1"], "total": [84.50]})

missing_cols = [c for c in expected if c not in delivered.columns]
print(missing_cols)['order_total', 'status']
The delivered table has good rows and no nulls, but two promised columns are missing. A query for order_total would fail with a KeyError. The contract check finds this at the door.
Stop the job, or tell someone tomorrow
Not every failure is worth waking someone at 3 AM. Give each check a severity: block or warn.
A blocking check stops publishing when a wrong number would mislead people, like revenue reports. A warning check logs the problem for the morning and lets the job finish.
checks = {
    "unique_order_id": (True, "block"),
    "same_row_count": (False, "block"),
    "status_mix_normal": (False, "warn"),
}

blocking = [name for name, (ok, level) in checks.items() if not ok and level == "block"]
warnings = [name for name, (ok, level) in checks.items() if not ok and level == "warn"]

print("stop the job:", blocking)
print("tell someone tomorrow:", warnings)stop the job: ['same_row_count'] tell someone tomorrow: ['status_mix_normal']
Lost join rows stop the job, because understated revenue misleads people. An odd mix of statuses only raises a warning, because existing queries still work.
An assert crashes the script at the first failure and hides the rest. A dictionary lets every check run, so you see all failures in one go and can send them to a log or an alert.
Common beginner questions
Do I need all three kinds on every pipeline?
No. Start with unit checks on the key. Add integration checks whenever you add a join or a total, where rows can be lost or doubled. Add contract checks on tables other teams depend on.
How is a data contract different from schema validation?
Schema validation checks that column names and types match the table definition. A contract is a promise between the team that makes the data and the teams that use it. It can also cover allowed values, freshness and who to contact when it breaks.
What if a check has a bug?
Then it can pass forever and give you false confidence. Test a check by feeding it data you broke on purpose and making sure it fails.
Unit check: A single not-null check on order_id passes every morning. That alone cannot show the table is sound.
- order_id not null
- passes
Join: A join between orders and payments drops ORD-2, because payments spelled it ord-2 in lowercase.
- 4 orders
- ord-2 mismatch
- 3 output rows
Blind spot: Both unit checks still pass. No surviving key is empty and none repeats. The lost row goes unnoticed.
- not_null True
- unique True
- row missing
Integration: An integration check compares the rows going in with the rows coming out. 3 is not 4, so it fires.
- len(joined) == len(orders)
- False
Contract: A contract check confirms that columns like order_total still exist before dashboards query them.
- verify schema
- missing_cols
Suite: Collect the results in a dictionary. Separate the blocking failures from the warnings.
- suite dict
- all() decides
- block vs warn
What comes next
Next lesson, Why quality gates, moves the checks into the pipeline itself. A gate sits between the transform and the publish step and stops a bad run before any table is updated.
Practice
In the exercise, build a suite dictionary with 2 checks on df_orders["order_id"]: not_null using isna() and unique using duplicated(). Print whether all checks passed with all(suite.values()), and assign df_orders.loc[:, ["order_id"]] to result.
Going further: test the test
A check that never fails gives false comfort. The simplest way to trust a check is to run it on data you broke on purpose and confirm it fails. If it still passes, the check is not testing what you think.
2 versions of a not-null check for an amount column. Predict which one catches the bad data.
import pandas as pd

def weak_check(df):
    return len(df) > 0                      # passes as long as there are any rows

def real_check(df):
    return df["amount"].notna().all()       # passes only if no amount is missing

good = pd.DataFrame({"amount": [10, 20, 30]})
broken = pd.DataFrame({"amount": [10, None, 30]})

for name, check in [("weak", weak_check), ("real", real_check)]:
print(f"{name}: good -> {bool(check(good))} broken -> {bool(check(broken))}")weak: good -> True broken -> True real: good -> True broken -> False
The weak check passes the broken data, so it would have stayed green forever. The real one fails on the broken data, as it should. A check earns trust only after you have seen it fail. Keep that broken sample as a small test of the check itself.
| Kind of test | Runs on | Catches |
|---|---|---|
| Unit test of the transform code | A tiny hand-made input | A logic bug in the code |
| Data test (not null, unique, ranges) | The real table, every run | Bad data from upstream |
| Reconciliation against the source | Source and target counts and sums | Lost or doubled rows |
| Test of the check itself | Data you broke on purpose | A check that cannot fail |
Try a new scenario
A uniqueness check on order_id has been green for a year. How do you gain confidence it is working, and what do you look at first?
Work it out, then open the answer
Run it on a copy of the table with 1 row duplicated and confirm it fails. Then look at what the check actually compares: a check on the wrong column, a table that is empty, or a filter that excludes the recent data would all stay green. A year of green proves nothing until you have seen the check go red once.
Interview: what would you test first in a new pipeline?
The grain and the keys (unique and not null), then row counts and totals against the source, then ranges and allowed values on the most important columns. Start with the checks that would hurt most if they failed.
Close the lesson and explain it
Without scrolling up, explain why a check should be tried on broken data, and what that proves.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.