
Overview
A green DAG that wrote null order_ids is not a successful night. The gate is a function that returns success and a count, then you print it.
On this page8 sections
What happened
A nightly pipeline takes yesterday's transactions, cleans them into a revenue table and updates the dashboards. That final, ready-to-use table is often called a gold table.
One night, an upstream service sends a few orders with blank order_id values. The cleaning script does not crash. pandas happily loads the gaps and the table is written as usual.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Gold table | The final, cleaned table that reports and dashboards read |
| Quality gate | A checkpoint that checks the data before it is published |
| Quarantine | A separate table where bad rows are held for review |
| Exit code 0 | The signal a program gives when it finished without an error |
| Expectation | One named check, such as "order_id is never empty" |
| Schema | The list of columns in a table and their types |
Every step finishes without an error. The problem only shows up later, when someone uses the table.
The scheduler marks the job green. The dashboards refresh. The problem appears days later, when the finance team tries to match refunds to orders and finds rows with no order_id.
Published gold rows. The total revenue looks fine, but two payments cannot be looked up.
| order_id | order_total | can be refunded? |
|---|---|---|
| ORD-9001 | 54.00 | yes |
| ORD-9002 | 19.99 | yes |
| (empty) | 42.50 | no: missing lookup key |
| (empty) | 8.75 | no: missing lookup key |
| ORD-9005 | 120.00 | yes |
Why it broke (or worked)
From the scheduler's side, the job worked. A green status only means the program ran to the end without crashing. It says nothing about whether the rows are right.
No step looked at the values before writing them. The log said the files were written. It did not say that two rows had no key.
Finding out late is expensive. By the time finance noticed, the dashboards had charted the numbers, other models had read the rows and analysts had exported files.
The forklift can run all night. Someone still has to check that every crate has a label. A running motor does not mean the manifest is right.
Fixing the upstream bug took minutes. Cleaning up every table and report that used the bad batch took days.
The pattern to steal
The fix is a quality gate. It is a checkpoint that runs after the transform and before the publish. If every check passes, the data is published. If any check fails, publishing is blocked.
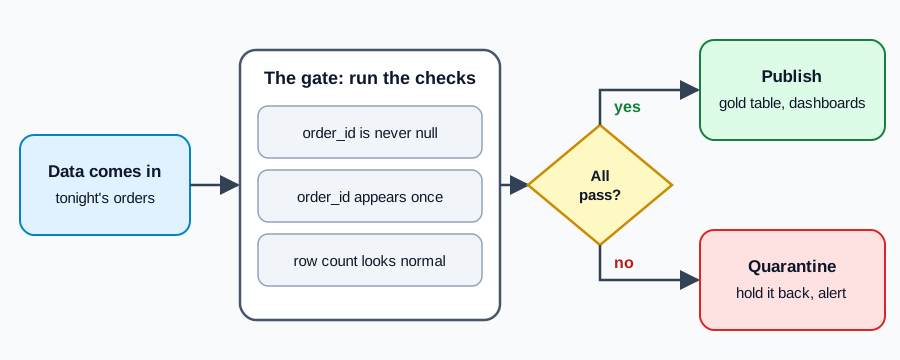
Read it left to right. New rows arrive at the gate. The gate runs the checks. If everything passes, the rows go to the gold table.
If a check fails, the gate holds the data back. Teams usually pick one of two ways to handle it.
They can stop the whole batch and keep yesterday's good table. Or they can split the batch: publish the good rows and send the bad ones to quarantine.
A split gate. Three good rows publish now. Two bad rows wait for review.
| order_id | order_total | where it goes |
|---|---|---|
| ORD-9001 | 54.00 | published to gold |
| ORD-9002 | 19.99 | published to gold |
| ORD-9005 | 120.00 | published to gold |
| (empty) | 42.50 | routed to quarantine |
| (empty) | 8.75 | routed to quarantine |
If the checks run after the table is written, the bad rows have already reached the dashboards. The gate must sit between the transform and the publish step.
How you write it
Libraries like Great Expectations call a single check an expectation. In pandas, you can build the same idea yourself with a small function that returns a dictionary.
Predict: what will the dictionary say for tonight's batch?
import pandas as pd

tonight = pd.DataFrame({
    "order_id": ["ORD-9001", "ORD-9002", None, None, "ORD-9005"],
    "order_total": [54.00, 19.99, 42.50, 8.75, 120.00],
})

failed = int(tonight["order_id"].isna().sum())
check = {"success": failed == 0, "failed_rows": failed}
print(check){'success': False, 'failed_rows': 2}The dictionary says whether the check passed and how many rows failed. The pipeline reads it to decide what to do.
if check["success"]:
    print("publish")
else:
print("quarantine:", check["failed_rows"], "rows")quarantine: 2 rows
In production, those print lines become real work: writing to the gold table, or writing to a quarantine table and sending an alert. The order never changes: check first, read the result, then publish.
A gate that fails into a channel nobody reads only delays the problem. When you add a gate, decide who gets the alert and how the quarantined rows get fixed.
Catching a schema change early
Sometimes the source team renames or drops a column without telling anyone. Your queries then fail halfway through the run.
A contract gate compares the columns that arrived with the columns you expect, before the transform starts.
expected_columns = {"order_id", "order_status", "order_total"}
actual_columns = set(df_orders.columns)

missing_columns = expected_columns - actual_columns
print("missing columns:", sorted(missing_columns))missing columns: []
df_orders has all three columns, so the list is empty. If a column had been renamed, its name would show up here, and the run could stop before any query broke.
Common beginner questions
Why not fill in the missing order IDs automatically?
Because you cannot make up an identity. A guessed ID might link a payment or refund to the wrong customer. The gate's job is to hold the rows back so a person can find the real cause.
Do checks slow the pipeline down?
A null check takes milliseconds, much less than a big join. Fixing a corrupted warehouse costs days. The check is cheap insurance.
What if a check fails and nobody answers the alert?
The gate still protects the tables, because the bad rows were held back. But a quarantine table that keeps growing needs an owner, or good data will go missing for a long time.
Pipeline: A nightly order pipeline runs to the end, writes its tables and exits with code 0.
- extract
- transform
- green exit
Defect: The source sent orders with missing order IDs. Without checks they landed in the gold table.
- missing keys
- unverified load
- gold corrupted
Impact: Refund matching fails later, because some payments cannot be linked to an order.
- refund lookup
- missing key
- incident
Gate: A quality gate sits between the transform and the publish step and checks the rules first.
- checks run
- read success
- publish or hold
Check: Each check returns {'success': bool, 'failed_rows': int}, so the code can send rows to gold or to quarantine.
- success True -> gold
- success False -> quarantine
What comes next
Next lesson, Not-null on keys and measures, looks closely at how isna().sum() finds missing values in key columns and number columns.
Practice
In the exercise, write expect_column_not_null(df, col) so that it returns {'success': bool, 'failed_rows': int}. Call it on df_orders['order_id'], print the dictionary, and assign df_orders.loc[:, ['order_id']] to result.
Going further: decide in advance what stops the pipeline
A quality gate is a decision made before a failure, not during it: which problems stop the pipeline from publishing, and which only raise a warning. If everything blocks, people disable the gate. If nothing blocks, it is decoration.
3 checks with different severities run before publishing. Predict whether the table is published in each case.
def gate(results):
    errors = [name for name, (passed, severity) in results.items() if not passed and severity == "error"]
    warnings = [name for name, (passed, severity) in results.items() if not passed and severity == "warn"]
    return ("BLOCK" if errors else "PUBLISH"), errors, warnings

monday = {"order_id unique": (True, "error"), "amount not null": (True, "error"), "email present >= 95%": (False, "warn")}
tuesday = {"order_id unique": (False, "error"), "amount not null": (True, "error"), "email present >= 95%": (True, "warn")}

for day, results in [("monday", monday), ("tuesday", tuesday)]:
    decision, errors, warnings = gate(results)
print(day, decision, "errors:", errors, "warnings:", warnings)monday PUBLISH errors: [] warnings: ['email present >= 95%'] tuesday BLOCK errors: ['order_id unique'] warnings: []
Monday publishes with a warning, because a slightly low email rate should be reported, not allowed to stop revenue reporting. Tuesday blocks, because duplicate order ids would double count revenue. The last good version stays in place until someone fixes it.
| Severity | Use when | Example |
|---|---|---|
| Error (block) | Wrong numbers would be used for decisions or money | Duplicate keys, missing amounts, row count collapse |
| Warn | Worth knowing, not worth stopping for | A small drop in optional fields |
| Quarantine the rows | Only some rows are bad and the rest are fine | Rows with an invalid date |
Try a new scenario
A check on 'country is not null' fails for 0.2% of rows every day, and the pipeline blocks every morning, so the team disables the check. What is a better design?
Work it out, then open the answer
Do not block on a known small defect. Quarantine the few bad rows so they can be fixed, publish the rest, and keep the check as a warning with a threshold (for example block above 2%). A gate that fires every day on something nobody will fix trains the team to ignore or remove gates, which is worse than a calibrated one.
Why not fix bad data downstream in the dashboard?
Every consumer would have to repeat the fix, and they would fix it differently, so the numbers would disagree. Catching it once, at the gate, keeps one version of the truth.
Close the lesson and explain it
Without scrolling up, explain how to choose which failures block a pipeline and which only warn.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.