
Overview
orders.order_id should be unique. ecommerce_events.event_id is duplicated on purpose for late ingest. The function must tell those stories apart.
On this page8 sections
The table we keep using
A sales report shows more daily revenue than the payment gateway paid out. To find out why, we look for duplicate rows.
Every example in this lesson uses this 5-row orders table. Row 2 is an accidental copy of row 1, so ORD-202 appears twice.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Duplicate | A row that repeats another row it should not repeat |
| Grain | What one row stands for. Here, one row is one order |
| Primary key | The column that is different for every row, like order_id |
| Foreign key | A column that points to another table and can repeat, like user_id |
| Row | One record |
| Entity resolution | Working out that two slightly different records are the same real thing |
Row 2 is an accidental copy of ORD-202. Row 3 repeats user_id U-7, but that is a real repeat purchase.
Look at row 2. It repeats the order ID ORD-202. Row 3 also repeats a value, user_id U-7, but that one is a returning customer. Telling the two apart is the point of this lesson.
What we need from it
Every table has a grain. It says what one row means. In this table one row is one order, so order_id must be unique.
When a key repeats, totals go up. Compare the sum with and without the duplicate.
One duplicate order adds 31.00 to the revenue.
| version | rows | SUM(order_total) |
|---|---|---|
| with duplicate row 2 included | 5 | 179.00 |
| with duplicate row 2 removed | 4 | 148.00 |
In SQL you find duplicate keys with GROUP BY order_id HAVING COUNT(*) > 1. In pandas you use duplicated().
A duplicate order_id is like two tracking stickers on one crate. A query that adds up revenue counts that crate twice. Catch it at the gate.
In our warehouse tables, df_orders has unique order IDs. df_events repeats some event_id values on purpose, to copy what happens when a network retry sends an event twice. A uniqueness check finds those repeats.
Trace it step by step
duplicated() goes down a column. The first time it sees a value, it says False. Every later copy of that value gets True.
Step 1: only the extra copies are flagged. The first one stays False.
| row | order_id | duplicated() |
|---|---|---|
| 0 | ORD-201 | False |
| 1 | ORD-202 | False (first occurrence) |
| 2 | ORD-202 | True (duplicate of row 1) |
| 3 | ORD-203 | False |
| 4 | ORD-204 | False |
Predict: how many True flags will there be, and what will the sum of the totals be?
import pandas as pd

orders = pd.DataFrame({
    "order_id": ["ORD-201", "ORD-202", "ORD-202", "ORD-203", "ORD-204"],
    "user_id": ["U-7", "U-3", "U-3", "U-7", "U-9"],
    "order_total": [84.50, 31.00, 31.00, 12.50, 20.00],
})

flags = orders["order_id"].duplicated()
print(flags.tolist())
print(int(flags.sum()))
print(orders["order_total"].sum())[False, False, True, False, False] 1 179.0
The sum of the flags is 1, one extra row. The total, 179.0, is too high because it counts ORD-202 twice.
To pull out the extra rows, use the flags as a filter.
extras = orders[orders["order_id"].duplicated()]
print(extras.loc[:, ["order_id", "user_id", "order_total"]])order_id user_id order_total 2 ORD-202 U-3 31.0
Row 2 is picked out. Whether to keep the first copy or the newest one is a decision for the pipeline. The check's job is only to find and point at the extra rows.
Same table, next cut
Now run the same method on user_id, a column that is not the grain.
flags = orders["user_id"].duplicated()
print(flags.tolist())
print(int(flags.sum()))[False, False, True, True, False] 2
user_id flags 2 repeats, but row 3 is normal behaviour.
| row | user_id | duplicated() | is it a defect? |
|---|---|---|---|
| 0 | U-7 | False | no: first order by customer U-7 |
| 1 | U-3 | False | no: first order by customer U-3 |
| 2 | U-3 | True | yes, caught as part of the duplicate ORD-202 |
| 3 | U-7 | True | no: a real second order by returning customer U-7 |
| 4 | U-9 | False | no: first order by customer U-9 |
The check finds 2 repeats, so a uniqueness test on user_id would fail. But customers do come back and order again. The data is fine. The test was on the wrong column.
Uniqueness only makes sense on the column that identifies a row. On orders that is order_id. A check on user_id fails for every returning customer and gives a false alarm.
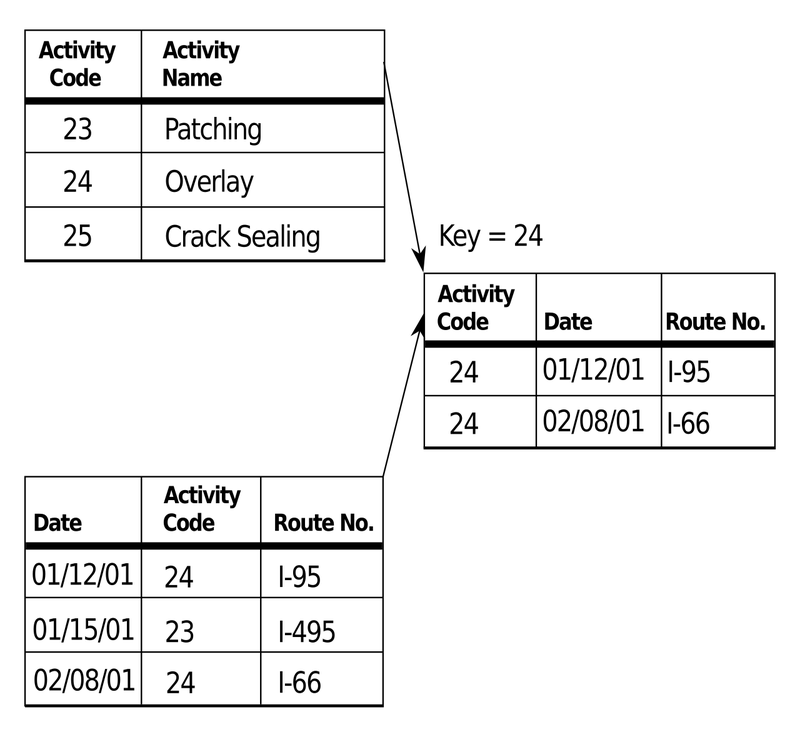
In the picture, Activity Code is unique in the top table, but repeats in the work log below, on purpose. On orders, order_id is the primary key. user_id is a foreign key, and repeats are normal.
Note that df["col"].duplicated() checks one column. df.duplicated() with no column checks whole rows, and would miss two rows that share an order_id but differ in another column.
In pandas, duplicated() also marks a second NaN as a duplicate. For a key check, drop the nulls first with dropna(). Then empty cells are reported by the not-null check and repeats by the uniqueness check, each under its own name.
A table where every order_id is different still passes a uniqueness check even if some order_total values are negative or wrong. Uniqueness checks the grain, not the numbers.
What if the duplicates are not exact?
A uniqueness check finds identical keys. But real data also has near-duplicates, caused by typing differences or by merged systems.
Three records, one real person.
| Record ID | Customer Name | Shipping Address | |
|---|---|---|---|
| 101 | Robert Smith | 123 Market St, San Francisco, CA | [email protected] |
| 102 | Rob Smith | 123 Market Street, San Francisco, CA | [email protected] |
| 103 | R. Smith | 123 Market St. | [email protected] |
If you treat these as three customers, your numbers are wrong and the same person gets three marketing emails. Working out that they are the same person is called entity resolution. Here are three common tools.
- Edit distance counts the fewest single-letter changes needed to turn one text into another. It catches spelling slips.
- Phonetic codes such as Soundex give names that sound alike the same code, so Smith and Smyth match.
- At large scale, teams first group records by something simple like the postal code. Then they compare only the records within each group, which saves a lot of time.
Common beginner questions
Why does duplicated() leave the first copy as False?
Because it counts the extra rows. The first one is treated as the original. The number of True flags is the number of surplus rows.
What if two rows share a key but have different values?
A program cannot know which one is true. Pipelines usually quarantine both rows for a person to review, or follow a written rule such as keeping the newest.
Can the grain be made of more than one column?
Yes. In an order_items table, one row is a pair: (order_id, line_number). In pandas, pass the columns as a list, like df.duplicated(subset=['order_id', 'line_number']).
Impact: A repeated order_id, ORD-202, raises the total from 148.00 to 179.00.
- 5 rows
- 1 duplicate key
- revenue inflated
Check: duplicated() goes down order_id and flags the second ORD-202 as True.
- flags: [F, F, T, F, F]
- duplicate_count = 1
Quarantine: Using the flags as a filter picks out the extra row, so it can go to quarantine.
- row 2 isolated
- clean rows proceed
Grain: Checking user_id flags 2 repeats, but returning customers are normal.
- user_id repeats
- grain mismatch
- not a defect
Rule: Always check uniqueness on the column that identifies a row, never on a foreign key.
- primary key: unique
- foreign key: allows repeats
What comes next
Next lesson, Row-count checks, starts the next module. It checks that the number of rows you loaded matches what the source sent.
Practice
In the exercise, write expect_column_unique(df, col) so that it returns {'success': bool, 'duplicate_count': int}, and run it on df_orders_dirty. It will fail, because duplicate order IDs exist.
Ignore missing values, because the not-null check already covers those. Then set result to every row whose order_id appears more than once, sorted by order_id.
Going further: uniqueness on a normalised key
A uniqueness check only compares exactly equal values. 'A1', 'a1' and ' A1' are three different strings, so a plain check passes while people see one order 3 times. Normalise the key the way the business would, then test.
Predict the number of distinct ids before and after cleaning.
import pandas as pd

ids = pd.Series(["A1", "a1", " A1", "A2"])
print("distinct as written :", ids.nunique())
print("distinct normalised :", ids.str.strip().str.upper().nunique())

orders = pd.DataFrame({"order_id": ["A1", "A1", "A2"], "line": [1, 2, 1]})
print("unique on order_id  :", orders["order_id"].is_unique)
print("unique on (order_id, line):", not orders.duplicated(subset=["order_id", "line"]).any())distinct as written : 4 distinct normalised : 2 unique on order_id : False unique on (order_id, line): True
As written there are 4 distinct ids, after normalising only 2. That is a hidden duplicate the plain check could never see. The second half shows the other common mistake: testing the wrong key.
In a table with 1 row per order line, order_id alone is not unique, and the correct key is the pair (order_id, line).
| Table grain | Key to test | Wrong test that misleads |
|---|---|---|
| 1 row per order | order_id | Row count alone |
| 1 row per order line | (order_id, line) | order_id alone: fails for a good table |
| 1 row per customer per day | (customer_id, day) | customer_id alone |
Try a new scenario
A customers table gets rows from two systems and the email is the natural key. Emails differ in case ('[email protected]' and '[email protected]'). How do you test uniqueness and which row do you keep?
Work it out, then open the answer
Test uniqueness on the lower-cased, trimmed email. For which row to keep, decide a rule in advance: the most recently updated, or the one from the more trusted system. Deleting arbitrarily gives different answers on different runs. Keep a record of what was merged so a wrong merge can be undone.
Interview: unique key versus primary key?
A primary key is the one chosen identifier of a row and must be unique and not null. A table can have other unique keys too. Many warehouses do not enforce either, so you prove them with a test.
Close the lesson and explain it
Without scrolling up, explain how a key can look unique and still hide duplicates, and how to pick the key to test.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.