
Overview
Nightly warehouse loads are batch. Click-by-click is streaming. Latency, cost, and complexity decide. FakeKafkaTopic in later lessons is a Python class of lists. No Kafka broker runs here.
On this page8 sections
The decision
This track assumes you know Python basics (lists, dictionaries, classes) and batch scheduling from Orchestration. A later lesson links to PySpark Structured Streaming.
Your online store collects orders all day. Finance wants a revenue number. The fraud team wants to know about a stolen card before the parcel leaves the warehouse. Should both of them get their answer the same way?
Usually not. The first choice you make in any data pipeline is how long you are willing to wait between an event happening and seeing the result.
An event is a record that something happened: a payment, a click, or a delivery scan. There are three common answers to the waiting question, and each has a name.
- Batch: let events pile up, then process the whole pile in one scheduled job. A job at 02:00 that reads yesterday's orders and writes the daily revenue table is batch.
- Micro-batch: the same idea with a much smaller pile. A job runs every 1 to 15 minutes and processes whatever arrived since the last run.
- Streaming: handle each event within seconds of it happening, without waiting for a pile to form.
Most of this track covers the machinery needed to make streaming work reliably: queues, partitions, and offset bookmarks. Streaming takes the most work to run, so you need to know when it is worth the cost.
The same events, three clocks. Each step to the right shortens the wait and adds machinery to run.
From left to right, the wait gets shorter and the machinery grows. Batch is the slowest to show an answer and the cheapest to run. Streaming is the fastest and asks the most of the engineers on call.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Batch | Process a pile of data on a schedule |
| Streaming | Process each event as it arrives |
| Latency | How long you wait for the answer |
| Event | One thing that happened, such as an order |
| Lag | How far behind the reader is |
| Window | A slice of time over which you add things up |
What is at stake
There are two ways to get this decision wrong, and they hurt in opposite directions.
The first mistake is building too much. Finance closes the accounting books once a day. Nobody in finance needs each paid order in the warehouse within 2 seconds.
If you build a streaming pipeline for that, you must now run a message log, worker programs that read from it, health monitors, and an on-call rotation, all to answer a question a 02:00 batch job already answers.
The second mistake is building too little. Say the product catalog shows warehouse stock from last night's load.
A customer in Pune buys the last jacket at noon, but the page keeps showing it in stock until tomorrow morning. Other shoppers order jackets you cannot deliver, which leads to cancellations, refunds, and angry customer reviews.
Latency (how stale a number is allowed to be) is a business requirement, not an engineering preference.
Ask stakeholders: how out of date can this number be before the business loses money or customer trust? Every step from hours down to seconds costs more money to build and keep running.
People say real-time when they mean "I do not want to wait until Monday". Ask for an exact number: seconds, minutes, or hours. The number picks the design, the word does not.
Option A vs Option B
A supermarket till shows the difference clearly. Scanning each item as the customer pays is streaming. Adding up all the day's sales receipts after the store closes is batch. Micro-batch is the store supervisor checking hourly totals every 15 minutes.
Three ways to treat the same events.
| Style | When it runs | Typical wait | Good fit |
|---|---|---|---|
| Batch | On a schedule, after the window has closed | Hours | Daily finance, nightly rebuilds, monthly invoices |
| Micro-batch | On a short timer, 1 to 15 minutes | Minutes | Dashboards that should feel fresh without a full streaming setup |
| Streaming | On each event, or tiny groups of events | Seconds | Fraud checks, live stock levels, click tracking |
When batch is the better pick
A batch job sees the whole time window at once, so its totals are complete. If the pipeline code had a bug, you fix the code and rerun yesterday's slice.
Batch pipelines are simpler to test, cheaper to run, and easier to recover. Do not pick batch when waiting causes financial loss, such as a fraud check on a card swipe.
When streaming is the better pick
Streaming delivers answers in seconds, but you pay for it in complexity. You need storage to buffer the events, programs that consume them, monitoring for when workers fall behind, and a strategy for handling duplicates and out-of-order data.
Later lessons in this track cover each of those challenges. Never pick streaming for a weekly summary. Micro-batch sits between the two: it often reuses standard batch tools on a tight schedule, adding much less operational burden.
Here is the same evening of orders on all three clocks. Three payments arrive at 22:14, 22:15, and 22:18, with amounts in rupees.
Input: three payment events from one evening.
| order_id | event | paid_at | amount (₹) |
|---|---|---|---|
| ORD-1 | paid | 22:14 | 120.50 |
| ORD-2 | paid | 22:15 | 40.00 |
| ORD-3 | paid | 22:18 | 88.25 |
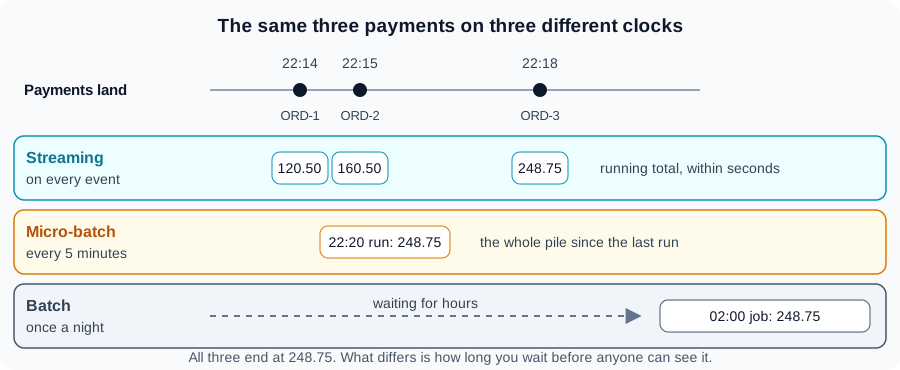
Look at the three lanes in the diagram. In the top lane, the total updates the moment each payment arrives. In the middle lane, nothing shows until the 22:20 run picks up the small pile.
In the bottom lane, you wait until the 02:00 scheduled job. All three produce the exact same final revenue of ₹248.75.
Trace the clock
Step through the trace below and observe which processing style reveals the third order first.
A worked comparison
Here is the batch approach in Python. All records sit in a list, and one job sums them after the collection window closes.
# Batch: wait, then process the whole pile
orders = [
    {"order_id": "ORD-1", "amount": 120.50},
    {"order_id": "ORD-2", "amount": 40.00},
    {"order_id": "ORD-3", "amount": 88.25},
]
nightly_revenue = sum(row["amount"] for row in orders)
print("batch revenue", nightly_revenue)batch revenue 248.75
Now compare that with streaming. We do not have a broker running here, so an in-memory list stands in for our event log. Each payment appends to the log as it happens, updating the running total immediately.
# Streaming stand-in: 1 event at a time onto a list
log = []

def on_payment(order_id, amount):
    log.append({"order_id": order_id, "amount": amount})
    return sum(row["amount"] for row in log)

print("after ORD-1", on_payment("ORD-1", 120.50))
print("after ORD-2", on_payment("ORD-2", 40.00))
print("running total", on_payment("ORD-3", 88.25))after ORD-1 120.5 after ORD-2 160.5 running total 248.75
Both programs calculate 248.75. The batch version produces one answer at the end of the window. The streaming version produces an updated answer after every single event, which is what a live dashboard or alert system needs.
In later lessons, this Python list becomes a class called FakeKafkaTopic. Note that no Kafka broker runs in this tab. The exercises run pure Python, teaching the mental model before you manage distributed clusters.
Consider five pipeline requests a food delivery platform in Bengaluru might receive, and how the freshness requirement determines the design.
Same company, three different answers.
| Request | How stale is too stale? | Pick | Why |
|---|---|---|---|
| Daily revenue report for finance, ready by 08:00 | Hours | Batch | Restaurants finish settlement at 02:00. The nightly job has 6 hours to complete. |
| Show a restaurant as "closed" the moment it goes offline | Seconds | Streaming | Allowing orders for an offline kitchen results in cancelled meals and unhappy users. |
| Ops dashboard of active deliveries per city zone | A few minutes | Micro-batch | A job every 5 minutes feels fresh without running 24/7 stream infrastructure. |
| Flag a stolen credit card before food is prepared | Seconds | Streaming | Once the kitchen prepares the meal, the cost cannot be recovered. |
| Monthly payout calculations for delivery partners | Days | Batch | Partners expect complete, audited figures at the end of the billing cycle. |
- Write down the business question and state the allowable staleness as an exact duration in seconds, minutes, or hours.
- If the business can wait until tomorrow morning, start with batch. It is the cheapest to run and easiest to recover from errors.
- If answers need to be fresh within a few minutes, evaluate micro-batch before building 24/7 streaming infrastructure.
- If seconds directly prevent losses or preserve trust, design for streaming, and plan for consumer lag, retries, and crashes.
Common beginner questions
Is micro-batch just streaming with a delay?
Not quite. A micro-batch engine waits for a small time window to fill, then processes the accumulated records as a small batch, often reusing batch execution logic. A streaming engine processes events continuously as they arrive. They are operated, monitored, and tuned differently.
Why not stream every pipeline by default?
Streaming requires persistent event storage, continuous worker processes, consumer lag monitoring, and recovery logic for malformed messages. That infrastructure is far more expensive to build and maintain than scheduled SQL jobs. Stream only when delay costs real money or trust.
Does batch processing mean lower quality data?
No. Batch jobs inspect the entire dataset after the window closes, so you can remove every duplicate and check the totals against other tables. Streaming pipelines often publish fast initial totals that may need correction as late events arrive. Freshness and completeness trade off against each other.
Finance: Finance wants yesterday's revenue by 08:00. Nobody needs it sooner.
- question
- hours are fine
Batch: A 02:00 job reads the whole pile of orders and writes one total. That is batch.
- pile up
- one job
- one answer
Micro-batch: The ops dashboard can be 5 minutes old, so a job every 5 minutes is enough. That is micro-batch.
- short timer
- small pile
- fresh enough
Streaming: The fraud system must catch a stolen card before food is prepared. Seconds matter, so each payment is checked as it arrives. That is streaming.
- event
- check now
- answer in seconds
Comparison: Same 3 orders, same final revenue of 248.75. The only difference is how long you waited to see it.
- same data
- different clock
What comes next
Once you decide a pipeline requires streaming, you need a safe place for events to wait until downstream programs process them. That storage layer is a message queue, and the next lesson explains why you need one.
Practice
Run the sample, then open the exercise. Write style() so it picks batch, micro-batch or streaming from how long the business can wait. Use it on the four needs in the exercise, store the list in result, and print it.
Going further: event time and arrival time are different clocks
A streaming job has to decide which time a record belongs to: when the event happened (event time) or when the job received it (arrival time). They differ whenever something is late, and the choice changes the answer. Predict the counts per minute for both.
from collections import Counter

# (event minute, arrival minute). The third click happened at minute 1 but arrived at minute 3.
clicks = [(0, 0), (0, 0), (1, 3), (2, 2), (2, 2), (3, 3)]

by_event = Counter(event for event, _ in clicks)
by_arrival = Counter(arrival for _, arrival in clicks)

print("by event time  :", dict(sorted(by_event.items())))
print("by arrival time:", dict(sorted(by_arrival.items())))by event time : {0: 2, 1: 1, 2: 2, 3: 1}
by arrival time: {0: 2, 2: 2, 3: 2}By event time, minute 1 has 1 click, which is what really happened. By arrival time minute 1 shows 0 and minute 3 shows 2, because the late click is counted in the wrong minute.
Reports for the business want event time. The price is that the job must wait for stragglers before it can call a minute final.
| Event time | Arrival time | |
|---|---|---|
| Answers | What happened, when | What we received, when |
| Late data | Fixes the count, if you wait | Misplaces it in a later window |
| Cost | State to hold open windows, and a rule for how long to wait | Simple and immediate |
To count by event time, a streaming job must set an allowance for how long to wait for stragglers before closing a time window. Later in this track, you will see how watermarks formalise this heuristic. Waiting longer captures late arrivals but delays publishing the final numbers.
Try a new scenario
Phones sometimes upload their taps in a batch when they get signal, up to 10 minutes late. You report taps per 5-minute window. What do you set, and what do you pay?
Work it out, then open the answer
Use event time with a wait of at least 10 minutes, so late batches still land in the right window. The price is delay: a window cannot be final until about 10 minutes after it closes, and the job keeps state for those open windows. A shorter wait gives faster numbers but drops or misplaces the latest batches.
Interview: when is batch the better choice?
When nobody needs the answer sooner than the schedule, when logic needs the whole day of data, or when simplicity and cost matter more than freshness. Streaming earns its extra complexity only when a delay of minutes or hours has a real cost.
Close the lesson and explain it
Without scrolling up, explain the difference between event time and arrival time, and what waiting for late events trades off.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.