
Overview
A topic is a named log split into partitions. Keys normally choose a partition so related events stay together, but the exact partitioning rule belongs to the producer client.
On this page8 sections
The picture
Picture one billing counter at a supermarket on a festival evening. Hundreds of people stand in a single line, and one cashier serves them. The shop opens eight more counters and the line finally moves.
A queue has the same problem. ShopKart sends 100,000 click events a second into one queue, and a single reader cannot keep up. So the queue is cut into lanes, called partitions, and a separate reader takes each lane.
There is a catch. If the 3 events of one order (created, paid, shipped) land in three different lanes, three readers may handle them at the same moment, and shipped can be processed before paid.
So we need a rule: all events of one order go to the same lane.
ORD-1 always lands in partition 2, so every event about ORD-1 sits in one list, in the order it was written.
The four boxes are how 1 message finds its lane. It carries a key (ORD-1). The key is turned into a number, the number is divided by 3, and the remainder picks the lane. That is all the routing there is.
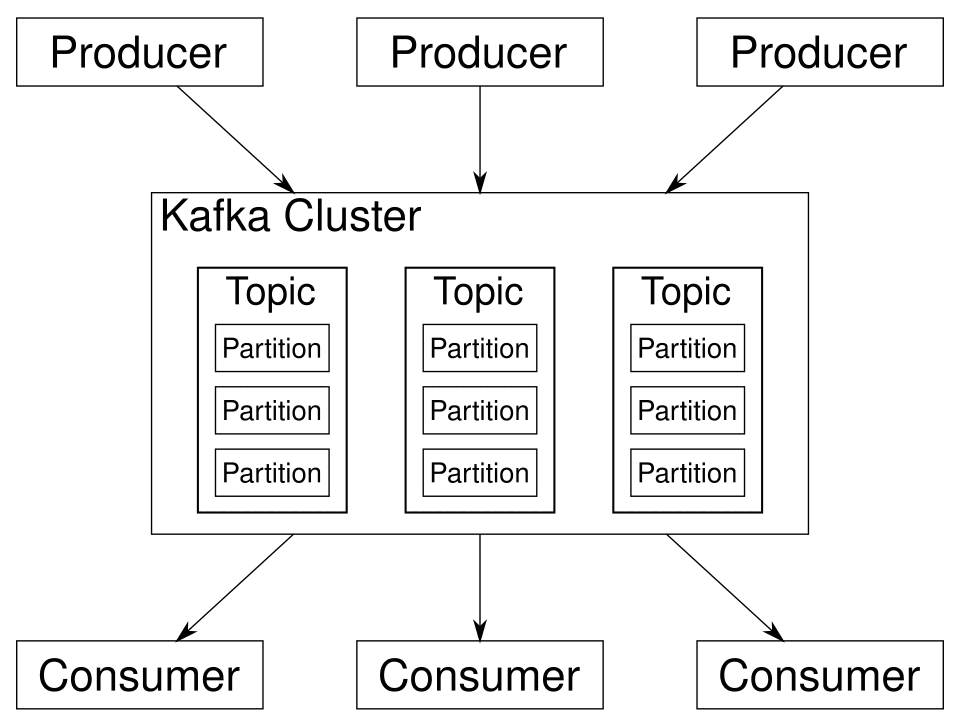
This is the whole system in one frame. The boxes on top are programs that write. The boxes at the bottom are programs that read.
In the middle, the cluster holds topics, and every topic is a stack of partitions. The words topic and partition are what this lesson is about.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Partition | One lane of a topic |
| Key | The value that decides which lane an event goes to |
| Consumer | Whatever reads events out |
| Lane | Another word for one partition |
| Order | Events with the same key stay in the order they arrived |
| Topic | A named stream of events |
Why this shape
Two separate problems push you to this design.
The first is speed. If one consumer can handle 10,000 messages a second and 100,000 arrive, you need 10 consumers.
They cannot all read from the same list without stepping on each other. So the list is split into partitions, and each partition is read by one consumer at a time.
The second is order. Suppose ORD-1 produces 3 events: created, paid, shipped. If those went to three different partitions, three different consumers might process them at the same moment. "Shipped" could be handled before "paid", and the order's status would end up wrong.
So every event for ORD-1 must go to the same partition. The key is what makes that happen.
You pay for it in one place: order is only guaranteed inside a partition. 2 events for different orders may be read in either order, and for different orders, that rarely matters.
A real Kafka setup hashes the key with an algorithm called murmur2 to pick a partition.
In this track we use a simpler stand-in, the sum of the key's character codes, because you can work it out by hand. The behaviour is the same: a given key always gives the same partition.
Walk the boxes
Here is the vocabulary, in the order a message meets it.
- Topic: a named log for one kind of event, such as orders or clicks.
- Partition: one ordered list inside a topic. A topic with 3 partitions is 3 separate lists.
- Key: a label on the message, such as ORD-1, used to choose the partition.
- Offset: a message's position within its partition, starting at 0. Offsets belong to a partition, not to the whole topic.
Now 5 events through a topic with 3 partitions.
Input: 5 events, in the order they were produced.
| Arrival | Key | Event |
|---|---|---|
| 1 | ORD-1 | created |
| 2 | ORD-2 | created |
| 3 | ORD-1 | paid |
| 4 | ORD-3 | created |
| 5 | ORD-2 | paid |
To pick a lane we need a number for each key. Python gives every character a code with ord(). Add up the codes and take the remainder when dividing by 3.
For ORD-1 that is 79 + 82 + 68 + 45 + 49 = 323, and 323 divided by 3 leaves 2.
Sum for ORD-1: 79 + 82 + 68 + 45 + 49 = 323. 323 % 3 = 2.
| Character | ord() value |
|---|---|
| O | 79 |
| R | 82 |
| D | 68 |
| - | 45 |
| 1 | 49 |
Only the last character differs, so the 3 keys land in three different lanes.
| Key | Sum of codes | Sum % 3 | Partition |
|---|---|---|---|
| ORD-1 | 323 | 2 | 2 |
| ORD-2 | 324 | 0 | 0 |
| ORD-3 | 325 | 1 | 1 |
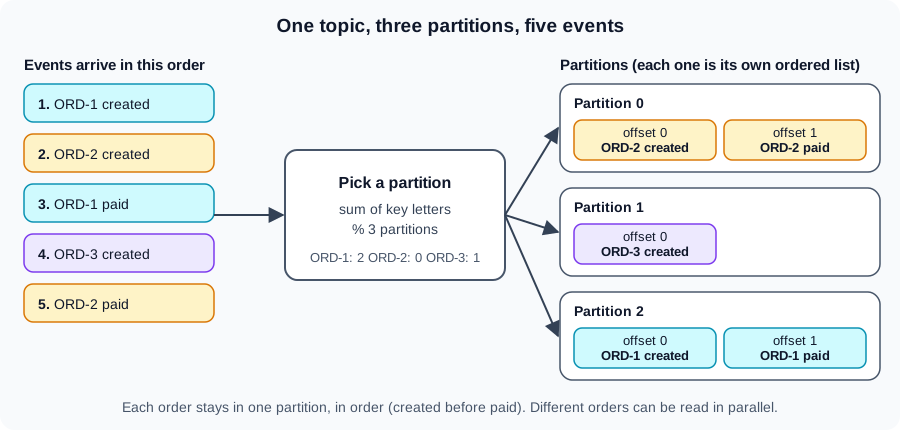
Read the colours. Cyan is ORD-1, amber is ORD-2 and purple is ORD-3. Each colour stays inside 1 partition, and ORD-1's created event comes before its paid event at offsets 0 and 1.
Partitions 0 and 2 each hold 2 events and partition 1 holds one, so a consumer for each lane would be working in parallel.
A matching example
Here is the same thing in code. partition_for turns a key into a lane, and FakeKafkaTopic is a list of lists: one inner list per partition.
def partition_for(key: str, n_partitions: int) -> int:
    return sum(ord(c) for c in key) % n_partitions

print(partition_for("ORD-1", 3))
print(partition_for("ORD-2", 3))
print(partition_for("ORD-3", 3))2 0 1
class FakeKafkaTopic:
    def __init__(self, name: str, n_partitions: int):
        self.name = name
        self.partitions = [[] for _ in range(n_partitions)]

    def produce(self, key: str, value: str) -> int:
        idx = partition_for(key, len(self.partitions))
        self.partitions[idx].append({"key": key, "value": value})
        return idx

topic = FakeKafkaTopic("orders", 3)
for key, value in [("ORD-1", "created"), ("ORD-2", "created"), ("ORD-1", "paid"),
                   ("ORD-3", "created"), ("ORD-2", "paid")]:
    topic.produce(key, value)

for i, part in enumerate(topic.partitions):
print("partition", i, part)partition 0 [{'key': 'ORD-2', 'value': 'created'}, {'key': 'ORD-2', 'value': 'paid'}]
partition 1 [{'key': 'ORD-3', 'value': 'created'}]
partition 2 [{'key': 'ORD-1', 'value': 'created'}, {'key': 'ORD-1', 'value': 'paid'}]This matches the picture. Both ORD-1 events are in partition 2, with created first. A consumer reading partition 2 sees ORD-1's history in order and never has to wonder about the other orders.
A second, more realistic case: a ride-hailing app sends location pings for each driver. If the key is the driver_id, every ping from driver D-17 lands in 1 partition, in order, so a consumer can compute that driver's route without sorting.
If instead you picked no key at all, pings from one driver would spread across lanes and could be processed out of order.
Python's built-in hash() for strings is randomised each time the interpreter starts. hash("ORD-1") would give a different lane after every restart, and the same key would stop mapping to the same partition. Use a stable function. The exercise grades the sum of character codes.
Partitions only share the work evenly if keys are spread evenly. If you used country as the key and most orders come from one country, 1 partition gets most of the traffic and its consumer falls behind while the others sit idle. Pick a key with many different values, like order_id.
How many lanes should a topic have?
Work backwards from the traffic. Say ShopKart expects 100 MB of events every second, and one reader can process about 10 MB a second.
import math

target_mb_per_sec = 100
one_reader_mb_per_sec = 10

partitions = math.ceil(target_mb_per_sec / one_reader_mb_per_sec)
print(partitions)10
10 lanes, so 10 readers can share the load. Going lower has a cost you will not see until it hurts.
- Too few lanes: a topic with 4 lanes and 8 readers leaves 4 readers idle, because each lane is read by only one reader at a time.
- Too many lanes: more files for the servers to manage, and slower recovery when one server fails.
What if one key is much bigger than the rest?
Say one big seller sends 70% of ShopKart's orders and you chose seller_id as the key. Every one of that seller's events lands in the same lane. That lane's reader falls behind while the other lanes sit nearly empty. This is a hot partition.
Two common fixes. Make the key finer, such as seller_id plus order_id, so the seller's orders spread over many lanes while each single order still stays in order. Or, when order does not matter, send the events without a key and let them spread evenly.
Common beginner questions
How many partitions should a topic have?
There is no single right number. More partitions allow more consumers to work at once, and also mean more to manage. A moderately busy topic often starts with somewhere around 6 to 12, but it depends on your traffic. Work out how many consumers you will eventually want.
Can I add partitions later?
Yes, though you cannot easily reduce them. Adding them changes the remainder, so keys can move. With our stand-in, ORD-1 gives 323 % 3 = 2 on 3 partitions but 323 % 4 = 3 on four. From that moment its new events go to a different lane than its old ones, which breaks the order guarantee across the change.
What if I need all messages in strict order?
Then you use 1 partition, and give up the parallel reading. Order is only guaranteed within a partition, so most designs only ask for order per key.
Producer: 5 events arrive: ORD-1 created, ORD-2 created, ORD-1 paid, ORD-3 created, ORD-2 paid.
- 5 events
- 3 lanes
Producer: Each event carries its order id as the key. The key decides the lane, so nobody has to guess.
- key
- number
- lane
Router: ORD-1 adds up to 323, and 323 divided by 3 leaves 2. ORD-1 goes to lane 2. ORD-2 goes to lane 0 and ORD-3 to lane 1.
- 323 % 3 = 2
- lane 2
Lane 2: Both ORD-1 events sit in lane 2, created first and paid second, because a lane keeps its own order.
- offset 0: created
- offset 1: paid
Consumers: Three readers, one per lane, work at the same time. None of them ever sees ORD-1 out of order.
- reader 0
- reader 1
- reader 2
What comes next
You know where messages live. The next lesson covers how a consumer remembers how far it has read in each partition. Those bookmarks are called offsets.
Practice
Run the sample, then open the exercise. Write partition_for(key, n) so that it returns the sum of the key's character codes, divided by n, keeping the remainder.
Call it with the key ORD-1 and 3 partitions, assign the result to result and print it. Check your answer against the worked arithmetic above.
Going further: retention, and the consumer that falls too far behind
A topic does not keep events forever. It keeps them for a retention period and then deletes the oldest. A consumer that stays within that window never notices. A consumer that falls behind by more than the window loses data it never read.
The log below keeps only the 5 newest events. A consumer last read up to offset 2 and was offline while 10 more events arrived. Predict where it can resume.
RETENTION = 5                      # the log keeps only the newest 5 events

class Log:
    def __init__(self):
        self.start = 0             # offset of the oldest event still kept
        self.next = 0              # offset of the next event to be written
    def append(self, count):
        self.next += count
        self.start = max(self.start, self.next - RETENTION)

log = Log()
log.append(3)                      # offsets 0..2 exist
saved_position = 3                 # the consumer has read all of them
log.append(10)                     # the consumer is offline; 10 more events arrive

print("log keeps offsets", log.start, "to", log.next - 1)
if saved_position < log.start:
print("saved position", saved_position, "is gone ->", log.start - saved_position, "events were deleted unread")log keeps offsets 8 to 12 saved position 3 is gone -> 5 events were deleted unread
The log now keeps offsets 8 to 12, so the consumer's saved position of 3 no longer exists. The events 3 to 7 (5 events) were deleted before it read them. What happens next is a setting: the consumer may jump to the oldest kept event or to the newest, or stop with an error.
In every case there is a permanent gap.
The fix is operational. Set retention longer than the longest outage you want to survive, and alert on consumer lag so you act long before the lag approaches the retention window.
| Retention | Lag alert | Result |
|---|---|---|
| 7 days | Alert at 1 hour of lag | Time to react, and a week of buffer |
| 1 hour | Alert at 30 minutes of lag | An outage over an hour loses data |
| 7 days | No lag alert | Works until the day nobody notices for 8 days |
Try a new scenario
Retention is 24 hours and a weekend outage keeps your consumer down for 60 hours. What was lost, and what could you do now?
Work it out, then open the answer
The topic kept only the last 24 hours, so about 36 hours of events were deleted before the consumer could read them. If the source system still holds the data (a database, or files), re-extract that period from the source. If not, the gap is permanent. Longer retention and a lag alert would have prevented it.
Interview: how do you pick a partition key?
Pick the field whose order matters and that spreads load evenly, such as a customer or order id. A key with a few huge values creates a hot partition, and a random key loses the per-key order.
Close the lesson and explain it
Without scrolling up, explain what retention does and what happens to a consumer that falls behind by more than the retention period.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.