
Overview
A click should not wait for the warehouse. A queue decouples the two, buffers when the reader is down, and lets you replay old messages.
On this page8 sections
The idea
A customer on ShopKart in Bengaluru taps Buy Now on a jacket.
Behind that single tap, four downstream systems need the order details: the warehouse to pack it, the notification service to send a confirmation SMS, the fraud engine, and the analytics database that powers the live revenue dashboard.
The straightforward approach is for the checkout server to make a direct network call to each downstream service in turn, waiting for each reply before confirming the order to the shopper.
That synchronous chain is brittle. If the analytics database is slow or undergoing maintenance, the customer's checkout screen spins. If an unhandled timeout occurs, the purchase can fail even though the customer's card was already charged.
A message queue solves this problem by placing a durable buffer between the producer and the consumers. The checkout server, acting as the producer, appends 1 message such as 'order ORD-1 placed' into the queue and immediately returns a success response to the customer.
Each downstream service acts as an independent consumer, reading messages from the queue at its own pace without blocking checkout or each other.
The producer drops a message and leaves. The consumer reads when ready. The queue holds everything in between.
Notice that only the producer step sits on the customer's critical path. Downstream consumers can slow down, crash, or restart for deployments, and the checkout page continues operating smoothly.
Think of a postbox at an apartment gate. The courier drops parcels into the box and leaves immediately. You collect your parcel when you return home in the evening. Neither party waits on the other.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Kafka | A system that stores a stream of events for many readers |
| Topic | A named stream of events |
| Producer | Whatever writes events in |
| Consumer | Whatever reads events out |
| Consumer lag | How far behind the reader is |
| Poison pill | A bad event that keeps crashing the reader |
Why this exists
Placing a message queue between services provides three architectural benefits that direct API calls cannot match.
Decoupling: one slow system cannot freeze others
Suppose the customer notification service crashes at 21:00. With a message queue, the customer still sees 'Order confirmed', the warehouse still packs the jacket, and the payment settles.
The SMS receipts are simply delayed. When the notification service recovers, it resumes reading from where it stopped and sends the pending messages.
Buffering: absorbing traffic spikes
During a Diwali flash sale, order volume can surge from 50 orders per minute to 5,000 orders per minute. A database handling direct HTTP calls would be overwhelmed and drop connections.
A queue absorbs the traffic spike, within its storage and retention limits. The warehouse consumer keeps reading orders at a steady rate it can handle, which protects the database from the spike.
A queue buffers temporary spikes, but it does not make overload disappear. If arrivals exceed consumer capacity over a long period, unread messages accumulate. We inspect how to track this in the consumer lag section below.
Replay: re-reading historical events
Direct HTTP requests vanish from memory once delivered. By contrast, a persistent message log keeps messages on disk even after consumers read them.
Suppose a new tax calculation deployed on Tuesday contains a bug that is discovered on Thursday. You deploy the fix, rewind the consumer bookmark back to Tuesday morning, and reprocess every order to correct the warehouse table.
Multiple independent readers
When marketing requests order data for a new customer tool, the checkout service requires zero code changes. Engineers simply attach a new consumer to the existing queue.
The fraud engine, warehouse worker, analytics pipeline, and marketing loader each read from the same stream at their own independent speeds.
3 core jobs a queue performs that direct calls cannot.
| Ability | Without a queue | With a queue |
|---|---|---|
| Decouple | The checkout page waits for every downstream write | Checkout writes 1 message and returns immediately |
| Buffer | Traffic spikes overload downstream services or drop events | Surges wait safely in the queue until workers consume them |
| Replay | Delivered calls vanish; re-reading requires custom sender logic | Rewind the consumer bookmark and re-read historical messages |
Picture this
Consider how the Wikimedia Foundation operates background updates across Wikipedia. When you save an edit on an article, MediaWiki must update every related page that links to it. That intensive work is not performed while your browser waits.
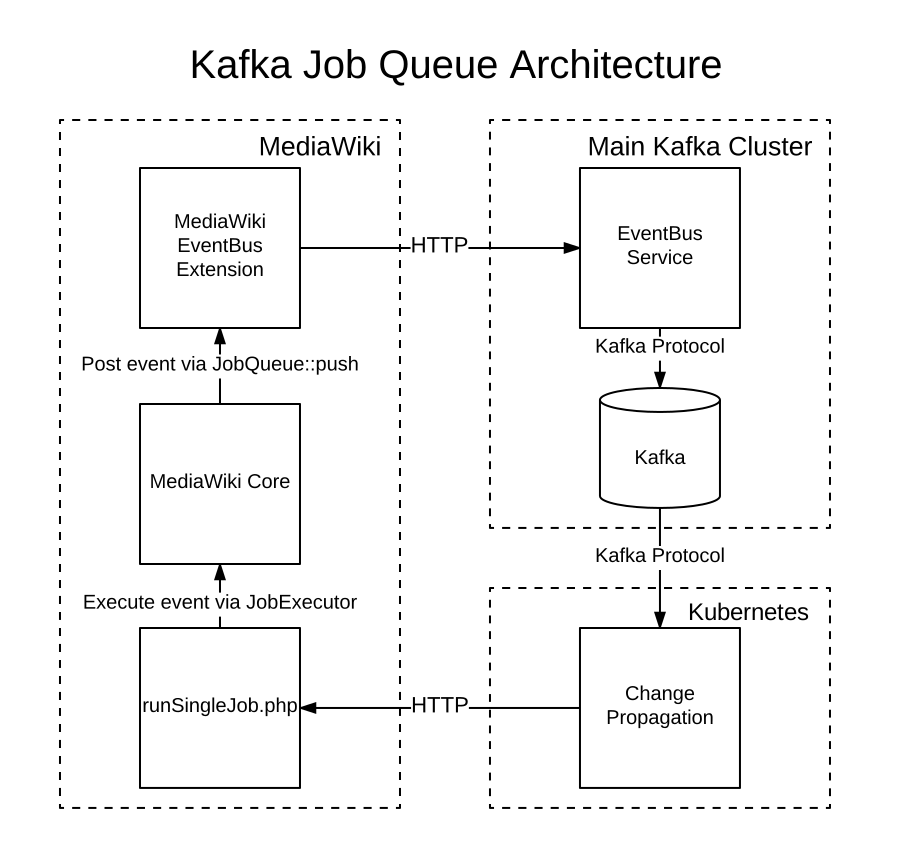
Follow the arrows in the diagram clockwise from the top-left box. MediaWiki publishes a job event to the Kafka cluster and returns to the editor immediately.
Later, an independent Kubernetes service reads the event from Kafka and calls MediaWiki back asynchronously to execute the update. The user who saved the edit never waits for the background processing.
A small example
In this track, a Python class called FakeKafkaTopic models the core behavior of an event queue. It wraps an in-memory list with two primary operations: producing and consuming.
Note that no Kafka broker runs in this tab. The exercises run standard Python lists. Real production systems like Apache Kafka or Amazon SQS run distributed clusters across many servers, but the foundational mechanics are identical.
class FakeKafkaTopic:
    def __init__(self):
        self.messages = []

    def produce(self, message):
        """The sender adds a message to the end and moves on."""
        self.messages.append(message)

    def consume(self, offset, count):
        """The reader asks for count messages starting at offset."""
        return self.messages[offset:offset + count]

topic = FakeKafkaTopic()
topic.produce({"event": "click", "user": "u1", "page": "/products"})
topic.produce({"event": "click", "user": "u2", "page": "/cart"})
topic.produce({"event": "click", "user": "u1", "page": "/checkout"})

print(topic.consume(offset=0, count=2))
print(topic.consume(offset=2, count=5))
print(topic.consume(offset=0, count=3))[{'event': 'click', 'user': 'u1', 'page': '/products'}, {'event': 'click', 'user': 'u2', 'page': '/cart'}]
[{'event': 'click', 'user': 'u1', 'page': '/checkout'}]
[{'event': 'click', 'user': 'u1', 'page': '/products'}, {'event': 'click', 'user': 'u2', 'page': '/cart'}, {'event': 'click', 'user': 'u1', 'page': '/checkout'}]Observe how the three consume calls behave. 3 messages were buffered in memory before any consumer read them.
The first read fetched 2 messages starting at offset 0. The second read started at offset 2 and read to the end of the available list.
The third read started at offset 0 again and retrieved all 3 messages. Reading did not delete or destroy the messages. That persistence is what makes replay possible.
Here is the notification service outage represented as an offset trace. The service was offline while payments ORD-2 and ORD-3 arrived.
Messages at offset 1 and 2 arrived while the reader was offline.
| offset | message | notification service status |
|---|---|---|
| 0 | payment ORD-1 succeeded | processed before maintenance |
| 1 | payment ORD-2 succeeded | buffered in queue during outage |
| 2 | payment ORD-3 succeeded | buffered in queue during outage |
The payment checkout service was never impacted. When the notification service restarted, it queried the queue starting from offset 1, sent the two delayed receipts, and caught up completely.
Monitoring consumer lag
To verify that consumers keep up with incoming traffic, monitor consumer lag: the difference between the newest message offset written by producers and the last offset processed by the consumer.
- Newest message: offset 1,000,000
- Consumer finished: offset 950,000
- Lag: 50,000 messages
Lag hovering near zero indicates consumers are keeping pace. Lag that increases steadily across hours indicates incoming volume exceeds consumer processing capacity, requiring faster processing or horizontal scaling.
Handling poison pills
Suppose a message contains malformed JSON or invalid types. A consumer reading it throws an exception, crashes, restarts, reads the same message again, and crashes in an infinite loop. This unprocessable record is known as a poison pill.
Production pipelines protect themselves using a dead-letter queue (DLQ). After a bounded number of retry attempts, the consumer moves the failing message to the dead-letter queue and advances its offset bookmark, allowing normal processing to continue.
Queues move events between systems. In Apache Kafka, messages are retained for a configurable period (7 days by default) and then deleted. In Amazon SQS, messages are deleted once acknowledged. Consumers must persist processed results to durable stores like PostgreSQL or a data lake.
Common beginner questions
Why not use direct HTTP calls between all microservices?
Direct HTTP calls work well when the caller requires an immediate response to proceed. For handing off asynchronous pipeline tasks, direct calls tightly couple services: if the receiver is slow or down, the sender stalls, and failed requests cannot be replayed later.
Is a traditional message queue different from an event log like Kafka?
Yes. Traditional message queues (such as Amazon SQS or RabbitMQ) delete messages once a worker acknowledges them. Distributed event logs (such as Apache Kafka or AWS Kinesis) retain messages on disk for days or weeks, allowing multiple consumers to replay history from any offset bookmark.
Can a message queue run out of disk space?
Yes. If producer traffic continuously exceeds consumer throughput, unread messages accumulate. Distributed logs mitigate this by enforcing retention policies based on time or disk size, deleting old records once limits are reached.
What happens if a producer changes the message structure?
Producers and consumers deploy independently, so a renamed field can silently break downstream jobs. Engineering teams establish schema contracts using tools like Schema Registry, ensuring backwards compatibility before new message formats are published.
Checkout: A customer completes checkout on ShopKart. The server charges the card and saves the transaction.
- tap
- charge
- save order
Producer: Checkout publishes an 'order ORD-1 placed' message to the queue and returns immediately to the shopper.
- message
- queue
- response
Queue: The analytics consumer is experiencing high load, so the message waits safely in the queue buffer.
- downstream busy
- message buffered
Consumer: The notification service restarts after maintenance, reads from offset 1, and dispatches the pending receipts.
- restart
- read offset 1
- receipts sent
Replay: A downstream tax bug is fixed. The consumer rewinds its bookmark to the start of the week and re-reads historical records.
- deploy fix
- rewind offset
- reprocess
What comes next
One queue read by a single consumer works for moderate traffic. When messages arrive faster than one consumer process can handle, the queue is split into parallel lanes called partitions. That is the next lesson, on topics, partitions and keys.
Practice
Run the sample, then open the exercise. 3 problems are listed. For each one, decide which job of a queue solves it: decouple, buffer or replay. Put the 3 words in a list called result, in the same order, and print it.
Going further: a queue turns a burst into a wait
A queue sits between a producer and a consumer so that a burst does not have to be handled at the instant it arrives. The consumer works at its own steady speed, and the queue grows while the burst lasts and shrinks afterwards. Predict how deep the queue gets.
arrivals = [10, 10, 100, 100, 100, 10, 10, 10, 10, 10]    # events per second
capacity = 40                                              # events the consumer handles per second

queue = 0
for second, arriving in enumerate(arrivals):
    queue = max(0, queue + arriving - capacity)
print(f"second {second}: arrived {arriving:3} queue depth {queue:3}")second 0: arrived 10 queue depth 0 second 1: arrived 10 queue depth 0 second 2: arrived 100 queue depth 60 second 3: arrived 100 queue depth 120 second 4: arrived 100 queue depth 180 second 5: arrived 10 queue depth 150 second 6: arrived 10 queue depth 120 second 7: arrived 10 queue depth 90 second 8: arrived 10 queue depth 60 second 9: arrived 10 queue depth 30
The queue climbs to 180 during the burst and then shrinks by 30 a second (40 handled minus 10 arriving). It is still at 30 in the last second shown and reaches 0 1 second later, because the consumer's capacity (40) is above the normal arrival rate (10).
Nothing was lost, and nobody had to size the consumer for the 100-per-second peak. The cost is delay: events at the back of the queue waited several seconds.
The condition for this to work is that the average arrival rate stays below capacity. If arrivals stay above 40, the queue grows forever and the delay grows with it. That is when you add consumers or slow the producers.
| Without a queue | With a queue |
|---|---|
| A burst overloads the consumer or is dropped | The burst waits in line |
| Producer and consumer must run at the same moment | They can run at different times, and the consumer can restart |
| One consumer only, usually | Several consumers can read the same events independently |
Try a new scenario
Events arrive at a steady 60 per second for an hour, and your consumer handles 50 per second. What happens to the queue, and what are your options?
Work it out, then open the answer
The queue grows by 10 events a second. After an hour it holds 36000 events, and the delay keeps growing. A queue cannot fix a consumer that is slower than the average arrival rate. Add worker consumers, speed up the handler, or reduce what is sent. (A later lesson shows how partitions let multiple consumers share the work).
What is backpressure?
It is what happens when a consumer cannot keep up with producers. A queue absorbs short mismatches, but if the gap is permanent the queue grows without limit. Systems respond by slowing producers, adding consumers, or dropping data on purpose.
Close the lesson and explain it
Without scrolling up, explain how a queue absorbs a burst, and the one condition that makes it work.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.