
Overview
At-most-once can drop events. At-least-once can duplicate them. Exactly-once is hard because the bookmark commit and the write are 2 steps. Idempotent consumers close the gap.
On this page8 sections
The idea
Picture a program that reads payment events one at a time and adds a row to the warehouse for each. Halfway through the day the machine it runs on loses power. When it starts again, what should it do?
As established in [Offsets and commits](/learn/streaming-queues/stream-offsets), stream consumers read records sequentially from partitions and commit offset bookmarks back to the broker. When a consumer writes an event to a database and commits its offset to Kafka, it executes two separate network operations.
Reading an event is not the same as finishing with it, so the consumer also commits its offset, which means saving the bookmark somewhere safe so that a restart can pick up from there.
That leaves 2 jobs per event: write the row, and commit the bookmark. Delivery semantics describe what you can promise about the result if a crash lands between them.
- At-most-once: each event is handled one time or not at all. You might lose events, but you never double-count.
- At-least-once: each event is handled one time or more. You never lose one, but you might see it twice.
- Exactly-once: each event has exactly one effect on the result, even if the consumer crashes and restarts.
Think of a postal clerk who stamps a parcel and then writes its tracking number in a ledger.
If the clerk stamps, faints, and the replacement finds an unrecorded parcel, they stamp it a second time. If the clerk writes the ledger first and faints before stamping, the parcel is recorded but never stamped.
Both failures come from 2 steps that cannot happen together. Each delivery promise is a different way of choosing which failure you can live with.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| At-least-once | Every event is delivered, but some may be delivered twice |
| Exactly-once | Every event is counted once and only once |
| Idempotent | Safe to do twice |
| Offset | The position of an event in the log |
| Zombie | An old worker that does not know it was replaced |
| Commit | Record that you finished processing up to a point |
Why this exists
The crash is only a problem because writing and committing are two separate actions. Between them there is a small gap, and the order you choose decides what a crash in that gap costs you.
Say the log holds 3 events and the bookmark is at 0.
The log. The consumer has read nothing yet.
| offset | order_id | amount |
|---|---|---|
| 0 | ORD-1 | 120.50 |
| 1 | ORD-2 | 40.00 |
| 2 | ORD-3 | 88.25 |
First choice: write the row, then commit. The consumer writes ORD-2 and the machine dies before the commit.
The saved bookmark still says 1, so on restart the consumer reads ORD-2 again and writes it a second time. That is at-least-once, and the warehouse now has ORD-2 twice.
Second choice: commit, then write. The consumer commits the bookmark past ORD-2, then dies before writing. On restart it starts at ORD-3 and never goes back. ORD-2 is gone. That is at-most-once.
Correct revenue is 248.75. The third row is the one we are after.
| Order of steps | Warehouse after a crash on ORD-2 and a restart | Revenue |
|---|---|---|
| Commit, then write (at-most-once) | ORD-1, ORD-3 | 208.75 (40.00 missing) |
| Write, then commit (at-least-once) | ORD-1, ORD-2, ORD-2, ORD-3 | 288.75 (40.00 counted twice) |
| Write by key, then commit | ORD-1, ORD-2, ORD-3 | 248.75 |
Which mistake would you rather have? For payments, orders and balances, a duplicate you can detect beats a gap you may never notice, so most pipelines pick write-then-commit and deal with duplicates.
With enable.auto.commit=true the client saves the offset of what it fetched on a timer, not of what you finished. A crash after the timer fires but before your write skips those events.
Picture this
The warehouse write and the bookmark commit are separate calls. A crash between them is the whole problem.
The first three boxes are the happy path. The red box says where things go wrong. Whether that crash gives you a gap or a duplicate depends only on which of the two middle steps you put first.
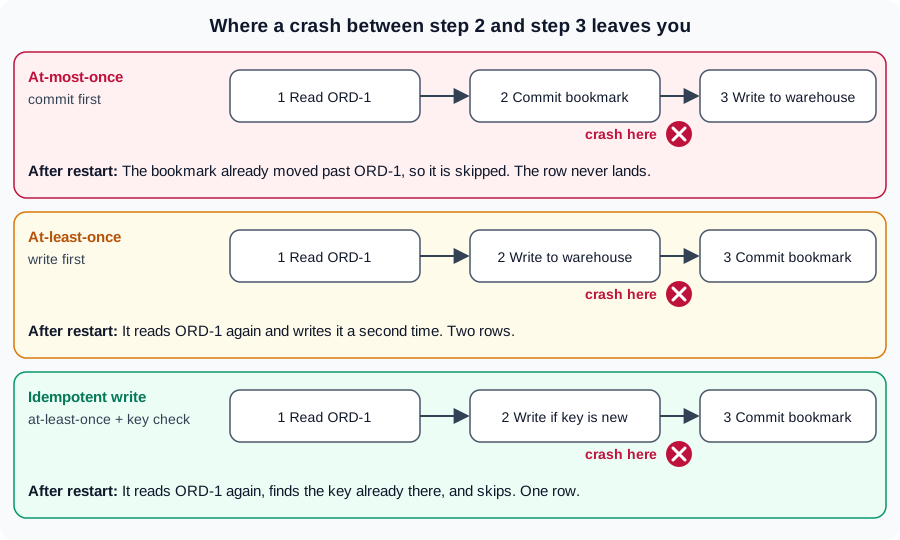
Each lane is one ordering. The red cross marks the crash. The line under each lane says what the warehouse looks like after the restart.
The bottom lane is the same ordering as the middle one, with one change in how the write works. We cover that change next.
Look at the middle and bottom lanes together. Both write first, both crash in the gap, both redeliver the event. The only difference is the sink.
A naive sink appends blindly, so the repeat becomes a second row. An idempotent sink recognises the key and changes nothing.
A small example
Time to run all three. The code below has a consumer that can be told to crash on a chosen order, between its 2 steps. We run it once with the crash and once more after the "restart", starting from the saved bookmark.
log = [
    {"order_id": "ORD-1", "amount": 120.50},
    {"order_id": "ORD-2", "amount": 40.00},
    {"order_id": "ORD-3", "amount": 88.25},
]

def consume(log, bookmark, write, commit_first, crash_on=None):
    """Read from the bookmark onward. Return (new bookmark, status)."""
    offset = bookmark
    while offset < len(log):
        event = log[offset]
        if commit_first:
            bookmark = offset + 1              # commit
            if event["order_id"] == crash_on:
                return bookmark, "crashed"
            write(event)                       # write
        else:
            write(event)                       # write
            if event["order_id"] == crash_on:
                return bookmark, "crashed"
            bookmark = offset + 1              # commit
        offset += 1
    return bookmark, "done"

def run(commit_first, write):
    bookmark, status = consume(log, 0, write, commit_first, crash_on="ORD-2")
    print("first run:", status, "bookmark", bookmark)
    bookmark, status = consume(log, bookmark, write, commit_first)
    print("restart:  ", status, "bookmark", bookmark)

# At-most-once: commit, then write
rows = []
run(True, rows.append)
print([r["order_id"] for r in rows], sum(r["amount"] for r in rows))
print()

# At-least-once: write, then commit
rows = []
run(False, rows.append)
print([r["order_id"] for r in rows], sum(r["amount"] for r in rows))first run: crashed bookmark 2 restart: done bookmark 3 ['ORD-1', 'ORD-3'] 208.75 first run: crashed bookmark 1 restart: done bookmark 3 ['ORD-1', 'ORD-2', 'ORD-2', 'ORD-3'] 288.75
There are your two bugs. In the first run the bookmark jumped to 2 before the write, so ORD-2 is missing. In the second the bookmark stayed at 1, so ORD-2 was written twice.
Now the fix that most teams use. Keep write-then-commit, so nothing is ever lost, and change the write so that doing it twice leaves the same result.
A write like that is called idempotent. Here the warehouse is a dict keyed by order_id, so writing ORD-2 again just overwrites the row it already put there.
# Still write, then commit. But the write is an upsert on order_id.
table = {}

def upsert(event):
    table[event["order_id"]] = event

run(False, upsert)
print(list(table), sum(r["amount"] for r in table.values()))first run: crashed bookmark 1 restart: done bookmark 3 ['ORD-1', 'ORD-2', 'ORD-3'] 248.75
The consumer still delivered ORD-2 twice. The warehouse just does not mind. This is how many real pipelines reach "exactly 1 row per order" without any special transaction machinery. A set of keys you have already seen would do the same job.
The idea has to be built into the write itself. Here is a second case, from a stock table, that shows the difference between a safe write and an unsafe one.
-- Not safe to replay: a second delivery subtracts again
UPDATE stock SET qty = qty - 1 WHERE sku = 'SKU-9';

-- Safe to replay (PostgreSQL): the order_id is the key, a repeat changes nothing
INSERT INTO sales (order_id, sku, qty)
VALUES ('ORD-2', 'SKU-9', 1)
ON CONFLICT (order_id) DO NOTHING;
Subtracting one is not idempotent: run it twice and you have removed two. Inserting a row whose key already exists, and being told to ignore the repeat, is idempotent. You can then compute the stock from the sales rows.
Making writes idempotent is the most practical way to get exactly-once results across separate systems. You do not need a transaction across both if the destination recognises a repeat.
| Sink | How it ignores a repeat |
|---|---|
| PostgreSQL, MySQL | A unique key on order_id with INSERT ... ON CONFLICT DO NOTHING |
| Iceberg, Delta Lake | Store the source offsets in the same table commit, so a replay is detected |
| Event tables where upserts are costly | A fast cache (Redis) of recently seen keys, checked before writing |
What does Kafka's own exactly-once cover?
Kafka can make a read-process-write loop atomic when both the input and the output are Kafka topics: the new messages and the new bookmark commit together or not at all. It also numbers each producer's messages, so a retried send is not stored twice.
That protection ends at Kafka's edge. It cannot stretch a transaction across Snowflake or PostgreSQL, so for those sinks you still make the write safe to repeat.
What is a zombie worker?
A worker freezes for a long pause, the group decides it died and hands its lane to a second worker, then the first one wakes up and keeps writing.
Two writers now own the lane. The fix is a fencing token: each owner gets a rising number, and the storage rejects writes carrying an older number.
Some tools offer an exactly-once setting. It usually works by one of two tricks: a transaction that covers the write and the commit together, or a write that tolerates repeats. The transaction version only works where both steps live in the same system. Across a log and a warehouse, you are back to making your write idempotent.
- Decide whether a lost event or a duplicate event hurts more. For money, orders and balances, duplicates are easier to live with.
- Write first, then commit the bookmark, so a crash between the 2 steps repeats an event instead of losing it.
- Make the write safe to repeat, on a key such as order_id.
- Describe the whole path honestly. If the write is not safe to repeat, the pipeline is at-least-once, whatever a setting says.
Common beginner questions
Databases have transactions. Why is this hard?
A transaction protects steps inside one system. Here the bookmark lives with the log and the row lives in the warehouse. Two systems, two commits, and a crash can land between them. A transaction across both needs special machinery and is usually slower.
Is idempotent the same as exactly-once?
Not quite. Idempotent means that doing the work twice leaves the same final state as doing it once. The event may still be processed twice. What the reader of the table sees matches exactly-once, and that is usually what you care about.
Should I pick at-most-once to avoid duplicates?
Only if losing an event is fine, as it can be for some click counters or debug traces. Orders, payments and balances are not that kind of data.
What if my sink cannot be idempotent, like sending emails?
When calling third-party services that have permanent real-world side effects (such as sending emails or charging credit cards), you cannot simply repeat writes. Instead, use an outbox table or reservation token pattern: record the intended action in a local database table first with a unique idempotency key, commit it with your business transaction, and have a dedicated dispatcher execute the external API call using that key.
Log: Three payments sit in the log: ORD-1 (120.50), ORD-2 (40.00), ORD-3 (88.25). The correct revenue is 248.75.
- ORD-1
- ORD-2
- ORD-3
- 248.75
At-most-once: Commit first, then write. The machine dies on ORD-2 after the commit. ORD-2 is gone and revenue shows 208.75.
- commit
- crash
- gap
At-least-once: Write first, then commit. The machine dies on ORD-2 before the commit. ORD-2 is written twice and revenue shows 288.75.
- write
- crash
- duplicate
Idempotent write: Keep write-then-commit, but write by key. The second ORD-2 lands on the same key and changes nothing.
- write by key
- crash
- same row
Warehouse: Revenue is 248.75 again, even though ORD-2 was delivered twice. That is how most pipelines get exactly-once results.
- delivered twice
- stored once
What comes next
This lesson covered the three delivery promises and why exactly-once is hard. The next lesson explores late data: what happens when network delays or offline devices deliver events with old timestamps.
Practice
Run the sample, then open the exercise. Write semantics() to tell which delivery promise a run kept, by comparing what was sent with what arrived. Use it on the three cases in the exercise, store the list in result, and print it.
Going deeper: what exactly-once can and cannot promise
The lesson above taught you the crash window between a write and a commit. This section adds the part that confuses people in interviews: three different systems each make a promise, and 'exactly-once' means something different at each of them.
If you mix the layers up, you either claim a guarantee you do not have, or you dismiss a real one.
3 layers, three different promises
Check the layer before you use the words 'exactly-once'.
| Layer | Question it answers | Typical mechanism | What it cannot cover |
|---|---|---|---|
| 1. Delivery into the log | If the producer retries a send, does the log end up with the record twice? | Idempotent producer: the broker remembers each producer's id and a sequence number per partition and drops a repeated sequence number. | A producer that restarts gets a new identity, so a re-send after a restart is a new record. It also covers 1 partition at a time. |
| 2. Processing (read, compute, write back to the log) | If a consumer crashes midway, is the output appended once and the input position moved forward in the same step? | Kafka transactions: output records and the consumer offsets are committed atomically. Downstream readers set isolation.level=read_committed so they skip aborted data. | Only the data that lives inside Kafka. A database row or an HTTP call is outside the transaction. |
| 3. The sink (database, lake table, email, payment API) | If the same event reaches the sink twice, does the business state change twice? | A stable event key with an upsert, a unique constraint, or a transaction that writes the data and the position together. | A sink that cannot recognise a repeat, such as 'send an email' or 'subtract 1'. |
A broker cannot make your database idempotent. Each layer has to earn its own promise.
Trace one payment through every failure point
Event pay-77 for 40.00 travels producer to log to consumer to warehouse. Walk the timeline and, at every row, ask: if the machine dies right here, what do we see after the restart?
Without step 2's protection the log holds the payment twice. Without step 4's protection the warehouse holds it twice.
| Step | What happens | If it fails here | What protects you |
|---|---|---|---|
| 1 | Producer sends pay-77 with sequence 0 | The send may or may not have reached the broker | Producer retries the same record |
| 2 | Broker appends it at offset 41, but the acknowledgement is lost on the network | Producer believes it failed and sends it again | Idempotent producer: the broker sees sequence 0 again and discards the copy |
| 3 | Consumer reads offset 41 | Nothing is changed yet, so a crash here is harmless | Nothing needed |
| 4 | Consumer writes the row to the warehouse | Crash after this line, before step 5 | The write must tolerate a repeat |
| 5 | Consumer commits offset 42 | Crash before this line means the event is read again | Sink key on event_id (the upsert from step 4) |
| 6 | Restart: consumer resumes at the last committed offset | It re-reads pay-77 | Step 4 finds the key and changes nothing |
The next program replays steps 1 to 6 with the protections switched on and off, so you can see each layer do its job.
class Broker:
    def __init__(self, idempotent):
        self.log, self.idempotent, self.last_seq = [], idempotent, {}

    def append(self, producer_id, seq, payload, ack_lost):
        if self.idempotent and self.last_seq.get(producer_id, -1) >= seq:
            return "ack"                     # repeat of a known sequence: do not append
        self.log.append(payload)
        self.last_seq[producer_id] = seq
        return None if ack_lost else "ack"

def produce(idempotent):
    b = Broker(idempotent)
    ev = {"event_id": "pay-77", "amount": 40.0}
    if b.append("P1", 0, ev, ack_lost=True) is None:   # the ack never arrives
        b.append("P1", 0, ev, ack_lost=False)          # producer retries
    return b.log

for idem in (False, True):
    print("idempotent producer =", idem, "-> records in log:", len(produce(idem)))

log = produce(True) + [{"event_id": "pay-78", "amount": 10.0}]

def consume(sink_write):
    committed = 0
    for crash in (True, False):                # first run crashes, second run is the restart
        off = committed
        while off < len(log):
            sink_write(log[off])               # step 4: write
            if crash and off == 0:
                break                          # dies before step 5
            committed = off + 1                # step 5: commit
            off += 1

appended = []
consume(appended.append)
print("append sink:", [r["event_id"] for r in appended], sum(r["amount"] for r in appended))

keyed = {}
consume(lambda e: keyed.__setitem__(e["event_id"], e))
print("keyed sink: ", list(keyed), sum(r["amount"] for r in keyed.values()))
Before you open the output: with the plain broker the lost acknowledgement causes a retry. How many records do you expect in the log? And what will the append sink hold after the crash and restart, compared with the keyed sink?
idempotent producer = False -> records in log: 2
idempotent producer = True -> records in log: 1
append sink: ['pay-77', 'pay-77', 'pay-78'] 90.0
keyed sink:  ['pay-77', 'pay-78'] 50.0
Read the output as a checklist. The idempotent producer fixed the log (1 record, not 2). The keyed sink fixed the warehouse (50.00, not 90.00). Those are two separate repairs, and neither one helps the other layer.
What you can and cannot honestly promise
Say exactly which boundary the guarantee covers.
| You can promise | You cannot promise |
|---|---|
| 1 row per event_id in the warehouse table after any number of replays. | That the network delivered each message once. It cannot be guaranteed; retries are the reason this topic exists. |
| Kafka-to-Kafka jobs commit their output and input position together (transactions). | That an email, SMS or webhook went out once, unless the other service accepts an idempotency key. |
| A repair path: replay from the log and converge to the same table. | That the event key is stable. If your code generates a new UUID on every retry, the sink sees a different key each time and deduplicates nothing. |
Create the event_id once, where the event is born (the order service), and carry it with the event. A key created inside the consumer or inside the retry loop changes on every attempt, which defeats the whole idea.
Misconceptions to unlearn
| Belief | Why it fails | Better version |
|---|---|---|
| 'Exactly-once delivery exists.' | The sender can never be sure whether a lost acknowledgement means the message or only the reply was lost. | Aim for exactly-once effect: at-least-once delivery plus a safe repeat. |
| 'Our broker has transactions, so we are done.' | Transactions stop at the edge of Kafka. The warehouse write is a second system. | Decide the guarantee per hop and test each one. |
| 'Idempotent means it never runs twice.' | It means running twice leaves the same result as running once. | Expect repeats; make them harmless. |
Try a new scenario (do not look at the answer yet)
A consumer reads user_signed_up events. For each event it inserts a row into the users table and sends a welcome email. The consumer crashes after sending the email but before committing the offset. Design it so the user gets at most one email and exactly one users row.
Your design, then compare
Users table: unique key on user_id, so the insert is an upsert and a replay changes nothing. Email: it lives outside your database, so record 'welcome email sent for user_id' in a table with a unique key, and check it before sending. Best case, give the email provider an idempotency key such as the user_id. Order the work as: insert user and a 'send pending' row in one database transaction, send the email, then mark it sent. A crash between sending and marking can still produce one extra email on replay. State that honestly: for external side effects the achievable goal is at-least-once with de-duplication, and you decide whether one rare duplicate email is acceptable.
Why not commit the offset first so the email can never repeat?
Then a crash after the commit and before the send loses the email silently. A duplicate email is annoying and visible; a missing welcome email is invisible. For most products, duplicates you can detect beat gaps you cannot.
Close the lesson and explain it
Without scrolling up, explain the difference between delivery, processing and sink guarantees. Then answer: a service generates a new UUID for every retry of the same order. Which of the 3 layers breaks, and why?
Check yourself
The sink breaks. Each attempt looks like a new event, so the unique key never matches and a duplicate row is written. The fix is to create the id once at the source and carry it with every retry.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.