
Overview
A dbt project is a folder of SQL files plus a few YAML files. Staging models clean one raw table each, and marts answer business questions.
On this page8 sections
The picture
When you clone a dbt repository for the first time, you might expect a desktop app with graphical menus and buttons.
Instead, you find a directory of plain text files organized on your computer: SQL models and YAML configuration files.
What does a dbt project look like on disk?
Every dbt project across the analytics industry follows the same standard directory layout.
Once you learn this layout, you can navigate any dbt repository in minutes.
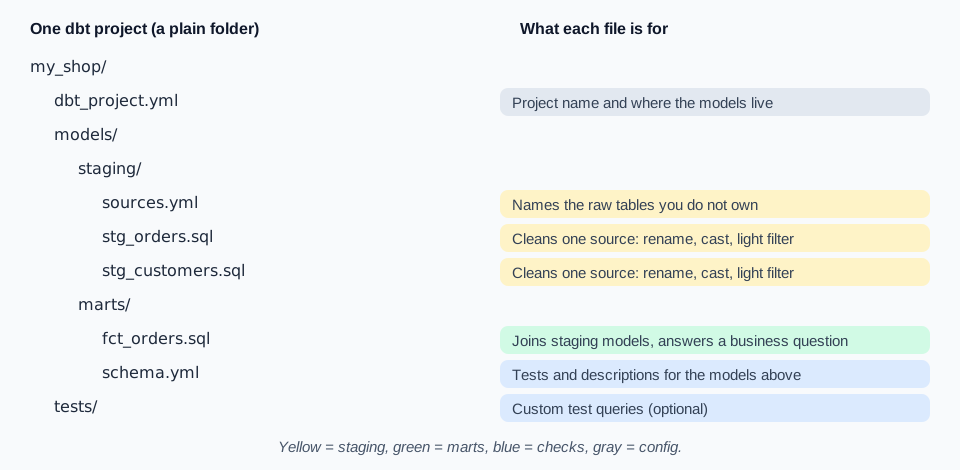
The root directory holds the main configuration file that tells dbt how to connect to your warehouse.
The models folder separates lightweight staging cleanup from aggregated business marts.
Every dbt project is a structured directory of SQL queries and YAML configurations.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Project | The folder that holds all your dbt files |
| dbt_project.yml | The main settings file at the top of the project |
| Models folder | Where your SQL SELECT files live |
| YAML | A plain text format for settings, written as indented key: value lines |
| Source | A raw table that dbt reads but does not build |
| Lineage | A map of which table is built from which |
Why this shape
Teams require strict structural boundaries to prevent unmaintainable query sprawl.
What breaks when teams put all queries into one folder?
Picture a project where teammates save cleanup code and reporting queries in the same directory without conventions.
Different analysts copy raw table references into multiple personal queries without coordination.
Structured folders prevent source changes from breaking downstream queries.
| Folder layout | How changes work | Risk when source changes |
|---|---|---|
| Unstructured folder | Raw tables copied across 12 files | Upstream rename breaks dozens of queries |
| Standard dbt layout | Raw tables cleaned once in staging | Upstream rename requires editing exactly 1 file |
The folder structure solves this problem directly.
Staging models clean raw sources once, while marts join clean models to answer business questions.
Staging models clean each source once so upstream schema updates touch 1 file.
What role do YAML configuration files play in the project?
YAML is a structured text format that uses indented key and value pairs.
dbt uses YAML files to declare sources, document models, and attach automated tests.
version: 2

sources:
  - name: ecommerce
    tables:
      - name: orders

models:
  - name: stg_orders
    columns:
      - name: order_id
        data_tests:
          - not_null
          - unique
In sources.yml, you register external tables loaded by data engineers that you did not build.
In schema.yml, you attach tests so corrupt rows fail the build before reaching reports.
In dbt Core 1.8 and later (including 1.12), test definitions use the data_tests key, while older versions used tests.
Walk the boxes
Let us walk through each path in the project hierarchy and its specific job.
What is the responsibility of each folder in the project?
Each directory isolates one distinct phase of the data transformation lifecycle.
Each path and its job.
| Path | What it is | What goes in it |
|---|---|---|
| dbt_project.yml | Project settings | Project name, profile connection, and default materializations |
| models/ | All SQL models | One .sql file per SELECT query; each file is one model |
| models/staging/ | Staging layer | Rename, cast, and light filter; no joins, no aggregations |
| models/marts/ | Marts layer | Joined, aggregated tables that BI analysts query |
| seeds/ | Static reference CSVs | Small CSV lookup tables loaded via dbt seed, like country codes |
| tests/ | Custom test queries | Singular SQL tests that fail if they return any rows |
Notice that the term model appears repeatedly across these directories.
In dbt, a model is simply a SELECT statement saved in a .sql file, named after that file.
How does data flow across these project layers?
Data moves through the project directories in a clear, single direction.
Raw tables are named in sources.yml, cleaned by staging models, and combined by marts.
Data enters at the raw warehouse table and passes through exactly one staging model.
Marts combine clean staging models, and downstream dashboards query only the marts.
Beginners often join payments into stg_orders to save a step. Do not. Staging cleans one source. The moment it joins, a change to payments can break everything that reads orders. Put joins and grain changes in marts.
Marts query clean staging models, never messy raw tables directly.
How does dbt generate documentation and lineage graphs?
dbt generates comprehensive project documentation directly from your SQL and YAML files.
Self-generating documentation commands in dbt.
| Command | What it generates | How developers use it |
|---|---|---|
| dbt docs generate | manifest.json and catalog.json | Compiles lineage graph and column metadata |
| dbt docs serve | Local web server at port 8080 | Interactive DAG visualizer and searchable catalog |
The documentation site visualizes your end-to-end DAG lineage graph and displays column descriptions.
Developers inspect this visual graph to evaluate dependencies before modifying existing models.
A matching example
In this tab there is no file browser or command line. The SQL editor runs plain SQL in DuckDB.
A query in the editor stands in for the SQL inside a model file, like models/staging/stg_orders.sql.
What does a model-shaped query look like in SQL?
Here are 3 sample rows from the raw orders table landing in the warehouse:
Input: the raw orders table in the warehouse.
| order_id | user_id | order_status | order_total |
|---|---|---|---|
| ORD-0001 | U004 | paid | 612.07 |
| ORD-0002 | U073 | refunded | 446.70 |
| ORD-0003 | U078 | paid | 1104.32 |
Here is the SELECT statement that would live in models/staging/stg_orders.sql:
-- would live in models/staging/stg_orders.sql
SELECT
    order_id,
    order_status,
    order_total
FROM orders
LIMIT 10;
Predict what the output columns look like before checking the table below:
Output: 3 columns kept, user_id dropped because this model does not need it.
| order_id | order_status | order_total |
|---|---|---|
| ORD-0001 | paid | 612.07 |
| ORD-0002 | refunded | 446.70 |
| ORD-0003 | paid | 1104.32 |
3 columns are preserved, while user_id is dropped because this specific model does not need it.
When real dbt runs this file, it wraps the SELECT in CREATE VIEW stg_orders AS or CREATE TABLE automatically.
When you land in an unfamiliar dbt project, read dbt_project.yml and then the sources.yml under models/staging. Between them you know what the project is called, where it builds things, and which raw tables it starts from.
How does a request travel through the project folders?
Settings: dbt_project.yml defines project configurations and defaults.
- dbt_project.yml
- dbt engine
Staging: stg_orders.sql cleans raw orders registered in sources.yml.
- sources.yml
- stg_orders.sql
Marts: fct_orders.sql joins clean staging models to deliver business metrics.
- stg_orders.sql
- fct_orders.sql
Checks: schema.yml tests verify key constraints before dashboards refresh.
- fct_orders.sql
- BI reports
4 rules to remember about dbt project layout:
- A dbt project is a folder of SQL models and YAML configuration files on disk.
- Staging models clean one source table each without joins or aggregations.
- Marts combine clean staging models to answer business and analytical questions.
- YAML files register external sources, configure settings, and declare automated tests.
Common beginner questions
Do I need to memorise this folder layout?
No. It is an industry convention, and a project that breaks the convention still works. Learn the reason behind it: clean once in staging, answer questions in marts. The names will follow naturally.
Where do tests go, exactly?
Most teams write generic tests in a YAML file next to the models, like schema.yml. Custom tests that need a long SQL query live as .sql files in the tests/ folder. You will write both kinds later in this track.
Is a model the same as a table?
Close, but not quite. A model is the SELECT query in your file. What dbt builds from it can be a view, a table, or an incremental model, which you configure per model. The model is the recipe; the table is the dish.
What comes next
You can now read and navigate a dbt project layout.
The next lesson, Jinja basics, opens a model file and explains the curly-brace expressions called Jinja, showing what they compile to before the warehouse executes them.
Practice
The exercise asks for a model-shaped SELECT from orders with 3 columns, capped at 10 rows.
Treat what you type as the contents of a .sql file under models/. Write plain SQL only.
Going further: view or table, and when each goes stale
Every dbt model has a materialization setting that controls how its output is stored in the warehouse. A view stores the query and re-executes it every time someone reads it. A table stores the computed rows on disk at build time. Both come from the exact same SELECT statement, but they behave differently when raw data changes.
The example below creates a temporary raw table, builds a view and a table over it, and then inserts a new order. Predict how many rows the view and table return before revealing the output.
CREATE OR REPLACE TEMPORARY TABLE raw_orders AS
    SELECT 1 AS id, 'paid' AS status, 100.00 AS amount
    UNION ALL SELECT 2, 'paid', 250.00
    UNION ALL SELECT 3, 'cancelled', 80.00;

CREATE OR REPLACE VIEW paid_view AS
    SELECT * FROM raw_orders WHERE status = 'paid';

CREATE OR REPLACE TABLE paid_table AS
    SELECT * FROM raw_orders WHERE status = 'paid';

INSERT INTO raw_orders VALUES (4, 'paid', 60.00);

SELECT 'view' AS kind, COUNT(*) AS rows FROM paid_view
UNION ALL
SELECT 'table', COUNT(*) FROM paid_table;kind rows view 3 table 2
The view returns 3 rows because it evaluates the query against raw_orders on every read, picking up order 4 immediately. The table returns 2 rows because its data was frozen at build time and will not reflect order 4 until the next dbt build runs.
A table is fast to query but becomes stale between pipeline runs. A view is always current but pays the compute cost of the transformation query on every single read.
| Materialization | How it is stored | Recommended use | Trade-off |
|---|---|---|---|
| view | Saved SQL query | Light staging models and simple casts | Slow when stacked several layers deep |
| table | Physical rows on disk | Marts queried frequently by BI dashboards | Rebuild compute cost grows as table size increases |
| incremental | Physical rows, appending new records | High-volume event logs and audit streams | Requires unique keys and careful filter logic |
| ephemeral | Inlined CTE in dependent models | Lightweight intermediate calculations | Cannot be queried directly or tested in isolation |
In standard dbt project layouts, staging models default to views (cheap renames and casts), while marts default to tables. You configure these defaults in dbt_project.yml and can override them on individual models.
Try a new scenario
A BI dashboard queries a mart that joins five large tables. The dashboard takes 45 seconds to refresh on every user visit because the mart is materialized as a view. What configuration change resolves this, and what is the operational trade-off?
Work it out, then open the answer
Change the mart materialization from view to table in dbt_project.yml or inside the model config. The warehouse joins the 5 tables once during the scheduled dbt build instead of re-running the join on every dashboard visit. The trade-off is staleness: dashboard data is as fresh as the last pipeline build schedule.
What is a seed in dbt, and when should you use it?
A seed is a CSV file placed in the seeds/ folder that dbt loads into the warehouse using the dbt seed command. Use seeds for small, static reference datasets like postal codes, tax rates, or country mappings. Never use seeds for large or frequently changing transactional data.
Close the lesson and explain it
Without scrolling up, explain the core difference between view and table materializations, and why marts usually build as tables.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.