
Overview
{{ source('jaffle', 'orders') }} compiles to orders and {{ ref('stg_orders') }} to stg_orders. You do the swap by hand.
On this page8 sections
What you will do
When an upstream data ingestion team renames an operational table in the warehouse, every query hardcoding that table breaks simultaneously.
If many reporting queries hard-code that raw name, someone has to search for, edit and test every one of them by hand.
With dbt, models reference external data through source() and internal models through ref(). When a raw table moves, you edit exactly one YAML file and every downstream model recompiles cleanly.
Last lesson you saw that ref() and source() become table names.
Now you will use that fact to understand something bigger: how dbt knows which model to build first.
Then you will practise the compile step on a source() call.
What will you build and verify in this lab?
You will trace how dbt collects dependency calls from SQL models to construct a directed execution graph.
In plain words: source() is how a model says "this table was loaded by someone else, outside dbt". ref() is how a model says "this table is built by another dbt model". Because every ref() names its parent, dbt can work out the build order by itself.
You will declare external raw tables in YAML, test source freshness, and compile source calls into physical relations.
source() declares external raw tables; ref() links internal models into an execution DAG.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Source | A raw table that was loaded by someone else |
| ref() | A link from one model to another model |
| DAG | The build order drawn as boxes and arrows |
| Freshness | How recently a source table received new rows |
| Selector | A short pattern that picks which models to run |
| Schema | A named folder of tables inside the warehouse |
Why this skill
Picture a project with 40 models.
Some read raw tables, some read other models.
If you ran them in alphabetical order, a model that needs stg_orders might run before stg_orders exists, and fail.
If you hard-code a table name, dbt has no way to see the dependency at all.
Why can you not run warehouse models in alphabetical order?
Alphabetical execution ignores data dependencies.
When downstream marts build before upstream staging models finish, the warehouse throws missing relation errors.
dbt schedules work based on declared references rather than arbitrary file names.
Declaring explicit dependencies allows dbt to order runs reliably without manual scheduling.
How does dbt turn dependencies into an execution graph?
source() and ref() make model dependencies visible to the compiler.
source() says this is a raw table loaded by an external tool.
ref() says this is another model created inside this project.
Both give dbt the information it needs, and both turn into plain table names at compile time.
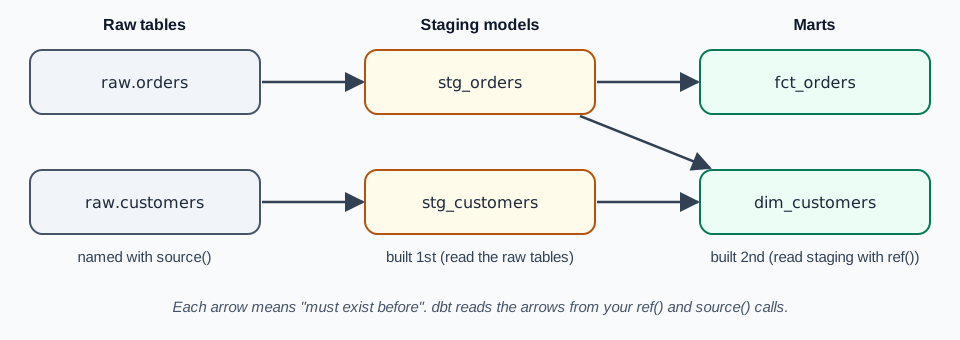
Left to right is the order of work. The two raw tables are named with source().
The two staging models read them, so they are built first. The marts read the staging models with ref(), so they are built last.
Notice stg_orders has two arrows leaving it: both marts need it.
This picture is a DAG, short for directed acyclic graph. Directed means arrows point forward, and acyclic means there are no loops.
dbt builds every parent model before the children that depend on it.
How the code works
source() needs a bit of setup before models can reference external tables.
You tell dbt about the raw table once, in a YAML file, and then every model refers to it by that name.
How do you declare raw external tables in sources.yml?
Raw ingestion tables reside in a sources.yml file inside your models directory:
version: 2

sources:
  - name: jaffle        # a label you choose for this group of raw tables
    schema: raw         # where the loader put them in the warehouse
    tables:
      - name: orders
The name jaffle is only a label you pick. The schema line is the real location.
Now a model can write {{ source('jaffle', 'orders') }}, and dbt looks the answer up in this file.
If the loader later moves the table to another schema, you change this 1 file.
How do source() and ref() differ in practice?
The two functions serve distinct roles across the transformation boundary:
The two dependency functions. Exact schema names depend on your project settings.
| Function | Points at | Compiles to (typical) | Where it is defined |
|---|---|---|---|
| {{ source('jaffle', 'orders') }} | A raw table you do not own | raw.orders | sources.yml |
| {{ ref('stg_orders') }} | A model in this project | analytics.stg_orders | stg_orders.sql |
source() abstracts unmanaged raw landing tables, whereas ref() links managed project models.
If model A refs B and B refs A, there is no first one to build. dbt refuses to run and prints a compilation error naming the loop. The fix is always to break the loop, usually by moving the shared part into a third model that both can read.
It is tempting to write FROM source(...) in a mart to skip staging. Then that mart gets the uncleaned columns and the cleaning rules are repeated in two places. Read staging models with ref() instead.
How does ref() resolve target schemas across environments?
When a model calls ref('stg_orders'), dbt dynamically checks the active target profile:
- Developer laptopcompiles to dbt_priya.stg_orders
- CI test runnercompiles to dbt_pr_104.stg_orders
- Production runcompiles to analytics.stg_orders
In development it compiles to your personal sandbox schema, preventing team collisions.
In production it compiles to the shared analytics schema automatically without altering model code.
How do graph selection operators target subsets of models?
In large projects with hundreds of models, rebuilding everything takes excessive compute.
The dbt CLI provides graph operators to select specific portions of the DAG:
dbt graph selection syntax for targeted execution.
| CLI command | What it selects | Common use case |
|---|---|---|
| dbt run --select stg_orders | Only the stg_orders model | Quick syntax check on a single file |
| dbt run --select stg_orders+ | stg_orders and all downstream children | Testing downstream impact of a staging change |
| dbt run --select +fct_orders | fct_orders and all upstream parents | Rebuilding a broken mart and its dependencies |
| dbt run --select @stg_orders | stg_orders, its children, and their parents | Running a self-contained pipeline slice |
Using graph operators saves warehouse credits by running only the models affected by your changes.
How do freshness tests catch upstream ingestion stalls?
Silent ingestion failures occur when third-party sync pipelines stall without raising errors.
You declare freshness thresholds in sources.yml using the loaded_at_field property:
version: 2

sources:
  - name: jaffle
    schema: raw
    loaded_at_field: _loaded_at
    freshness:
      warn_after: {count: 12, period: hour}
      error_after: {count: 24, period: hour}
    tables:
      - name: orders
Executing dbt source freshness queries the maximum timestamp in the raw table.
If records have not arrived within 24 hours, dbt halts dependent runs before dashboards display stale data.
How do you map messy upstream table identifiers cleanly?
Legacy databases often use irregular naming conventions like mixed casing or version numbers.
You can decouple clean model references from ugly physical table names using identifier:
version: 2

sources:
  - name: pos_backend
    schema: raw
    tables:
      - name: raw_transactions
        identifier: tbl_RAW_Transactions_v2
Models write {{ source('pos_backend', 'raw_transactions') }} without caring about the legacy name.
If the warehouse table name changes, you update only one line in sources.yml.
Worked examples
Let us walk through three concrete examples showing how source and ref work in real queries.
Example 1: How do you compile a source() call by hand?
Here is a model written with source(), and sample rows from the raw orders table:
Input: raw orders from the warehouse (first 3 rows).
| order_id | user_id | order_status | order_total |
|---|---|---|---|
| ORD-0001 | U004 | paid | 612.07 |
| ORD-0002 | U073 | refunded | 446.70 |
| ORD-0003 | U078 | paid | 1104.32 |
select order_id, user_id, order_total
from {{ source('jaffle', 'orders') }}
where order_total > 1000
order by order_id
limit 1;
In this tab, the editor evaluates standard SQL in DuckDB. Replace the source expression with the relation name orders:
SELECT order_id, user_id, order_total
FROM orders
WHERE order_total > 1000
ORDER BY order_id
LIMIT 1;
Output: 1 row with order_total over 1,000.
| order_id | user_id | order_total |
|---|---|---|
| ORD-0003 | U078 | 1104.32 |
The compiler replaces the source call with the warehouse relation name while preserving filters.
Example 2: How do you simulate ref() using a Common Table Expression?
There is no separate stg_orders table in this tab, but you can simulate one with a Common Table Expression:
The CTE stands in for the model that ref() would point at. Now a mart-style query reads it by name:
WITH stg_orders AS (
    SELECT
        order_id,
        user_id AS customer_id,
        order_status,
        order_total AS amount
    FROM orders
)
SELECT
    customer_id,
    ROUND(SUM(amount), 2) AS total_spent
FROM stg_orders
WHERE order_status = 'paid'
  AND customer_id IN ('U004', 'U057')
GROUP BY customer_id;
Output: U004 has two paid orders (612.07 and 311.70). U057's only order was cancelled, so U057 is filtered out.
| customer_id | total_spent |
|---|---|
| U004 | 923.77 |
In a real project the WITH block would be its own file, stg_orders.sql, and the line after it would say FROM {{ ref('stg_orders') }}.
The cleaning happens once, and every mart that reads it gets the same customer_id and amount.
Example 3: How does dbt schedule multi-wave execution waves?
Take an e-commerce platform like ShopKart with raw orders, customers and payments.
It would have three staging models, then one mart called fct_orders that refs all three and a second mart that refs fct_orders.
dbt reads those ref() calls and builds them in four waves. The three staging models are independent, so it can run them side by side.
Order comes from the ref() calls, not from file names.
| Wave | Models built | Why this wave |
|---|---|---|
| 1 | stg_orders, stg_customers, stg_payments | They only read raw sources |
| 2 | fct_orders | Needs all three staging models to exist |
| 3 | fct_customer_revenue | Needs fct_orders |
For a new model, trace its ref() calls on the graph with a finger. If you land on a box that isn't built yet, or you end up back where you started, fix that before you run anything.
What happens when a model creates a circular dependency cycle?
If model A references model B and model B references model A, neither model can execute first.
dbt identifies circular loops during graph compilation before dispatching SQL to the warehouse:
dbt.exceptions.CompilationError: Found a cycle in the model dependencies:
stg_orders -> customer_summary -> stg_orders
To resolve a circular loop, extract the shared columns or aggregations into a third independent staging model.
- Cycle detectedA refs B and B refs A
- Refactorextract shared logic to model C
- Valid DAGboth A and B ref C cleanly
Restructuring models to point downstream preserves the acyclic property required by the DAG compiler.
How does dbt trace dependencies from raw source to final mart?
Declare: sources.yml registers raw landing tables with freshness rules.
- sources.yml
- source() macro
Stage: stg_orders cleans raw fields using source('jaffle', 'orders').
- source() macro
- stg_orders.sql
Reference: fct_orders reads clean data using ref('stg_orders').
- stg_orders.sql
- fct_orders.sql
Schedule: dbt orders staging models in parallel wave 1 and marts in wave 2.
- fct_orders.sql
- Warehouse DAG
4 rules to remember about source and ref dependencies:
- source() references raw landing tables defined in sources.yml and supports freshness checks.
- ref() references internal models and resolves target schemas dynamically across environments.
- Dependencies form a DAG, so dbt runs upstream parent models before downstream children.
- Circular dependency loops halt compilation immediately; extract shared calculations to resolve cycles.
Common beginner questions
What is the difference between source() and ref()?
source() is for tables that exist before dbt does anything, like what a loader wrote. ref() is for models dbt builds itself. dbt also treats them differently: it can check how fresh a source is, and it builds every ref'd model before the one that uses it.
Does the first argument of source() mean something?
It is just a label from sources.yml, which you chose. The second argument is the table name in that group. Together they point to one entry in the YAML file.
Why does dbt forbid loops?
A loop would mean A needs B and B needs A, so neither can be built first. There is no valid order, so dbt stops before running any SQL.
What comes next
That finishes the free foundations. The next module goes into staging models proper: renaming, casting and lightly filtering a raw source, followed by the first tests, starting with not_null.
Practice
The exercise gives you a model that reads from source('jaffle', 'orders'), filters to paid orders and aliases a column. You write the compiled SQL with a 20 row limit. Replace the template, keep the alias and the filter exactly, and leave no curly braces behind.
Going further: why ref() beats a hard-coded name
source() and ref() are compiled into real table names, and the real name depends on where you run. In development, ref('orders') should point at your own schema. In production it should point at the shared one. A hard-coded name ignores the environment and, worse, can make a development run write into production.
The sketch compiles one model for two environments, once with ref() and once with a hard-coded name. Predict which one stays safe.
import re

def compile_sql(sql, schema):
    return re.sub(r"\{\{\s*ref\('(\w+)'\)\s*\}\}", lambda m: f"{schema}.{m.group(1)}", sql)

with_ref   = "create table {{ ref('revenue') }} as select * from {{ ref('orders') }}"
hard_coded = "create table analytics.revenue as select * from analytics.orders"

for environment, schema in [("dev", "dbt_alice"), ("prod", "analytics")]:
    print(environment, "| ref()      :", compile_sql(with_ref, schema))
print(environment, "| hard-coded :", compile_sql(hard_coded, schema))dev | ref() : create table dbt_alice.revenue as select * from dbt_alice.orders dev | hard-coded : create table analytics.revenue as select * from analytics.orders prod | ref() : create table analytics.revenue as select * from analytics.orders prod | hard-coded : create table analytics.revenue as select * from analytics.orders
With ref(), the dev run writes to dbt_alice.revenue and the prod run to analytics.revenue, from 1 file. The hard-coded version is identical in both environments, so a developer testing a change overwrites the production table. That is the real-world cost of a hard-coded name.
| You write | dbt produces | Why it matters |
|---|---|---|
| {{ ref('orders') }} | The schema for the current environment | Safe in dev and prod, and recorded in lineage |
| {{ source('shop', 'orders') }} | The raw table, as declared in sources | One place to rename it, and freshness checks |
| analytics.orders | The same text everywhere | Breaks isolation and hides the dependency |
Try a new scenario
The raw table shop.orders is renamed by the data platform team to shop.orders_v2. You have 14 models that read it. How many places do you change if they use source(), and how many if they hard-code the name?
Work it out, then open the answer
With source(), you change one line in the sources file and all 14 models follow. With a hard-coded name, you edit all 14 files and risk missing one, which then fails or reads a stale table. That is the maintenance argument for source() in addition to the environment argument.
When do you use source() and when ref()?
Use source() for raw tables loaded by something outside dbt. Use ref() for models that dbt itself builds. That split lets dbt track lineage from raw tables through every model.
Close the lesson and explain it
Without scrolling up, explain how ref() keeps development and production separate and what a hard-coded table name risks.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.