
Overview
{{ ref('stg_orders') }} turns into a table name when dbt compiles. {% if %} is template logic. Jinja does not run in this tab, so you write the compiled SQL.
On this page8 sections
What you will do
Open almost any dbt model file and you will see SQL mixed with curly braces, like FROM {{ ref('stg_orders') }}.
If you paste that directly into a database console, the database halts with an error. Those braces are Jinja templating, and today you learn how they compile into plain database code.
What happens when you mix Jinja templates into SQL?
By the end of this lab, you will look at any templated model and write down the exact SQL it produces.
That compiled SQL is what your warehouse executes, and it is what you type in this lesson editor.
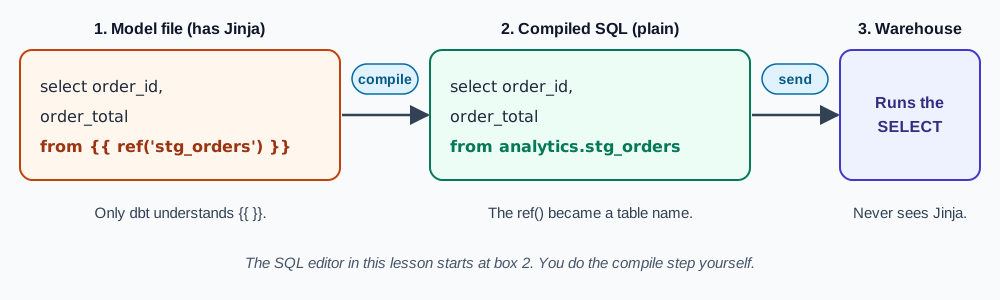
The left box shows what you author with Jinja.
The middle box shows what dbt compiles with templates removed.
The right box shows the warehouse receiving only plain SQL.
The warehouse never sees Jinja; it receives only compiled SQL.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Jinja | A small templating language. It lets SQL files contain simple logic |
| Template | A file with blanks that get filled in before it runs |
| Macro | A reusable snippet, like a function for SQL |
| ref() | Points to another model by name, so dbt works out the table for you |
| source() | Points to a raw table by name |
| Compile | Turn the template into plain SQL that the warehouse can run |
Why this skill
Hardcoding schema names and table paths in SQL makes analytics projects fragile and difficult to test.
Why should you avoid hardcoding table names directly?
In production, stg_orders lives under analytics.stg_orders. In development, you need it in your private schema like dev_priya.stg_orders so you do not overwrite production tables.
If every query hardcodes physical schemas, switching environments requires editing dozens of files by hand.
Jinja ref() decouples queries from hardcoded physical schemas.
| Query style | How environment changes work | Lineage tracking |
|---|---|---|
| Hardcoded FROM analytics.orders | Manual text replace across files | Invisible to dbt compiler |
| Dynamic FROM {{ ref('orders') }} | Automatic schema resolution | Builds DAG dependencies automatically |
Jinja enables models to run cleanly across local development, staging, and production environments.
When a query fails in the warehouse, the error points to line numbers in the compiled SQL, not your source file.
ref() discovers DAG dependencies and switches schemas automatically across environments.
How the code works
Jinja provides three different delimiters, distinguished by their bracket syntax.
What are the 3 core Jinja markers?
Each marker serves a distinct syntactic purpose during template compilation.
The three Jinja markers.
| Marker | Name | What it does | Example |
|---|---|---|---|
| {{ ... }} | Expression | Gets replaced by a value in the SQL text | {{ ref('stg_orders') }} |
| {% ... %} | Statement | Controls the template: if, for, set; leaves no text of its own | {% if target.name == 'dev' %} |
| {# ... #} | Comment | Removed completely during compilation | {# note to self #} |
Expressions are the most common marker. They evaluate Python-like functions and output raw text into SQL.
Statements manage template control flow like conditional branches and loops, leaving no text behind.
Comments wrapped in curly-hash pairs vanish entirely during the compilation phase.
If you paste {{ ref('orders') }} into the SQL editor the query fails, because the editor is a plain SQL engine with no Jinja step. Compile it yourself: replace the whole {{ ... }} with the table name, so FROM orders.
What are dbt macros and how do they work?
Writing custom macros turns repetitive SQL expressions into reusable functions across your project.
In dbt, macros live in the macros/ directory and are defined using the macro statement tag.
-- macros/cents_to_dollars.sql
{% macro cents_to_dollars(column_name) %}
    ROUND(CAST({{ column_name }} AS DOUBLE) / 100.0, 2)
{% endmacro %}
You invoke macros inside model SELECT queries just like built-in database functions.
When dbt compiles the file, the macro expands into standard SQL expressions before running in the warehouse.
Worked examples
Let us examine four concrete examples of Jinja compilation in action.
What happens when compiling a single ref function?
Here is a minimal model file in models/marts/orders_summary.sql:
SELECT
    order_id,
    order_total
FROM {{ ref('stg_orders') }};
During compilation, dbt substitutes the expression with the resolved warehouse relation name:
SELECT
    order_id,
    order_total
FROM analytics.stg_orders;
The warehouse executes the compiled SQL without ever seeing the Jinja syntax.
What is the difference between source and ref?
Both functions resolve into physical table names, but dbt treats them differently in the dependency graph.
Jinja expressions and what is left after compile. Schema names depend on target profile settings.
| In the model file | After compile (typical) | It points at |
|---|---|---|
| {{ ref('stg_orders') }} | analytics.stg_orders | Another model in this project |
| {{ source('ecommerce', 'orders') }} | raw.orders | A raw table you do not own |
| {{ config(materialized='table') }} | (empty text) | A setting for dbt, removed from SQL |
ref points to models you author, while source points to external raw tables loaded by data engineers.
How does a Jinja loop generate repetitive SQL columns?
Consider a payments table where finance wants total revenue pivoted per payment method.
Instead of hand-coding repetitive CASE statements, write a Jinja loop:
SELECT
    order_id,
    {% for method in ['card', 'upi', 'netbanking'] %}
    ROUND(SUM(CASE WHEN method = '{{ method }}' THEN amount ELSE 0 END), 2) AS {{ method }}_amount{% if not loop.last %},{% endif %}
    {% endfor %}
FROM {{ ref('stg_payments') }}
GROUP BY order_id;
The compiler loops through each item and produces clean standard SQL:
SELECT
    order_id,
    ROUND(SUM(CASE WHEN method = 'card' THEN amount ELSE 0 END), 2) AS card_amount,
    ROUND(SUM(CASE WHEN method = 'upi' THEN amount ELSE 0 END), 2) AS upi_amount,
    ROUND(SUM(CASE WHEN method = 'netbanking' THEN amount ELSE 0 END), 2) AS netbanking_amount
FROM analytics.stg_payments
GROUP BY order_id;
Adding a fourth payment method requires updating one list item without rewriting repetitive SQL logic.
How do you compile a model query by hand in this editor?
The editor accepts only standard SQL, so you perform the compilation step manually.
Suppose the source model reads:
SELECT
    order_id,
    order_status,
    order_total
FROM {{ ref('orders') }}
WHERE order_status = 'paid'
LIMIT 5;
Replace the template with the known table name orders:
SELECT
    order_id,
    order_status,
    order_total
FROM orders
WHERE order_status = 'paid'
LIMIT 5;
Output on the seeded orders table: only paid orders are returned.
| order_id | order_status | order_total |
|---|---|---|
| ORD-0001 | paid | 612.07 |
| ORD-0003 | paid | 1104.32 |
| ORD-0005 | paid | 261.73 |
| ORD-0006 | paid | 431.34 |
| ORD-0007 | paid | 396.72 |
A very common slip is to change the table name but leave {{ and }} behind, like FROM {{ orders }}. The braces are part of the template syntax, so they must go too. What remains has to be plain SQL.
The warehouse only ever saw the compiled SQL, so its error line numbers point there. Open the copy under target/compiled/, not your source file, and the line numbers will match.
How do you conditionally limit query volume in development?
dbt exposes built-in environment context so you can adjust behavior between development and production runs.
SELECT *
FROM {{ ref('stg_orders') }}
{% if target.name == 'dev' %}
LIMIT 500
{% endif %};
In development environments, the query processes only 500 rows to conserve compute and reduce build time.
In production, the condition evaluates to false and dbt compiles the query without the limit clause.
How do you debug compilation errors before warehouse execution?
When a Jinja tag is missing or misnamed, dbt halts with a compilation error before running SQL.
- Write modelSQL + Jinja tags
- dbt compileparses templates locally
- Inspect target/view compiled .sql
- dbt runexecutes against warehouse
Executing dbt compile verifies syntax and outputs rendered SQL into the target/ directory.
Inspecting target/compiled/ allows engineers to catch malformed SQL before running costly warehouse queries.
How does compilation transform a model from template to warehouse?
Template: write SQL models containing ref() calls and Jinja macros.
- Model .sql
- Jinja compiler
Compile: dbt resolves relations, evaluates loops, and strips markers.
- Jinja compiler
- Compiled SQL
Inspect: rendered SQL sits in target/compiled/ for debugging.
- Compiled SQL
- target/ directory
Warehouse: database executes clean compiled SQL without templates.
- Compiled SQL
- Warehouse engine
4 rules to remember about Jinja in dbt:
- Expressions {{ }} output values, statements {% %} control logic, and comments {# #} vanish.
- ref() dynamically discovers dependencies and resolves target schemas across environments.
- source() points to raw landing tables declared in sources.yml.
- The warehouse only ever receives compiled SQL; inspect target/ to debug syntax issues.
Common beginner questions
Do I need to learn all of Jinja?
No. Most dbt work uses ref(), source(), config() and the occasional if condition or for loop. Learn those first. When you meet something unfamiliar, read the compiled output to see what it does.
Why not just write the table name directly?
Because the name changes between environments, and because ref() is how dbt discovers which model depends on which. Hard-coding the name hides dependency information from dbt.
Where can I see the compiled SQL in real dbt?
When you run dbt compile or dbt run, dbt writes the compiled version to a folder called target/compiled/ inside your project. Opening that file is the first thing to do when a model errors.
What comes next
You have seen that ref() and source() become table names.
In the next module, What dbt Is, you will explore why teams use dbt instead of manual scripts, and how ref() and source() build the dependency graph that orchestrates your pipeline.
Practice
The exercise gives you a model written with ref() and asks for the compiled SQL with an 8 row limit.
Remember the two parts: turn the whole expression into a table name, and make sure no curly braces are left in the editor.
Going further: let a loop write the repetitive SQL
Jinja is useful when you would otherwise copy and paste the same SQL line with one word changed. A loop over a list generates the lines, and the list becomes the one place to edit. Always read the compiled result: the SQL that runs is what Jinja produces, not what you wrote.
The example renders a template that makes 1 column per payment method, then runs the compiled SQL. Predict the compiled SQL before revealing the output.
import duckdb
from jinja2 import Template

template = Template("""
SELECT order_id,
{%- for method in methods %}
       SUM(CASE WHEN method = '{{ method }}' THEN amount ELSE 0 END) AS {{ method }}_amount{{ "," if not loop.last }}
{%- endfor %}
FROM payments
GROUP BY order_id
ORDER BY order_id
""")
sql = template.render(methods=["card", "upi", "cash"]).strip()
print(sql)

con = duckdb.connect()
con.execute("CREATE TABLE payments AS SELECT * FROM (VALUES (1,'card',100),(1,'upi',50),(2,'cash',80)) t(order_id, method, amount)")
print()
for row in con.execute(sql).fetchall():
print(row)SELECT order_id,
SUM(CASE WHEN method = 'card' THEN amount ELSE 0 END) AS card_amount,
SUM(CASE WHEN method = 'upi' THEN amount ELSE 0 END) AS upi_amount,
SUM(CASE WHEN method = 'cash' THEN amount ELSE 0 END) AS cash_amount
FROM payments
GROUP BY order_id
ORDER BY order_id
(1, 100, 50, 0)
(2, 0, 0, 80)The loop wrote three CASE lines. loop.last stops the trailing comma after the final one, which would be a syntax error. Adding a new method means adding one word to the list, not editing SQL in three places.
The cost of this power is readability. When a model fails, open the compiled file (under target/) and debug the SQL, not the template. If a Jinja block takes a minute to understand, a few plain lines of SQL may be the better choice.
Try a new scenario
You must sum amount for each of the years 2024, 2025 and 2026 as separate columns. What goes in the list and what does the loop write?
Open the answer
The list is the 3 years and each pass writes one SUM(CASE ...) column: SUM(CASE WHEN year = 2024 THEN amount END) AS y2024, SUM(CASE WHEN year = 2025 THEN amount END) AS y2025, SUM(CASE WHEN year = 2026 THEN amount END) AS y2026. The separator logic matters: forgetting it produces a trailing comma and a syntax error that only appears in the compiled SQL.
Interview: what is the risk of too much Jinja in SQL models?
Models become hard to read and debug because the SQL that runs is not the SQL you see. Keep Jinja for repetition and configuration, read the compiled SQL when something fails, and prefer plain SQL when a reader would understand it faster.
Close the lesson and explain it
Without scrolling up, explain what a Jinja loop produces, why you read the compiled SQL, and when plain SQL is clearer.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.