
Overview
Analytics engineering sits between loading data and analysing it: you reshape what is already in the warehouse. dbt is the usual tool. This tab runs the SELECT, not `dbt run`.
On this page8 sections
The idea
Open a raw orders table straight from an application database and you will notice immediate issues.
Column names disagree across tables, totals sit stored as text strings, and cancelled transactions sit right beside completed payments.
What happens when analysts query messy raw tables directly?
When reporting analysts query raw tables directly, every dashboard cleans data in its own private way.
One analyst in Bengaluru filters out cancelled rows, while another forgets to filter and counts refunded transactions as valid revenue.
Raw orders landing table: inconsistent identifiers, text numbers, and mixed statuses.
| order_id | user_id | order_status | order_total |
|---|---|---|---|
| ORD-0001 | U004 | paid | 612.07 |
| ORD-0002 | U073 | refunded | 446.70 |
| ORD-0003 | U078 | paid | 1104.32 |
Two different revenue figures go into the Monday leadership meeting, and stakeholders spend 30 minutes debating whose spreadsheet is correct.
The issue is not broken SQL. The issue is having no shared place where business logic gets defined once.
Clean data once in code so reports never debate definitions in meetings.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Warehouse | The big database where a company keeps its data for reporting |
| Model | One SQL SELECT saved in a file. dbt turns it into a table or view |
| Staging | A first cleanup step. Rename columns and fix types, nothing fancy |
| Mart | A finished table built for reports, such as monthly revenue |
| ELT | Extract, load, then transform. Raw data goes in first, cleaning happens inside the warehouse |
| dbt | A tool that runs your SQL models, tests them and keeps them in Git |
What is analytics engineering?
Somebody has to turn raw tables into clean, dependable datasets that every analyst can trust.
That responsibility has an industry name: analytics engineering.
- Raw tablesloaded by data engineers
- Staging modelsrenamed and cast in SQL
- Automated checksverified for nulls and duplicates
- Reporting martsqueried by BI analysts
An analytics engineer writes SQL that reshapes data already inside the warehouse, tests it, and stores it in Git.
The primary tool teams use for this workflow is dbt, which stands for data build tool.
For now, remember one fundamental boundary: dbt does not move data across networks. It starts after data arrives in the warehouse.
Analytics engineers bring software engineering discipline to warehouse SQL.
Why this exists
Organizations need a single source of truth for their core metrics.
Why do reports drift apart without a shared modeling layer?
Consider two teammates answering the exact same question: what was total sales revenue last month?
Both query the same database, but each writes private filter logic inside their own query window.
Without a shared layer, simple queries produce conflicting answers.
| Analyst | Filter applied | Calculated total (₹) | Outcome |
|---|---|---|---|
| Analyst A | WHERE order_status = 'paid' | 1716.39 | Correct total |
| Analyst B | No filter applied | 2163.09 | Counts refunded order |
Rename a source column upstream, and a dozen personal dashboards break without warning.
Load the same order batch twice, and revenue quietly doubles because nothing checked primary keys for duplicates.
Without shared models, every reporting tool re-invents data cleaning independently.
How does a shared transformation layer solve this confusion?
The solution is to clean raw data once in a central transformation layer, and require everyone to query that layer.
Building, testing, and documenting that layer is the analytics engineer core job.
- Raw orders tablesource of truth for checkout
- Shared stg_orders modelcleans and filters once
- Finance dashboardqueries clean model
- Operations dashboardqueries clean model
When a source column changes tomorrow, the analytics engineer updates exactly one staging model.
Every downstream report inherits the fix immediately, without any analyst rewriting their queries.
Fix data once in the shared layer instead of patching 12 dashboards.
Picture this
Think of a retail shop with a loading bay, stock shelves, and customers.
How do data team responsibilities divide across the warehouse?
Trucks unload boxes at the loading bay, staff shelve clean goods, and customers browse shelves.
Your data platform functions the same way across three distinct roles.
Data engineers fill the bottom layer. Analytics engineers build the middle layer. Analysts live in the top layer.
Read the diagram from the bottom. Data engineers get raw tables landed inside the warehouse.
Analytics engineers turn those raw tables into clean, tested models with agreed business definitions.
Analysts query the clean models to answer strategic questions and build leadership dashboards.
| Role | What they own | What they hand over |
|---|---|---|
| Data engineering | Pipelines that load data | Raw tables, like orders and events |
| Analytics engineering | SQL models, tests, documentation | Clean tables, like stg_orders and fct_revenue |
| Analysis | Questions and reports | Dashboards and answers |
Notice that analysts never touch the raw loading bay. They query only the curated middle layer.
What is the difference between ETL and ELT?
Data architectures evolved from ETL to ELT over the last two decades.
ELT stands for extract, load, and transform, in that exact sequence.
Same 3 steps, different order. With ELT the raw copy survives, so you can change your mind later.
In older ETL architectures, external transformation servers cleaned data before loading, discarding raw source records.
If business definitions changed 6 months later, recalculating historical numbers from source was hard or impossible.
In modern ELT, ingestion tools stream raw records directly into the warehouse without upfront transformation.
Transformations run in SQL inside the warehouse, so you can test, version, and rerun models whenever logic changes.
ELT keeps raw records so you can recalculate metrics whenever logic updates.
Where does dbt sit inside the warehouse?
Follow the route data takes inside an ELT warehouse architecture.
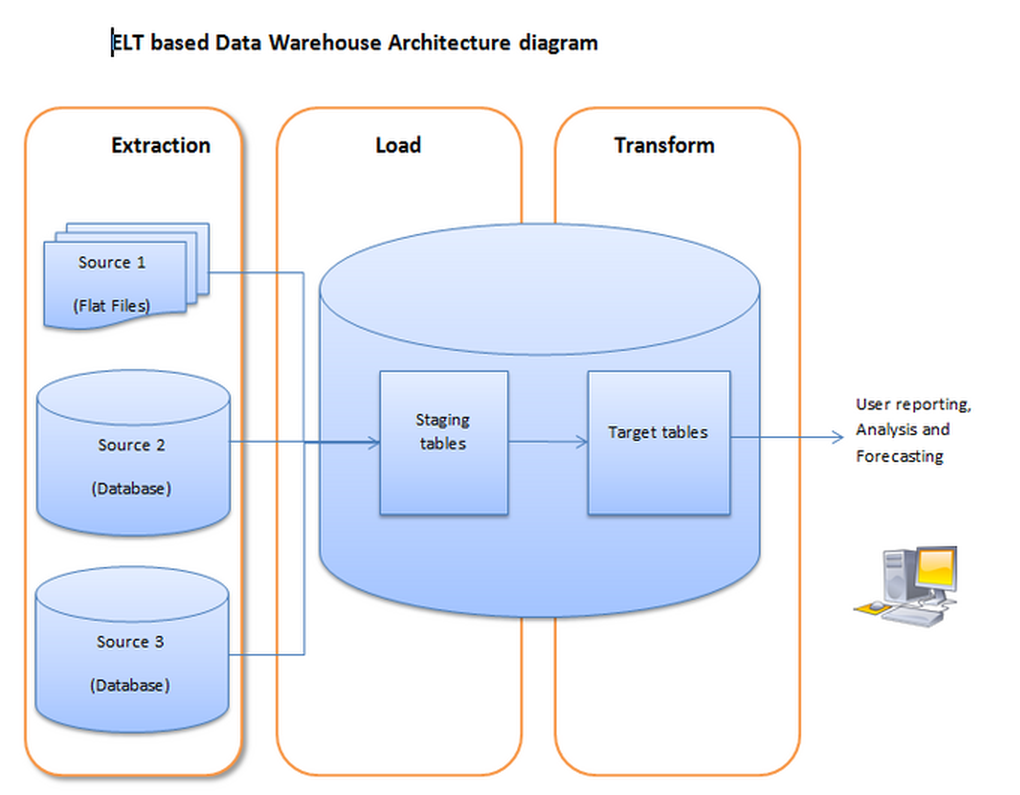
Notice that staging tables and target tables sit inside the exact same database cylinder.
No rows ship to an external server for processing. That allows a simple SQL file to serve as the entire transform step.
dbt operates strictly inside that final transformation stage, compiling and running your SQL models.
A small example
Here is the smallest honest version of an analytics engineering transformation.
What does a raw source table look like when it lands?
Here are three raw rows straight from the orders table in your warehouse:
Input: raw orders landing table, exactly as loaded.
| order_id | user_id | order_status | order_total |
|---|---|---|---|
| ORD-0001 | U004 | paid | 612.07 |
| ORD-0002 | U073 | refunded | 446.70 |
| ORD-0003 | U078 | paid | 1104.32 |
Notice the rough edges: user_id is ambiguous, and order_total needs standardizing as amount.
If downstream analysts use user_id while other tables use customer_id, join syntax becomes confusing.
How does a staging model standardize those raw records?
The first model an analytics engineer writes is a staging model.
It is a plain SELECT query that renames columns to team standards and applies consistent aliases.
SELECT
    order_id,
    user_id AS customer_id,
    order_total AS amount
FROM orders
LIMIT 3;
Predict what the output columns look like before checking the transformed table below:
Output: the same rows with names the rest of the project agrees on.
| order_id | customer_id | amount |
|---|---|---|
| ORD-0001 | U004 | 612.07 |
| ORD-0002 | U073 | 446.70 |
| ORD-0003 | U078 | 1104.32 |
Same 3 rows, but every downstream query now refers to customer_id and amount consistently.
If the source database team renames user_id next month, you update one staging SELECT instead of 12 reports.
The SQL editor in this tab runs plain SQL in DuckDB. It does not run the dbt CLI or compile Jinja templates. In real dbt, you save this SELECT in a .sql file. dbt Core wraps it in CREATE VIEW or CREATE TABLE and executes it against your warehouse.
If a teammate asks dbt to pull orders out of an app database, the answer is no. A loader tool or ingestion script puts raw tables in the warehouse first. dbt starts from there.
Which software engineering practices does dbt bring to SQL?
Analytics engineering applies 4 core software development practices to analytical databases.
Core software development practices applied to warehouse SQL.
| Software practice | How dbt implements it | Benefit to the team |
|---|---|---|
| Version control | Models and YAML stored in Git | Every query change reviewed via pull request |
| Automated quality checks | Assertions run after models build | Catches missing keys or duplicate rows after builds |
| Modularity (DRY) | Reusable staging and mart models | Stops copy-pasting repetitive SQL blocks |
| Automated documentation | YAML descriptions compile to DAG site | Lineage graph shows table dependencies visually |
Instead of copying SQL across personal query consoles, teams organize models into modular, testable files.
In modern dbt Core (1.8 and above, including 1.12), column tests are defined under the data_tests key in YAML.
Generic tests like unique and not_null run after a model builds, verifying output rows without blocking writes at the storage engine level unless contracts are configured.
Treat analytical SQL with the same testing and version control as application code.
How does a complete analytics engineering pipeline run from source to mart?
Extract and Load: ingestion tools load raw tables straight into the warehouse.
- Source app
- Raw orders table
Staging: a lightweight SELECT renames fields and standardizes types.
- Raw orders table
- stg_orders model
Testing: automated assertions verify non-null keys and accepted values after build.
- stg_orders model
- CI test suite
Marts: tested models join into dimensional tables that feed BI dashboards.
- stg_orders model
- fct_revenue mart
4 rules to remember about analytics engineering:
- Data engineers land raw data; analytics engineers transform and test models inside the warehouse.
- ELT stores raw source records permanently so models can be re-run whenever definitions update.
- Staging models rename and cast columns one-to-one with source tables without joins or aggregations.
- dbt applies software engineering discipline: version control, automated testing, modularity, and lineage.
Common beginner questions
Is analytics engineering the same as data engineering?
No, though on small teams one person often does both. Data engineering gets data into the warehouse and keeps those pipelines alive. Analytics engineering takes what is already there and models it with SQL, tests, and documentation.
Why transform inside the warehouse and not before loading?
Warehouses are very good at running SQL over large tables, and SQL is a language most of your team already reads. Keeping the cleaning next to the data also means you can rerun it from the raw copy when a definition changes.
Do tests in dbt prevent bad rows from being written?
By default, generic dbt tests run after a model builds. If a test fails, dbt halts downstream dependent models, but the bad rows already landed in that table unless you configure database constraints or transactions.
What comes next
You now understand the analytics engineering role and where it sits in the data stack.
In the next lesson, dbt project structure, you will explore what a dbt project looks like on disk: which folders hold staging models, which hold marts, and where YAML configurations live.
Practice
Run the sample query once to see a staging-shaped SELECT in action.
Then complete the exercise: from orders, return order_id, user_id AS customer_id, and order_total AS amount, limited to 20 rows. Write clean SQL only.
Going further: the grain is the model's contract
An analytics engineer builds tables other people trust. The most important promise a table makes is its grain: 1 row per what. Everything downstream, every sum and count, assumes that promise holds. dbt's unique test is the fastest check on that promise.
A model that claims to be 1 row per order, with an accidental duplicate.
| order_id | amount |
|---|---|
| ORD-0001 | 612.07 |
| ORD-0002 | 446.70 |
| ORD-0002 | 446.70 |
| ORD-0003 | 1104.32 |
The unique test runs a query that groups by the primary key and returns rows with a count greater than one. Predict what this query returns before revealing the output.
WITH orders_model AS (
    SELECT 'ORD-0001' AS order_id, 612.07 AS amount
    UNION ALL SELECT 'ORD-0002', 446.70
    UNION ALL SELECT 'ORD-0002', 446.70
    UNION ALL SELECT 'ORD-0003', 1104.32
)
SELECT order_id, COUNT(*) AS n
FROM orders_model
GROUP BY order_id
HAVING COUNT(*) > 1;order_id n ORD-0002 2
Order ORD-0002 appears twice, so the test returns a row and fails. That failure prevents downstream models from building on duplicate data. Without this test, summing amount gives 2,609.79 instead of the real 2,163.09 total.
| Model promise | dbt test | What it protects |
|---|---|---|
| 1 row per order | unique on order_id | Revenue sums and order counts |
| Every order has a key | not_null on order_id | Downstream joins |
| Every order links to a customer | relationships to customers | Orphaned transactions |
Try a new scenario
You join orders to order_items to build a reporting model called orders_summary, but finance reports that revenue numbers are inflated. What caused this, and how do you resolve it?
Work it out, then open the answer
The join expanded the grain from 1 row per order to 1 row per line item. If an order has 3 items, the order total gets added 3 times. To fix it, either aggregate line items to the order level before joining, or keep the model at the line item grain, rename it to order_items_summary, and test uniqueness on item_id.
What is the difference between a data engineer and an analytics engineer?
Data engineers build and maintain the infrastructure that ingests raw data into the warehouse reliably. Analytics engineers use SQL, dbt, and Git to transform that raw data into clean, tested models for business analysts.
Close the lesson and explain it
Without scrolling up, explain what table grain means and why a unique test protects aggregate numbers.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.