
Overview
dbt compiles a folder of SELECT statements, runs them in order and tests the results. The editor here runs the SELECT part. It cannot run `dbt run`.
On this page8 sections
The idea
If you have ever kept a folder of SQL files and run them by hand in sequence, you have already done the job dbt automates.
You opened file one, ran it, opened file two, ran it, and hoped nobody had modified file one in between.
What is dbt at its core?
dbt is a compiler, a dependency orchestrator, and an automated test runner wrapped around analytical SQL.
It does not store your data, because the warehouse handles storage.
It does not perform heavy computing, because your warehouse engine executes queries.
Functional separation between dbt and the underlying cloud warehouse.
| Responsibility | Tool that handles it | How it operates |
|---|---|---|
| Data storage | Cloud warehouse (Snowflake, BigQuery) | Stores physical columns and partitions |
| Query compute | Cloud warehouse engine | Executes table joins and aggregations |
| Compilation and DAG order | dbt Core | Resolves ref() calls and schedules execution order |
| Data ingestion | Fivetran, Airbyte, Python jobs | Loads raw records into landing schemas |
dbt only transforms tables that already reside inside the warehouse.
dbt is a compiler and dependency runner; the warehouse handles all storage and compute.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| dbt run | The command that builds every model |
| Dependency | When one model reads from another, it depends on it |
| DAG | A map of models with arrows from inputs to outputs and no loops |
| Materialization | Whether a model is saved as a view or a table |
| Target | The place dbt builds into, such as dev or prod |
| Compile | Turn a model file into plain SQL |
Why this exists
Before dbt, data teams scattered business logic across scheduled scripts, stored procedures, and BI dashboards.
Why is managing SQL dependencies by hand risky?
3 problems repeat when engineers coordinate queries manually.
First, order: table B reads from table A, so A must build first, but with 50 models nobody remembers the sequence.
Second, trust: when a metric looks wrong, you cannot tell which intermediate step introduced the error.
Third, change: renaming an upstream column requires searching every reporting query by hand.
dbt changes how the SQL is organised and checked. The SQL itself is still SQL.
Each row on the left is a chore a human performs manually.
Each row on the right is dbt automating the step from the ref() calls you already wrote.
dbt calculates model build order automatically from declared dependencies.
Picture this
When you execute dbt run on your computer, a 4-step sequence occurs.
What happens during a dbt run execution?
Notice that only one of the 4 steps involves your warehouse running queries.
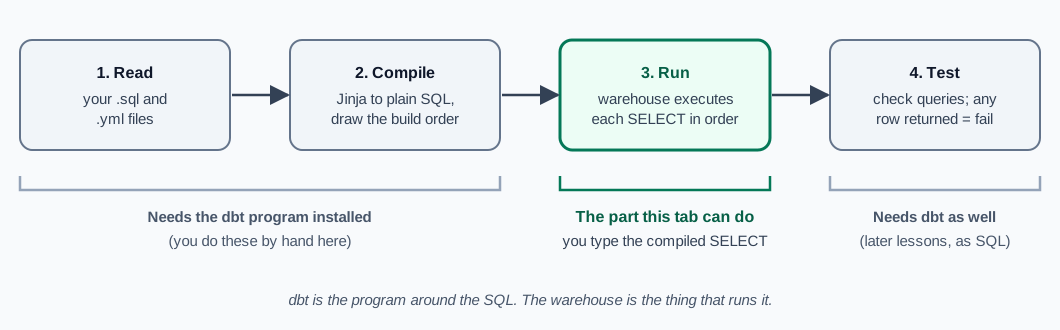
Step 1 reads your project files from disk.
Step 2 compiles Jinja into SQL and constructs the DAG build order from ref() calls.
Step 3 transmits each SELECT to the warehouse in topological sequence.
Step 4 executes your automated data tests, returning rows only when constraints fail.
The highlighted third box is the only part this browser tab covers. The SQL editor here is the warehouse execution engine.
What it lacks is the dbt compiler, so there is no local project folder and no profiles.yml file.
A model is a recipe, and dbt is the kitchen staff who decide which recipe goes first, cook it and taste it. In this tab you have a working stove and no staff, so you do the ordering yourself.
A model is the recipe; the warehouse is the kitchen that cooks the dish.
A small example
Here are two minimal models demonstrating how dbt discovers build sequence automatically.
How does dbt deduce build sequence between 2 models?
Here are sample raw orders landing from the checkout system for customers U004 and U057:
Input: raw orders from the warehouse (sample rows for customers U004 and U057).
| order_id | user_id | order_status | order_total |
|---|---|---|---|
| ORD-0001 | U004 | paid | 612.07 |
| ORD-0004 | U057 | cancelled | 339.90 |
| ORD-0180 | U004 | paid | 311.70 |
The first model cleans orders, and the second aggregates paid orders per customer:
-- models/staging/stg_orders.sql (illustration, not run here)
select
    order_id,
    user_id as customer_id,
    order_status,
    order_total as amount
from {{ source('jaffle', 'orders') }}

-- models/marts/customer_paid_orders.sql (illustration, not run here)
select
    customer_id,
    count(*) as paid_orders
from {{ ref('stg_orders') }}
where order_status = 'paid'
group by customer_id
dbt observes that the second model calls ref('stg_orders'), so it builds stg_orders first.
You never instructed dbt on run order; you merely declared dependencies.
Output of customer_paid_orders: U004 has two paid orders. U057 had only a cancelled order, so U057 does not appear.
| customer_id | paid_orders |
|---|---|
| U004 | 2 |
In this tab, the SQL editor runs plain DuckDB queries without dbt CLI commands. You simulate both models using a CTE:
WITH stg_orders AS (
    SELECT
        order_id,
        user_id AS customer_id,
        order_status,
        order_total AS amount
    FROM orders
)
SELECT customer_id, COUNT(*) AS paid_orders
FROM stg_orders
WHERE order_status = 'paid'
  AND customer_id IN ('U004', 'U057')
GROUP BY customer_id;
In larger systems with hundreds of models, maintaining execution sequence manually is impractical.
It sees file names, ref() calls and the pass or fail results the warehouse sends back. The data stays where it was. That is how dbt can drive a model over 1 billion rows from a laptop.
After this track you can write models and tests as SQL and explain how dbt compiles and orders them. You have not run the dbt program until you install it on your own machine and type dbt run. Say that plainly if someone asks.
What happens if models accidentally create a circular dependency?
Suppose stg_orders calls ref('customer_paid_orders') while customer_paid_orders calls ref('stg_orders').
Neither table can build first, creating an impossible infinite loop.
dbt.exceptions.CompilationError: Found a cycle in the model dependencies:
stg_orders -> customer_paid_orders -> stg_orders
dbt catches this circular loop during the compilation phase before transmitting any SQL to the warehouse.
Because dbt constructs the full DAG up front, invalid relationship cycles are halted immediately.
dbt detects circular dependency cycles during compile before running a single query.
How does dbt function as a SQL compiler?
Think of dbt as a specialized compiler for analytical database systems.
-- models/marts/fct_daily_orders.sql (illustration, not run here)
{{
  config(
    materialized='table'
  )
}}

SELECT
    order_date,
    COUNT(order_id) AS total_orders,
    ROUND(SUM(order_total), 2) AS gross_revenue
FROM {{ ref('stg_orders') }}
WHERE order_status = 'paid'
GROUP BY order_date
When you execute dbt run, the compiler follows five distinct stages:
- 1. Jinja compilationresolves ref and config
- 2. DAG resolutioncalculates topological order
- 3. DDL wrappingwraps SELECT in CREATE TABLE
- 4. Artifact emissionwrites to target/compiled/
- 5. Warehouse runexecutes DDL over connections
dbt prepares and coordinates the DDL statements, while your warehouse performs the heavy lifting.
How do teams isolate local development from production?
Multiple developers collaborate on one warehouse without colliding through profiles in ~/.dbt/profiles.yml.
Environment isolation via target profiles in profiles.yml.
| Developer / Role | Target schema in warehouse | Collision protection |
|---|---|---|
| Priya (local laptop) | dbt_priya.stg_orders | Isolated sandbox for local edits |
| Rajesh (local laptop) | dbt_rajesh.stg_orders | Cannot overwrite Priya's models |
| Production orchestrator | analytics_prod.stg_orders | Nightly scheduled run for business reports |
Because models use ref() rather than static schemas, the same query runs everywhere without code changes.
Each developer operates within their own workspace without interfering with teammate queries.
When code merges into main, the production runner builds tables in the official analytics schema.
What happens if you accidentally hardcode a production schema name?
Consider what happens if an engineer writes FROM analytics_prod.orders instead of using the ref function.
During local development, Priya's test runs will read or overwrite live production data by mistake.
-- Fragile anti-pattern: hardcoding production schemas
SELECT * FROM analytics_prod.stg_orders;

-- Safe pattern: dbt resolves schema automatically
SELECT * FROM {{ ref('stg_orders') }};
Hardcoding physical schema names hides the dependency from the compiler.
Using ref lets dbt resolve the model in the schema selected by the active target profile. In Priya's local target that can be Priya's personal schema; in production it can be the shared analytics schema.
How does dbt contain failures during parallel builds?
dbt executes models concurrently across multiple warehouse threads.
- stg_orders failssyntax or timeout error
- fct_orders skippeddownstream child halted
- stg_users succeedsindependent branch continues
- dim_users buildsunaffected table finishes
When an upstream model fails, dbt halts its direct children while allowing independent branches to finish.
This failure containment prevents corrupted data from propagating into unrelated dashboards.
Why did declarative modeling replace imperative scripts?
Before dbt, data teams wrote imperative Bash and Python scripts to run drop and create statements manually.
Declarative modeling replaces fragile procedural scripts.
| Paradigm | Developer responsibility | Maintenance overhead |
|---|---|---|
| Imperative scripts | Write explicit DROP, CREATE, INSERT DDL | High; scripts break on schema drift |
| Declarative dbt models | Write pure SELECT and declare materialization | Low; dbt manages table replacement mechanics |
In dbt, you write what the final relation should contain, and dbt manages underlying warehouse transactions.
What artifacts does dbt generate in the target folder?
During compilation and execution, dbt writes standardized JSON metadata files into target/:
Machine-readable metadata emitted on every dbt build.
| Artifact | What it contains | How teams use it |
|---|---|---|
| manifest.json | Full project AST, models, tests, sources | Lineage visualization and CI impact analysis |
| run_results.json | Runtime telemetry, row counts, durations | Observability and pipeline monitoring |
| catalog.json | Column types, physical table sizes | Interactive documentation catalog |
These artifacts allow external tools to audit security policies and visualize data lineage.
How does Slim CI accelerate automated pull request testing?
In large repositories with thousands of models, rebuilding everything on each commit takes hours.
Slim CI solves this by downloading manifest.json from the latest production build:
dbt build --select state:modified+ --defer --state path/to/prod/artifactsdbt compiles only the models modified in the pull request and their direct children.
For unchanged upstream tables, dbt references existing production relations without rebuilding them.
How do you debug failing models with compiled SQL and logs?
When a model fails in the warehouse, look inside target/compiled/ to inspect the rendered SQL.
- Model fails in CIwarehouse error thrown
- Open target/compiled/inspect raw SQL query
- Check logs/dbt.logreview database error message
- Profile queryrun EXPLAIN in query console
Opening the compiled query reveals the exact SQL transmitted to the warehouse.
You can copy this query into your warehouse console to profile execution plans directly.
Running EXPLAIN on compiled SQL pinpoints inefficient table scans and missing cluster keys quickly.
How does dbt coordinate a project from source to production?
Declare: author pure SELECT models with ref() dependencies.
- models/ directory
- dbt Core
Compile: parse Jinja, resolve DAG, and wrap in warehouse DDL.
- dbt Core
- target/compiled/
Execute: transmit DDL in topological order across warehouse threads.
- target/run/
- Warehouse engine
Test: run automated data tests to verify primary key constraints.
- Warehouse engine
- CI pass/fail
4 rules to remember about how dbt operates:
- dbt is a compiler and dependency runner; your warehouse executes all storage and queries.
- ref() automatically deduces build order, eliminating manual run sequences.
- profiles.yml namespaces models into personal schemas during local development.
- Failure containment halts child models while allowing independent branches to finish.
Common beginner questions
Is dbt a database?
No. It connects to a database or warehouse you already have, such as Snowflake, BigQuery or Postgres, and tells it what SQL to run. All the data stays in the warehouse.
What are "view" and "table" in dbt?
They are two ways to store the result of a model, called materializations. A view saves the query and runs it each time it is read. A table saves the rows. dbt wraps your SELECT in the matching CREATE statement. A later lesson compares them.
Do I still need to know SQL?
Yes, more than anything. A dbt model is a SELECT. dbt adds structure around SQL, it does not replace it.
What comes next
You have seen that ref() and source() are what let dbt order the work.
The next lesson looks at those two functions closely and shows how they connect models into a graph, and what happens when the graph loops back on itself.
Practice
The exercise is a staging-shaped SELECT from orders: order_id, customer_id and amount, limited to 20 rows.
It is the first model in the project above, so it is a good moment to say the columns out loud before you type them.
Going further: how dbt knows the order to build things
You never tell dbt the order. Each model names the models it uses with ref(), and dbt reads those names to build a dependency graph, then runs models so that every parent finishes before its children. Understanding that one step explains lineage, selective runs and circular-dependency errors.
The sketch below does the same thing in a few lines: it reads ref() calls from model SQL and finds a valid run order. Predict the order.
import re

models = {
    "stg_orders":    "select * from raw.orders",
    "stg_customers": "select * from raw.customers",
    "orders_enriched": "select * from {{ ref('stg_orders') }} o join {{ ref('stg_customers') }} c using (customer_id)",
    "revenue_by_country": "select country, sum(amount) from {{ ref('orders_enriched') }} group by 1",
}

deps = {name: set(re.findall(r"ref\('(\w+)'\)", sql)) for name, sql in models.items()}

order, done = [], set()
while len(order) < len(models):
    ready = sorted(m for m in models if m not in done and deps[m] <= done)
    if not ready:
        raise SystemExit("circular dependency")
    order += ready
    done |= set(ready)

print("depends on:", {m: sorted(d) for m, d in deps.items()})
print("build order:", order)depends on: {'stg_orders': [], 'stg_customers': [], 'orders_enriched': ['stg_customers', 'stg_orders'], 'revenue_by_country': ['orders_enriched']}
build order: ['stg_customers', 'stg_orders', 'orders_enriched', 'revenue_by_country']The two staging models have no ref() calls, so they can go first (and could run in parallel). Then orders_enriched, then revenue_by_country. If 2 models referred to each other, no model would ever be ready, which is the circular-dependency error dbt reports.
The same graph is what dbt draws as lineage, and what lets you run one model and everything that depends on it. It also explains why you should write ref() and not a hard-coded table name: a hard-coded name is invisible to the graph, so the order can be wrong.
Try a new scenario
A model reads from analytics.stg_orders written as plain text, not ref(). It sometimes fails with 'table not found' right after a fresh build. Why?
Work it out, then open the answer
dbt cannot see the dependency, so it may build the new model before stg_orders exists. Replace the plain name with ref('stg_orders'). Then the graph knows the order, and the name also changes correctly between development and production schemas.
What does dbt not do?
dbt does not extract or load data, and it does not store or compute anything itself. It compiles your SQL models, sends them to the warehouse in dependency order, and runs tests. Loading is done by other tools.
Close the lesson and explain it
Without scrolling up, explain how dbt decides the order of models and what a circular dependency looks like.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.