Cloud
AWS Cloud Data Engineer
S3, Glue, Redshift, Athena, IAM and the AWS data stack, with the questions interviews ask.
- Handwritten-style
- Diagrams and tables
- Worked examples
Who this notebook is for
Engineers and candidates who need the AWS data stack explained as one system, including where each service fits and what it costs.
What you will be able to do
- Lay out a data lake on S3 with Glue as the catalog
- Choose between Athena, Redshift and EMR for a given workload
- Compare Kinesis and MSK for streaming ingestion
- Control cost and governance with FinOps habits and Lake Formation
What's inside
Pick a chapter and the notebook opens right there.
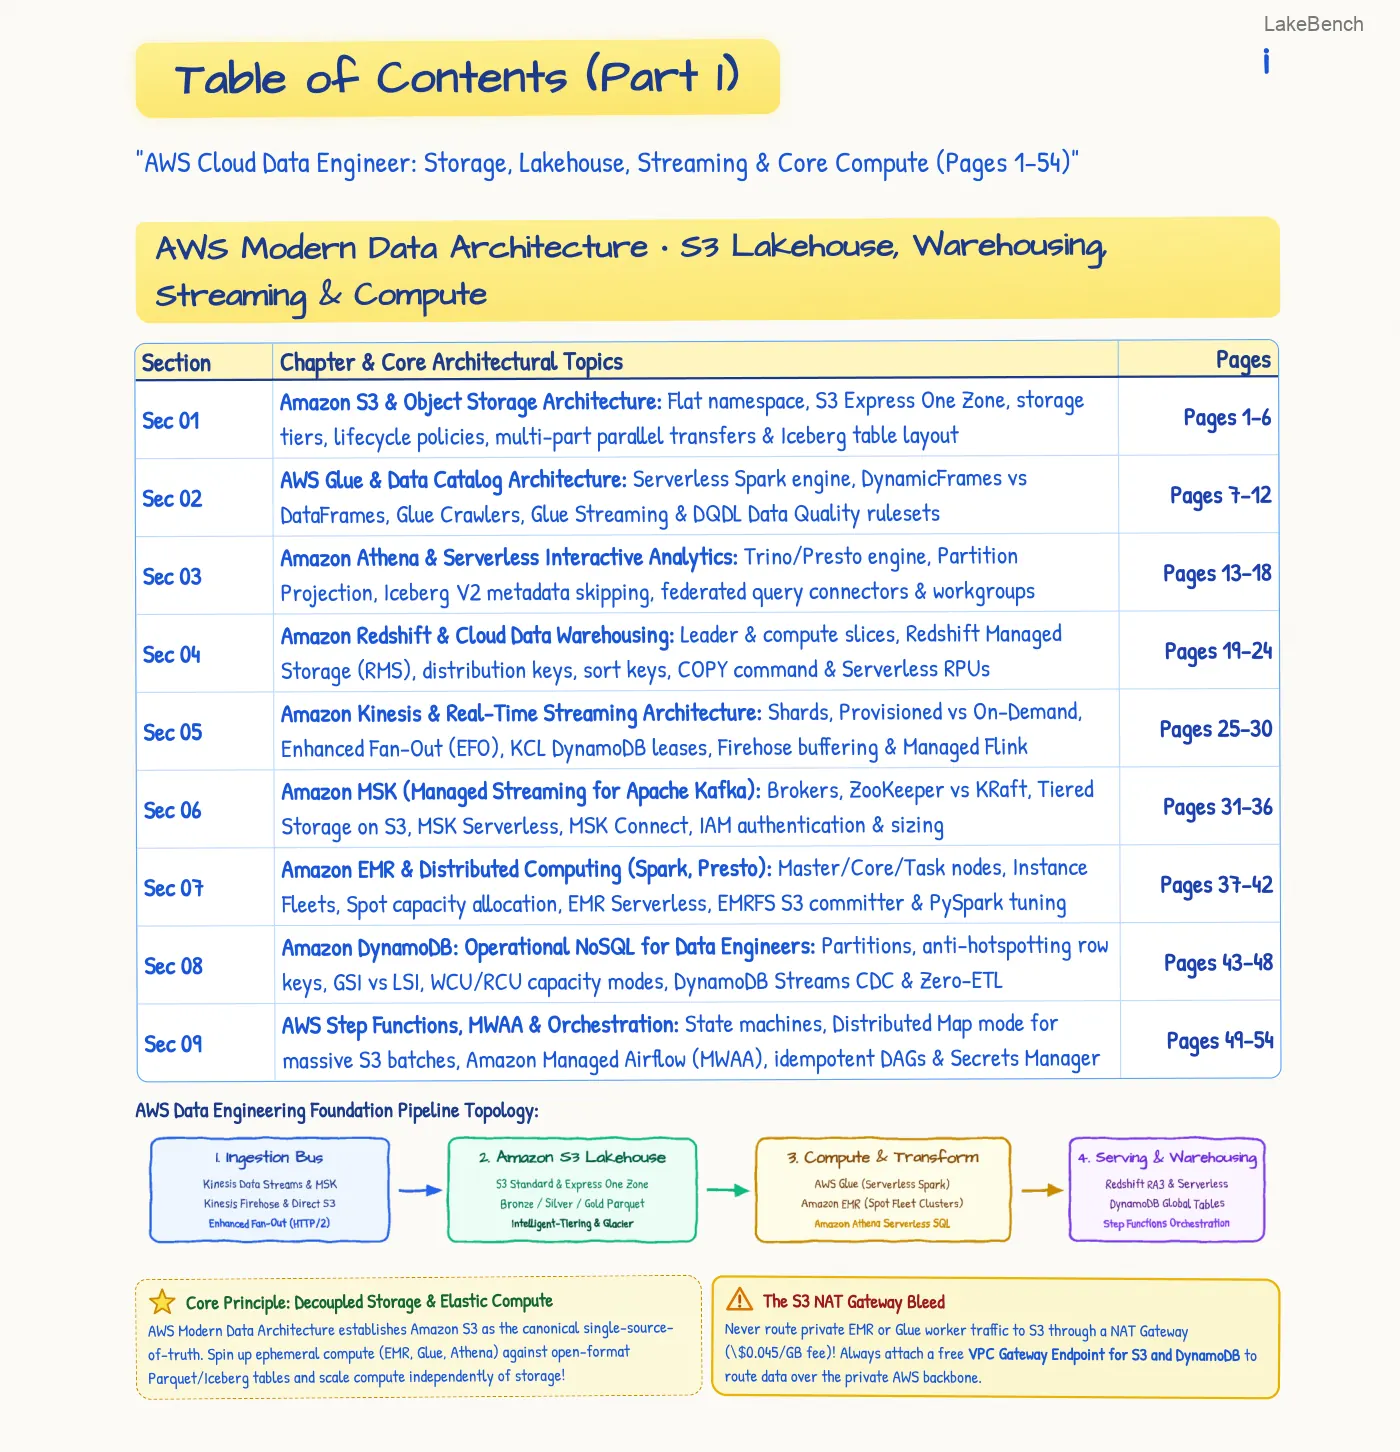
- Amazon S3 & Object Storage ArchitectureFlat namespace, S3 Express One Zone, storage tiers, lifecycle policies, multi-part parallel transfers & Iceberg table layoutStart here
- AWS Glue & Data Catalog ArchitectureServerless Spark engine, DynamicFrames vs DataFrames, Glue Crawlers, Glue Streaming & DQDL Data Quality rulesetsStart here
- Amazon Athena & Serverless Interactive AnalyticsTrino/Presto engine, Partition Projection, Iceberg V2 metadata skipping, federated query connectors & workgroupsStart here
- Amazon Redshift & Cloud Data WarehousingLeader & compute slices, Redshift Managed Storage (RMS), distribution keys, sort keys, COPY command & Serverless RPUsStart here
- Amazon Kinesis & Real-Time Streaming ArchitectureShards, Provisioned vs On-Demand, Enhanced Fan-Out (EFO), KCL DynamoDB leases, Firehose buffering & Managed FlinkStart here
- Amazon MSK (Managed Streaming for Apache Kafka)Brokers, ZooKeeper vs KRaft, Tiered Storage on S3, MSK Serverless, MSK Connect, IAM authentication & sizingStart here
- Amazon EMR & Distributed Computing (Spark, Presto)Master/Core/Task nodes, Instance Fleets, Spot capacity allocation, EMR Serverless, EMRFS S3 committer & PySpark tuningStart here
- Amazon DynamoDB: Operational NoSQL for Data EngineersPartitions, anti-hotspotting row keys, GSI vs LSI, WCU/RCU capacity modes, DynamoDB Streams CDC & Zero-ETLStart here
- AWS Step Functions, MWAA & OrchestrationState machines, Distributed Map mode for massive S3 batches, Amazon Managed Airflow (MWAA), idempotent DAGs & Secrets ManagerStart here
- AWS Lake Formation & Data Mesh GovernanceLF-Tags, column/cell-level filtering, cross- account RAM sharing, KMS encryption & IAM least-privilege boundaryStart here
- AWS DMS & Real-Time CDC ReplicationReplication instances, source/target endpoints, CDC log mining, DMS Serverless, SCD Type-2 pipelines & latency tuningStart here
- Amazon OpenSearch Service & Zero-ETLInverted index, UltraWarm cold tiers, Zero-ETL from DynamoDB/Aurora, Vector Search k-NN & log observabilityStart here
- Amazon Bedrock & Generative AI Data PipelinesFoundation models, Titan embeddings, Bedrock Knowledge Bases, pgvector RAG pipelines, Agents & Model EvaluationStart here
- Amazon S3 Tables & Apache Iceberg LakehouseTable buckets, Iceberg table maintenance, automated compaction, snapshot expiration, copy-on-write vs merge-on-readStart here
- AWS FinOps & Cost Optimization for Data EngineersS3 lifecycle traps, Redshift Serverless RPU sizing, Glue Flex Execution, EMR Spot fleets & NAT Gateway slasherStart here
- Hybrid & Multi-Cloud Networking for AWS DataDirect Connect, Transit Gateway, PrivateLink endpoint services, DataSync migrations, S3 CRR RTC & Pilot Light DRStart here
- Production Observability, SRE & SLA MonitoringCloudWatch Embedded Metric Format (EMF), EventBridge rules, CloudTrail audits, Kinesis IteratorAge & Composite AlarmsStart here
- Staff Data Engineer FAANG AWS System Drills100M QPS Prime Day clickstream, Netflix video feature store, financial double-entry ledger, Uber H3 geospatial & clean roomsStart here
- Gap-Fill Supplement: Schema Registry, DataZone & ML/BI ServingGlue Schema Registry & DataBrew, DataZone and SCP guardrails, SageMaker/Redshift ML/QuickSight, AppFlow, Parameter Store & NeptuneStart here
Practice this
Put it to work on LakeBench.
Common questions
- Which AWS services does it cover?
- S3, Glue, Athena, Redshift, Kinesis, MSK, EMR, DynamoDB, Step Functions and MWAA, Lake Formation, DMS, OpenSearch, and newer topics such as S3 Tables and Bedrock pipelines.
- Is it useful for AWS interviews?
- Yes. The closing chapters are system drills written for senior data engineering interviews on AWS.
- Can I read a sample before I commit?
- Yes. The contents pages and the first pages of every notebook can be read online, so you can judge the style before going further.