
Overview
GROUP BY collapses rows into buckets. COUNT, SUM, AVG, MIN, and MAX summarize each bucket.
On this page8 sections
The table we keep using
What are the 8 rows?
We reuse these exact rows all lesson, so you can trace every number back to its source. Amounts are in rupees.
orders_demo: 8 rows, 1 row per order.
| order_id | user_id | order_status | order_total |
|---|---|---|---|
| ORD-0001 | U01 | paid | 400 |
| ORD-0002 | U02 | paid | 800 |
| ORD-0003 | U01 | cancelled | 250 |
| ORD-0004 | U03 | paid | 200 |
| ORD-0005 | U02 | pending | 600 |
| ORD-0006 | U03 | paid | 500 |
| ORD-0007 | U04 | cancelled | 160 |
| ORD-0008 | U01 | paid | 100 |
5 orders are paid, two are cancelled, one is pending. The grain is 1 row per order.
What does the finance lead want to know?
ShopKart's finance lead in Bengaluru wants a daily briefing. How much revenue came in, and how many orders sit in each state?
- 8 orders today
- Add up the totals
- Count orders per status
With 8 orders a calculator works. With thousands an hour, the database must do it.
Can you build the table yourself?
Yes. The real orders table has 180 rows, so we make a small copy to trace by hand.
CREATE OR REPLACE TABLE orders_demo (
  order_id     VARCHAR,
  user_id      VARCHAR,
  order_status VARCHAR,
  order_total  DOUBLE
);

INSERT INTO orders_demo VALUES
  ('ORD-0001', 'U01', 'paid',      400),
  ('ORD-0002', 'U02', 'paid',      800),
  ('ORD-0003', 'U01', 'cancelled', 250),
  ('ORD-0004', 'U03', 'paid',      200),
  ('ORD-0005', 'U02', 'pending',   600),
  ('ORD-0006', 'U03', 'paid',      500),
  ('ORD-0007', 'U04', 'cancelled', 160),
  ('ORD-0008', 'U01', 'paid',      100);
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Aggregate | Combine many rows into one number |
| SUM | Add the values up |
| COUNT | Count the rows |
| AVG | Work out the average |
| GROUP BY | Put rows into buckets and aggregate each bucket |
| HAVING | Filter the buckets after grouping |
What we need from it
What is an aggregate function?
An aggregate reads many rows and collapses them into one summary value.
The five aggregates used in nearly every pipeline.
| Function | Returns | On order_total |
|---|---|---|
| COUNT | How many rows | 8 orders |
| SUM | Total of a column | Sum of all totals |
| AVG | Mean of a column | Typical ticket size |
| MIN | Smallest value | Smallest order |
| MAX | Largest value | Largest order |
What happens with no GROUP BY?
The whole table becomes one group. Predict: how many rows come back, and what is the sum?
SELECT
  COUNT(*)         AS orders,
  SUM(order_total) AS gmv,
  AVG(order_total) AS avg_ticket,
  MIN(order_total) AS min_ticket,
  MAX(order_total) AS max_ticket
FROM orders_demo;orders gmv avg_ticket min_ticket max_ticket 8 3010 376.25 100 800
8 rows in, 1 row out. GMV means gross merchandise value, the total of order amounts.
Why is 3010 a misleading revenue?
The total lumps real money with orders that never paid.
2000 + 600 + 410 = 3010. We need totals per status.
| order_status | Rupees in the total | Is it real revenue? |
|---|---|---|
| paid | 2000 | Yes |
| pending | 600 | Not yet |
| cancelled | 410 | No |
One un-grouped total hides which rupees are real.
Trace it step by step
How does GROUP BY sort rows into buckets?
GROUP BY order_status makes one bucket per distinct status. Each aggregate runs inside its own bucket.
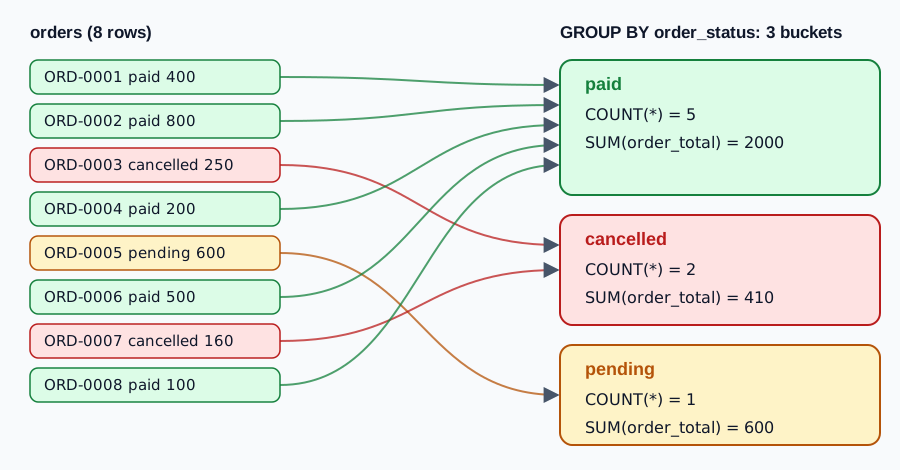
The engine finds three statuses: paid, pending and cancelled.
What does each bucket add up to?
Check the arithmetic by hand before running anything.
Each bucket is computed on its own.
| Bucket | Rows that land in it | COUNT | SUM |
|---|---|---|---|
| paid | ORD-0001, 0002, 0004, 0006, 0008 | 5 | 400 + 800 + 200 + 500 + 100 = 2000 |
| cancelled | ORD-0003, 0007 | 2 | 250 + 160 = 410 |
| pending | ORD-0005 | 1 | 600 |
What does the grouped query return?
Predict: how many rows come back, which status comes first, and what is the cancelled gmv?
SELECT
  order_status,
  COUNT(*)         AS orders,
  SUM(order_total) AS gmv
FROM orders_demo
GROUP BY order_status
ORDER BY gmv DESC;order_status orders gmv paid 5 2000 pending 1 600 cancelled 2 410
8 rows became three. The grain changed from 1 row per order to 1 row per status. The order ids are gone.
A grouped query returns 1 row per group, not 1 row per order.
What if you select a column that is not grouped?
Try to show order_id next to a status bucket. Predict what the engine says.
SELECT order_id, order_status, COUNT(*)
FROM orders_demo
GROUP BY order_status;Binder Error: column "order_id" must appear in the GROUP BY clause or must be part of an aggregate function.
Either add it to the GROUP BY list, or use "ANY_VALUE(order_id)" if the exact value of "order_id" is not important.
LINE 1: SELECT order_id, order_status, COUNT(*)
^The paid bucket holds 5 order ids, and the engine cannot guess which one to show.
The paid bucket contains five distinct order_id values. The query engine cannot guess which single order ID to display on that single summary line. You must either add order_id to the GROUP BY list (which changes the bucket definition) or wrap it in an aggregate such as MIN(order_id) or MAX(order_id).
In what order does SQL run the clauses?
SELECT is written first but runs near the end.
Query clauses execute in a strict logical order that differs from written syntax.
- FROM locates the table.
- WHERE filters individual rows before buckets exist.
- GROUP BY constructs the buckets.
- HAVING filters those buckets after aggregates are computed.
- SELECT evaluates column expressions and creates aliases.
- ORDER BY sorts the output rows.
So ORDER BY, which runs last, can use the alias gmv. Standard SQL does not let WHERE or HAVING use it. DuckDB is lenient in HAVING, but portable queries repeat the aggregate.
Same table, next cut
Cut 1: what does WHERE do before the buckets form?
Operations only wants orders of at least 200 rupees. WHERE runs first, so ORD-0007 (160) and ORD-0008 (100) never reach a bucket.
SELECT
  order_status,
  COUNT(*)         AS orders,
  SUM(order_total) AS gmv
FROM orders_demo
WHERE order_total >= 200
GROUP BY order_status
ORDER BY gmv DESC;order_status orders gmv paid 4 1900 pending 1 600 cancelled 1 250
Paid fell from 5 to 4 orders and from 2000 to 1900 because ORD-0008 left. Cancelled fell from 410 to 250 because ORD-0007 left.
Cut 2: can WHERE filter on COUNT(*)?
Keep statuses with at least 2 orders. Beginners try the aggregate in WHERE. Predict the error.
SELECT order_status, COUNT(*) AS orders
FROM orders_demo
WHERE COUNT(*) >= 2
GROUP BY order_status;Binder Error: WHERE clause cannot contain aggregates!
LINE 1: ... order_status, COUNT(*) AS orders FROM orders_demo WHERE COUNT(*) >= 2 GROUP BY order_status
^When WHERE runs, no groups exist yet, so COUNT(*) has no value. Use HAVING, which runs after GROUP BY.
Cut 2: how does HAVING filter whole buckets?
Predict which status disappears.
SELECT
  order_status,
  COUNT(*)         AS orders,
  SUM(order_total) AS gmv
FROM orders_demo
GROUP BY order_status
HAVING COUNT(*) >= 2
ORDER BY gmv DESC;order_status orders gmv paid 5 2000 cancelled 2 410
Pending had one order, so HAVING dropped the whole bucket.
WHERE removes rows. HAVING removes whole buckets.
Cut 3: how do all three clauses work together?
Marketing wants VIP customers who spent at least 600 on paid orders. Trace the pipeline first.
- WHERE keeps only order_status = 'paid'.
- GROUP BY puts the survivors into one bucket per user_id.
- HAVING drops buckets whose SUM(order_total) is below 600.
- ORDER BY puts the highest spenders first.
SELECT
  user_id,
  COUNT(*)         AS paid_orders,
  SUM(order_total) AS paid_total
FROM orders_demo
WHERE order_status = 'paid'
GROUP BY user_id
HAVING SUM(order_total) >= 600
ORDER BY paid_total DESC;
Predict: does U01 appear? Add up their paid orders first.
user_id  paid_orders  paid_total
U02      1            800
U03      2            700
U01 paid 400 + 100 = 500, short of 600, so HAVING drops it. U04 had only a cancelled order, so WHERE dropped it before grouping.
Cut 4: what happens when you group by 2 columns?
GROUP BY user_id, order_status makes a bucket for every distinct pair. Predict how many.
SELECT
  user_id,
  order_status,
  COUNT(*)         AS total_orders,
  SUM(order_total) AS subtotal
FROM orders_demo
GROUP BY user_id, order_status
ORDER BY user_id, order_status;user_id order_status total_orders subtotal U01 cancelled 1 250 U01 paid 2 500 U02 paid 1 800 U02 pending 1 600 U03 paid 2 700 U04 cancelled 1 160
Six pairs, so 6 rows.
How many orders and how many customers is that?
COUNT(*) counts rows. COUNT(DISTINCT user_id) counts different customers.
SELECT COUNT(*)                AS paid_orders,
       COUNT(DISTINCT user_id) AS paid_customers
FROM orders_demo
WHERE order_status = 'paid';paid_orders paid_customers 5 3
Five paid orders came from 3 customers: U01, U02 and U03.
Does the same query work on the real orders table?
Yes. Only the table name changes.
SELECT
  order_status,
  COUNT(*)                   AS orders,
  ROUND(SUM(order_total), 2) AS gmv
FROM orders
GROUP BY order_status
ORDER BY gmv DESC;order_status orders gmv paid 93 43606.63 pending 29 14478.51 refunded 28 14082.4 cancelled 30 11248.61
The real table has a fourth status, refunded. Group buckets appear on their own, one per distinct value.
How does one query run, start to finish?
FROM orders_demo: 8 rows.
WHERE order_status = 'paid': 5 rows survive.
GROUP BY user_id: 3 buckets, U01, U02, U03.
HAVING SUM(order_total) >= 600: U01 (500) drops, U02 (800) and U03 (700) stay.
SELECT and ORDER BY: two summary rows, highest spender first.
Keep these.
- An aggregate turns many rows into one value.
- GROUP BY makes one output row per bucket.
- WHERE filters rows before grouping. HAVING filters buckets after.
- Every SELECT column must be grouped or aggregated.
- SQL runs FROM, WHERE, GROUP BY, HAVING, SELECT, ORDER BY.
Common beginner questions
What is the operational difference between COUNT(*), COUNT(column), and COUNT(DISTINCT column)?
COUNT(*) counts all rows in the group regardless of contents, including rows containing NULLs. COUNT(column) counts only rows where that specific column is NOT NULL. COUNT(DISTINCT column) counts the number of unique non-NULL values. For example, in our paid orders bucket of 5 rows, COUNT(*) is 5, but COUNT(DISTINCT user_id) is 3 because the 5 orders came from users U01, U02, and U03.
How do aggregate functions handle NULL values in calculations?
Numeric aggregate functions such as SUM, AVG, MIN, and MAX completely ignore NULL values. If an order has a NULL total, SUM adds up the non-NULL numbers, and AVG divides by the count of non-NULL rows. If every row in a group is NULL, SUM and AVG return NULL, while COUNT returns 0.
Why can I reference column aliases in ORDER BY but not in WHERE or HAVING?
Because SQL executes clauses in a specific logical order: FROM, WHERE, GROUP BY, HAVING, SELECT, and finally ORDER BY. Aliases defined in the SELECT list do not exist when WHERE and HAVING run. By the time ORDER BY executes, SELECT has finished evaluating, so ORDER BY can safely use your aliases.
Do I always need a GROUP BY clause when using aggregate functions?
No. If you omit GROUP BY, the query engine treats the entire table as one single group. That is why our first query returned exactly one summary row showing total orders and total GMV across the entire company.
What comes next
Everything in this lesson queried a single table. In production data pipelines, business entities are split across normalized tables, such as orders and payments. In the next lesson on Joins, you will learn how SQL matches records across tables using foreign keys, and how one-to-many relationships can create fan-out that accidentally distorts the aggregations you just learned.
Practice
Open the exercise tab and inspect the sample query. Group the orders table by order_status and calculate the order count alongside the sum of order_total aliased as gmv. Filter your query to include only statuses that have at least 5 orders, remembering to place group-level filters in HAVING rather than WHERE.
Going further: conditional counts and subtotals
Aggregation collapses many rows to one per group. Two tools extend it. FILTER counts or sums only some rows, so one pass can produce several columns. ROLLUP adds subtotal and grand total rows. Predict how many rows the second query returns.
The sales table.
| region | channel | amount |
|---|---|---|
| North | web | 100 |
| North | store | 60 |
| North | web | 40 |
| South | web | 70 |
| South | store | 30 |
SELECT region,
       SUM(amount)                                 AS total,
       SUM(amount) FILTER (WHERE channel = 'web')  AS web_total,
       COUNT(*)    FILTER (WHERE amount >= 60)     AS big_sales
FROM sales
GROUP BY region
ORDER BY regionregion total web_total big_sales North 200 140 2 South 100 70 1
One scan produced 3 measures per region. FILTER is the readable version of SUM(CASE WHEN ... THEN amount END).
SELECT region, channel, SUM(amount) AS total
FROM sales
GROUP BY ROLLUP (region, channel)
ORDER BY region NULLS LAST, channel NULLS LASTregion channel total North store 60 North web 140 North NULL 200 South store 30 South web 70 South NULL 100 NULL NULL 300
The NULL in channel marks a regional subtotal, and the row with both NULL is the grand total (300). The NULLs here mean 'all channels' and 'all regions', not missing data, so label them before you show the table to anyone.
Try a new scenario
For each channel, show the number of sales and the average sale amount, but only for channels with at least 3 sales. Which clause filters the channels?
Open the answer
HAVING filters groups after the aggregate is known, so the clause is HAVING COUNT(*) >= 3. The result is channel sales avg_amount ; web 3 70.0: only web has 3 or more sales. WHERE could not do this because it runs before the groups exist.
Interview: what is the difference between COUNT(*) and COUNT(column)?
COUNT(*) counts rows. COUNT(column) counts the rows where that column is not NULL, and COUNT(DISTINCT column) counts different non-NULL values. They differ whenever the column has missing values or repeats.
Close the lesson and explain it
Without scrolling up, explain the difference between WHERE and HAVING, and what a NULL means in a ROLLUP row.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this idea
Each page shows the idea moving, then lists problems from easiest. Open one now, or come back when you finish the lesson.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.
- Departments with more than three peopleInterview-style drill: HAVING filter for departments larger than 3 employees.Studiobeginnersql8 min
- Employee salary aggregatesInterview-style drill: Return count, average, min, and max salary across all employees.Studiobeginnersql8 min
- Conditional category revenueInterview-style drill: SUM CASE WHEN for Electronics and Clothing revenue in 1 row.Studiointermediatesql12 minLocked