
Overview
A primary key uniquely identifies each row. A foreign key connects one table to another.
On this page8 sections
The idea
How do you tell 2 customers named Priya Sharma apart?
Two ShopKart customers share a name. Support gets an email: cancel Priya Sharma's order. Names and addresses are ambiguous.
No 2 rows ever share an order_id. That is what makes a row identifiable.
| order_id | user_id | order_total (₹) |
|---|---|---|
| ORD-0001 | U004 | 612.07 |
| ORD-0002 | U073 | 446.70 |
| ORD-0003 | U078 | 1104.32 |
Real names, street addresses and job titles all repeat. Databases fix this with an id that no other row may use.
What is a primary key?
A primary key is the column that uniquely identifies every row. It enforces 2 rules.
Both rules together make a row identifiable.
| Rule | Meaning | In orders.order_id |
|---|---|---|
| Unique | No 2 rows share a value | ORD-0002 appears once |
| Never NULL | Every row must have a value | No order without an id |
A primary key is a column no 2 rows ever share.
Why not copy the order details into each payment?
A payment belongs to an order. You could copy the total, address and email into it.
Store a fact in one place and point to it.
| Approach | Payment row carries | When the address changes |
|---|---|---|
| Copy everything | Total, address, email, items | Update 10 places, miss one, data drifts |
| Point at the order | Only order_id | Update the order row once |
What is a foreign key?
A column in one table that holds the primary key of another table is a foreign key. It works as a pointer.
Each payment points at the row of orders whose order_id matches.
| payment_id | order_id (foreign key) | amount |
|---|---|---|
| PAY-0001 | ORD-0001 | 612.07 |
| PAY-0002 | ORD-0002 | 446.70 |
| PAY-0003 | ORD-0003 | 1104.32 |
A foreign key is a pointer to a primary key in another table.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Primary key | A column whose value is different in every row |
| Foreign key | A column that points at the primary key of another table |
| Constraint | A rule the database enforces, such as no repeats |
| Duplicate | The same record stored twice |
| Reference | A value in one table that points at a row in another |
| Join | Combining rows from two tables using a shared value |
Why this exists
What if a pipeline loads one order twice?
A faulty job loads ORD-0002 a second time, so a copy of the orders table now has 4 rows. No error appears anywhere.
ORD-0002 appears twice.
| order_id | order_total (₹) |
|---|---|
| ORD-0001 | 612.07 |
| ORD-0002 | 446.70 |
| ORD-0002 | 446.70 |
| ORD-0003 | 1104.32 |
Add up the column and you get 2,609.79. The real revenue is 2,163.09. The report looks healthier than reality, and someone decides from it.
What do constraints do about it?
A constraint is a rule the database enforces when rows are written.
A foreign key guarantees referential integrity: children point at parents that exist.
| Constraint | Rejects | Without it |
|---|---|---|
| Primary key | A second row with the same key | Duplicate rows, inflated totals |
| Foreign key | A child row pointing at nothing | Orphan payments no order can claim |
Orphans leave accountants unable to match bank deposits to purchases. Both constraints turn silent data corruption into a loud error at write time.
Picture this
Which payment finds which order?
Follow each arrow from a payment to its order.
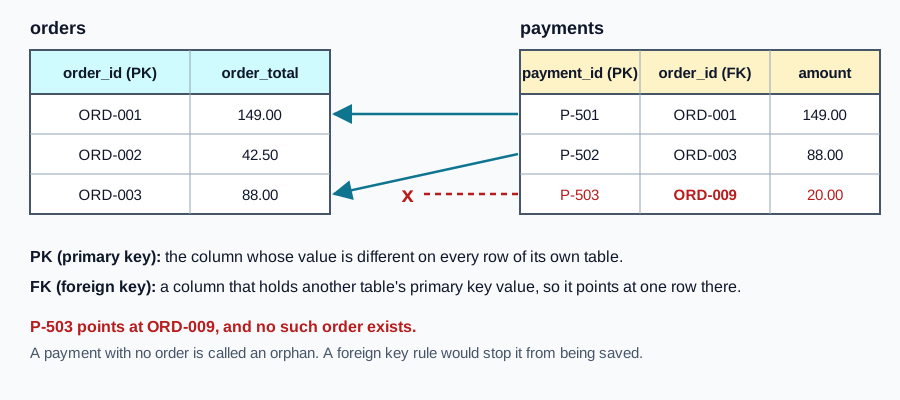
P-501 finds ORD-001 and P-502 finds ORD-003. P-503 carries ORD-009, which does not exist: an orphan.
Can a foreign key repeat?
Yes. One order can have many items, so the same order_id shows up on several order_items rows.
Only the parent key must be unique. The child column repeats freely.
| order_id (FK in order_items) | product_id | quantity | unit_price |
|---|---|---|---|
| ORD-0001 | SKU-017 | 3 | 152.54 |
| ORD-0001 | SKU-008 | 1 | 154.45 |
| ORD-0002 | SKU-004 | 2 | 206.15 |
| ORD-0002 | SKU-015 | 1 | 34.40 |
Each repeat is a different line item pointing at the same parent order. That is how one order owns many rows.
Which column plays which role?
1 column name, 2 jobs.
The shared order_id column is what lets a query connect a payment to its order.
In orders, order_id is the primary key. In payments, it is a foreign key. Keys let you keep small focused tables and still join them accurately.
Is this idea new?
No. The same lookup was drawn long before SQL, in a road-maintenance example from the US Department of Transportation.
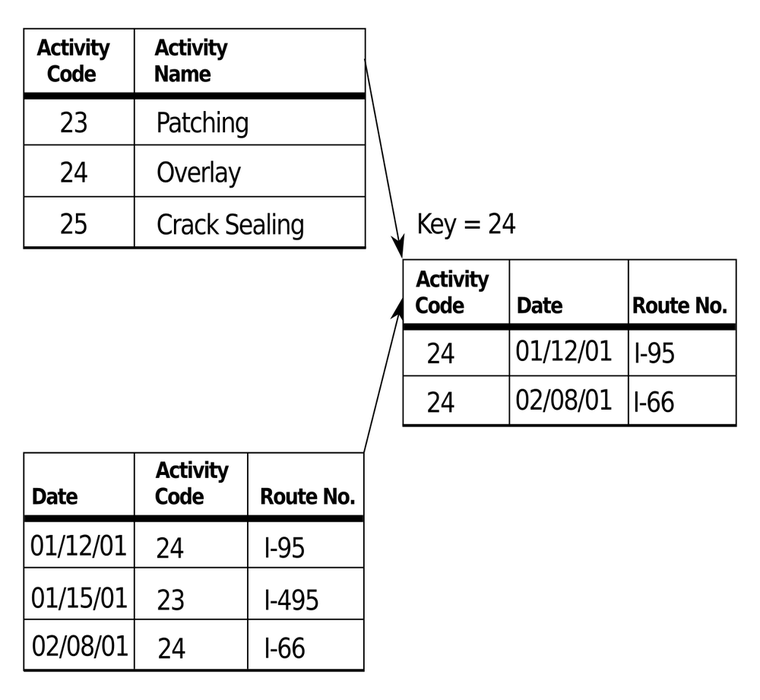
Pick key 24 and the arrows pull matching rows from both tables. The name 'Overlay' is stored once, not on every work record.
What kinds of key are there?
Three terms cover most conversations.
A composite key is for cases where no single column is unique but a pair is, like one product line on one order.
| Term | What it does | Example | What goes wrong without it |
|---|---|---|---|
| Primary key | Makes each row identifiable | orders.order_id | Duplicate rows, inflated totals |
| Foreign key | Points at a row in another table | payments.order_id | Orphan rows that belong to nothing |
| Composite key | 2 columns together are unique | (order_id, product_id) | Repeated line items on an order |
In textbooks, an order_items table uses the pair (order_id, product_id), since an order has many products and a product is in many orders.
Does the pair really stay unique in our order_items?
Never trust a design, test it. Here are the items on ORD-0003.
SELECT order_id, product_id, quantity, unit_price
FROM order_items
WHERE order_id = 'ORD-0003'
ORDER BY product_id;order_id product_id quantity unit_price ORD-0003 SKU-004 2 220.3 ORD-0003 SKU-023 3 190.36 ORD-0003 SKU-023 3 30.88
SKU-023 appears twice on one order. In this practice table, 9 pairs repeat, so the pair is not a safe key here.
Natural key or surrogate key?
A natural key already exists in the real world. A surrogate key is invented by the system.
Surrogate keys shield relationships from outside changes.
| Natural key | Surrogate key | |
|---|---|---|
| Examples | Email, tax id, vehicle registration | 1, 2, 3, a UUID, or a code like ORD-0001 |
| Change over time? | Yes: people change emails | No: immutable |
| Risk | Privacy rules, typos that force key updates | No business meaning |
| Warehouses prefer | Rarely | Usually |
If an email is the key and the customer changes it, every row that points at it must change too. A made-up id never needs to.
What makes a good key?
Check any candidate against 4 questions.
- Is it unique today? Run the GROUP BY check.
- Will it stay unique as new rows arrive?
- Is it always present, never NULL?
- Does it ever change? If yes, pick another.
Take email as a candidate for a customers table. It is unique today, but people change email addresses, and a few customers may share one. A key that changes breaks every row in other tables that pointed to it. A plain number like customer_id never changes and has no meaning, which is exactly why it makes a safe key.
A small example
How do you test whether a column is unique?
Rebuild the damaged table from real rows, then group by the supposed key.
CREATE OR REPLACE TABLE orders_copy AS
SELECT order_id, order_total
FROM orders
WHERE order_id IN ('ORD-0001', 'ORD-0002', 'ORD-0003');

INSERT INTO orders_copy VALUES ('ORD-0002', 446.70);

SELECT order_id, COUNT(*) AS copies
FROM orders_copy
GROUP BY order_id
HAVING COUNT(*) > 1;order_id copies ORD-0002 2
GROUP BY has its own lesson soon. Read it as: bundle rows by order_id, count each bundle, keep bundles larger than one.
Is order_id unique in the real orders table?
Same query, real table. Predict the result.
SELECT order_id, COUNT(*) AS copies
FROM orders
GROUP BY order_id
HAVING COUNT(*) > 1;order_id copies (0 rows)
An empty result is the pass. No bundle has more than 1 row, so no order_id repeats.
An empty uniqueness check is the good answer.
What happens when a real primary key sees a duplicate?
Declare PRIMARY KEY and the database enforces it. Predict what the second insert does.
DROP TABLE IF EXISTS payments_strict;
CREATE OR REPLACE TABLE orders_strict (
  order_id    VARCHAR PRIMARY KEY,
  order_total DECIMAL(8, 2)
);

INSERT INTO orders_strict VALUES ('ORD-0001', 612.07);
INSERT INTO orders_strict VALUES ('ORD-0001', 200.00);Constraint Error: Duplicate key "order_id: ORD-0001" violates primary key constraint.
ORD-0001 is already taken, so the row is refused. A new order needs a new key.
Can a primary key be NULL?
No. That is the second rule. Try to insert a row with no order_id.
INSERT INTO orders_strict VALUES (NULL, 200.00);Constraint Error: NOT NULL constraint failed: orders_strict.order_id
A row you cannot identify is a row you cannot find, update or delete safely.
What happens when a foreign key points at nothing?
Declare the link with REFERENCES and the database guards it. Predict what happens to PAY-0099.
CREATE OR REPLACE TABLE payments_strict (
  payment_id VARCHAR PRIMARY KEY,
  order_id   VARCHAR REFERENCES orders_strict (order_id)
);

INSERT INTO payments_strict VALUES ('PAY-0001', 'ORD-0001');
INSERT INTO payments_strict VALUES ('PAY-0099', 'ORD-0009');Constraint Error: Violates foreign key constraint because key "order_id: ORD-0009" does not exist in the referenced table
PAY-0001 is accepted because ORD-0001 exists. PAY-0099 is refused, so an orphan can never get in.
A foreign key constraint means no child row without a parent.
Does any payment point at an order that does not exist?
Detect orphans by joining the child to the parent and keeping rows with no parent. JOIN has its own lesson later. For now read it as: take every payment, attach its order if one exists, and keep the payments where no order was found.
SELECT p.payment_id, p.order_id
FROM payments p
LEFT JOIN orders o ON p.order_id = o.order_id
WHERE o.order_id IS NULL;payment_id order_id (0 rows)
Zero rows, so every payment finds its order here. Run this after every load, because orphans appear when a parent row is deleted or a file arrives out of order.
What goes wrong when you join on a shared column name?
order_id exists in both tables. Predict what happens if you select it without saying which.
SELECT order_id
FROM payments
JOIN orders ON payments.order_id = orders.order_id
LIMIT 5;Binder Error: Ambiguous reference to column name "order_id" (use: "payments.order_id" or "orders.order_id")
LINE 1: SELECT order_id FROM payments JOIN orders ON payments.order_id...
^The engine cannot guess which table you mean, so it stops instead of picking one. Put the table name in front of the column.
How do you fix it?
Prefix each column with its table name.
SELECT orders.order_id, payments.payment_id
FROM payments
JOIN orders ON payments.order_id = orders.order_id
LIMIT 2;order_id payment_id ORD-0001 PAY-0001 ORD-0002 PAY-0002
ORD-0001 connects to PAY-0001 across the shared key.
Do warehouses enforce keys?
It depends on the kind of database.
Checking billions of rows on every insert would slow bulk loads.
| System | Examples | Rejects a duplicate key on insert? |
|---|---|---|
| Databases that enforce keys | PostgreSQL, MySQL, DuckDB | Yes |
| Cloud warehouse | Snowflake, BigQuery, Redshift | Typically no: keys are declared as documentation |
A well-built production database can reject a duplicate key or an orphan row on the spot. Data that arrives from files and pipelines often has no such guard, so duplicates slip in. That is why you check uniqueness yourself instead of assuming it.
So who checks the keys?
Your pipeline does, after every load. Tools like dbt run these assertion queries for you.
- Load a batch
- Run the uniqueness query
- Run the orphan query
- Any rows? Fail the pipeline
Never trust a PRIMARY KEY declaration in a warehouse. Verify with a query. A common interview question is how referential integrity survives when the engine does not enforce it, and this is the answer.
Can a foreign key be NULL?
Yes, when a relationship is optional, like a guest checkout with no customer account.
A plain join silently drops rows with a NULL key. Plan for them.
| order | customer_id | Customer found by a plain join? |
|---|---|---|
| ORD-A (illustrative) | C-77 | Yes |
| ORD-B (guest) | NULL | No: the row drops out of the report |
How does the whole lesson replay on one question?
Names repeat, so each order gets order_id as its primary key.
Payments store order_id as a foreign key and point at the order.
A pipeline loads ORD-0002 twice. GROUP BY order_id HAVING COUNT(*) > 1 finds it.
The real orders table returns zero rows, so order_id is unique.
A LEFT JOIN with a missing parent finds orphan payments. Zero here.
Remember these.
- A primary key is unique and never NULL. It identifies a row.
- A foreign key stores another table's primary key. It points at a row.
- Surrogate keys are system-made and stable. Natural keys come from the real world and change.
- A warehouse often will not enforce keys. Test uniqueness and orphans yourself.
- Prefix shared column names with their table name when you join.
Common beginner questions
Can a table have no primary key?
Some do, but it is risky. Without a key you cannot easily tell a genuine second order from an accidental duplicate. Well-designed tables always have one.
Does a foreign key have to be unique?
No. One order can have two payments, so ORD-0003 could appear twice in payments. It is the primary key in the other table that has to be unique.
What is a surrogate key?
An id the system invents just to identify rows, like payment number P-501. It has no business meaning. A natural key comes from the real data, like an email address. Both are used, and later modelling lessons explain when to pick which.
What comes next
That finishes the vocabulary. Next you start writing real queries: SELECT and WHERE on a single table first, and a few lessons later you will use these keys to join tables. Later, keys also tie fact tables to dimension tables in star schemas.
Practice
Check whether order_id is really unique in the orders table. Use the grouping pattern from this lesson, and remember that a table with unique keys should give you an empty result. The exercise checks that you grouped and filtered the groups the right way.
Going further: what happens at the edge of a foreign key
A foreign key promises that every order points at a real customer. The interesting questions are at the edges: can you add an order for a missing customer, and can you delete a customer who still has orders? Predict both.
INSERT INTO orders VALUES (13, 99, 10);
DELETE FROM customers WHERE customer_id = 1;
SELECT c.name, COUNT(o.order_id) AS orders FROM customers c LEFT JOIN orders o USING (customer_id) GROUP BY c.name ORDER BY c.nameError: Constraint Error: Violates foreign key constraint because key "customer_id: 99" does not exist in the referenced table Error: Constraint Error: Violates foreign key constraint because key "customer_id: 1" is still referenced by a foreign key in a different table. If this is an unexpected constraint violation, please refer to our foreign key limitations in the documentation name orders Asha 2 Ben 1 Chen 0
Both statements were refused. The database will not create an orphan (an order whose customer does not exist), and it will not delete a parent that children still point at. The count query at the end confirms nothing changed.
The names are standard SQL, but not every engine supports every option. Check yours.
| When you delete a parent row that has children | What happens | Typical use |
|---|---|---|
| Restrict or no action (the default in most engines) | The delete is refused | Financial data you must not lose |
| Cascade | The children are deleted too (engine dependent) | Rows that make no sense alone, such as order items |
| Set null | The child's key becomes NULL | Optional links |
Warehouses often do not enforce foreign keys at all, to keep loads fast. The key is documentation there, and you check it yourself with a query for orphans.
CREATE TABLE customers (customer_id INTEGER, name VARCHAR);
CREATE TABLE orders (order_id INTEGER, customer_id INTEGER);
INSERT INTO customers VALUES (1,'Asha'),(2,'Ben');
INSERT INTO orders VALUES (10,1),(11,2),(12,7);
SELECT o.order_id, o.customer_id
FROM orders o
LEFT JOIN customers c ON c.customer_id = o.customer_id
WHERE c.customer_id IS NULLorder_id customer_id 12 7
Try a new scenario
An order_items table points at orders. Which delete behaviour fits when an order is deleted, and which fits when a product that appears on old orders is deleted?
Work it out, then open the answer
Items have no meaning without their order, so cascading the delete from orders to items is reasonable. A product that old orders refer to should not be deletable (restrict), or you lose the history of what was sold. Better still, mark the product inactive instead of deleting it.
Interview: surrogate key or natural key?
A natural key comes from the real world, such as an email, and can change or repeat. A surrogate key is a made-up identifier with no meaning, which stays stable. Many tables use a surrogate primary key and keep the natural key under a unique constraint.
Close the lesson and explain it
Without scrolling up, explain what an orphan row is and how you would find one when the database does not enforce the key.
Finished this lesson?
Mark it as read when you could explain it to someone else.