
Overview
Window functions compute across related rows without collapsing them into one summary line.
On this page8 sections
The table we keep using
What does the slice look like?
Look at event_id. E17 appears twice, E42 3 times and E55 twice.
events_demo: 7 rows, but only 3 real events. E55 arrived twice in the same minute.
| event_id | user_id | event_type | ingest_time |
|---|---|---|---|
| E17 | U10 | purchase | 2026-08-01 03:02 |
| E17 | U10 | purchase | 2026-08-01 03:09 |
| E42 | U11 | page_view | 2026-08-01 02:58 |
| E42 | U11 | page_view | 2026-08-01 03:07 |
| E42 | U11 | page_view | 2026-08-01 03:19 |
| E55 | U12 | add_to_cart | 2026-08-01 04:15 |
| E55 | U12 | add_to_cart | 2026-08-01 04:15 |
Why does an events table hold the same event twice?
A phone sends 'user bought something', gets no answer, and sends it again. Now the table holds the event twice and the purchase count is wrong by one.
- Phone sends event
- No reply arrives
- Phone sends it again
- Table has 2 rows
Each row is one arrival. ingest_time is when the row reached our system.
Can you build this table yourself?
Yes. Run this once and every query below works on the same 7 rows.
CREATE OR REPLACE TABLE events_demo (
  event_id VARCHAR, user_id VARCHAR, event_type VARCHAR, ingest_time TIMESTAMP
);
INSERT INTO events_demo VALUES
  ('E17', 'U10', 'purchase',    TIMESTAMP '2026-08-01 03:02:00'),
  ('E17', 'U10', 'purchase',    TIMESTAMP '2026-08-01 03:09:00'),
  ('E42', 'U11', 'page_view',   TIMESTAMP '2026-08-01 02:58:00'),
  ('E42', 'U11', 'page_view',   TIMESTAMP '2026-08-01 03:07:00'),
  ('E42', 'U11', 'page_view',   TIMESTAMP '2026-08-01 03:19:00'),
  ('E55', 'U12', 'add_to_cart', TIMESTAMP '2026-08-01 04:15:00'),
  ('E55', 'U12', 'add_to_cart', TIMESTAMP '2026-08-01 04:15:00');
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Window function | A calculation across related rows that keeps every row |
| PARTITION BY | Split rows into groups for the window |
| ORDER BY | Say which row comes first inside the group |
| ROW_NUMBER | Number the rows in a group 1, 2, 3 |
| Duplicate | The same record stored twice |
| Dedupe | Keep one row from each group of copies |
What we need from it
Why can't GROUP BY give us the whole row?
We want 1 row per event, the latest arrival, with all its columns. GROUP BY gets close. Predict how many rows come back.
SELECT event_id, COUNT(*) AS copies, MAX(ingest_time) AS latest
FROM events_demo
GROUP BY event_id
ORDER BY event_id;event_id copies latest E17 2 2026-08-01 03:09:00 E42 3 2026-08-01 03:19:00 E55 2 2026-08-01 04:15:00
3 rows, but user_id and event_type are gone. The other rows in each group were flattened away.
What does a window do differently?
A window looks at a group of rows without collapsing them. Every row stays, and each gets an extra column about its group.
Both look at a group of rows. Only one still lets you see each row afterwards.
GROUP BY collapses rows. A window function keeps them.
Trace it step by step
What is the shape of every window function?
The recipe has three parts and reads almost like English.
function() OVER (
  PARTITION BY  grouping_column   -- who shares a window
  ORDER BY      sort_column       -- the sequence inside it
)
PARTITION BY splits rows into independent groups, like GROUP BY but the rows stay. ORDER BY sorts the rows inside each group. Either part can be left out.
Step 1: how do you count the copies without losing any?
A plain COUNT becomes a window function when you add OVER. No ORDER BY is needed, because a count ignores order.
SELECT event_id, ingest_time,
       COUNT(*) OVER (PARTITION BY event_id) AS copies
FROM events_demo
ORDER BY event_id, ingest_time;event_id ingest_time copies E17 2026-08-01 03:02:00 2 E17 2026-08-01 03:09:00 2 E42 2026-08-01 02:58:00 3 E42 2026-08-01 03:07:00 3 E42 2026-08-01 03:19:00 3 E55 2026-08-01 04:15:00 2 E55 2026-08-01 04:15:00 2
7 rows in, 7 rows out. Each row carries its group's count.
Step 2: how do you number the copies, newest first?
A count gives the group size. To pick 1 row you need a rank. ROW_NUMBER() hands out 1, 2, 3 inside each partition, and DESC puts the newest at 1.
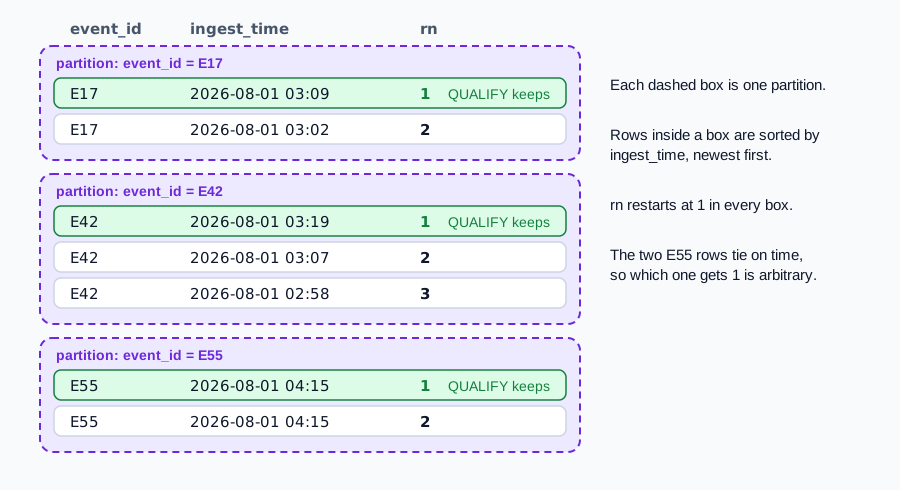
In the E42 box the arrivals sort as 03:19, 03:07, 02:58, so they get 1, 2, 3. Then numbering restarts for E55. The green rows are the ones we keep.
SELECT event_id, user_id, event_type, ingest_time,
       ROW_NUMBER() OVER (
         PARTITION BY event_id
         ORDER BY ingest_time DESC
       ) AS rn
FROM events_demo
ORDER BY event_id, rn;event_id user_id event_type ingest_time rn E17 U10 purchase 2026-08-01 03:09:00 1 E17 U10 purchase 2026-08-01 03:02:00 2 E42 U11 page_view 2026-08-01 03:19:00 1 E42 U11 page_view 2026-08-01 03:07:00 2 E42 U11 page_view 2026-08-01 02:58:00 3 E55 U12 add_to_cart 2026-08-01 04:15:00 1 E55 U12 add_to_cart 2026-08-01 04:15:00 2
Still 7 rows. The new column rn is what we filter on. Try the player below, and predict each step before you reveal it.
Same table, next cut
Cut 1: why does WHERE rn = 1 fail?
WHERE runs before window functions are calculated, so rn does not exist yet. Predict the error.
SELECT event_id, user_id, event_type, ingest_time,
       ROW_NUMBER() OVER (
         PARTITION BY event_id ORDER BY ingest_time DESC
       ) AS rn
FROM events_demo
WHERE rn = 1;Binder Error: WHERE clause cannot contain window functions!
LINE 2: ROW_NUMBER() OVER (
^DuckDB lets WHERE see the alias rn and then complains about the window function inside it. Other engines say the column rn does not exist. Either way, the rule is the same.
How does QUALIFY keep the latest row?
QUALIFY is the clause that filters on a window result. It runs after the window is calculated.
SELECT event_id, user_id, event_type, ingest_time
FROM events_demo
QUALIFY ROW_NUMBER() OVER (
  PARTITION BY event_id
  ORDER BY ingest_time DESC
) = 1
ORDER BY event_id;event_id user_id event_type ingest_time E17 U10 purchase 2026-08-01 03:09:00 E42 U11 page_view 2026-08-01 03:19:00 E55 U12 add_to_cart 2026-08-01 04:15:00
7 rows became 3: 1 row per real event, with all its columns.
Rank in a window, then keep rank 1.
What if your database has no QUALIFY?
DuckDB, Snowflake and BigQuery have it. PostgreSQL and MySQL do not. The version that works everywhere ranks in a CTE, then filters.
WITH ranked AS (
  SELECT event_id, user_id, event_type, ingest_time,
         ROW_NUMBER() OVER (
           PARTITION BY event_id
           ORDER BY ingest_time DESC
         ) AS rn
  FROM events_demo
)
SELECT event_id, user_id, event_type, ingest_time
FROM ranked
WHERE rn = 1
ORDER BY event_id;event_id user_id event_type ingest_time E17 U10 purchase 2026-08-01 03:09:00 E42 U11 page_view 2026-08-01 03:19:00 E55 U12 add_to_cart 2026-08-01 04:15:00
Same 3 rows. This is the standard way to drop late or replayed duplicates from an event stream. You will meet it again in the PySpark and streaming tracks.
E55 arrived twice at exactly 04:15, so ROW_NUMBER can give rn = 1 to either copy. Here the 2 rows are identical, so it does not matter. When copies differ, add a second sort column, such as ORDER BY ingest_time DESC, event_id.
Cut 2: how do ROW_NUMBER, RANK and DENSE_RANK treat ties?
2 rows can share a sort value. Three functions handle that differently. Here is a small scores table to see it.
CREATE OR REPLACE TABLE scores_demo (department VARCHAR, student_name VARCHAR, score INTEGER);
INSERT INTO scores_demo VALUES
  ('Data', 'Aarav', 95), ('Data', 'Diya', 90), ('Data', 'Kabir', 90),
  ('Data', 'Neha', 85),  ('Data', 'Rohan', 75),
  ('Cloud', 'Pooja', 98), ('Cloud', 'Ananya', 92), ('Cloud', 'Vikram', 92);
Predict the numbers for Diya and Kabir (both 90) and for Neha (85).
SELECT student_name, score,
       ROW_NUMBER() OVER (ORDER BY score DESC, student_name) AS row_num,
       RANK()       OVER (ORDER BY score DESC) AS rnk,
       DENSE_RANK() OVER (ORDER BY score DESC) AS dense_rnk
FROM scores_demo
WHERE department = 'Data'
ORDER BY score DESC, student_name;student_name score row_num rnk dense_rnk Aarav 95 1 1 1 Diya 90 2 2 2 Kabir 90 3 2 2 Neha 85 4 4 3 Rohan 75 5 5 4
Diya and Kabir tie. RANK gives both 2, then skips 3 and jumps to 4. DENSE_RANK gives both 2 and continues with 3.
Pick by what should happen after a tie.
| Function | Result on the tie | Use it for |
|---|---|---|
| ROW_NUMBER() | 1, 2, 3, 4 | Exactly one winner, such as deduplication |
| RANK() | 1, 2, 2, 4 | Podium ranks with gaps |
| DENSE_RANK() | 1, 2, 2, 3 | Tiers without gaps, such as top-N salary levels |
ROW_NUMBER never repeats, so we added student_name to settle the tie.
Cut 3: how do you build a running total?
A window can look at neighbouring rows in sequence. For that we need numbers over days. Here are 5 days of revenue.
CREATE OR REPLACE TABLE daily_demo (report_date DATE, revenue DOUBLE);
INSERT INTO daily_demo VALUES
  (DATE '2026-08-01', 1000), (DATE '2026-08-02', 1500), (DATE '2026-08-03', 1200),
  (DATE '2026-08-04', 1800), (DATE '2026-08-05', 2000);
A frame (ROWS BETWEEN) says which neighbouring rows the window may use. Predict day 3's moving average of 3 days.
SELECT report_date, revenue,
       SUM(revenue) OVER (
         ORDER BY report_date
         ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
       ) AS running_total,
       ROUND(AVG(revenue) OVER (
         ORDER BY report_date
         ROWS BETWEEN 2 PRECEDING AND CURRENT ROW
       ), 1) AS moving_avg_3d
FROM daily_demo
ORDER BY report_date;report_date revenue running_total moving_avg_3d 2026-08-01 1000 1000 1000 2026-08-02 1500 2500 1250 2026-08-03 1200 3700 1233.3 2026-08-04 1800 5500 1500 2026-08-05 2000 7500 1666.7
Day 3 is (1000 + 1500 + 1200) / 3 = 1233.3. The 3-row window slides forward 1 row each day.
These frames come up most often.
- UNBOUNDED PRECEDING to CURRENT ROW: a running total from the first row.
- 2 PRECEDING to CURRENT ROW: the current row plus the two before it.
- 1 PRECEDING to 1 FOLLOWING: a centred 3-row average.
- UNBOUNDED PRECEDING to UNBOUNDED FOLLOWING: the whole partition, for percent of total or global extremes.
What frame do you get if you write none?
With an ORDER BY inside OVER and no frame, the default runs from the first row to the current row. So the default SUM is also a running total.
SELECT report_date, revenue,
       SUM(revenue) OVER (ORDER BY report_date) AS default_frame_total
FROM daily_demo
ORDER BY report_date;report_date revenue default_frame_total 2026-08-01 1000 1000 2026-08-02 1500 2500 2026-08-03 1200 3700 2026-08-04 1800 5500 2026-08-05 2000 7500
The totals match the explicit version. But the default is RANGE, not ROWS, and that difference shows on ties.
What is the difference between ROWS and RANGE?
ROWS counts physical rows, while RANGE treats equal sort values as peers. The two E55 rows tie on ingest_time. Predict the last two counts.
SELECT event_id, ingest_time,
       COUNT(*) OVER (ORDER BY ingest_time) AS running_range,
       COUNT(*) OVER (
         ORDER BY ingest_time
         ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
       ) AS running_rows
FROM events_demo
ORDER BY ingest_time, event_id;event_id ingest_time running_range running_rows E42 2026-08-01 02:58:00 1 1 E17 2026-08-01 03:02:00 2 2 E42 2026-08-01 03:07:00 3 3 E17 2026-08-01 03:09:00 4 4 E42 2026-08-01 03:19:00 5 5 E55 2026-08-01 04:15:00 7 6 E55 2026-08-01 04:15:00 7 7
RANGE counts both E55 rows at once, so both show 7. ROWS counts 1 row at a time, 6 then 7.
Everything up to here is the core of window functions. Cuts 4 to 7 are extras that come up in reports and interviews. Read them now, or come back once the dedupe pattern feels natural.
Cut 4: why does LAST_VALUE just repeat the current row?
FIRST_VALUE and LAST_VALUE return the first or last value in the frame. The default frame stops at the current row. Predict last_rev_trap.
SELECT report_date, revenue,
       FIRST_VALUE(revenue) OVER (ORDER BY report_date) AS first_rev,
       LAST_VALUE(revenue)  OVER (ORDER BY report_date) AS last_rev_trap,
       LAST_VALUE(revenue)  OVER (
         ORDER BY report_date
         ROWS BETWEEN UNBOUNDED PRECEDING AND UNBOUNDED FOLLOWING
       ) AS last_rev_fixed
FROM daily_demo
ORDER BY report_date;report_date revenue first_rev last_rev_trap last_rev_fixed 2026-08-01 1000 1000 1000 2000 2026-08-02 1500 1000 1500 2000 2026-08-03 1200 1000 1200 2000 2026-08-04 1800 1000 1800 2000 2026-08-05 2000 1000 2000 2000
last_rev_trap copies each row's own revenue, because the frame ends at the current row. To see the true last value, extend the frame to UNBOUNDED FOLLOWING.
The default frame ends at the current row, so LAST_VALUE cannot see ahead.
Cut 5: how do you get day-over-day growth?
LAG fetches the value from the previous row. Predict growth_pct for day 2.
SELECT report_date, revenue,
       LAG(revenue) OVER (ORDER BY report_date) AS prev_day_revenue,
       ROUND(100.0 * (revenue - LAG(revenue) OVER (ORDER BY report_date))
         / NULLIF(LAG(revenue) OVER (ORDER BY report_date), 0), 1) AS growth_pct
FROM daily_demo
ORDER BY report_date;report_date revenue prev_day_revenue growth_pct 2026-08-01 1000 NULL NULL 2026-08-02 1500 1000 50 2026-08-03 1200 1500 -20 2026-08-04 1800 1200 50 2026-08-05 2000 1800 11.1
Day 1 has no previous row, so LAG gives NULL. NULLIF avoids dividing by zero. LEAD does the same thing looking forward.
How do you get percent of total?
Use an empty OVER (). It makes one window out of the whole table, so SUM(revenue) OVER () is the grand total on every row.
SELECT report_date, revenue,
       SUM(revenue) OVER () AS grand_total,
       ROUND(100.0 * revenue / SUM(revenue) OVER (), 1) AS pct_of_total
FROM daily_demo
ORDER BY report_date;report_date revenue grand_total pct_of_total 2026-08-01 1000 7500 13.3 2026-08-02 1500 7500 20 2026-08-03 1200 7500 16 2026-08-04 1800 7500 24 2026-08-05 2000 7500 26.7
August 5 brought in 26.7 percent of the week's revenue.
Cut 6: how do you split rows into quartiles?
NTILE(n) deals rows into n roughly equal buckets, numbered 1 to n. It is common in customer scoring.
SELECT student_name, score,
       NTILE(4) OVER (ORDER BY score DESC) AS quartile
FROM scores_demo
WHERE department = 'Data'
ORDER BY score DESC;student_name score quartile Aarav 95 1 Diya 90 1 Kabir 90 2 Neha 85 3 Rohan 75 4
5 rows into 4 buckets: the first bucket gets the extra row. Kabir and Diya tie at 90 yet land in different quartiles, so NTILE splits ties.
Which of the two lands in quartile 1 is not guaranteed, so add a tie-break column to the ORDER BY when it matters.
How do you find the top 2 per group?
This is a classic interview question. Rank inside each department in a CTE, then keep ranks 1 and 2.
WITH ranked AS (
  SELECT department, student_name, score,
         DENSE_RANK() OVER (
           PARTITION BY department
           ORDER BY score DESC
         ) AS rnk
  FROM scores_demo
)
SELECT department, student_name, score, rnk
FROM ranked
WHERE rnk <= 2
ORDER BY department, rnk, student_name;department student_name score rnk Cloud Pooja 98 1 Cloud Ananya 92 2 Cloud Vikram 92 2 Data Aarav 95 1 Data Diya 90 2 Data Kabir 90 2
Each department returns its top 2 tiers. DENSE_RANK keeps both tied students; ROW_NUMBER would have dropped one.
Cut 7: how do you reuse one window?
When several functions share the same window, name it once with WINDOW at the end of the query.
SELECT report_date, revenue,
       SUM(revenue) OVER w AS running_total,
       ROUND(AVG(revenue) OVER w, 1) AS running_avg
FROM daily_demo
WINDOW w AS (
  ORDER BY report_date
  ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
)
ORDER BY report_date;report_date revenue running_total running_avg 2026-08-01 1000 1000 1000 2026-08-02 1500 2500 1250 2026-08-03 1200 3700 1233.3 2026-08-04 1800 5500 1375 2026-08-05 2000 7500 1500
Both columns use the same window, defined once as w.
ORDER BY inside OVER decides which row is first within each partition. The ORDER BY at the very end of the query decides how the final result is displayed. They are independent, and getting rn right says nothing about the display order.
How does the whole dedupe run, start to finish?
events_demo has 7 rows but only 3 real events, because phones retry.
PARTITION BY event_id puts the copies of each event in one window.
ORDER BY ingest_time DESC with ROW_NUMBER gives the newest copy rn = 1.
QUALIFY ... = 1 (or a CTE with WHERE rn = 1) keeps only that row.
7 rows become 3, each with user_id and event_type intact.
Keep these.
- A window function adds a column and keeps every row. GROUP BY collapses them.
- OVER (PARTITION BY who ORDER BY sequence) is the shape of every window.
- WHERE cannot see a window result. Use QUALIFY, or rank in a CTE and filter after.
- Dedupe recipe: ROW_NUMBER() newest first, keep rn = 1. Add a tie-breaker.
- Write the frame when you use LAST_VALUE or moving averages.
WHERE runs before window functions, so WHERE rn = 1 fails. Use QUALIFY if your database has it, or compute the window in a CTE and filter in the next query.
ROW_NUMBER() OVER (PARTITION BY event_id ORDER BY ingest_time DESC), then keep rn = 1 in a later step.
Common beginner questions
Do I always need PARTITION BY?
No. Leave it out and the entire result is one big partition. ROW_NUMBER() OVER (ORDER BY ingest_time DESC) would number all 7 rows from 1 to 7, which is useful for a global ranking.
Can I use more than one window function in the same query?
Yes. Each has its own OVER clause, and they can use different partitions and orders, like the rn and rnk columns above.
What is the difference between ROWS and RANGE in window frames?
ROWS counts physical rows (for example, 2 PRECEDING means exactly 2 physical rows back). RANGE looks at value offsets in the ORDER BY column, treating rows with identical sort values as peers and expanding the frame to include all ties.
Why does LAST_VALUE repeat the current row without an explicit frame?
Because ANSI SQL defaults to RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW when an ORDER BY is present. The frame stops at the current row, so the engine cannot see any later values unless you specify UNBOUNDED FOLLOWING.
What comes next
You now have the full set of analytical window tools: frames, rankings, offsets, running totals, and moving averages.
The next lesson, Data cleaning, takes the other side of the job, fixing messy values like NULL statuses, padded text and wrong date grains, so that the rows you group and rank are trustworthy to begin with.
Practice
The exercise asks for a ROW_NUMBER() column called rn, partitioned by event_id and ordered by ingest_time descending, returning event_id, ingest_time and rn for 20 rows.
Run the sample first to see QUALIFY keep only the winners. Then write your own version that shows every row with its number, and check that the numbering restarts at 1 for each new event_id.
Going deeper: window or GROUP BY, and the cases that surprise people
You already know the pieces: PARTITION BY, ORDER BY, ranking functions and frames. Here is one table to keep in front of you while you decide between a window and a GROUP BY, and while you look at the edge cases that produce wrong numbers without any error.
The sales table for this section. Esha's amount is missing on purpose.
| region | rep | day | amount |
|---|---|---|---|
| North | Asha | 2026-09-01 | 100 |
| North | Ben | 2026-09-01 | 100 |
| North | Chen | 2026-09-02 | 80 |
| South | Dev | 2026-09-01 | 60 |
| South | Esha | 2026-09-02 | NULL |
| South | Farid | 2026-09-03 | 90 |
The first question: fewer rows, or the same rows?
SELECT region, SUM(amount) AS region_total
FROM sales
GROUP BY region
ORDER BY region;
GROUP BY returns 1 row per region. The window version keeps all 6 rows and attaches the regional total to each, so you can still compare a rep with the total. Predict how many rows each query returns before you open the outputs.
region  region_total
North   280
South   150
region  rep    amount  region_total
North   Asha   100     280
North   Ben    100     280
North   Chen   80      280
South   Dev    60      150
South   Esha   NULL    150
South   Farid  90      150
Case 1: a NULL changes more than one result
NULL is not zero. Esha's missing amount is ignored by SUM and AVG, but it still occupies a row. LAG with a default only fills in when there is no previous row at all; a previous row that holds NULL gives you NULL back. Predict Farid's prev_or_zero.
SELECT rep, amount,
       LAG(amount, 1, 0) OVER (PARTITION BY region ORDER BY day) AS prev_or_zero
FROM sales
WHERE region = 'South'
ORDER BY day;rep amount prev_or_zero Dev 60 0 Esha NULL 60 Farid 90 NULL
Farid's previous row is Esha, whose amount is NULL, so the answer is NULL, not 0. If you want 0, wrap the value: COALESCE(amount, 0) before you take the LAG, or around the result.
Decide what NULL should mean first. Also note where NULLs sort: engines differ on whether NULLs come first or last in a descending sort, so write NULLS LAST or NULLS FIRST when it matters.
Case 2: a tie makes ROW_NUMBER an arbitrary choice
Asha and Ben both sold 100. ROW_NUMBER must give them different numbers, and with ORDER BY amount alone the database may order them either way, and that can change from run to run. RANK gives both 1, and DENSE_RANK also gives both 1 but continues with 2 afterwards.
SELECT rep, amount,
       ROW_NUMBER() OVER (ORDER BY amount DESC, rep) AS rn,
       RANK()       OVER (ORDER BY amount DESC)      AS rk,
       DENSE_RANK() OVER (ORDER BY amount DESC)      AS dr
FROM sales
WHERE region = 'North'
ORDER BY rn;rep amount rn rk dr Asha 100 1 1 1 Ben 100 2 1 1 Chen 80 3 3 2
Look at Chen: RANK jumps to 3 because two people are ahead, while DENSE_RANK goes to 2. When you need exactly 1 row per group, add a tie-breaker (here, rep) to the ORDER BY so the choice is repeatable.
Case 3: you cannot filter on a window result directly
WHERE runs before windows are computed, so WHERE rn = 1 is invalid. Compute the number in a CTE or subquery, then filter outside it.
WITH ranked AS (
  SELECT region, rep, amount,
         ROW_NUMBER() OVER (PARTITION BY region
                            ORDER BY amount DESC NULLS LAST, rep) AS rn
  FROM sales
)
SELECT region, rep, amount
FROM ranked
WHERE rn = 1
ORDER BY region;region rep amount North Asha 100 South Farid 90
Try a new scenario
For every row in the sales table, show the gap between that rep's amount and the best amount in the same region, and a running total of amount by day within the region. Break ties by rep. Predict the gap for Esha and the running total for Esha before you check.
SELECT region, rep, day, amount,
       MAX(amount) OVER (PARTITION BY region) - amount AS gap_to_best,
       SUM(amount) OVER (PARTITION BY region
                         ORDER BY day, rep
                         ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW) AS running_total
FROM sales
ORDER BY region, day, rep;
Open the answer
The gap is NULL for Esha, because the best amount minus NULL is NULL. The running total for Esha is 60, because SUM ignores NULL and the earlier row contributed 60. Output: North rows gap 0, 0, 20 with totals 100, 200, 280. South rows gap 30, NULL, 0 with totals 60, 60, 150.
Why does ROWS BETWEEN matter when the running total uses ORDER BY day, rep?
Because day alone has a tie in North on 2026-09-01. With ORDER BY day and the default RANGE frame, Asha and Ben are peers and both see 200. Adding rep as a tie-breaker and using ROWS makes each row see only the rows up to itself.
Close the lesson and explain it
Without scrolling up, explain when you would choose a window function over GROUP BY, and name one way a NULL or a tie can make a correct-looking query wrong.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this idea
Each page shows the idea moving, then lists problems from easiest. Open one now, or come back when you finish the lesson.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.
- 3-day moving average of transactionsInterview-style drill: 3-day moving average over daily transaction totals.Studiointermediatesql12 min
- Sessionize events with 30-minute gapsInterview-style drill: Build sessions where a gap > 30 minutes starts a new session.Studiointermediatesql12 min
- Cities where cases rose every dayInterview-style drill: Filter for cities whose daily case count strictly increased on every single recorded day.Studiointermediatesql16 minLocked