
Overview
Data is recorded information. Structured data lives in tables with rows and columns. Unstructured data is everything else.
On this page8 sections
The idea
You do not need any programming or database background for this track. Every word is explained the first time it appears, and the SQL editor in this tab already has real tables loaded, so there is nothing to install.
What happens to your order after you tap pay?
You buy a keyboard on ShopKart. The server writes the facts of that purchase into storage.
- You tap pay
- App sends the order to a server
- Server writes the facts down
- Storage keeps them for later
Those recorded facts are data. Each single fact, like a status, a price or a timestamp, is one data value. Saving them is what lets anyone check later what happened.
Data is a fact someone recorded so it can be checked later.
What does one order's data look like?
ShopKart keeps 1 row per order. Here are the first 3 orders, exactly as the warehouse stores them.
3 orders, 4 columns, 12 data values. We keep using these rows on this page.
| order_id | user_id | order_status | order_total (₹) |
|---|---|---|---|
| ORD-0001 | U004 | paid | 612.07 |
| ORD-0002 | U073 | refunded | 446.70 |
| ORD-0003 | U078 | paid | 1104.32 |
Without these saved values, nobody could pick the parcel, deliver it, or prove how much money came in.
What are the three shapes data comes in?
Data arrives structured, semi-structured or unstructured. This track works mostly with the first.
In an interview, name where each kind lives and how it becomes a table.
| Kind | Example | Where it usually lives | Ready for SQL? |
|---|---|---|---|
| Structured | Orders, payments | Database tables | Yes |
| Semi-structured | JSON sent by a web service | Files, message queues | After flattening into columns |
| Unstructured | Photos, emails, free text | File storage | After facts are extracted |
Later tracks deal with the bottom 2 rows.
What makes data structured?
Every row is one thing, like one order. Every column is one property, like a price or a status.
The left side already has boxes and labels. The right side has to be processed before a query can use it.
The columns are known ahead of time, so a database can sort, filter and add up millions of rows quickly.
What about photos and support recordings?
A person can watch a video and see an angry customer. A database cannot average a video.
Pull out the facts first. Then SQL has a column to work with.
| Unstructured item | Fact you can pull out | Column it would fill |
|---|---|---|
| Photo of a receipt | The total printed on it | order_total |
| Support email | The order it complains about | order_id |
| Photo of a damaged parcel | Whether it arrived damaged | is_damaged |
Programs can do this extraction. Until it happens, the file is only stored. SQL cannot ask it anything, because there is no column to point at.
What is semi-structured data?
It has labels built in but no fixed grid. Web services send orders in this shape all the time, called JSON.
{"order_id": "ORD-0001", "items": [{"sku": "SKU-001", "qty": 1}], "paid": true}Data engineers write pipelines that read this and write clean table rows.
How would you explain the three kinds in an interview?
Do not only recite definitions. Say where each kind lands and who turns it into a table.
- Structured data belongs in relational tables, ready for SQL.
- Semi-structured JSON arrives from event streams into a landing area, where a pipeline parses it into tables.
- Unstructured files sit in file storage, with a table row pointing to each one.
A short spoken answer: "A table of orders is structured. The JSON a mobile app sends on every tap is semi-structured, so we land it first and then parse it into columns. A photo of a damaged parcel is unstructured, so we store the file and keep a row that says where it is."
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Data | Facts written down so they can be stored and used |
| Structured | Data that fits neatly in rows and columns |
| Semi-structured | Data with labels but no fixed table shape, like JSON |
| Unstructured | Data with no set shape, like photos or voice recordings |
| Record | One entry, such as one order |
| JSON | A text format that labels each value, like "amount": 450 |
Why this exists
How do you count yesterday's paid orders from emails?
A small shop gets one receipt email per order. Your boss asks: how many were paid yesterday?
- 20 receiptsa boring half hour with a tally sheet
- 20,000 receiptsimpossible by hand
The facts exist, but they are written in a form only a person can read. No program can answer the question until the facts sit in one place with the same labels.
What does a data engineer do about it?
Imagine ShopKart receives 25,000 orders an hour across five distribution centres, from many different systems.
- Apps, gateways, couriers, PDFs
- Pipeline extracts and cleans
- Loads clean tables
- Anyone asks SQL questions
A data engineer builds that pipeline. Once the facts sit in tables, a question takes seconds, not days.
Put the facts in one place, in the same labelled shape every time.
What goes wrong without tables?
Teams still decide things, but they decide blind.
Clean tabular data becomes the single source of truth.
| Team | Without clean tables | With clean tables |
|---|---|---|
| Inventory | Orders stock by intuition | Uses real replenishment rates |
| Marketing | Spends without knowing what worked | Sees which campaigns brought paying customers |
| Auditors | No verifiable log of revenue | Check quarterly earnings against the rows |
Picture this
How does an email become a row?
Reading the email and filling in the cells is the extract step.
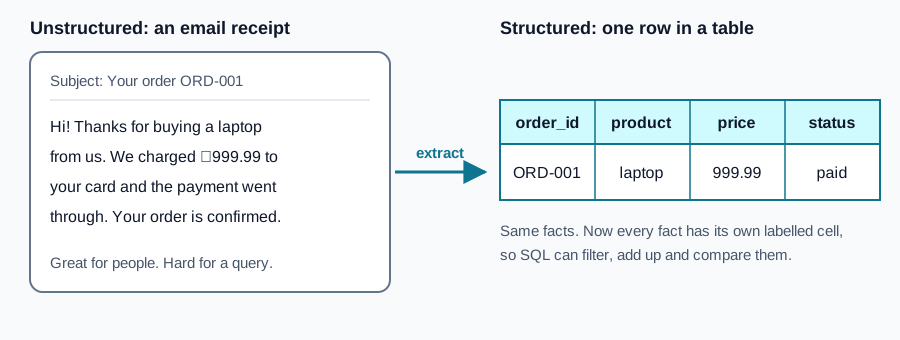
After extraction, the word paid is no longer part of a sentence. It is the value in the status column.
Why does the column matter more than the word?
A query cannot tell two email sentences apart by the word paid alone.
The column removes the guesswork.
| Where paid appears | Can a query be sure? |
|---|---|
| '...your invoice has been paid in full' | Not without reading the sentence |
| '...your payment failed and was not paid' | Same word, opposite meaning |
| order_status column holds paid | Yes: order_status = 'paid' |
Why does JSON get flattened?
A customer may buy one item or 50, so JSON stores a list. A table wants one fixed shape.
{"order_id": "ORD-0001",
 "items": [{"sku": "SKU-001", "qty": 1}, {"sku": "SKU-014", "qty": 2}]}
Flattened: 1 row per item.
| order_id | sku | qty |
|---|---|---|
| ORD-0001 | SKU-001 | 1 |
| ORD-0001 | SKU-014 | 2 |
Parsing nested text on every query gets slow at scale, so engineers flatten once, before analysts ask.
What does 612.07 mean on its own?
The header gives a value its meaning. Read the column names before you read the values.
The same row, read through its labels.
| Column | Value in ORD-0001 | What it means |
|---|---|---|
| order_total | 612.07 | A price in rupees |
| user_id | U004 | The customer who ordered |
| order_status | paid | Where the order stands |
The value 999.99 on its own could be a price, a weight or a temperature. It only means 'price' because the column header says price. When you look at any new dataset, read the column names before you read the values.
A small example
How many of these orders were paid?
Look back at the 3-row table. Count the rows whose status is paid, then add their totals.
Two paid orders. 612.07 + 1104.32 = 1,716.39 rupees.
| order_id | order_status | order_total (₹) | Counted? |
|---|---|---|---|
| ORD-0001 | paid | 612.07 | Yes |
| ORD-0002 | refunded | 446.70 | No |
| ORD-0003 | paid | 1104.32 | Yes |
The status column decided it. If these were three voicemails, someone would listen to all three and write the numbers down.
How do you ask the database yourself?
A query is a question written in SQL. The editor in this tab already has an orders table. Predict: how many rows and which columns?
SELECT *
FROM orders
LIMIT 5;order_id user_id order_status order_total currency created_at updated_at ORD-0001 U004 paid 612.07 INR 2026-08-02 16:33:28 2026-08-02 19:33:28 ORD-0002 U073 refunded 446.7 INR 2026-08-03 20:40:58 2026-08-03 20:40:58 ORD-0003 U078 paid 1104.32 INR 2026-08-06 09:58:04 2026-08-06 11:58:04 ORD-0004 U057 cancelled 339.9 INR 2026-08-11 03:43:33 2026-08-11 06:43:33 ORD-0005 U012 paid 261.73 INR 2026-08-14 07:06:40 2026-08-14 08:06:40
5 rows, 7 columns. The star means all columns. LIMIT 5 tells the database to stop after 5 rows.
What does each of the 7 columns hold?
Every row carries the same seven properties. Learn the labels once and every order reads the same way.
7 columns shown as 6 rows, because the two timestamps share a line.
| Column | Holds | ORD-0001 |
|---|---|---|
| order_id | The unique label of the order | ORD-0001 |
| user_id | The customer who placed it | U004 |
| order_status | paid, refunded, cancelled or pending | paid |
| order_total | The amount in the currency below | 612.07 |
| currency | Which money the total is in | INR |
| created_at / updated_at | When it was created and last changed | 2026-08-02 16:33:28 / 19:33:28 |
The status and total columns answer most business questions. The two timestamps say when to look.
How many paid orders are in the whole table?
Let the database do the tally. WHERE keeps only the rows whose status is paid, and COUNT(*) counts them.
SELECT COUNT(*) AS paid_orders
FROM orders
WHERE order_status = 'paid';paid_orders 93
The table holds 93 paid orders. No email was opened.
How much money did those paid orders bring in?
Same filter, different tally. SUM adds up the order_total column, and ROUND tidies the decimals.
SELECT ROUND(SUM(order_total), 2) AS paid_revenue
FROM orders
WHERE order_status = 'paid';paid_revenue 43606.63
Rupees 43,606.63, found by reading 1 column of 93 rows. A refunded or cancelled total never enters the sum.
What happens if you forget the quotes?
Beginners write the text value without quotes. Predict what the database says.
SELECT *
FROM orders
WHERE order_status = paid;Binder Error: Referenced column "paid" not found in FROM clause!
Candidate bindings: "updated_at", "created_at"
LINE 1: SELECT * FROM orders WHERE order_status = paid
^Without quotes, the database hunts for a column named paid and finds none.
How do you fix it?
Wrap text values in single quotes.
SELECT order_id, order_total
FROM orders
WHERE order_status = 'paid'
LIMIT 2;order_id order_total ORD-0001 612.07 ORD-0003 1104.32
ORD-0002 was skipped because its status is refunded.
Text values go in single quotes. Bare words are column names.
Why does LIMIT matter on a big table?
A real warehouse table can hold billions of rows.
SELECT *
FROM orders;
-- On 1 billion-row table this streams every row over the network.
LIMIT is a guard rail. It makes the database stop early instead of pulling gigabytes through memory and the network. Some cloud warehouses charge by the data they scan, and LIMIT does not always reduce that, so check how your warehouse bills.
What two traps hit raw data first?
Raw feeds often arrive with the wrong unit or without a time zone.
Always check the unit and the time zone before storing incoming data.
| Trap | Raw value | What goes wrong |
|---|---|---|
| Units | 61207 (paise) | Loaded into a rupee column as is, ORD-0001 looks 100 times too big |
| Time zone | 2026-08-02 16:33:28 | Is it India time or UTC? They are 5.5 hours apart, so daily reports shift |
How does messy data become structured?
Every query you write in this track relies on this chain.
- Raw event in the world
- Landing file or JSON
- Parse, clean, validate
- Structured table
- SQL report
Think of a warehouse. Pallets are scanned and put in labelled bins, so any item is found in seconds. Structured tables do that for business facts.
How does it all replay on our 3 orders?
ShopKart saves ORD-0001 as a user, a status and a total.
Every order lands as 1 row in the orders table, with fixed columns.
WHERE order_status = 'paid' keeps rows by the status label, so ORD-0002 drops out.
COUNT(*) counts the survivors. For all orders in the table, it prints 93.
Remember these when you start the next lesson.
- Data is a fact someone recorded.
- Structured data lives in rows and columns, so SQL can work on it.
- Semi-structured JSON and unstructured files are turned into tables first.
- A column header gives a value its meaning.
- Text values need single quotes, and big tables need LIMIT.
Common beginner questions
What is the difference between data and information?
Data is the raw recorded fact, like a price of 49.99. Information is what you get after you process data to answer a question, like 'we earned 12,450 last month'. Data engineers build the machinery that turns the first into the second.
Why not keep everything in a spreadsheet?
For a few hundred rows and one person, a spreadsheet is a fine choice. It starts to hurt when many people edit at once, when the file gets very large, or when you need the same numbers every time you ask. The next lesson covers what a database does about that.
Is a photo really data?
Yes. It is recorded information, just not in rows and columns. Programs can extract structured facts from photos and audio (for example, the text on a receipt), and those extracted facts then go into tables.
What comes next
Next you will meet the database itself: the software that stores these tables and answers questions about them. After that you will look closely at tables, rows and columns, and then at the keys that connect one table to another.
Practice
Run the sample query to see the first rows of the orders table in the editor. Then answer the exercise question: how many columns does the result have? Point at 1 row and say which order it describes, and point at 1 column and say which property it holds.
Going further: the same facts at two different grains
The lesson showed that data is recorded facts. A question that trips beginners next is: how detailed is each recorded fact? That level of detail is the grain. The same website activity can be stored as 1 row per click or as 1 row per user per day, and the two answer different questions.
The clicks table. 1 row per click.
| user_id | page | clicked_at |
|---|---|---|
| u1 | home | 2026-09-01 09:00 |
| u1 | shop | 2026-09-01 09:05 |
| u2 | home | 2026-09-01 10:00 |
| u1 | shop | 2026-09-02 08:30 |
| u2 | cart | 2026-09-02 11:00 |
| u2 | home | 2026-09-02 11:30 |
Counting rows gives clicks. Counting distinct users gives people. Predict both numbers per day before you open the output.
SELECT CAST(clicked_at AS DATE) AS day,
       COUNT(*)                AS clicks,
       COUNT(DISTINCT user_id) AS users
FROM clicks
GROUP BY day
ORDER BY dayday clicks users 2026-09-01 3 2 2026-09-02 3 2
Day 1 has 3 clicks but only 2 people, because u1 clicked twice. Both numbers are correct. They answer different questions, and mixing them up is how a report says 'visitors' and means 'clicks'.
| Question | Count | Why |
|---|---|---|
| How busy was the site? | Rows | Each click is one fact |
| How many people came? | Distinct user_id | One person can produce many rows |
| How many people came on both days? | Needs a different query | The grain of the table cannot answer it directly |
Try a new scenario
A table has 1 row per order line (an order with 3 products has 3 rows). A colleague says 'we had 1,200 orders yesterday' after running COUNT(*). What do you check?
Work it out, then open the answer
COUNT(*) counts order lines, not orders. Check the grain first, then use COUNT(DISTINCT order_id). If the true number is lower, the report overstated orders, and any revenue computed from an order-level column such as order total would also be inflated by the number of lines.
What is the difference between data and information?
Data is recorded facts, such as a row for each sale. Information is what you learn from the data, such as sales per region. The job of a query is to turn one into the other.
Close the lesson and explain it
Without scrolling up, explain what grain means and why clicks and users can both be right and still differ.
Finished this lesson?
Mark it as read when you could explain it to someone else.