
Overview
A subquery is a query in parentheses. WITH gives it a name so the next step can read it.
On this page8 sections
What you will do
A ShopKart analyst writes one huge query with three subqueries nested inside each other. It runs, but nobody on the team can read it, and a small change breaks it.
The fix is to name each step with WITH, so the query reads from top to bottom like a recipe.
Which 2 tables do we use?
The orders table has eight purchases. The line items table has 5 rows, spread over three of those orders.
orders_demo: eight purchases, totals in rupees.
| order_id | user_id | order_status | order_total |
|---|---|---|---|
| ORD-0001 | U01 | paid | 400 |
| ORD-0002 | U02 | paid | 800 |
| ORD-0003 | U01 | cancelled | 250 |
| ORD-0004 | U03 | paid | 200 |
| ORD-0005 | U02 | pending | 600 |
| ORD-0006 | U03 | paid | 500 |
| ORD-0007 | U04 | cancelled | 160 |
| ORD-0008 | U01 | paid | 100 |
line_items_demo: 5 rows. ORD-0004 and ORD-0008 are paid but have no items yet.
| order_id | product_id | quantity | unit_price |
|---|---|---|---|
| ORD-0001 | P-10 | 1 | 400 |
| ORD-0002 | P-20 | 2 | 300 |
| ORD-0002 | P-30 | 1 | 200 |
| ORD-0006 | P-20 | 1 | 300 |
| ORD-0006 | P-30 | 1 | 200 |
ORD-0002 has 2 line items, three units in all. ORD-0006 has two. ORD-0001 has one.
What does the operations director want?
ShopKart's ops director in Bengaluru wants one report: every paid order with the number of items it contained. Orders with no items must still appear, with 0.
- orders
- keep paid ones
- count items per order
- join the two
- report
The report must not inflate revenue. The totals have to match the bank.
Can you build both tables yourself?
Yes. The real tables are bigger, so we make small copies that match the pictures above.
CREATE OR REPLACE TABLE orders_demo (
  order_id VARCHAR, user_id VARCHAR, order_status VARCHAR, order_total DOUBLE
);
INSERT INTO orders_demo VALUES
  ('ORD-0001', 'U01', 'paid',      400), ('ORD-0002', 'U02', 'paid',      800),
  ('ORD-0003', 'U01', 'cancelled', 250), ('ORD-0004', 'U03', 'paid',      200),
  ('ORD-0005', 'U02', 'pending',   600), ('ORD-0006', 'U03', 'paid',      500),
  ('ORD-0007', 'U04', 'cancelled', 160), ('ORD-0008', 'U01', 'paid',      100);

CREATE OR REPLACE TABLE line_items_demo (
  order_id VARCHAR, product_id VARCHAR, quantity INTEGER, unit_price DOUBLE
);
INSERT INTO line_items_demo VALUES
  ('ORD-0001', 'P-10', 1, 400), ('ORD-0002', 'P-20', 2, 300),
  ('ORD-0002', 'P-30', 1, 200), ('ORD-0006', 'P-20', 1, 300),
  ('ORD-0006', 'P-30', 1, 200);
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| CTE | A named step you write above the main query with WITH |
| Subquery | A query inside another query |
| WITH | The keyword that starts a CTE |
| Alias | A new name for a table or column |
| Readable | Easy for another person to follow |
| Join | Combine rows from two tables |
Why this skill
What goes wrong if you just join the 2 tables?
Each order row is repeated once per line item. Predict the paid revenue after this join. The true figure is 2000.
SELECT SUM(o.order_total) AS naive_gmv
FROM orders_demo o
JOIN line_items_demo i ON i.order_id = o.order_id
WHERE o.order_status = 'paid';naive_gmv 3000
ORD-0002 counted twice (800 extra) and ORD-0006 counted twice (500 extra). The join also dropped the 2 orders with no items.
Count the items first, then join. The join should see 1 row per order.
How do you do that with a nested subquery?
Put each preparation step inside parentheses in the FROM and JOIN clauses. Predict what items shows for ORD-0004.
SELECT p.order_id, p.order_total, i.items
FROM (
  SELECT order_id, order_total
  FROM orders_demo
  WHERE order_status = 'paid'
) p
LEFT JOIN (
  SELECT order_id, SUM(quantity) AS items
  FROM line_items_demo
  GROUP BY order_id
) i ON i.order_id = p.order_id
ORDER BY p.order_total DESC;order_id order_total items ORD-0002 800 3 ORD-0006 500 2 ORD-0001 400 1 ORD-0004 200 NULL ORD-0008 100 NULL
Five paid orders, no inflation. The 2 orders without items show NULL, which we fix later with COALESCE.
Why is that query hard to read?
Your eyes jump to the middle to find the paid filter, then lower to find the item count, then back to the top for the columns.
Left: you read from the inside out. Right: you read from top to bottom.
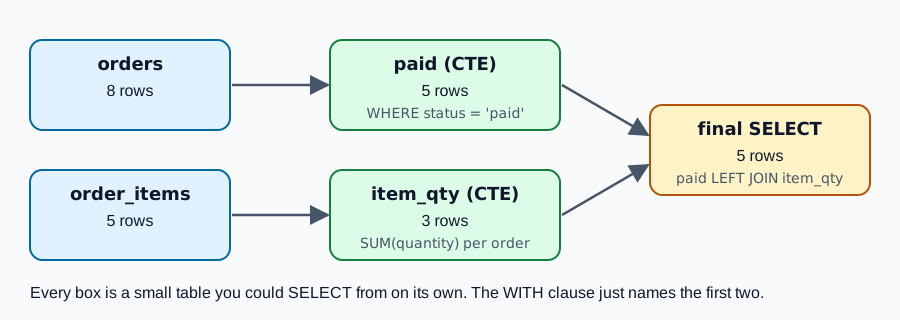
A CTE (Common Table Expression) is a named result you define first with WITH, then use like a table.
How the code works
What does the smallest CTE look like?
WITH, a name, AS, then the query in parentheses. After the closing bracket, the main SELECT reads from that name.
WITH paid AS (
  SELECT order_id, user_id, order_total
  FROM orders_demo
  WHERE order_status = 'paid'
)
SELECT COUNT(*) AS paid_orders, SUM(order_total) AS gmv
FROM paid;paid_orders gmv 5 2000
Five paid orders, 2000 in revenue. The filter lives in one place, so you can check it on its own.
A CTE is not saved in the database and creates no object. It exists only while its statement runs, then it is gone.
How do you chain two CTEs?
Write WITH once. Separate the stages with commas. Predict what total_items shows for ORD-0004.
WITH paid AS (
  SELECT order_id, user_id, order_total
  FROM orders_demo
  WHERE order_status = 'paid'
),
item_qty AS (
  SELECT order_id, SUM(quantity) AS items
  FROM line_items_demo
  GROUP BY order_id
)
SELECT p.order_id, p.order_total, COALESCE(i.items, 0) AS total_items
FROM paid p
LEFT JOIN item_qty i ON i.order_id = p.order_id
ORDER BY p.order_total DESC;order_id order_total total_items ORD-0002 800 3 ORD-0006 500 2 ORD-0001 400 1 ORD-0004 200 0 ORD-0008 100 0
This is the report we set out to build. COALESCE turned the NULL item counts into 0, and the totals still add up to 2000.
One WITH, then commas. Each stage gets a name that says what it is.
How do you check one stage on its own?
Keep the WITH part and swap the final SELECT for a plain look at one stage. Nothing else changes.
WITH item_qty AS (
  SELECT order_id, SUM(quantity) AS items
  FROM line_items_demo
  GROUP BY order_id
)
SELECT * FROM item_qty ORDER BY order_id;order_id items ORD-0001 1 ORD-0002 3 ORD-0006 2
3 rows, one per order that has items. If a total looks wrong, check each stage like this from the top down.
Can one stage read from another stage?
Yes, any stage defined above it. Here big_paid builds on paid instead of rescanning orders. Predict the survivors.
WITH paid AS (
  SELECT order_id, order_total
  FROM orders_demo
  WHERE order_status = 'paid'
),
big_paid AS (
  SELECT order_id, order_total
  FROM paid
  WHERE order_total >= 500
)
SELECT * FROM big_paid ORDER BY order_id;order_id order_total ORD-0002 800 ORD-0006 500
big_paid does not repeat the status filter. It trusts paid, and only adds its own rule.
Can you use the same CTE twice in one statement?
Yes, as many times as you need inside the one statement.
WITH paid AS (
  SELECT * FROM orders_demo WHERE order_status = 'paid'
),
big AS (
  SELECT * FROM paid WHERE order_total >= 500
)
SELECT (SELECT COUNT(*) FROM paid) AS paid_n,
(SELECT COUNT(*) FROM big) AS big_n;paid_n big_n 5 2
Warehouses like DuckDB and Snowflake may compute a CTE once and reuse it. Or they may paste it in like a subquery. Either way the answer is the same.
What happens with a trailing comma?
A comma tells the parser another CTE is coming. Predict the error when SELECT follows it instead.
WITH paid AS (
  SELECT order_id, order_total FROM orders_demo WHERE order_status = 'paid'
),
SELECT * FROM paid;Parser Error: syntax error at or near "SELECT"
LINE 4: SELECT * FROM paid
^Commas go between CTEs, never after the last one.
What happens if you repeat WITH?
WITH opens the whole block, so it appears once. Predict where the parser stops.
WITH stage_a AS (SELECT * FROM orders_demo),
WITH stage_b AS (SELECT * FROM stage_a)
SELECT * FROM stage_b;Parser Error: syntax error at or near "WITH"
LINE 2: WITH stage_b AS (SELECT * FROM stage_a)
^The second WITH is the problem. Delete it and keep the comma.
Can the next statement use a CTE?
No. A CTE vanishes when its statement ends. Run the first statement, then try the second.
WITH temp_summary AS (
  SELECT order_status, COUNT(*) AS cnt FROM orders_demo GROUP BY order_status
)
SELECT * FROM temp_summary ORDER BY order_status;order_status cnt cancelled 2 paid 5 pending 1
SELECT * FROM temp_summary;Catalog Error: Table with name temp_summary does not exist!
Did you mean "telemetry"?
LINE 1: SELECT * FROM temp_summary
^The first statement works. The second finds no table called temp_summary. If a later step needs the data, save it with CREATE TEMP TABLE.
CTE, temp table or view?
All three give an intermediate result a name. They differ in how long it lives.
Pick by how long the result must live.
| Tool | Lives for | Saved in the catalog? | Use it for |
|---|---|---|---|
| CTE | One statement | No | Readable steps inside one query |
| Temp table | Your session | Session only | Sharing data across several script steps |
| View | Until dropped | Yes | A saved query that any query can use |
Worked examples
What is a scalar subquery?
A subquery that returns one number can sit anywhere a constant fits. Here it is the overall average order total.
SELECT order_id, order_total
FROM orders_demo
WHERE order_total > (SELECT AVG(order_total) FROM orders_demo)
ORDER BY order_total DESC;order_id order_total ORD-0002 800 ORD-0005 600 ORD-0006 500 ORD-0001 400
The average of all eight totals is 376.25. 4 orders are above it. A CTE is not needed when you only want one number.
What is a correlated subquery?
Its inner WHERE mentions a column from the outer row. The threshold then changes for every customer.
Each customer's own average order total, from orders_demo.
| user_id | own average |
|---|---|
| U01 | 250 |
| U02 | 700 |
| U03 | 350 |
| U04 | 160 |
SELECT o.order_id, o.user_id, o.order_total
FROM orders_demo o
WHERE o.order_total > (
  SELECT AVG(inner_o.order_total)
  FROM orders_demo inner_o
  WHERE inner_o.user_id = o.user_id
)
ORDER BY o.order_id;order_id user_id order_total ORD-0001 U01 400 ORD-0002 U02 800 ORD-0006 U03 500
Think of it as running the inner query once per outer row. Engines usually rewrite it into a faster join, but on very large tables it can still be slow.
What is a derived table?
A subquery in FROM is a derived table (an inline view). Standard SQL wants an alias, such as AS dt.
SELECT dt.user_id, dt.total_spend, dt.order_count
FROM (
  SELECT user_id, SUM(order_total) AS total_spend, COUNT(*) AS order_count
  FROM orders_demo
  WHERE order_status = 'paid'
  GROUP BY user_id
) AS dt
WHERE dt.total_spend >= 500.0
ORDER BY dt.total_spend DESC;user_id total_spend order_count U02 800 1 U03 700 2 U01 500 2
It does the same job as a CTE, only the definition sits inline. DuckDB accepts a derived table with no alias, but standard SQL and several warehouses reject it, so always write one.
What does LATERAL add?
Normally a FROM subquery cannot see its neighbour tables. LATERAL lifts that rule, like a loop over the left rows.
SELECT o.order_id, o.user_id, o.order_total, lat.avg_user_total
FROM orders_demo o,
LATERAL (
  SELECT ROUND(AVG(inner_o.order_total), 1) AS avg_user_total
  FROM orders_demo inner_o
  WHERE inner_o.user_id = o.user_id
) AS lat
WHERE o.order_total > lat.avg_user_total
ORDER BY o.order_id;order_id user_id order_total avg_user_total ORD-0001 U01 400 250 ORD-0002 U02 800 700 ORD-0006 U03 500 350
Same 3 rows as the correlated version. DuckDB and PostgreSQL support LATERAL, and it is handy for top-N per group and for unpacking JSON arrays.
How should you name a stage?
Name it after what the rows are, not after the step number. A reviewer should understand the query from the names alone.
A good name says what 1 row of the stage means.
| Hard to follow | Clear |
|---|---|
| WITH a AS (...), b AS (...) | WITH paid AS (...), item_qty AS (...) |
| WITH step1 AS (...) | WITH big_paid AS (...) |
| WITH tmp AS (...) | WITH orders_per_user AS (...) |
When a stage name needs a long sentence to explain it, the stage is probably doing 2 jobs. Split it in two.
Which kind of subquery should you pick?
Ask what the inner query returns and where you need it.
When a step needs a name or is used twice, promote it to a CTE.
| Kind | Returns | Where it sits | Example in this lesson |
|---|---|---|---|
| Scalar subquery | One value | WHERE or SELECT | Average order total |
| Correlated subquery | One value per outer row | WHERE | Customer's own average |
| Derived table | A table | FROM or JOIN | Spend per user |
| CTE | A named table | Top of the statement | paid and item_qty |
If a subquery grows past a few lines, or 2 steps depend on each other, a CTE reads better.
How does the whole report run, start to finish?
Question: every paid order with its item count, and 0 where there are none.
A plain join repeats ORD-0002 and ORD-0006, so revenue shows 3000, not 2000.
Stage paid keeps the five paid orders. Stage item_qty sums quantity per order.
LEFT JOIN keeps ORD-0004 and ORD-0008. COALESCE turns their NULL into 0.
5 rows, one per order, total 2000. Each stage can be checked alone.
Keep these.
- Aggregate the many side first, then join. The join should see 1 row per order.
- WITH once, a comma between CTEs, no comma before the final SELECT.
- A CTE lives for one statement. Use a temp table to keep data longer.
- A stage can read any stage above it. Name stages by what they hold.
- Scalar, correlated and derived-table subqueries do the same work inline.
Common beginner questions
Is a CTE the same as a temporary table or a view?
No. A CTE lives for one statement and is not stored anywhere in the database catalog. A temporary table is stored for your active session and a view is a saved query definition that other queries can use later. A CTE is meant for organizing and reading a single complex query.
Does a CTE make a query run faster?
Not necessarily. Query optimizers are free to inline a CTE or materialize it based on internal cost estimations. Choose CTEs for code readability, modularity, and maintainability. If a query is slow, profile the execution plan to see whether indexes or partition filters are needed.
How many CTEs can I chain together in one statement?
There is no practical limit in modern engines like DuckDB, Snowflake, or PostgreSQL. If each stage has a clear business name and performs a focused transformation, chaining four or five CTEs is far more maintainable than a multi-level nested subquery.
What comes next
So far every SQL statement you wrote only read data from existing tables. In the next lesson, you will learn the four commands that change data: CREATE TABLE, INSERT, UPDATE, and DELETE.
After that, window functions let you rank and compare rows without collapsing them, often together with CTEs.
Practice
Open the workspace exercise and define a CTE named paid that filters the orders table for confirmed paid transactions.
Then write an outer query that selects order_id and order_total from that CTE, sorted by order_total descending with a limit of 10 rows. Verify that your query produces exactly the expected paid rows.
Going further: a CTE that refers to itself
An ordinary CTE names a subquery. A recursive CTE can refer to itself, which is how SQL walks a hierarchy of unknown depth, such as who reports to whom. It has a starting row and a step that repeats until nothing new appears.
The staff table. Dana is at the top.
| id | name | manager_id |
|---|---|---|
| 1 | Dana | NULL |
| 2 | Eli | 1 |
| 3 | Fay | 1 |
| 4 | Gus | 2 |
| 5 | Hal | 4 |
Predict Hal's depth (Dana is level 1).
WITH RECURSIVE chain AS (
  SELECT id, name, 1 AS level FROM staff WHERE manager_id IS NULL
  UNION ALL
  SELECT s.id, s.name, c.level + 1
  FROM staff s JOIN chain c ON s.manager_id = c.id
)
SELECT name, level FROM chain ORDER BY level, namename level Dana 1 Eli 2 Fay 2 Gus 3 Hal 4
The first SELECT is the anchor (the top of the tree). The second joins staff to the rows found so far, one level deeper each round, until no more matches. Hal is level 4: Dana, Eli, Gus, Hal.
Try a new scenario
Generate every date from 2026-09-01 to 2026-09-05, 1 row each, using a recursive CTE. Where is this useful in a pipeline?
Open the answer
The anchor is the first date and the step adds a day while the day is below the end, giving days first_day last_day ; 5 2026-09-01 2026-09-05. A date list like this fills gaps: LEFT JOIN your daily totals onto it so that days with no sales show 0 instead of disappearing from a chart.
Interview: CTE or subquery?
They give the same result in most cases. A CTE has a name and reads top to bottom, which helps with several steps, and it can be reused in the same query. A short one-off condition is fine as a subquery.
Close the lesson and explain it
Without scrolling up, explain the two parts of a recursive CTE and what stops it.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this idea
Each page shows the idea moving, then lists problems from easiest. Open one now, or come back when you finish the lesson.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.
- Customers above average spendInterview-style drill: Multi-CTE: spenders above average with rank and revenue share.Studiointermediatesql12 minLocked
- Employee hierarchy under AliceInterview-style drill: Recursive CTE for all reports under employee_id 1.Studiointermediatesql12 minLocked
- Gaps in order_id sequenceInterview-style drill: Find gaps where order_id jumps by more than one.Studiointermediatesql12 minLocked