Modern stack
Apache Kafka & Stream Processing for Data Engineers
Topics, partitions, consumer groups and stream processing patterns in Kafka.
- Handwritten-style
- Diagrams and tables
- Worked examples
Who this notebook is for
Engineers building or maintaining streaming pipelines, and candidates facing Kafka design and failure questions.
What you will be able to do
- Explain topics, partitions and consumer groups clearly
- Choose producer settings for durability and throughput
- Reason about at-least-once, at-most-once and exactly-once delivery
- Move data between systems with Connect and Debezium, and process it with Kafka Streams or Flink
What's inside
Pick a chapter and the notebook opens right there.
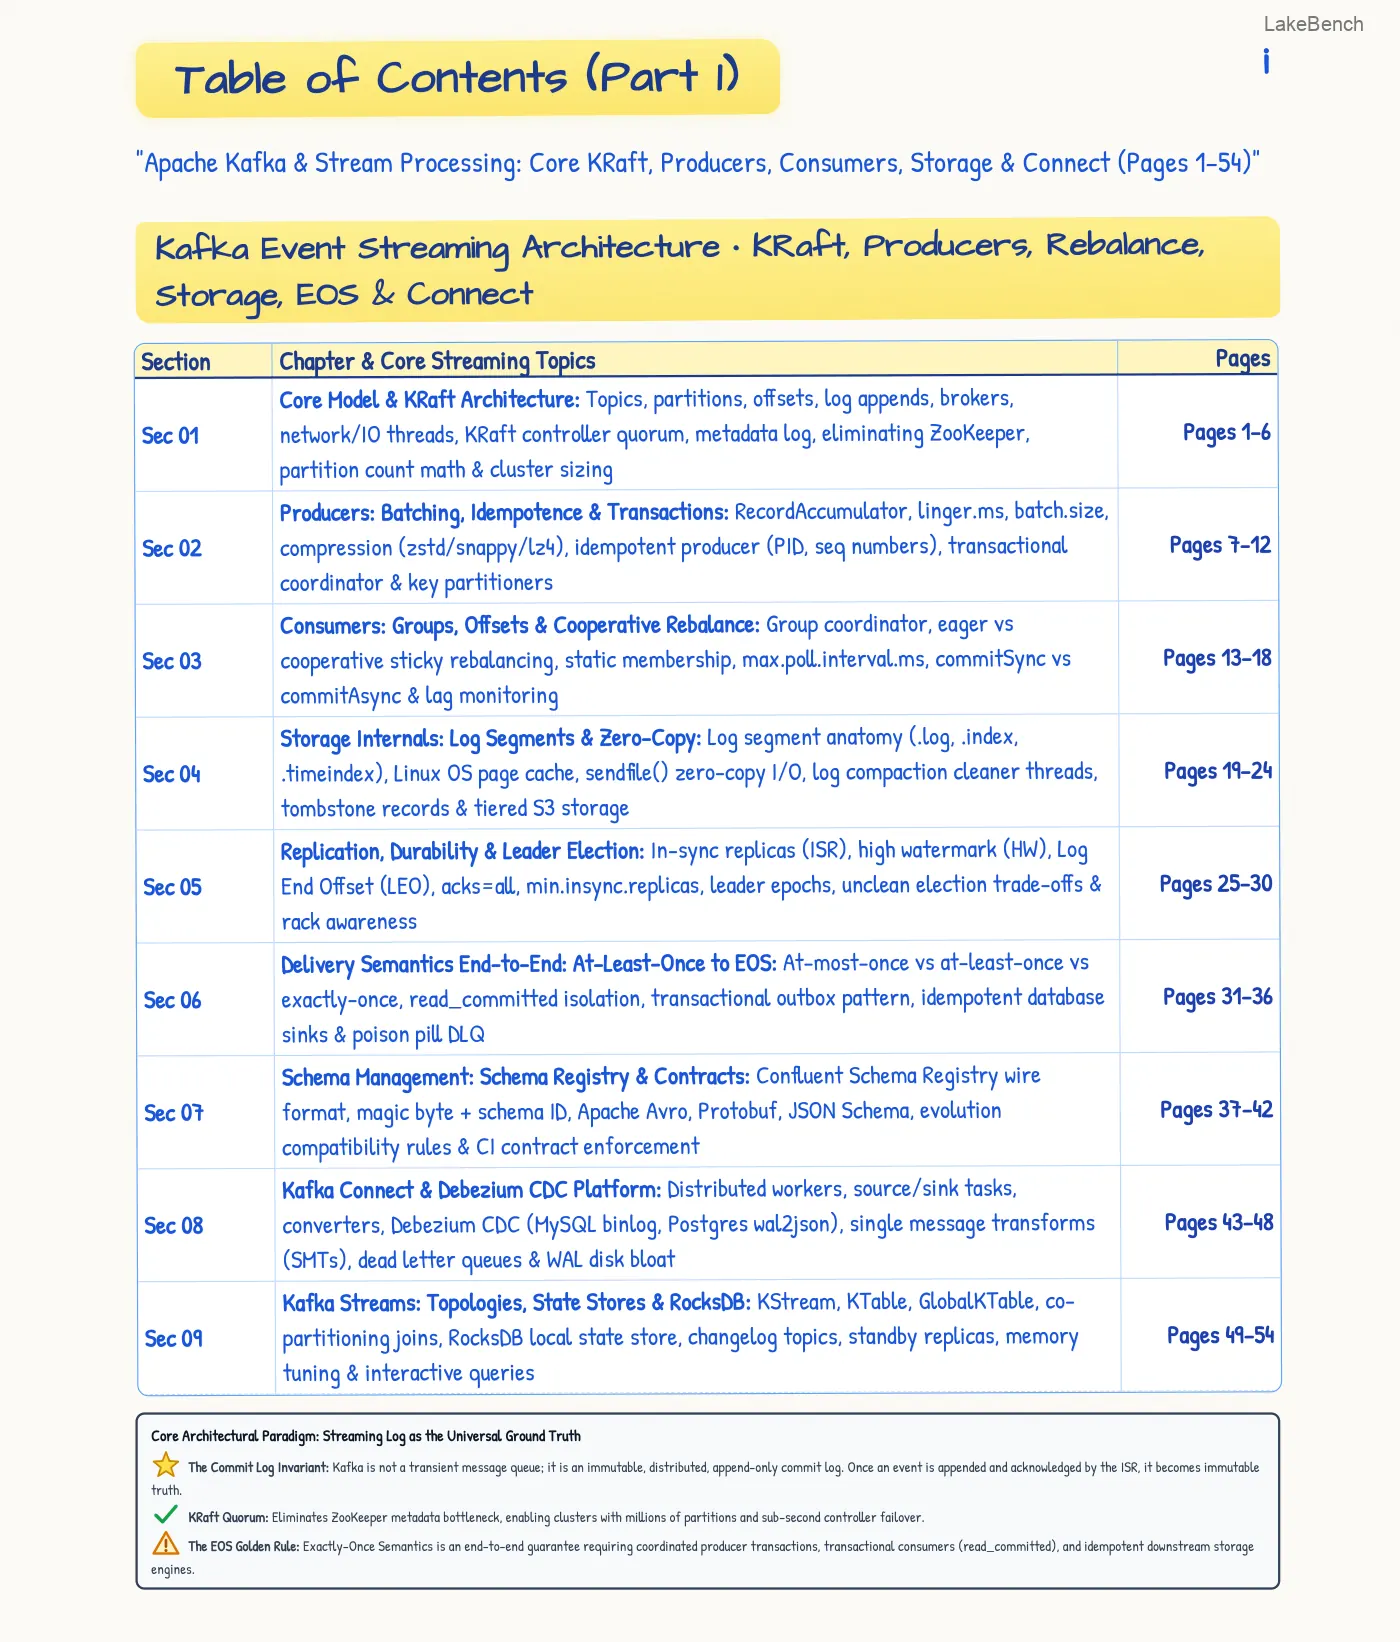
- Core Model & KRaft ArchitectureTopics, partitions, offsets, log appends, brokers, network/IO threads, KRaft controller quorum, metadata log, eliminating ZooKeeper, partition count math & cluster sizingStart here
- Producers: Batching, Idempotence & TransactionsRecordAccumulator, linger.ms, batch.size, compression (zstd/snappy/lz4), idempotent producer (PID, seq numbers), transactional coordinator & key partitionersStart here
- Consumers: Groups, Offsets & Cooperative RebalanceGroup coordinator, eager vs cooperative sticky rebalancing, static membership, max.poll.interval.ms, commitSync vs commitAsync & lag monitoringStart here
- Storage Internals: Log Segments & Zero-CopyLog segment anatomy (.log,.index,.timeindex), Linux OS page cache, sendfile() zero-copy I/O, log compaction cleaner threads, tombstone records & tiered S3 storageStart here
- Replication, Durability & Leader ElectionIn-sync replicas (ISR), high watermark (HW), Log End Offset (LEO), acks=all, min.insync.replicas, leader epochs, unclean election trade-offs & rack awarenessStart here
- Delivery Semantics End-to-End: At-Least-Once to EOSAt-most-once vs at-least-once vs exactly-once, read_committed isolation, transactional outbox pattern, idempotent database sinks & poison pill DLQStart here
- Schema Management: Schema Registry & ContractsConfluent Schema Registry wire format, magic byte + schema ID, Apache Avro, Protobuf, JSON Schema, evolution compatibility rules & CI contract enforcementStart here
- Kafka Connect & Debezium CDC PlatformDistributed workers, source/sink tasks, converters, Debezium CDC (MySQL binlog, Postgres wal2json), single message transforms (SMTs), dead letter queues & WAL disk bloatStart here
- Kafka Streams: Topologies, State Stores & RocksDBKStream, KTable, GlobalKTable, co- partitioning joins, RocksDB local state store, changelog topics, standby replicas, memory tuning & interactive queriesStart here
- ksqlDB vs Apache Flink SQLPush vs pull queries, continuous queries, dynamic tables, retraction streams (ChangelogMode), temporal joins with late data, feature comparison matrix & enterprise migration pathsStart here
- Apache Flink: Watermarks, State & CheckpointsEvent time vs processing time, watermarks, Chandy-Lamport distributed checkpointing, savepoints, unaligned checkpoints, backpressure debloating & state backendsStart here
- Stream Processing Patterns & WindowingTumbling, sliding, session & global windows; allowed lateness & side outputs; real-time sessionization, continuous Top-N ranking, deduplication & CEP pattern matchingStart here
- Operations, JMX Telemetry & SecurityCritical metrics (UnderReplicatedPartitions, OfflinePartitions, ConsumerLag), mTLS, SASL/SCRAM, wire encryption, Kafka ACLs, rolling upgrades & client rate quotasStart here
- Multi-Cluster & Managed Kafka ServicesMirrorMaker 2 (MM2), cluster linking, active- passive DR vs active-active bi-directional sync, offset translation, AWS MSK, Confluent Cloud, Event Hubs & Redpanda C++Start here
- Performance Tuning & Partition MathematicsThroughput vs latency tuning, partition count formula, broker file descriptors, socket buffers (SO_SNDBUF), JVM GC tuning & 10 GB/sec zero-copy benchmarkingStart here
- Lakehouse Integration: Kafka to Iceberg & DeltaStreaming ingestion into Apache Iceberg / Delta Lake, solving the small-file catastrophe, compaction schedules, commit frequency & CDC MERGE deduplicationStart here
- Failure Playbooks & Incident RecoveryTriage runbooks for runaway lag, rebalance storms, broker disk exhaustion, poison pill offsets, split-brain scenarios, corrupted KRaft snapshots & data loss post-mortemsStart here
- Staff Drills & Master Cheat Sheet1M events/sec clickstream architecture, payments ledger with EOS, CDC fan-out to Lakehouse, RabbitMQ to Kafka migration, CLI syntax reference & production readiness checklistStart here
Practice this
Put it to work on LakeBench.
Read the guide first
Short explainers that pair with this notebook.
Common questions
- Does it cover Kafka internals?
- Yes. There are chapters on KRaft, log segments, replication and leader election, plus operations and failure playbooks.
- Is Flink included?
- Yes. It covers Flink watermarks, state and checkpoints, and compares ksqlDB with Flink SQL.
- Can I read a sample before I commit?
- Yes. The contents pages and the first pages of every notebook can be read online, so you can judge the style before going further.