Modern stack
Snowflake for Data Engineers
Warehouses, stages, streams, tasks and cost control in Snowflake.
- Handwritten-style
- Diagrams and tables
- Worked examples
Who this notebook is for
Engineers who use or are about to use Snowflake and want the architecture and the cost levers explained, not only the syntax.
What you will be able to do
- Explain how micro-partitions, caching and warehouses affect speed and cost
- Load data with stages, COPY INTO and Snowpipe
- Build change pipelines with streams, tasks and dynamic tables
- Use Time Travel, cloning, masking and sharing safely
What's inside
Pick a chapter and the notebook opens right there.
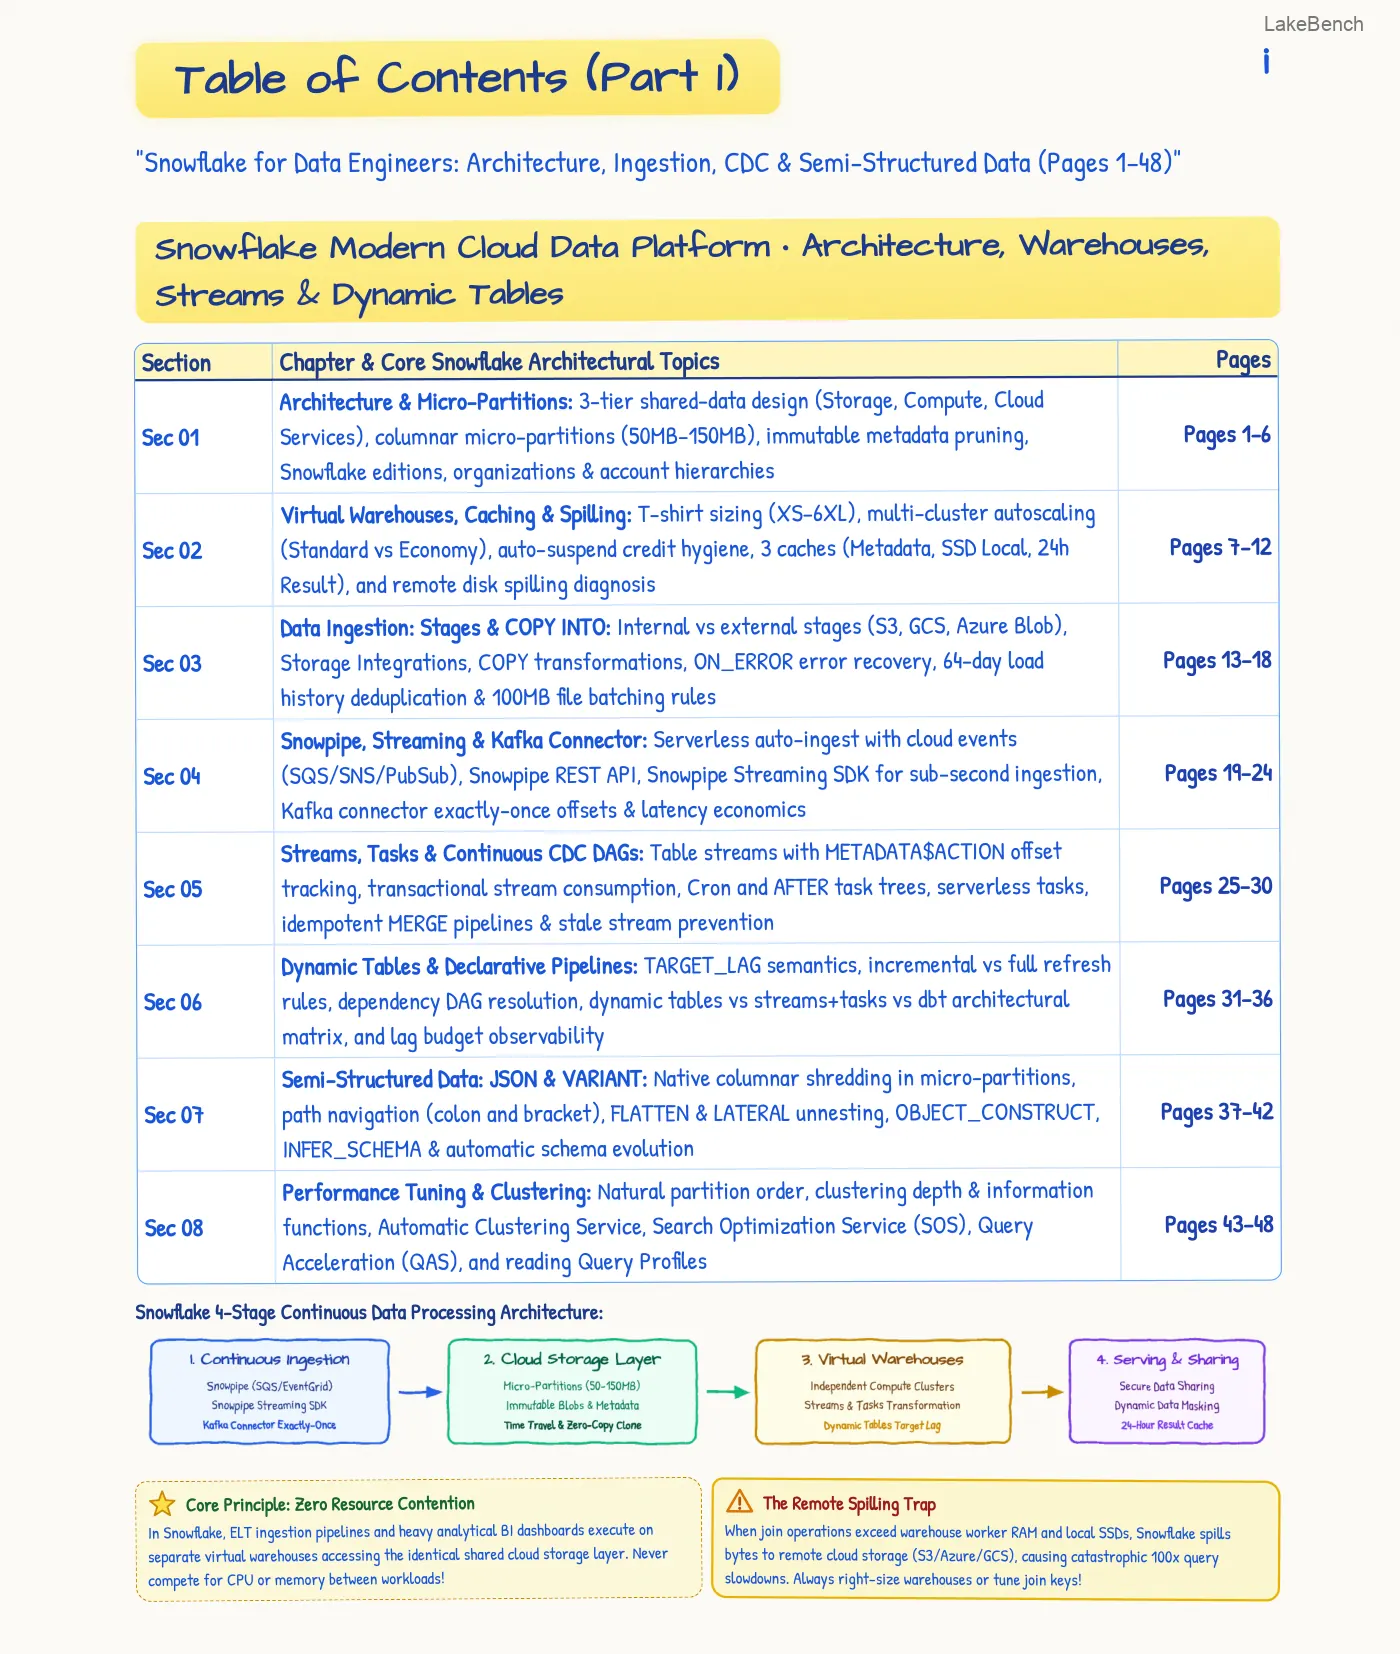
- Architecture & Micro-Partitions3-tier shared-data design (Storage, Compute, Cloud Services), columnar micro-partitions (50MB–150MB), immutable metadata pruning, Snowflake editions, organizations & account hierarchiesStart here
- Virtual Warehouses, Caching & SpillingT-shirt sizing (XS–6XL), multi-cluster autoscaling (Standard vs Economy), auto-suspend credit hygiene, 3 caches (Metadata, SSD Local, 24h Result), and remote disk spilling diagnosisStart here
- Data Ingestion: Stages & COPY INTOInternal vs external stages (S3, GCS, Azure Blob), Storage Integrations, COPY transformations, ON_ERROR error recovery, 64-day load history deduplication & 100MB file batching rulesStart here
- Snowpipe, Streaming & Kafka ConnectorServerless auto-ingest with cloud events (SQS/SNS/PubSub), Snowpipe REST API, Snowpipe Streaming SDK for sub-second ingestion, Kafka connector exactly-once offsets & latency economicsStart here
- Streams, Tasks & Continuous CDC DAGsTable streams with METADATA$ACTION offset tracking, transactional stream consumption, Cron and AFTER task trees, serverless tasks, idempotent MERGE pipelines & stale stream preventionStart here
- Dynamic Tables & Declarative PipelinesTARGET_LAG semantics, incremental vs full refresh rules, dependency DAG resolution, dynamic tables vs streams+tasks vs dbt architectural matrix, and lag budget observabilityStart here
- Semi-Structured Data: JSON & VARIANTNative columnar shredding in micro-partitions, path navigation (colon and bracket), FLATTEN & LATERAL unnesting, OBJECT_CONSTRUCT, INFER_SCHEMA & automatic schema evolutionStart here
- Performance Tuning & ClusteringNatural partition order, clustering depth & information functions, Automatic Clustering Service, Search Optimization Service (SOS), Query Acceleration (QAS), and reading Query ProfilesStart here
- Time Travel, Fail-Safe & Zero-Copy CloningAT/BEFORE syntax (TIMESTAMP, OFFSET, STATEMENT), 0–90 days data retention storage costs, 7-day disaster Fail-safe, metadata pointer cloning & instant UNDROP table recoveryStart here
- Security, Governance, RBAC & MaskingFunctional vs Access roles hierarchy, SCIM/SSO provisioning, Dynamic Data Masking policies (INVOKER_ROLE), Row Access Policies (RAP), object tagging, lineage & ACCESS_HISTORYStart here
- Data Sharing, Clean Rooms & MarketplaceZero-copy secure shares, reader accounts for non-Snowflake consumers, Marketplace listings, cross-cloud cross-region database replication, and privacy-preserving Clean RoomsStart here
- Snowpark, Stored Procs & SPCSPython/Java DataFrame API, AST pushdown to SQL, vectorized UDFs with Pandas/NumPy, Stored Procedures (Caller vs Owner rights), Snowpark Container Services & Native NotebooksStart here
- Apache Iceberg & Open LakehouseInternal vs external vs Iceberg tables, Snowflake- managed vs externally-managed Iceberg, Polaris and Open Catalog integrations, and UniForm interop across Delta Lake & IcebergStart here
- FinOps, Cost Optimization & Right-SizingCredit consumption math, 10% Cloud Services adjustment rule, Resource Monitors (75%/90%/100%), ACCOUNT_USAGE cost tracking, right-sizing warehouses & storage leak remediationStart here
- CI/CD, Terraform, schemachange & Alertsschemachange versioned migrations (V/R/A scripts), Terraform Snowflake provider for infra-as-code, dbt-snowflake integration with QUERY_TAG, zero-copy PR clones & event alertsStart here
- Staff DE System Drills & Master Cheat Sheet50K events/sec clickstream design, multi- tenant B2B lakehouse with RAP, SCD Type-2 with Streams/Tasks, Teradata/Redshift migration playbook, lock deadlock triage & cheat sheetStart here
Practice this
Put it to work on LakeBench.
Common questions
- Does it cover cost control?
- Yes. There are chapters on virtual warehouse sizing and spilling, and on FinOps and right-sizing.
- Does it include Snowpark and Iceberg?
- Yes. It covers Snowpark and stored procedures, and Apache Iceberg for an open lakehouse layout.
- Can I read a sample before I commit?
- Yes. The contents pages and the first pages of every notebook can be read online, so you can judge the style before going further.