
Overview
Logs often arrive as one long line. Use named regular-expression groups to pull out fields such as time, status, request path, and latency.
On this page8 sections
What you will do
A web server writes one line of text for every request it handles. Nothing in that line is a column. It is one long string, and somewhere inside it is the status code that tells you whether the request worked.
2026-08-26T02:14:12Z GET /orders 503 2100msIn this lesson you pull a line like that apart into labelled fields using a regular expression, often shortened to regex. A regex is a short pattern that describes the shape of some text, so Python can find every piece of text with that shape.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Regex | A pattern that describes the shape of text |
| Pattern | The text you write to say what to look for |
| Match | A piece of text that fits the pattern |
| Group | A part of the pattern you want to pull out |
| Named group | A group with a name, like (?P<city>...) |
| Compile | Prepare a pattern once so you can reuse it |
Why this skill
Why does split() break on real logs?
Log lines drift. Here are two error lines from the same service, and we pick the fifth word of each.
Predict: line a has the message 'payment failed' and line b has 'timeout'. Do both lines print the same kind of value?
a = "2026-08-26T02:14:15Z ERROR payment failed order=ORD-7 amount=49.90"
b = "2026-08-26T02:14:16Z ERROR timeout order=ORD-8 amount=12.00"

print(a.split()[4])
print(b.split()[4])order=ORD-7 amount=12.00
Same index, different field. The first message was two words long, so everything after it moved over by one. What you really want is "find the thing that starts with order= and take what follows". That is a pattern, not a position.
split() counts positions. A regex describes a shape.
What can regex do that split() cannot?
- Find every line that contains a 5xx status.
- Lift an order id out of free text.
- Check that an id looks like ORD- followed by digits.
An example. The line "2026-01-05 ERROR order=ORD-1042 status=503" has no fixed number of words, so split() cannot promise where the order id sits. A pattern such as ORD-\d+ finds it wherever it appears, and it still works if someone adds a word before it.
Real logs come from web servers, application traces, firewalls and legacy banking exports. A pattern keeps working when someone adds a word to a message. A word count silently loads the wrong column into your warehouse.
How the code works
Which symbols do you need?
Python's re module is built in. A pattern is mostly made of a handful of symbols.
The small vocabulary that covers most log parsing.
| Symbol | Matches | Example |
|---|---|---|
| \d | one digit | \d matches 5 |
| \d{3} | exactly three digits | matches 503 |
| \d+ | one or more digits | matches 2100 |
| \S+ | one or more characters that are not whitespace | matches /orders |
| \s+ | one or more whitespace characters | matches the gap between fields |
| GET|POST | either word | matches GET |
| (?P<name>...) | a named group: whatever matches inside gets a label | (?P<status>\d{3}) |
How do named groups turn text into fields?
Write (?P<name>...) around each piece. Python then hands back a dictionary of name to text, which is one table row.
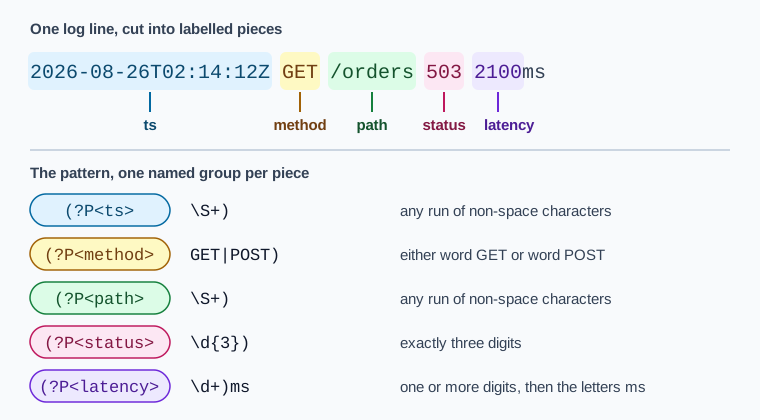
The top row is the line, coloured by field. Below it, (?P<status>\d{3}) means "capture exactly three digits and call them status". The \s+ between the groups is the whitespace between fields.
Predict: what does m.groupdict() contain, and what does m.group("status") print?
import re

line = "2026-08-26T02:14:12Z GET /orders 503 2100ms"

pat = re.compile(
    r"(?P<ts>\S+)\s+(?P<method>GET|POST)\s+(?P<path>\S+)\s+(?P<status>\d{3})\s+(?P<latency>\d+)ms"
)

m = pat.search(line)
print(m.groupdict())
print(m.group("status")){'ts': '2026-08-26T02:14:12Z', 'method': 'GET', 'path': '/orders', 'status': '503', 'latency': '2100'}
503search looks for the pattern anywhere in the line. Look at '503' in quotes: regex always returns text, so cast latency with int() before you do maths.
The r before the quote makes a raw string, so backslashes reach the regex engine untouched. Always write patterns as raw strings.
Why compile the pattern once?
re.compile builds the pattern a single time. Do it outside your loop and reuse the compiled object for every line, instead of rebuilding the same pattern a million times.
An analogy: if you check a million lines for a phone number, you would not rewrite the checking rules on a fresh page for every line. You write the rules once and keep them in front of you. The compiled pattern is that one page of rules.
Name each group you care about, and compile the pattern once.
Worked examples
Example 1: how do you parse every line in a batch?
search finds the first match. finditer gives one match per line across a whole block of text. Here are four lines, shown as the table we want to end up with.
The four lines, shown as the table we want to end up with.
| ts | method | path | status | latency |
|---|---|---|---|---|
| 2026-08-26T02:14:11Z | GET | /orders | 200 | 41ms |
| 2026-08-26T02:14:12Z | GET | /orders | 503 | 2100ms |
| 2026-08-26T02:14:13Z | POST | /ingest | 201 | 88ms |
| 2026-08-26T02:14:14Z | GET | /health | 500 | 12ms |
Predict: how many lines parse, what is rows[1], and how many have a status starting with 5?
import re

LOG = """2026-08-26T02:14:11Z GET /orders 200 41ms
2026-08-26T02:14:12Z GET /orders 503 2100ms
2026-08-26T02:14:13Z POST /ingest 201 88ms
2026-08-26T02:14:14Z GET /health 500 12ms
"""

pat = re.compile(
    r"(?P<ts>\S+)\s+(?P<method>GET|POST)\s+(?P<path>\S+)\s+(?P<status>\d{3})\s+(?P<latency>\d+)ms"
)

rows = [m.groupdict() for m in pat.finditer(LOG)]
fives = [row for row in rows if row["status"].startswith("5")]

print(len(rows), "lines parsed")
print(rows[1])
print("5xx:", len(fives))4 lines parsed
{'ts': '2026-08-26T02:14:12Z', 'method': 'GET', 'path': '/orders', 'status': '503', 'latency': '2100'}
5xx: 2Regex does the middle two steps. The rest is ordinary Python you already know.
rows is the same kind of list of dictionaries you built in the structures lesson. From here it is ordinary Python. The two server errors are 503 and 500.
How do you turn the captured text into numbers?
Every value in rows is text. Cast first, then the maths works.
Predict: what are the slowest request and the average latency?
import re

LOG = """2026-08-26T02:14:11Z GET /orders 200 41ms
2026-08-26T02:14:12Z GET /orders 503 2100ms
2026-08-26T02:14:13Z POST /ingest 201 88ms
2026-08-26T02:14:14Z GET /health 500 12ms
"""

pat = re.compile(
    r"(?P<ts>\S+)\s+(?P<method>GET|POST)\s+(?P<path>\S+)\s+(?P<status>\d{3})\s+(?P<latency>\d+)ms"
)

rows = [m.groupdict() for m in pat.finditer(LOG)]
latencies = [int(row["latency"]) for row in rows]

print(latencies)
print("slowest:", max(latencies), "ms")
print("average:", sum(latencies) / len(latencies), "ms")[41, 2100, 88, 12] slowest: 2100 ms average: 560.25 ms
Without int(), max() would compare text and '88' would beat '2100'. The cast is the step that makes the numbers real.
Try re.findall(r"\d{3}", LOG) on the four lines from Example 1. You get more than the status codes. You also get pieces of the year (202) and of the latency (210 out of 2100). A bare \d{3} matches any three digits anywhere. Anchor your pattern to the text around the field, so it can only match where you intend.
Example 2: how do you lift one value out of free text?
Sometimes you want a single field from a messy message. The pattern can be tiny.
Predict: does order=(?P<order>\S+) work on both lines, even though their messages differ in length?
import re

a = "2026-08-26T02:14:15Z ERROR payment failed order=ORD-7 amount=49.90"
b = "2026-08-26T02:14:16Z ERROR timeout order=ORD-8 amount=12.00"

for text in (a, b):
    m = re.search(r"order=(?P<order>\S+)", text)
print(m.group("order"))ORD-7 ORD-8
The pattern says: find order=, then capture everything up to the next space. It does not care where in the line that sits, which is the point.
Why write \S+ instead of .* ?
The dot star means any character, as many as possible. On this line it swallows the rest of the message.
import re

line = "2026-08-26T02:14:15Z ERROR payment failed order=ORD-7 amount=49.90"

print(re.search(r"order=(.*)", line).group(1))
print(re.search(r"order=(\S+)", line).group(1))ORD-7 amount=49.90 ORD-7
Be explicit about what a field may contain: \S+ for a word, \d{3} for three digits, [^"]* for text inside quotes. Specific patterns fail fast on bad input.
Open-ended ones with nested repeats, such as (a+)+, can make the engine retry an exponential number of ways on a line that almost matches. One malformed line can then freeze a pipeline.
The dot means "any character" and the star means "as many as possible". On <b>x</b> <i>y</i> the pattern <.*> matches the whole string, from the first < to the very last >. Add a question mark, <.*?>, and it stops at the first >. When you know the shape of a field, prefer \S+ or \d{3} over a loose .*.
How do you hide or clean parts of a line?
re.sub replaces whatever a pattern matches. Pipelines use it to mask private values before a line is stored.
import re

line = "2026-08-26T02:14:15Z ERROR payment failed order=ORD-7 amount=49.90"

print(re.sub(r"order=\S+", "order=***", line))2026-08-26T02:14:15Z ERROR payment failed order=*** amount=49.90
Everything the pattern matched became ***. The rest of the line is untouched.
What if a field is sometimes missing?
Put a group in (?:...)? to make it optional. Some log lines have a trailing latency and some do not.
Predict: what does the optional latency group hold for the second line?
import re

pat = re.compile(r"(?P<path>/\S+)\s+(?P<status>\d{3})(?:\s+(?P<latency>\d+)ms)?")

for line in ("GET /orders 503 2100ms", "GET /health 200"):
print(pat.search(line).groupdict()){'path': '/orders', 'status': '503', 'latency': '2100'}
{'path': '/health', 'status': '200', 'latency': None}A group that did not take part gives None, so cast only after checking. Without the ? the second line would not match at all.
How do you check that a whole id is valid?
search accepts a match anywhere. fullmatch needs the whole string to fit, which is what you want when validating.
import re

good = "ORD-12345678"
bad = "INVALID_ORD-12345678_EXTRA"

print(bool(re.search(r"ORD-\d{8}", bad)))
print(bool(re.fullmatch(r"ORD-\d{8}", bad)))
print(bool(re.fullmatch(r"ORD-\d{8}", good)))True False True
You can also anchor a pattern: ^ means start of the string and $ means end, so r"^ORD-\d{8}$" behaves like fullmatch.
What happens when a line does not match?
search returns None when nothing matches. Calling .group on None crashes the script.
import re

pat = re.compile(r"(?P<status>\d{3})ms")
m = pat.search("not a log line at all")
print(m)
print(m.group("status"))None Traceback (most recent call last): File "pipeline.py", line 6, in <module> AttributeError: 'NoneType' object has no attribute 'group'
Real feeds always hold a few bad lines: a blank line, a truncated write, a stray debug print. Test with if m: before using the match, and set unmatched lines aside instead of dropping them.
import re

LOG = """2026-08-26T02:14:11Z GET /orders 200 41ms
2026-08-26T02:14:12Z GET /orders 503 2100ms
2026-08-26T02:14:13Z POST /ingest 201 88ms
2026-08-26T02:14:14Z GET /health 500 12ms
--- truncated write ---
"""

pat = re.compile(
    r"(?P<ts>\S+)\s+(?P<method>GET|POST)\s+(?P<path>\S+)\s+(?P<status>\d{3})\s+(?P<latency>\d+)ms"
)

rows, rejects = [], []
for number, line in enumerate(LOG.splitlines(), start=1):
    m = pat.search(line)
    if m:
        rows.append(m.groupdict())
    else:
        rejects.append((number, line))

print(len(rows), "parsed")
print("rejected:", rejects)4 parsed rejected: [(5, '--- truncated write ---')]
The rejects list is your early warning. If its size jumps, an upstream team probably changed the log format, and you update the pattern before reports go wrong.
How does the whole lesson replay on one log?
A web server writes the line 2026-08-26T02:14:12Z GET /orders 503 2100ms. It is one string.
- log line
The pattern is compiled once with re.compile, as a raw string.
- re.compile
- pattern
finditer walks the four lines and returns one match per line.
- 4 lines
- 4 matches
groupdict turns each match into a dictionary. rows[1] has status '503' and latency '2100', both text.
- match
- dict
Filtering on status.startswith('5') keeps 503 and 500, so the count is 2.
- status
- 5xx: 2
A line that does not fit gives None. The script checks if m: and sets it aside.
- None
- rejects
Six things every data engineer must know about regex:
- Use a pattern, not a position, when text can drift.
- Write patterns as raw strings: r"...".
- Name the groups you need with (?P<name>...) and read them with groupdict().
- Regex returns text, so cast numbers yourself.
- Prefer \S+ and \d{3} to .*, and use fullmatch to validate a whole value.
- Check for None before using a match, and quarantine lines that do not fit.
Write the pattern as a raw string, name each group you care about with (?P<name>...), and check for None before you use the match. Everything captured comes back as text, so convert numbers yourself.
Common beginner questions
Do I need to memorise all the symbols?
No. The seven in the table cover most log work. Everyone looks up the rest, and testing a pattern on a few sample lines before using it is normal.
What is the difference between search, match and fullmatch?
search looks anywhere in the text. match only succeeds if the pattern fits at the very start. fullmatch needs the whole text to fit the pattern, which makes it the right choice when you are validating something like an id.
When should I not use regex?
When the data already has a structure. For CSV use the csv module, for JSON use the json module. Regex is the tool for text that has no structure you can read directly, like a log line.
What comes next
The next lesson is about encoding: what happens when the bytes in a file are not the text you think they are. After that comes logging, so your own pipeline can write the kind of log lines you just learned to parse.
Practice
The exercise uses the same four log lines. Write a pattern that captures the status, count how many are 5xx, print the count, and store it in result.
Think about the loose-pattern warning above, and make your pattern specific to the status field rather than a bare three-digit match.
Going further: search, match and a pattern that is too loose
Two small differences cause many regex bugs. re.match only looks at the start of the text, while re.search looks anywhere. And a pattern that is a little too loose happily accepts text you meant to reject. Predict which calls find the order id.
import re

line = "2026-09-01 ERROR order=ORD-1042 failed"

print("match :", re.match(r"order=(ORD-\d+)", line))
print("search:", re.search(r"order=(ORD-\d+)", line).group(1))match : None search: ORD-1042
match returns None because the line does not start with 'order='. search finds it in the middle. If a pattern 'works in the tester but not in the code', check which of the two you called.
Now a pattern that is too loose. We want ids like ORD-1042 and nothing else.
import re

candidates = ["ORD-1042", "ORD-1042-extra", "xORD-1042", "ORD-10"]
loose = re.compile(r"ORD-\d+")
strict = re.compile(r"ORD-\d{4}")

for text in candidates:
print(f"{text:15} loose={bool(loose.search(text))!s:5} strict-full={bool(strict.fullmatch(text))}")ORD-1042 loose=True strict-full=True ORD-1042-extra loose=True strict-full=False xORD-1042 loose=True strict-full=False ORD-10 loose=True strict-full=False
The loose search accepts every candidate, including 'xORD-1042' and the short 'ORD-10'. fullmatch with an exact digit count accepts only ORD-1042. Use fullmatch when you are validating a whole value, and search when you are looking for a value inside a longer line.
Try a new scenario
Extract the status code and the milliseconds from 'GET /orders 200 35ms' and from 'POST /pay 500 1204ms', and report which line is slow (over 1,000 ms).
Open the answer
The results are '200 35 False ; 500 1204 True'. Named groups give the fields readable names, and int() turns the text into a number before the comparison. Comparing the strings '1204' and '1000' would also appear to work, but '999' would compare as larger than '1000' as text, so convert first.
Why compile a regular expression once?
re.compile does the pattern-parsing work once so a loop over millions of lines reuses it. Python caches recent patterns anyway, so the gain is small for one-off use, but a named, compiled pattern also reads better and can be tested on its own.
Close the lesson and explain it
Without scrolling up, explain the difference between match, search and fullmatch, and when a loose pattern becomes a data bug.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this idea
Each page shows the idea moving, then lists problems from easiest. Open one now, or come back when you finish the lesson.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.
- Bigrams from a sentenceInterview-style drill: Build pairs of consecutive words after lowercasing and removing punctuation.Studiobeginnerpython8 min
- Compact a run-length encoded event logInterview-style drill: Compress a sequence of repeated status codes into a run-length encoded form.Studiobeginnerpython10 min
- Expand a run-length encoded shift logInterview-style drill: Expand a run-length encoded string back into its original repeated sequence.Studiobeginnerpython10 min