
Overview
Pipeline data is not one long list. Learn when to use lists, tuples, dictionaries, sets, and comprehensions to hold and reshape records.
On this page8 sections
What you will do
One order is easy to hold in your head. A day's worth is a thousand of them.
What three questions does one batch of orders raise?
The same data answers different questions, and Python gives you a different container for each. We use these three orders for the whole lesson.
The three orders we will use for the whole lesson.
| id | status | total |
|---|---|---|
| ORD-1 | paid | 120.5 |
| ORD-2 | cancelled | 40.0 |
| ORD-3 | paid | 88.25 |
Each question is a different way of touching the same data.
| The question | The container |
|---|---|
| Go through every order, in order | list |
| Find the one called ORD-3 | dict |
| Which statuses exist at all? | set |
| Keep one fixed record that must not change | tuple |
You will build all four, then finish with a one-line way to filter a batch.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| List | An ordered collection you read by position |
| Dictionary | A collection where you look up a value by its key |
| Key | The label you look things up by |
| Tuple | A list that cannot be changed after it is made |
| Set | A collection with no repeats |
| Lookup | Finding a value by its key |
Why this skill
Picking the right container decides how fast and how clean your code is.
What happens if you pick the wrong container?
The code still runs, but it gets slower or quietly wrong. Collect ids in a list when you meant to deduplicate and the duplicates stay.
Choose by how you will use the data, not by how it looks.
Left side: position or fixed shape matters. Right side: you ask is this one here, or what goes with this key.
Why is a dictionary lookup so much faster?
Searching a list with in scans from the first item to the last. A dictionary or set jumps straight to the answer.
The difference between a pipeline that finishes in seconds and one that hangs for hours.
| list | dict or set | |
|---|---|---|
| How it finds ORD-3 | Checks items one at a time | Computes where the key lives |
| With 1 million rows | Up to 1 million comparisons | About the same work as with 10 rows |
| Cost grows with size | Yes (O(N)) | No (O(1) on average) |
The right container can turn a slow step into a fast one, as the next example shows.
A list searches by walking. A dict searches by jumping.
What does that speed buy on a real join?
ShopKart has 100,000 evening orders and 50,000 customer records. Each order needs its customer contact details.
Same answer, very different compute cost.
| Approach | Work done |
|---|---|
| Nested loops: scan all customers for every order | 100,000 x 50,000 = 5 billion comparisons |
| Dict of customers, then one lookup per order | 50,000 + 100,000 = 150,000 operations |
- Loop through the 50,000 customers once and build a dictionary keyed by customer_id.
- Loop through the 100,000 orders once and do one dictionary lookup for each customer_id.
Nothing changed except the data structure, yet performance improved by thousands of times.
How the code works
Python provides clean syntax to construct, query, and transform each container. The examples use for and if to walk through the data. Those get their own lesson next, so for now read them as plain instructions: for each order, do this.
How does a list keep order?
Square brackets make a list. Items keep the order you gave them, and a for loop visits them one by one. Our orders are a list of dictionaries. Predict the print order.
orders = [
    {"id": "ORD-1", "status": "paid", "total": 120.5},
    {"id": "ORD-2", "status": "cancelled", "total": 40.0},
    {"id": "ORD-3", "status": "paid", "total": 88.25},
]

for row in orders:
print(row["id"], row["total"])ORD-1 120.5 ORD-2 40.0 ORD-3 88.25
Three orders, three lines, in the exact sequence they were stored.
How does a dictionary find a value by key?
Curly braces with key: value pairs make a dictionary. Each order above is one, and row["total"] reads the value stored under that key.
A dictionary can also index the whole batch. Here we key it by order id, so we can jump directly to ORD-3. What does a missing key give?
by_id = {row["id"]: row for row in orders}

print(by_id["ORD-3"])
print(by_id.get("ORD-9")){'id': 'ORD-3', 'status': 'paid', 'total': 88.25}
NoneORD-9 is not in the batch, so .get() gave None. Writing by_id["ORD-9"] would crash with a KeyError.
Ask by key and you get the record straight away, however many entries there are.
Left boxes are keys and right boxes are records. Python does not read down the keys to find yours.
Use .get() when a key might be missing. Use brackets only when its absence should stop the job.
What is actually inside a dictionary?
A hash function turns each key into a bucket number. The value sits in that bucket.
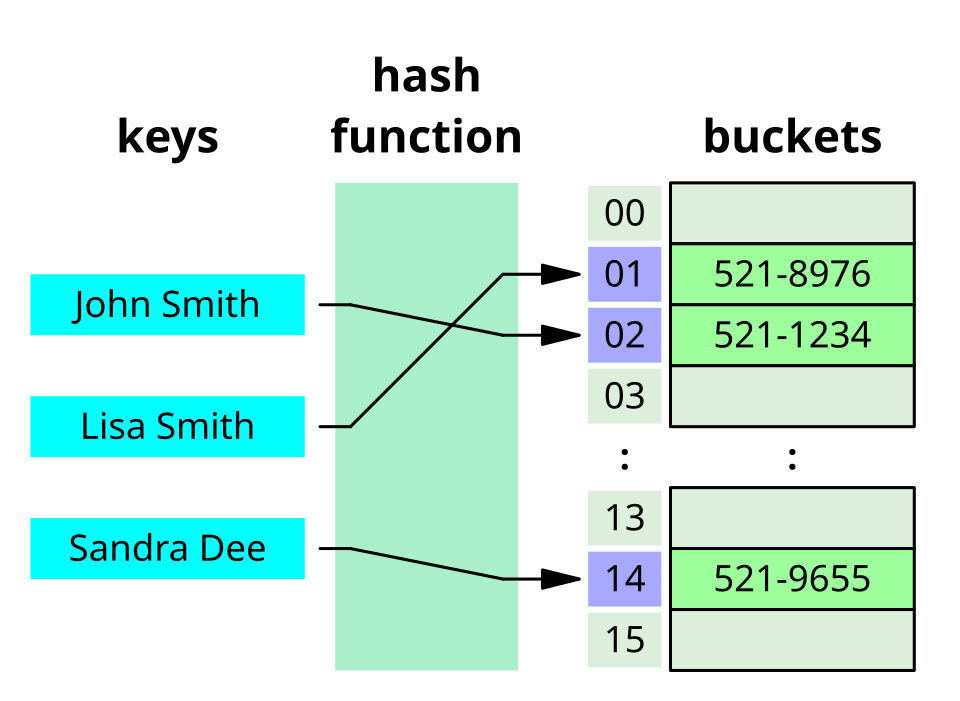
To look a name up again, Python runs the same function and walks straight to that bucket. Swap names for order ids and phone numbers for records and you have by_id.
How does a set keep each value once?
A set has no duplicates and no order. It answers which different values exist. Predict the counts of ids before and after.
statuses = set(row["status"] for row in orders)
print(sorted(statuses))

ids = ["ORD-1", "ORD-2", "ORD-1"]
print(len(ids), len(set(ids)))['cancelled', 'paid'] 3 2
The set collapsed three ids into two. That count difference is how you detect duplicates in a raw feed.
We wrapped the first set in sorted() because a set has no order of its own and may print differently each run.
How do sets find missing orders?
The website says it took 10,000 orders and the warehouse says it packed 9,985. Where are the 15? Set operations answer in one line each.
placed = {"ORD-1", "ORD-2", "ORD-3"}
packed = {"ORD-1", "ORD-3"}

print(sorted(placed - packed))
print(sorted(placed & packed))
print(sorted(placed | packed))['ORD-2'] ['ORD-1', 'ORD-3'] ['ORD-1', 'ORD-2', 'ORD-3']
Difference is placed but not packed. Intersection is in both. Union is everything seen at least once.
What makes a tuple a fixed record?
Round brackets make a tuple. It looks like a list, but once it exists you cannot change it. Can you edit grain[0]?
grain = ("ORD-1", "2026-08-01")
print(grain[0])

sales = {grain: 120.5}
print(sales[("ORD-1", "2026-08-01")])

grain[0] = "ORD-9"ORD-1 120.5 TypeError: 'tuple' object does not support item assignment
Python refuses the edit. Because a tuple can never change, it can be a dictionary key, which a list cannot.
Why can a tuple be a key but a list cannot?
A list can change in place, which would move its bucket and lose the key. A tuple cannot, so it is hashable.
A composite key such as warehouse plus SKU tracks stock per facility.
| Key | Works? | Why |
|---|---|---|
| ("BLR_WAREHOUSE", "SKU_7729") | Yes | Immutable, so its bucket never moves |
| ["BLR_WAREHOUSE", "SKU_7729"] | No | Mutable lists are not hashable |
Records with compound primary keys are common, and tuples are how you key a dictionary by several columns.
Which container do you reach for?
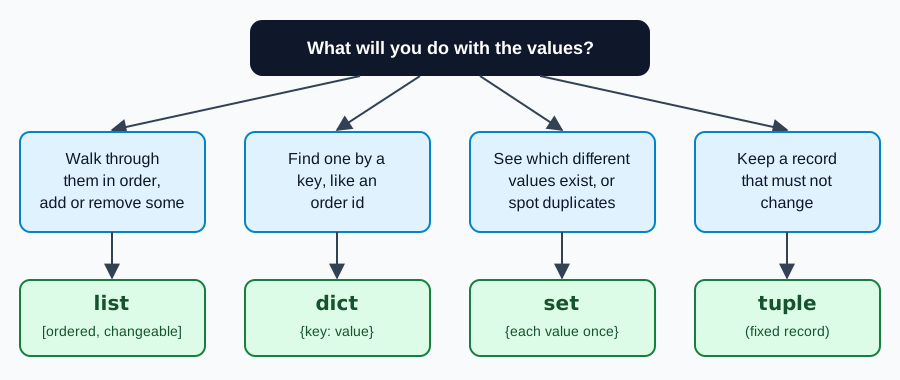
Start from the question and follow the arrow. If two arrows seem to fit, use a list, the one you will change your mind about least.
Worked examples
Example 1: how does a comprehension replace a loop?
Picking the paid totals takes a loop that builds a new list. A comprehension does the same in one line. Predict what is in paid_totals.
paid_totals = []
for row in orders:
    if row["status"] == "paid":
        paid_totals.append(row["total"])

# the same thing in one line
paid_totals = [row["total"] for row in orders if row["status"] == "paid"]

print(paid_totals)
print(sum(paid_totals))[120.5, 88.25] 208.75
Read it from the middle out. for row in orders walks the batch, the if keeps the paid ones, and row["total"] at the front says what to collect.
Example 2: how do you read a nested payment event?
API responses are dictionaries inside dictionaries, with lists inside those. You walk in one key at a time.
event = {
    "user": {"id": "U001", "country": "IN"},
    "items": [{"sku": "A1", "qty": 2}],
}

print(event["user"]["id"])
print(event["items"][0]["sku"])
print(event.get("coupon"))
print(event.get("coupon", "none"))
print(event["coupon"])U001 A1 None none KeyError: 'coupon'
The coupon key was never sent. .get() gives None or a default you choose, and brackets crash. Across thousands of events, the one that lacks a key is the one that kills the job.
Why does editing a copy change the original?
dict.copy() copies only the top level. Nested dictionaries and lists are still shared. Predict what a shows.
import copy

a = {"user": {"id": "U001"}}
b = a.copy()
b["user"]["id"] = "U999"
print(a["user"]["id"])

c = copy.deepcopy(a)
c["user"]["id"] = "U555"
print(a["user"]["id"])U999 U999
The shallow copy still points at the same inner dictionary, so editing b changed a. copy.deepcopy() gives a fully independent clone, so editing c left a alone (the second line stays U999).
dict.copy() duplicates only the top-level dictionary. Nested dictionaries and lists remain shared references. If you edit a nested value in the copy, the original changes too. Use copy.deepcopy() when cloning nested payloads.
Example 3: what happens with duplicate ids?
This mistake gives no error at all. Two rows share an id and we index the batch by id.
rows = [
    {"id": "ORD-1", "total": 10},
    {"id": "ORD-1", "total": 12},
]

by_id = {row["id"]: row for row in rows}
print(by_id)
print(len(rows), len(by_id)){'ORD-1': {'id': 'ORD-1', 'total': 12}}
2 1The later row silently replaced the earlier one. Compare len(rows) with len(by_id) to catch it.
A dict key holds one value. A repeated key quietly overwrites, so check the lengths.
Examples 4 to 6 are optional on a first read. They show up in real pipelines, and you can come back to them after the next lessons.
Example 4: how do you count with Counter?
Counting statuses with a plain dict means checking whether the key exists. collections.Counter counts for you.
from collections import Counter

statuses = ["paid", "cancelled", "paid", "paid", "refunded", "cancelled"]
counts = Counter(statuses)

print(dict(counts))
print("Most frequent:", counts.most_common(1))
print("Pending count:", counts["pending"]){'paid': 3, 'cancelled': 2, 'refunded': 1}
Most frequent: [('paid', 3)]
Pending count: 0A key Counter has never seen returns 0 instead of raising KeyError. most_common(k) returns the top k, ideal for top error codes.
Example 5: how do you group with defaultdict?
defaultdict creates the missing entry for you from a factory such as list or float. No if key not in groups check is needed.
from collections import defaultdict

orders = [
    {"user": "U1", "order_id": "ORD-1", "total": 120.5},
    {"user": "U2", "order_id": "ORD-2", "total": 40.0},
    {"user": "U1", "order_id": "ORD-3", "total": 88.25},
]

by_user = defaultdict(list)
for o in orders:
    by_user[o["user"]].append(o["order_id"])

totals = defaultdict(float)
for o in orders:
    totals[o["user"]] += o["total"]

print(dict(by_user))
print(dict(totals)){'U1': ['ORD-1', 'ORD-3'], 'U2': ['ORD-2']}
{'U1': 208.75, 'U2': 40.0}list starts each new key with an empty list and float starts with 0.0.
Example 6: how do you keep a rolling window with deque?
A stream pipeline keeps the latest N values. list.pop(0) is slow because every item shifts left. A deque with maxlen drops the oldest value for free.
from collections import deque

window = deque(maxlen=3)
stream = [10.0, 20.0, 30.0, 40.0, 50.0]
rolling_averages = []

for val in stream:
    window.append(val)
    avg = sum(window) / len(window)
    rolling_averages.append(round(avg, 1))

print("Final window:", list(window))
print("Rolling averages:", rolling_averages)Final window: [30.0, 40.0, 50.0] Rolling averages: [10.0, 15.0, 20.0, 30.0, 40.0]
At 40.0 the oldest value, 10.0, fell out. Memory stays at three items.
| Value arrives | Window holds | Average |
|---|---|---|
| 10.0 | 10.0 | 10.0 |
| 20.0 | 10.0, 20.0 | 15.0 |
| 30.0 | 10.0, 20.0, 30.0 | 20.0 |
| 40.0 | 20.0, 30.0, 40.0 | 30.0 |
| 50.0 | 30.0, 40.0, 50.0 | 40.0 |
[ ] makes a list, ( ) makes a tuple, { } with key: value pairs makes a dictionary, and { } with only values makes a set. An empty { } is a dictionary, not a set. To get an empty set write set().
How does the whole lesson replay on ORD-1 to ORD-3?
The three orders live in a list, so we can walk them in order.
- list of orders
- for loop
by_id turns the list into a dictionary, so ORD-3 is one jump away.
- list
- by_id dict
- ORD-3
A set of statuses shows which different values exist: cancelled and paid.
- orders
- set
- 2 statuses
A comprehension keeps the paid totals, 120.5 and 88.25, and sums them to 208.75.
- orders
- paid_totals
- 208.75
If two rows share an id, the dictionary keeps only the last, so compare the lengths.
- 2 rows
- by_id
- 1 key
Four rules to carry forward:
- List to walk through, dict to look up, set to deduplicate, tuple for a fixed record.
- Use .get() on a dict when a key might be missing, otherwise you get a KeyError.
- A comprehension is just a loop that builds a list, written on one line.
- A repeated dict key silently overwrites, so compare lengths when you index a batch.
Common beginner questions
Why not store everything in lists?
You can, and for small data it works. But finding an item in a list means checking items one at a time. On a large batch that gets slow, and a dictionary does the same job almost instantly.
What happens if I ask a dictionary for a key that is not there?
With square brackets Python raises a KeyError and stops. With .get(key) you get None, or whatever default you pass as the second argument, and the code carries on.
Is a set the same as a list with duplicates removed?
Close, but a set also throws away the order. If order matters, remove duplicates while you loop and keep a separate set of the ids you have already seen.
What comes next
You can now hold a batch of orders. The next lesson covers decisions and repeats: if, for and while, so you can go through every order and treat each one by its status.
After that comes control flow with error handling, where you skip bad rows, catch an error, and retry a failed call. Then come functions, so you can package this logic and reuse it.
Practice
The exercise gives you the same three orders. First build a dictionary keyed by id, then use a comprehension to collect the totals of the paid orders, print them, and keep the list in result.
Going further: which duplicate wins?
The lesson built dictionaries and sets. A common real job combines them: an events feed contains the same order several times, and you want the latest version of each. A dictionary does this almost by accident, because assigning to an existing key replaces its value. Predict the final status of each order.
events = [
    {"order_id": "A1", "status": "placed",  "at": 1},
    {"order_id": "A2", "status": "placed",  "at": 2},
    {"order_id": "A1", "status": "shipped", "at": 3},
    {"order_id": "A2", "status": "placed",  "at": 2},      # exact repeat
    {"order_id": "A1", "status": "placed",  "at": 1},      # a late, older copy
]

last_write_wins = {}
for e in events:
    last_write_wins[e["order_id"]] = e["status"]

latest = {}
for e in events:
    current = latest.get(e["order_id"])
    if current is None or e["at"] > current["at"]:
        latest[e["order_id"]] = e

print("last write wins:", last_write_wins)
print("newest timestamp:", {k: v["status"] for k, v in latest.items()})last write wins: {'A1': 'placed', 'A2': 'placed'}
newest timestamp: {'A1': 'shipped', 'A2': 'placed'}Order A1 is the trap. 'Last write wins' follows arrival order, so the late old copy overwrites 'shipped' with 'placed'. Comparing timestamps keeps the true latest. The rule you pick is a business decision: arrival order and event time are different things.
| Rule | Good when | Breaks when |
|---|---|---|
| Last one to arrive wins | The feed is always in order | Late or replayed events arrive |
| Highest timestamp wins | Every event carries a trustworthy time | 2 events share a timestamp, or clocks are wrong |
| Highest version number wins | The source assigns increasing versions | The source does not have versions |
Try a new scenario
A list of user ids contains repeats, and you must report how many different users there are and which ids appeared more than once. Which container do you use for each part?
Open the answer
A set answers 'how many different': its size is the count. To find repeats, check membership before adding. The result for this list is 3 ['u1', 'u2']: 3 different users, and u1 and u2 repeated. A set lookup is a single hash check, so this stays fast on millions of ids.
Interview: when would you use a set instead of a list?
When you only need membership tests or uniqueness. Checking whether a value is in a set takes about the same time however large it is, while a list must be scanned from the start. A set loses order and duplicates, so use a list when order or repeats matter.
Close the lesson and explain it
Without scrolling up, explain why a dictionary can keep the wrong version of a record, and what you would compare instead.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this idea
Each page shows the idea moving, then lists problems from easiest. Open one now, or come back when you finish the lesson.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.
- Contains DuplicateInterview-style drill: True if any value appears more than once.Studiobeginnerpython10 min
- Count events per minuteInterview-style drill: Group stream events into one-minute buckets and count how many fall in each bucket.Studiobeginnerpython10 min
- Counter for warehouse zone visitsInterview-style drill: Given a sequence of warehouse zone visits, return each zone's visit count sorted by frequency.Studiobeginnerpython10 min