
Overview
Large files do not always fit in memory. Learn how a generator uses yield to give a job one line or record at a time.
On this page8 sections
What you will do
A web server writes an access log that grows by gigabytes every day. Your pipeline worker has 2 GB of memory. You need to scan the entire file and count only the requests that failed.
Memory exhaustion on large files
The straightforward approach reads every line into a Python list before looping. Look at what happens to memory.
- 20 GB log file
- read all into a list
- needs 20 GB of RAM
- process is killed
The fix is to inspect one line at a time, process it, and immediately discard it before reading the next. A generator is Python's native tool for streaming data this way. We use ShopKart's events.ndjson to demonstrate it.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Generator | A function that hands out one value at a time |
| yield | Give back one value and pause until asked for the next |
| Lazy | Only do the work when the result is needed |
| Memory | The space your computer has for data that is in use right now |
| next() | Ask a generator for its next value |
| Chunk | A slice of a large file read in one go |
Why this skill
Memory footprint: list versus generator
Square one million integers in two ways. The list stores all one million squares in memory at once. The generator stores only the rule to compute the next number.
import sys

as_list = [n * n for n in range(1_000_000)]
as_gen = (n * n for n in range(1_000_000))

print(sys.getsizeof(as_list))
print(sys.getsizeof(as_gen))8448728 208
The list consumes over 8 megabytes just for pointer storage, while the generator stays at 208 bytes. The memory gap widens dramatically as datasets grow into gigabytes.
Container memory limits in production
Data pipelines frequently run inside worker pods, Cloud Functions, or scheduler tasks configured with tight memory ceilings between 512 MB and 2 GB. ShopKart's payment gateway deposits a 20 GB transaction archive every night.
Operating systems terminate memory-violating containers with exit code 137.
| Extraction approach | Memory required | Result on a 20 GB file |
|---|---|---|
| open(path).readlines() | Entire file size | Out of memory error, process killed |
| list(csv.reader(f)) | Entire file size | Out of memory error, process killed |
| for line in f | One line at a time | Safe, steady memory usage |
| Generator pipeline | One record at a time | Safe, steady memory usage |
A generator pipeline maintains flat memory usage whether the source file contains one hundred records or one hundred million records.
Lazy evaluation: compute on demand
A generator does no computation when instantiated. It produces individual values only when the consumer explicitly asks for the next item.
Same data, very different memory.
Laziness also enables early stopping. If you search for the first matching transaction, the generator halts immediately without reading the remaining gigabytes from disk.
Choose a generator when working with large files or when you only need a subset of the data.
How the code works
yield versus return
A standard return statement exits a function and destroys its local stack frame. A yield expression hands a value to the caller and freezes execution at that line, keeping all variables intact.
def three():
    yield "a"
    yield "b"
    yield "c"

g = three()
print(type(g).__name__)
print(next(g), next(g))
print(list(g))generator a b ['c']
Calling three() executes none of the function body; it returns a generator object. Each call to next(g) advances to the next yield. Passing the remainder to list(g) collects whatever is left.
Execution handoff between loop and generator
The calling loop and the generator alternate execution in lockstep. Follow the flow from top to bottom.
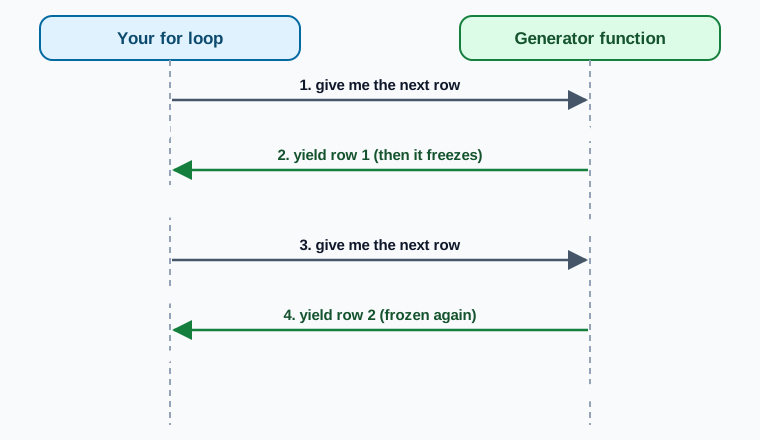
The loop requests a record. The generator executes until it hits yield, hands over the value, and suspends itself. The loop processes that record and requests another, whereupon the generator resumes on the line immediately following yield.
Observing the generator pause
Print statements make the pause and resume cycles visible. Predict when 'starting' prints, and what prints after 'about to yield 2'.
def countdown(n):
    print("starting")
    while n > 0:
        print("about to yield", n)
        yield n
        print("resumed after", n)
        n -= 1
    print("done")

gen = countdown(2)
print("created, nothing printed yet")
print("got", next(gen))
print("got", next(gen))created, nothing printed yet starting about to yield 2 got 2 resumed after 2 about to yield 1 got 1
Instantiating countdown(2) executed nothing. 'resumed after 2' printed only when the second next() arrived, proving that the code after yield waited for the consumer.
A generator preserves execution state. Nothing runs until the consumer requests the first element.
Exhaustion and StopIteration
A standard for loop catches completion automatically. When calling next() manually, Python raises StopIteration once the function finishes its body.
gen = countdown(1)
print(next(gen))
try:
    next(gen)
except StopIteration:
print("StopIteration: no more values")starting about to yield 1 1 resumed after 1 done StopIteration: no more values
Notice that 'done' printed before the exception was raised. Code placed after the final yield runs as the generator cleans up its stack frame.
Generator expressions
Replace the square brackets of a list comprehension with round parentheses to create a generator expression without writing a function. Predict what the second sum outputs.
squares = (n * n for n in range(5))
print(sum(squares))
print(sum(squares))30 0
The first call to sum() consumed all five generated numbers: 0 + 1 + 4 + 9 + 16 equals 30. The second call found the generator already exhausted and evaluated to 0.
Why generators do not support len()
Because a generator holds no elements in memory, it cannot report a length. It only knows how to compute the next value on demand.
squares = (n * n for n in range(5))
try:
    len(squares)
except TypeError as e:
print("TypeError:", e)TypeError: object of type 'generator' has no len()
To count elements without buffering them, evaluate sum(1 for _ in stream). Because that consumes the generator, always pass a fresh generator if subsequent steps need data.
Streaming file lines with a generator
Python file objects already stream line by line. Wrapping a file in a generator function lets you clean rows one at a time and still read the file line by line.
import json

def read_events(path):
    with open(path) as f:
        for line in f:
            yield json.loads(line)

stream = read_events("/data/events.ndjson")
print(next(stream)){'event_id': 'e1', 'user': 'U001', 'type': 'purchase', 'amount': 120.5}Only the first line was read and parsed into memory. The remaining lines in events.ndjson remain unparsed on disk.
Worked examples
Event stream structure in events.ndjson
The file events.ndjson stores one JSON event per line. These four sample records illustrate our streaming pipeline.
The sample events, stored as one JSON object per line.
| event_id | user | type | amount |
|---|---|---|---|
| e1 | U001 | purchase | 120.5 |
| e2 | U002 | page_view | null |
| e3 | U001 | purchase | 88.25 |
| e4 | U003 | add_to_cart | 15 |
Chaining generators into a pipeline
The generator read_events yields every event. A second generator, purchases, filters the stream and passes only purchases downstream. Predict the count and total revenue.
def purchases(events):
    for event in events:
        if event["type"] == "purchase":
            yield event

count = 0
revenue = 0
for event in purchases(read_events("/data/events.ndjson")):
    count += 1
    revenue += event["amount"]
    print(event["event_id"], event["amount"])

print("purchases", count, "revenue", revenue)e1 120.5 e3 88.25 purchases 2 revenue 208.75
The outer loop pulls from purchases, which pulls from read_events, which reads a single line from disk. Only one parsed event resides in memory at any moment.
Tracing record flow through the pipeline
Events e2 and e4 are parsed, checked, and immediately dropped inside the purchases generator. The consumer loop never sees them.
Each stage processes one event completely before the next line is read from disk.
| Event | read_events stage | purchases filter | Delivered to loop? |
|---|---|---|---|
| e1 purchase | Yields parsed dict | Passes through | Yes, counted |
| e2 page_view | Yields parsed dict | Filtered out | No, discarded |
| e3 purchase | Yields parsed dict | Passes through | Yes, counted |
| e4 add_to_cart | Yields parsed dict | Filtered out | No, discarded |
This architecture matches Unix command-line pipes. Each pipeline stage receives a record, applies logic, and passes it forward without creating intermediate files or lists on disk.
The single-pass trap: empty second loop
A logging function counts records in a stream, and then the loader attempts to insert the same stream. Predict what the loader receives.
stream = purchases(read_events("/data/events.ndjson"))

counted = sum(1 for _ in stream)
loaded = list(stream)
print("counted:", counted, "loaded:", len(loaded))

fresh = purchases(read_events("/data/events.ndjson"))
print("fresh loaded:", len(list(fresh)))counted: 2 loaded: 0 fresh loaded: 2
The count operation completely exhausted the stream, leaving zero elements for the loader. For multiple passes, instantiate a fresh generator or execute all tasks in a single pass.
A generator can be iterated only once. Subsequent loops over an exhausted generator silently do nothing.
After a full iteration pass, the generator is completely exhausted. A second loop over the same generator object immediately finishes with zero items. If you need a second pass, call the generator function again to obtain a fresh generator.
Deferred execution and late errors
A generator function does not execute its body until the consumer calls next(). Consequently, errors such as missing file paths manifest during iteration rather than function invocation.
def read_lines(path):
    with open(path) as f:
        for line in f:
            yield line

lines = read_lines("/data/missing.log")
print("generator created")
first = next(lines)generator created FileNotFoundError: [Errno 2] No such file or directory: '/data/missing.log'
The exception is raised on the next() line rather than during read_lines(). When debugging pipeline stack traces, remember that generator errors surface where consumption occurs.
Quarantining corrupt records inside the generator
An unhandled exception inside a generator halts the stream and terminates downstream processing. Catching syntax errors locally allows the generator to quarantine bad rows and continue streaming.
import io, json

text = '{"event_id": "e1"}\n{"event_id": \n{"event_id": "e3"}\n'
quarantine = []

def safe_events(f):
    for number, line in enumerate(f, start=1):
        try:
            yield json.loads(line)
        except json.JSONDecodeError:
            quarantine.append(number)

print([e["event_id"] for e in safe_events(io.StringIO(text))])
print("bad lines:", quarantine)['e1', 'e3'] bad lines: [2]
The generator successfully delivered events e1 and e3 while recording line 2 for inspection. Production pipelines write quarantined rows to dead-letter storage.
When a list is the right tool
Generators do not support indexing, slicing, or in-place sorting. They have no historical memory of previously yielded items.
gen = (n * n for n in range(5))
try:
    gen[2]
except TypeError as e:
    print("TypeError:", e)

print(sorted(n * n for n in range(5)))TypeError: 'generator' object is not subscriptable [0, 1, 4, 9, 16]
Built-in sorted() works by buffering all items into memory first. If your dataset fits comfortably in RAM and requires random access or multiple passes, a list is the right choice.
Calling list(stream) forces every yielded element into memory at once. On large datasets, this defeats the primary advantage of a generator. Consume elements one by one with a for loop, sum(), or direct batch writes.
Replay: four events through two generators
read_events opens events.ndjson and yields e1 as a parsed dict.
- file
- e1
purchases sees a purchase, so it passes e1 to the loop.
- e1
- purchases
- loop
The loop asks again. e2 is a page_view, so purchases drops it and asks for e3.
- e2
- dropped
- e3
e3 reaches the loop. e4 is read and dropped.
- e3
- loop
The file ends, StopIteration fires and the loop stops: 2 purchases, 208.75.
- done
Four core principles for streaming data:
- yield pauses a function and preserves local state until next() is called.
- Generators keep memory usage flat regardless of total file size on disk.
- A generator is single-pass. Re-running requires calling the function again.
- Chain small generators for extraction, parsing, and filtering without intermediate lists.
Common beginner questions
Is looping over a file with for already lazy?
Yes. A Python file object yields one line at a time from its internal buffer, which is why for line in f is safe on huge files. Wrapping a file object in a custom generator lets you add JSON parsing, type conversion, and row filtering while preserving that single-line memory footprint.
Why not return a list instead?
For small datasets that easily fit in memory, returning a list is often simpler and allows multiple passes. A generator becomes essential when files exceed available worker memory or when you want the ability to terminate processing early without reading the entire dataset.
What is the difference between yield and return?
A return statement completes the function call and hands back a single final result. A yield statement hands back an individual value and pauses execution, allowing the function to produce a continuous sequence of values over time.
What comes next
Generators establish the foundational mental model for data streaming. You will see this same record-by-record processing pattern in chunked file readers, PySpark data streams, and Kafka event consumers. Next, we examine object-oriented programming to structure reusable connectors and pipeline components.
Practice
The exercise provides a sample log file at /data/access.log. Write a generator lines(path) that yields stripped lines one at a time, count the total lines using a for loop, and assign the count to result.
Avoid calling list() on the whole file, as the verification checks will test for it.
Going further: batches from a generator
A generator gives you one item at a time, but databases and APIs like to receive many rows at once. Inserting rows one by one is slow, and loading everything at once defeats the point of a generator. The usual answer is to cut the stream into batches.
The function below takes any iterable and yields lists of up to 4 items. Predict the batch sizes for 10 items.
from itertools import islice

def batches(items, size):
    iterator = iter(items)
    while True:
        batch = list(islice(iterator, size))
        if not batch:
            return
        yield batch

for batch in batches(range(10), 4):
print(batch)[0, 1, 2, 3] [4, 5, 6, 7] [8, 9]
The batches are 4, 4 and 2. The last one is smaller, which is normal: code that sends batches must handle a short final batch. iter() matters here. islice takes the next 4 items from the same iterator each time, so each call continues where the last one stopped.
Predict what happens if you hand the function a generator and loop over it twice.
numbers = (n * n for n in range(3))
print("first pass :", list(numbers))
print("second pass:", list(numbers))first pass : [0, 1, 4] second pass: []
The second pass is empty. A generator is consumed as it is read. If you need the data twice, store it in a list, or create a new generator for the second pass.
Try a new scenario
A file has 1,000,003 lines and you send 100,000 lines per request. How many requests are sent, and how many lines are in the last one?
Open the answer
The answer is '11 3': 11 requests, the last with 3 lines. 10 full batches hold 1,000,000 lines and the 3 leftover lines need an eleventh request. A pipeline that ignores the short final batch silently drops those lines.
Interview: why use a generator instead of returning a list?
A generator produces one item at a time, so memory stays small however big the input is, and work starts before the whole input is read. Use a list when you need the data more than once, need its length, or need random access.
Close the lesson and explain it
Without scrolling up, explain why the batching function keeps one iterator, and why a short last batch must be handled.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this idea
Each page shows the idea moving, then lists problems from easiest. Open one now, or come back when you finish the lesson.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.
- Best 3-day sales windowInterview-style drill: Given daily sales figures, find the 3-day consecutive window with the highest total.Studiointermediatepython15 min
- Find All AnagramsInterview-style drill: Start indices of every anagram of p inside s.Studiointermediatepython14 minLocked
- Find Anagrams WindowInterview-style drill: Same behavior as find_anagrams: start indices of anagram windows.Studiointermediatepython14 minLocked