
Overview
Python became the default for pipelines because it is easy to read and has a library for nearly everything a pipeline touches.
On this page8 sections
The idea
Open any data engineering job listing and Python is on it.
Why does Python show up in every pipeline?
A typical nightly pipeline connects many different systems: it downloads a CSV, calls an external API, queries a database, writes Parquet files to cloud storage, and runs on an automated scheduler.
Each layer is handled by a specialised tool. Python scripts are the layer that connects the rest.
The databases, cloud providers, schedulers, and big-data engines all publish official Python libraries. One language drives all of them, so you do not need to master six different tools.
Python is not the fastest at any one job. It is capable at all of them, which is exactly what a pipeline needs.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Python | A general purpose programming language that reads almost like English |
| Library | Ready-made code you can borrow, such as pandas |
| Interpreted | Python reads and runs your code line by line instead of compiling it first |
| Script | A small program saved in a file |
| SQL | The language for asking questions of a database |
| Library | Ready-made code you can borrow, such as pandas |
Why this exists
Before Python became the industry standard, data teams stitched pipelines together with fragmented tools.
What did teams use before Python?
Each job had its own tool. Handing a pipeline to a new engineer meant handing them four disconnected skills.
Python won by being readable and reviewable, not by being fastest.
| Tool | Fine for | Where it broke |
|---|---|---|
| Drag-and-drop ETL software | Drawing a flow on screen | No git history, no tests, no diff to review |
| Bash scripts | Copying a file between servers | Nested JSON, OAuth and retries turn unreadable |
| Java or Scala | Large distributed systems | 50 lines of boilerplate to download a CSV |
| Python | All of the above, as plain text code | Lives in git, runs in tests, reads like pseudo-code |
With Python, your pipeline becomes plain text in a git repository. A teammate can read every changed line before it goes live, and small automatic tests can run first.
How does one language replace four?
Python is readable, expressive, and provides a library for almost every data system in production.
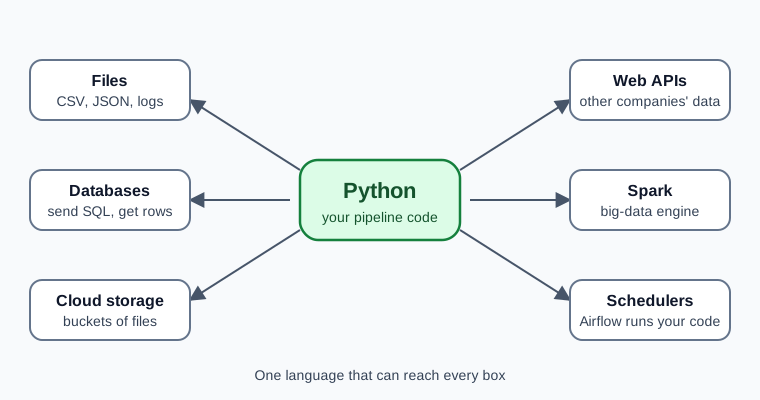
Each arrow represents an established library: the csv module for files, requests for APIs, and PySpark for distributed data.
What does it mean that Python is interpreted?
You do not compile a Python file first. The interpreter reads and executes it line by line.
- pipeline.pyplain text in git
- Python interpreterreads and runs each line
- Resultoutput or a traceback
Because Python is interpreted rather than compiled, you can test code interactively line by line and iterate rapidly.
Is Python too slow for data work?
For a pipeline, most execution time is spent waiting on network downloads, disk I/O, or database queries.
- Your Python scriptwrites the plan
- NumPy, pandas, DuckDB, Polarscompiled C, C++ or Rust
- Sparkruns on the JVM
When you filter 1 million rows with pandas or DuckDB, Python hands the heavy data processing to a precompiled C++ or Rust binary. Python acts as the steering wheel while compiled code runs the engine.
Python code you write yourself runs slower than Java or Rust, and that is fine. For heavy number crunching, libraries delegate work to compiled backends while Python handles the flow.
Python holds the steering wheel. A compiled engine does the heavy lifting.
Where does SQL fit?
Python does not replace SQL; the two split the pipeline workload.
Most pipelines use both. Python moves and fixes data, SQL asks questions of it.
| Job | Better fit | Why |
|---|---|---|
| Download a file, call an API, read a folder | Python | Plain SQL cannot open a network connection or a file |
| Fix a messy field before it is stored | Python | You need real logic and string handling |
| Sum, count and join large tables inside a warehouse | SQL | The warehouse is built for exactly this |
| Run the steps in order, retry failures | Python (plus a scheduler) | Control flow is code, not a query |
Python extracts and stages. SQL transforms and aggregates inside the warehouse.
Use Python to fetch, clean, and stage files. Use SQL once data is stored as tables inside the warehouse.
Which tool would you pick for each job?
Decide first, then read the answer column.
If the job touches the outside world, reach for Python. If it asks a question of a table, reach for SQL.
| The job | Your pick | Why |
|---|---|---|
| Retry a payment API call that returned HTTP 429 | Python | Waiting and retrying is control flow |
| Total paid revenue by city over 20 million rows | SQL | The warehouse aggregates at that size |
| Unzip yesterday's export and rename the file | Python | Plain SQL has no way to touch files |
Real pipelines combine both tools, and the next flow shows how.
What does that split look like for ShopKart?
Each night, ShopKart pulls refund requests from a payment provider's API. Plain SQL cannot do that part.
- Payment APIauth headers, pagination, gzipped JSON, rate limits
- Python extractretries on HTTP 429, checks the schema
- Parquet in cloud storageclean files
- SQL in the warehousejoins 20 million orders to 500,000 customers
SQL has no built-in way to handle HTTP authorization headers, pagination tokens, or retries. Python handles the messy external world, and SQL takes over once data lands as clean tables.
What will this track cover?
Each lesson builds on the last, from one variable to a working ingest pipeline.
A direct path from the first variable to the Python a pipeline uses every day.
| You will learn | So you can |
|---|---|
| Variables, lists and dictionaries | Hold 1 row, and a batch of rows |
| Loops, conditions and functions | Handle every order and reuse your logic |
| Strings, files, CSV and JSON | Read the formats pipelines actually receive |
| APIs and generators | Fetch remote data and stream big files |
| Dates and validation | Trust your timestamps and reject bad rows |
Do not only copy syntax to pass exercises. Keep asking what happens when a value is missing, a type is wrong, or the data grows from 10 orders to 10 million.
Picture this
Let us look at how the exact same analytical question is answered in SQL and in Python.
What does one question look like in SQL and in Python?
Take three ShopKart orders. How much did we earn from the paid ones?
The orders both versions work on.
| id | total | status |
|---|---|---|
| ORD-1 | 120.50 | paid |
| ORD-2 | 45.00 | cancelled |
| ORD-3 | 89.99 | paid |
SELECT SUM(total) FROM orders WHERE status = 'paid';SQL says it in one line, because the database does the looping for you.
How does the same question read in Python?
Python shows each step, which is what you want when data is messy. Predict how many orders the filter keeps and the exact sum.
orders = [
    {"id": "ORD-1", "total": 120.50, "status": "paid"},
    {"id": "ORD-2", "total": 45.00, "status": "cancelled"},
    {"id": "ORD-3", "total": 89.99, "status": "paid"},
]

paid = [o for o in orders if o["status"] == "paid"]
revenue = sum(o["total"] for o in paid)

print(f"Paid orders: {len(paid)}")
print(f"Total revenue: {revenue}")Paid orders: 2 Total revenue: 210.49
Keep the paid orders, add their totals, print 2 lines. You can guess that without having coded before.
How do you read the filter line?
One line did the filtering. Read it from left to right, like a sentence.
paid = [o for o in orders if o["status"] == "paid"] read in pieces.
| Part | Plain meaning |
|---|---|
| [ ... ] | Build a new list |
| o for o in orders | Take each order from orders and call it o |
| if o["status"] == "paid" | Keep it only when its status is paid |
| sum(o["total"] for o in paid) | Add up the total of each kept order |
This shape, a list built from a loop and a condition, appears in almost every pipeline you will write.
Which 2 rules do you need before moving on?
The code above already used both.
- Indentation groups lines. Everything indented under a for or an if belongs to it, usually four spaces.
- print(...) shows a value on screen. When you are unsure what your code did, print the value.
Indentation is how Python knows where a block ends. If a line under for is pushed in by four spaces, it runs on every pass. If it sits back at the left edge, it runs once, after the loop. One wrong space changes the answer, so keep the spacing exact.
print is your flashlight. Add print(total) after a line, run it, and you see the value at that moment. Most beginner bugs are found by printing the value you assumed and finding it is something else.
How do you check what your code did?
Print the value. Here we look at the second order and count the list.
print(orders[1])
print(len(orders)){'id': 'ORD-2', 'total': 45.0, 'status': 'cancelled'}
3Counting starts at 0, so orders[1] is the second order. Notice that 45.00 printed as 45.0.
A small example
Real pipeline datasets frequently arrive with missing values or omitted fields.
What happens when a status was never recorded?
Same 3 orders, but ORD-2 now has no status. Does it land in the paid list or the follow-up list?
orders = [
    {"id": "ORD-1", "total": 120.50, "status": "paid"},
    {"id": "ORD-2", "total": 45.00, "status": None},
    {"id": "ORD-3", "total": 89.99, "status": "paid"},
]

paid = [o for o in orders if o.get("status") == "paid"]
unresolved = [o["id"] for o in orders if o.get("status") is None]

print(f"Paid: {len(paid)}, needs follow-up: {unresolved}")Paid: 2, needs follow-up: ['ORD-2']
None means there is no value here. The code sets ORD-2 aside, so nobody quietly loses it.
What if the key is missing entirely?
Some providers leave the status key out. Direct bracket access demands the key exists.
orders_missing_key = [
    {"id": "ORD-1", "total": 120.50, "status": "paid"},
    {"id": "ORD-2", "total": 45.00},  # 'status' key omitted
]

crash_lookup = [o for o in orders_missing_key if o["status"] == "paid"]Traceback (most recent call last):
File "pipeline.py", line 6, in <module>
crash_lookup = [o for o in orders_missing_key if o["status"] == "paid"]
~^^^^^^^^^^
KeyError: 'status'The last line names the missing key. One incomplete record stops the whole run, and every later order goes unprocessed.
Is a None value the same as a missing key?
No, and the difference decides which lookup is safe.
Checked by running both lookups on each kind of record.
| The record | o["status"] | o.get("status") |
|---|---|---|
| status is None | None | None |
| status key is absent | KeyError: 'status' | None |
| status is "paid" | paid | paid |
Only .get() treats both gaps safely, which is what a messy external feed needs.
How does .get() fix the crash?
.get() returns None when the key is absent, instead of raising KeyError.
safe_paid = [o for o in orders_missing_key if o.get("status") == "paid"]
print(f"Safe paid orders count: {len(safe_paid)}")Safe paid orders count: 1
Both orders were inspected and the script kept running. Plan for the gap before it shows up.
Use o.get("key") when a field can be missing. Use o["key"] only when its absence should stop the job.
What comes with Python out of the box?
The standard library needs no installs, so small scripts run on any server. Here is csv reading the same 3 orders.
import csv
import io

raw = """id,total,status
ORD-1,120.50,paid
ORD-2,45.00,cancelled
ORD-3,89.99,paid"""

rows = list(csv.DictReader(io.StringIO(raw)))
print(len(rows))
print(rows[0])3
{'id': 'ORD-1', 'total': '120.50', 'status': 'paid'}Notice that total came back in quotes. A CSV only holds text, so the number is not a number yet. The next lesson fixes that.
The batteries-included modules a pipeline reaches for first.
| Module | What it does |
|---|---|
| csv | Read and write tabular files |
| json | Parse web payloads |
| datetime | Timezones and calendar math |
| pathlib | Work with files and folders |
| urllib | Make web requests |
Fewer external packages means fewer things to break on a server you do not control. Third-party libraries such as requests and pandas come later, once you know the basics.
Why does readable code matter during an outage?
A failure alert arrives for the nightly inventory job. You open the script and need the cause fast.
- Alert firesinventory job failed
- Open the scriptclean syntax, little boilerplate
- Spot the unhandled Nonein the status field
- Deploy the fixwithin minutes
Readable code is an operational requirement, not a style preference. During an incident, you want the logic to be traceable in minutes, not hours.
How does the whole story replay on 3 orders?
Python reads three ShopKart orders as a list of dictionaries.
- Orders list
A filter keeps the paid ones and sum adds their totals: 2 orders, 210.49.
- Orders list
- Paid filter
- Revenue
ORD-2 arrives with a None status, so it goes to the follow-up list.
- Paid filter
- Follow-up list
A record with no status key would crash o["status"], so we read it with .get().
- Record
- .get()
- Keeps running
Later, SQL in the warehouse aggregates the clean files Python staged.
- Python stages
- SQL aggregates
Four things to remember from this lesson:
- Python wins by connecting everything: files, APIs, databases, clouds and schedulers.
- It stays readable and lives in git, so teammates can review and test it.
- Heavy computation runs in compiled engines, and Python only gives the orders.
- Python moves and fixes data, SQL aggregates it in the warehouse, and .get() keeps one missing field from crashing a run.
Common beginner questions
Do I need to install Python on my computer?
Not for this track. The Python editor runs in your browser tab. Later, when you build pipelines on your own machine, you will install it. The code you write here will work the same there.
Which version of Python should I learn?
Python 3. Python 2 stopped being supported in 2020, and everything here is written for Python 3.
Should I learn Python or SQL first?
Either order works, because you need both. If you want to start with the part that reads like everyday English, begin with SQL. If you want to start with the part that moves data around, begin here. The tracks are independent.
Is Python too slow for big data?
For the code you write yourself, yes, a compiled language would run faster. For the data work, it rarely matters, because Python hands the heavy lifting to engines such as Spark or the warehouse. You write the plan and the engine does the muscle work.
What comes next
Next is the smallest building block of any program: a variable. You will see how Python stores a price, an order id and a quantity, why the type of each one matters, and why the number "49.90" coming out of a CSV file is not yet a number.
Practice
Run the sample to see Python filter and total a list of orders. Then take the exercise: count how many of the same 3 orders have the status paid, print the count, and keep it in a variable called result.
Going further: let the database do the filtering
Python can do almost any job in a pipeline, which tempts beginners to pull everything into Python and filter there. That works on 5 rows and hurts on 5 million. A better habit is to ask the database for only the rows you need.
The program below puts 100,000 orders in a small database and finds the refunded ones in two ways. Predict how many rows travel into Python in each case.
import sqlite3

db = sqlite3.connect(":memory:")
db.execute("CREATE TABLE orders (order_id INTEGER, status TEXT)")
db.executemany(
    "INSERT INTO orders VALUES (?, ?)",
    [(i, "refunded" if i % 100 == 0 else "paid") for i in range(1, 100_001)],
)

everything = db.execute("SELECT order_id, status FROM orders").fetchall()
refunded_a = [row for row in everything if row[1] == "refunded"]

refunded_b = db.execute("SELECT order_id, status FROM orders WHERE status = 'refunded'").fetchall()

print("filter in Python : rows moved =", len(everything), "result =", len(refunded_a))
print("filter in SQL : rows moved =", len(refunded_b), "result =", len(refunded_b))filter in Python : rows moved = 100000 result = 1000 filter in SQL : rows moved = 1000 result = 1000
Both give 1,000 refunded orders. The first moved 100,000 rows to get them. The second moved 1,000. With a real network between Python and a warehouse, that difference is the difference between seconds and minutes, and between a small bill and a large one.
A rule of thumb, not a law: move the question to the data, not the data to the question.
| The job | Better place | Why |
|---|---|---|
| Filter, join, group and sum large tables | SQL, in the database or warehouse | The data stays where it lives and only the answer moves |
| Call an API, read a file, parse messy text | Python | SQL cannot reach outside the database |
| Reshape one small result for a report | Python | The data is small, so flexibility is cheap |
| Decide what runs after what, and retry on failure | Python (an orchestrator) | That is control flow, not data work |
Try a new scenario
You must count, per country, the orders above 1,000 rupees from a 200-million-row warehouse table, then post the 12 country totals to a chat webhook. Which parts are SQL and which are Python?
Work it out, then open the answer
The filter and the per-country count are SQL: they scan 200 million rows and return 12. The webhook call is Python, because SQL cannot make an HTTP request. Python also formats the 12 numbers into a message. Pulling 200 million rows into Python to count them would be slow, memory-hungry and expensive.
Does this mean Python is slow?
No. It means Python is the wrong place for large scans. Python is a good glue language precisely because it sends the heavy work to the right engine and handles everything around it.
Close the lesson and explain it
Without scrolling up, explain why filtering in SQL moved 1,000 rows and filtering in Python moved 100,000, and when Python is still the right tool.
Finished this lesson?
Mark it as read when you could explain it to someone else.