
Overview
.map remaps a Series. .apply walks row by row or column by column. Vectorized comparisons are faster than both.
On this page8 sections
The decision
How many ways can you make a new column?
You have the orders table and you want a new column that says whether each order was paid. Pandas gives you three ways.
Two look at the values one by one in Python. The third hands the whole column to pandas in a single instruction.
Row-by-row code asks a Python function about each order in turn. A vectorized comparison asks pandas once, and pandas answers for the whole column.
Both boxes produce the same column of True and False. What differs is how many times Python gets involved: once per row on the left, once in total on the right.
What do map, apply and vectorized each do?
Vectorized just means done on the whole column at once.
Three levers for a new column.
| Tool | What it does | Example |
|---|---|---|
| map | On 1 column, replaces each value using a dictionary or a function | status.map({"paid": 1}) |
| apply | Runs a function you wrote, down a column or, with axis=1, across each row | df.apply(fn, axis=1) |
| vectorized | A comparison, arithmetic between columns, or a .str method | status == "paid" |
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| apply | Run a function on each row or value |
| map | Replace each value using a lookup or a function |
| Vectorized | One operation applied to a whole column at once |
| Function | A named piece of code you can run again and again |
| Column | One field of a DataFrame |
| Lambda | A tiny function written on one line |
What is at stake
How much slower is a row-by-row column?
On 180 rows you will not notice. On millions of rows the row-by-row version is the one that makes you fetch a coffee while it runs.
Predict: roughly how many times slower is apply with axis=1 than a comparison, on 200,000 rows?
Measured with pandas 2.2.3, the version in this tab, on 200,000 generated orders. Repeat runs gave a gap between 50 and 85 times. Your numbers will differ.
| Way to make the column | Time for 200,000 rows | Compared with a comparison |
|---|---|---|
| order_status == "paid" | about 8 ms | 1x |
| .apply(fn, axis=1) | about 600 ms | about 50 to 85x |
The apply version returned the same answers. It just asked Python 200,000 separate questions to get them.
Same answer, tens of times the work. Speed is the price of row-by-row code.
What else does apply cost you?
It is more code to read and more to get wrong. A lambda you have to squint at is worse than a comparison that says exactly what it does.
A small example: df["order_total"] * 0.18 works on the whole column at once. df["order_total"].apply(lambda x: x * 0.18) gives the same answer but calls a Python function once per row. On 1 million rows, the first takes a blink and the second can take many seconds.
The habit you build now is what keeps later notebooks quick.
Option A vs Option B
Which tool should you reach for first?
From best default to last resort.
The decision table.
| Tool | Works on | Typical use | Verdict |
|---|---|---|---|
| ==, >, +, * on columns | A whole column | Flags and arithmetic | First choice |
| .str.lower(), .str.strip() | A text column | Fix text | First choice |
| np.where(test, a, b) | A whole column | If/else for each row | First choice |
| .map({...}) | 1 column | Translate codes using a lookup | Good for lookups |
| .apply(fn, axis=1) | Each row | Logic that needs Python per row | Last resort |
The top 3 rows cover most of what beginners reach for apply to do. You only need apply when your rule needs a Python function with no pandas equivalent, such as calling another library for each row.
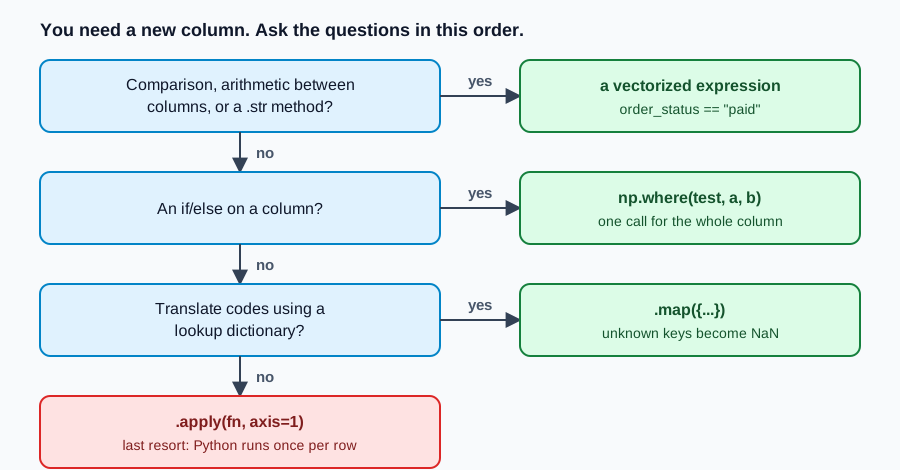
How do you decide in the moment?
Work down the questions in order and stop at the first yes.
A worked comparison
What are we working on?
The first 5 orders, so you can see every row.
Input: df_orders.head(5).
| order_id | order_status | order_total |
|---|---|---|
| ORD-0001 | paid | 612.07 |
| ORD-0002 | refunded | 446.70 |
| ORD-0003 | paid | 1104.32 |
| ORD-0004 | cancelled | 339.90 |
| ORD-0005 | paid | 261.73 |
How do you make the flag the fast way?
Compare the whole column to the word paid, then assign the answer to a new column.
out = df_orders.head(5).copy()
out["is_paid"] = out["order_status"] == "paid"
result = out.loc[:, ["order_id", "order_status", "is_paid"]]The highlighted is_paid column is the one we made. Every other column is untouched and the row count is still 5.
The comparison returns True or False for every row, lined up with the table. We called .copy() first so we edit our own table and not a view of the original.
What does the row-by-row version look like?
It gives the same answer and does far more work for it. Do not write this one.
out = df_orders.head(5).copy()
out["is_paid"] = out.apply(lambda row: row["order_status"] == "paid", axis=1)
print(out["is_paid"].tolist())[True, False, True, False, True]
The same five answers as the fast way. The lambda ran once for each row, which is the slow part at scale.
What do you use for a lookup table?
Say a report wants numeric codes for the status instead of words. That is a lookup, and map is exactly for lookups.
out = df_orders.head(5).copy()
out["status_code"] = out["order_status"].map({"paid": 1, "refunded": 2})
result = out.loc[:, ["order_id", "order_status", "status_code"]]
Output. cancelled was not in the dictionary, so it became NaN (a missing value).
| order_id | order_status | status_code | |
|---|---|---|---|
| 0 | ORD-0001 | paid | 1.0 |
| 1 | ORD-0002 | refunded | 2.0 |
| 2 | ORD-0003 | paid | 1.0 |
| 3 | ORD-0004 | cancelled | NaN |
| 4 | ORD-0005 | paid | 1.0 |
A value that is not a key in the dictionary becomes NaN, not an error. Because the column now holds a missing value, it turns into decimals: 1.0 and 2.0 instead of 1 and 2.
How do you stop a typo in the lookup from hiding?
Count the NaN values after a map. Then either add the missing key or fill on purpose.
Predict: with cancelled mapped to 3, what do the codes look like?
out = df_orders.head(5).copy()
codes = {"paid": 1, "refunded": 2, "cancelled": 3}
out["status_code"] = out["order_status"].map(codes)
print(out["status_code"].isna().sum())
print(out["status_code"].tolist())0 [1, 2, 1, 3, 1]
Zero NaN, and the column stays whole numbers. Check isna().sum() after every map on a real file.
How do you write an if/else column without apply?
People reach for apply to say "if this then that, otherwise something else". NumPy's where does it for the whole column.
NumPy is the number library pandas is built on, and it is already imported as np in this tab.
out = df_orders.head(5).copy()
out["size"] = np.where(out["order_total"] > 500, "big", "small")
result = out.loc[:, ["order_id", "order_total", "size"]]
Output: orders above 500 are big.
| order_id | order_total | size | |
|---|---|---|---|
| 0 | ORD-0001 | 612.07 | big |
| 1 | ORD-0002 | 446.70 | small |
| 2 | ORD-0003 | 1104.32 | big |
| 3 | ORD-0004 | 339.90 | small |
| 4 | ORD-0005 | 261.73 | small |
If you catch yourself typing lambda row, stop and ask whether a comparison, an arithmetic expression, .isin, a .str method or np.where already does the job. In this lesson's exercise the checker rejects code that contains the word apply, even in a comment.
How does the decision replay on the running example?
Start with the question: is each order paid? That is a comparison, so go vectorized.
- Need a paid flag
- comparison
Compare the whole column once. One instruction, five answers.
- status == "paid"
- True, False, True, False, True
Need codes from a lookup? Use map, and count the NaN values after.
- .map({...})
- isna().sum()
Need if/else? Use np.where. Keep apply for what nothing else can do.
- np.where
- apply as last resort
Five things to know from this lesson:
- Vectorized means done on the whole column at once, and it is the default.
- Reach for a comparison, arithmetic or .str first, then np.where, then map, and apply(axis=1) last.
- apply(axis=1) gave the same answer as a comparison but took tens of times longer on 200,000 rows.
- map turns keys it does not know into NaN, so count isna() afterwards.
- Call .copy() before you add the column so the original stays as it was.
Vectorized code is like painting a wall with a roller: one pass covers the whole thing. apply is painting it one brick at a time with a small brush. Fine for a tiny wall, painful for a big one.
Common beginner questions
When is apply actually fine?
When each row needs something pandas cannot express, such as calling an outside library or parsing an odd format that no .str method handles. Try a vectorized version first, and use apply only when you are stuck.
What does axis mean?
axis=0, the default, means down a column. axis=1 means across a row. For a flag like is_paid you should not need either, because you should not need apply.
Is map faster than apply?
For a dictionary lookup on 1 column, map is the clearer and usually the better tool. For an equality flag, neither one is right. Use a comparison.
What comes next
Next you will see where pandas fits next to SQL. Filtering, grouping and joining exist in both, and picking the right one is mostly a question of where your table lives.
Practice
In the exercise you copy df_orders, add an is_paid column with a vectorized comparison, keep 3 columns and 12 rows, and store the result. The paid flag in the worked comparison is the same idea. Remember that the checker looks for the name is_paid and rejects the word apply anywhere in your code.
Going further: check that the fast version agrees with the slow one
The lesson compared apply with vectorized choices. Before you replace a slow apply with a fast column operation, prove they agree on your data, including the awkward rows. This habit is how you refactor without silently changing a report.
The rule: orders over 200 are 'large', otherwise 'small', and a missing amount is 'unknown'. Predict whether the 2 versions agree.
import numpy as np
import pandas as pd

df = pd.DataFrame({"amount": [50.0, 250.0, None, 200.0, 201.0]})

def label(amount):
    if pd.isna(amount):
        return "unknown"
    return "large" if amount > 200 else "small"

slow = df["amount"].apply(label)
fast = pd.Series(
    np.select([df["amount"].isna(), df["amount"] > 200], ["unknown", "large"], default="small"),
    index=df.index,
)

print(slow.tolist())
print(fast.tolist())
print("same:", slow.tolist() == fast.tolist())['small', 'large', 'unknown', 'small', 'large'] ['small', 'large', 'unknown', 'small', 'large'] same: True
They agree, including the boundary (200 is small, 201 is large) and the missing value. np.select reads the conditions in order and uses the first that is true, so the missing check has to come first.
If the NaN test came second, NaN > 200 is False and the missing amount would fall through to 'small'.
| Task | Tool | Why |
|---|---|---|
| Two outcomes | np.where | One condition, 2 values |
| Several ordered rules | np.select | Conditions are checked in order |
| Replace values using a lookup table | Series.map with a dict | Missing keys become NaN, which is visible |
| Genuinely custom logic per row | apply | Slowest, so use it last and keep it correct |
Try a new scenario
Map the country codes IN, US and UK to their names, and see what happens to a code that is not in your table, 'DE'. Is that behaviour good or bad?
Open the answer
The result is ['India', nan, 'United States']: the unknown code becomes a missing value. That is good, because it is visible and countable. Silently keeping 'DE' would mix codes and names in 1 column, and silently using 'Unknown' would hide a gap in your lookup table. Count the missing values after a map as a check.
Interview: when is apply acceptable?
When the logic is genuinely custom per row and cannot be written with column operations, np.where, np.select or map. Keep it correct first, and measure before assuming it is a bottleneck.
Close the lesson and explain it
Without scrolling up, explain why np.select needs its missing-value test first, and how you check that a faster rewrite agrees with the original.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.