
Overview
pd.read_csv, read_excel, and read_json load files into DataFrames. In this tab the frames are already loaded.
On this page8 sections
What you will do
Someone sends you a file called orders.csv and asks a quick question about it. It is not in Python yet, and it is not clear what any of the columns mean.
Before anyone can count paid orders, the file has to be loaded into a table pandas can work with.
Where does every pandas job start?
With a table that is not in Python yet. It is a file somebody sent you.
A CSV is a text file where each line is a row and commas separate the columns. After read_csv, the first line becomes the column names.
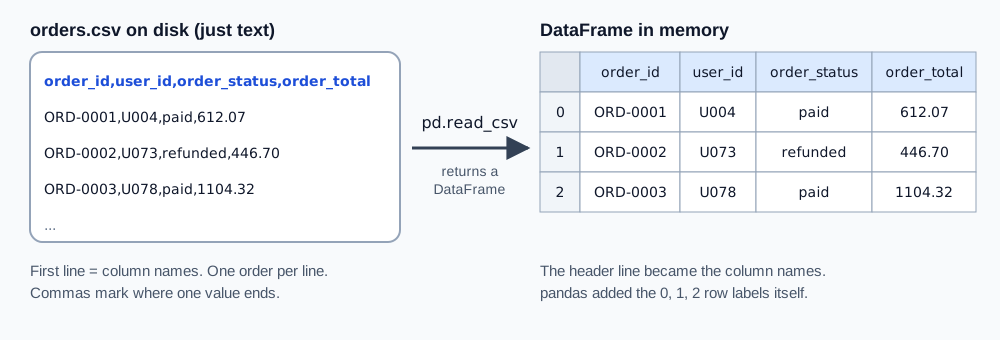
The left side is what you would see opening orders.csv in a text editor. Pandas adds the 0, 1, 2 row labels on its own.
Which reader do you call?
Pandas has one reader per file type. Whichever you call, you get a DataFrame back.
3 file types, one destination.
| Reader | Reads | Options you will reach for | Gives back |
|---|---|---|---|
| pd.read_csv(path) | Text tables: .csv, .tsv | sep, header, dtype, parse_dates, encoding | DataFrame |
| pd.read_json(path) | JSON, row-shaped | orient, lines | DataFrame |
| pd.read_excel(path) | Workbooks: .xlsx (needs the openpyxl package) | sheet_name, header | DataFrame |
JSON is a text format of nested key and value pairs that web services love.
Why does ShopKart get so many kinds of file?
Data never starts inside a clean Python table. Each partner sends what its own system exports.
- Merchant catalog: CSV
- Payment gateway: daily logs
- Logistics: tab-delimited
- Website tracking: JSON
Before you can filter, total or join anything, that text has to become a DataFrame. Loading is where every pipeline begins.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| read_csv | The pandas function that loads a CSV file into a DataFrame |
| CSV | A text file where each line is a row and commas separate columns |
| JSON | A text format for nested data, written with braces and keys |
| dtype | The type of a column, such as number or text |
| Header | The first line that names the columns |
| Encoding | The way characters are stored in a file, such as UTF-8 |
Why this skill
What goes wrong without anyone noticing?
Loading mistakes rarely crash. You just carry the wrong shape into every later step.
Three quiet failures.
| The file has | What you get | The fix |
|---|---|---|
| Semicolons between columns | One giant column | sep=";" |
| A stray word in a number column | The whole column loads as text | na_values, or clean first |
| Dates written as 2026-08-02 | Plain text, not dates | parse_dates |
A loud crash halts the pipeline and pages an engineer. A quiet mistake keeps running and feeds wrong numbers into dashboards for weeks.
A silent wrong load is worse than a crash. Always look at what you loaded.
How the code works
What are the steps of a good load?
The same 4 steps every time, whatever the file.
- Pick the reader for the file type.
- Pass options if the file is not the usual comma-separated shape.
- Look at the shape, the column names and the types before you do anything else.
- Only then start filtering and cleaning.
Why look before cleaning? A load can succeed and still be wrong. If the separator is a semicolon and you used the default comma, pandas happily gives you one column with whole lines inside it. Two seconds of looking at df.shape and df.head() would have caught it.
In this tab the studio already loaded df_orders. You can still practise real reading, because read_csv accepts text in memory: wrap a string in io.StringIO and it behaves like an open file.
What do the options mean?
The first argument is where the data is: a path, a web address, or a text buffer. The options say how to read it.
The options you will use most.
| Option | What it tells pandas | Example |
|---|---|---|
| sep | What separates the columns | sep=";" |
| header | Which line holds the names | header=None |
| dtype | Pin a column to a type | dtype={"order_id": "string"} |
| parse_dates | Turn text into dates | parse_dates=["created_at"] |
| usecols | Keep only these columns | usecols=["order_id"] |
| na_values | Extra tokens that mean missing | na_values=["N/A"] |
| skiprows | Ignore lines at the top | skiprows=2 |
| encoding | How the text was saved | encoding="latin1" |
| chunksize | Read in batches, not all at once | chunksize=50000 |
How does pandas know a column is a number?
A text file has no schema. Pandas samples the values and guesses a type for each column.
Predict: what happens to a column of 101 and 102 when one value is A-7?
import io

print(pd.read_csv(io.StringIO("id\n101\n102\nA-7\n"))["id"].tolist())['101', '102', 'A-7']
One odd value turned the whole column into text. Text takes several times the memory of numbers. In a scheduled job, pin the types yourself with dtype.
Worked examples
What does a good load look like?
We use 3 lines of the orders file as text.
Predict: what shape and what dtype for order_total will read_csv produce?
import io

text = """order_id,user_id,order_status,order_total
ORD-0001,U004,paid,612.07
ORD-0002,U073,refunded,446.70
ORD-0003,U078,paid,1104.32
"""
orders = pd.read_csv(io.StringIO(text))
print("orders shape:", orders.shape)
print("order_total dtype:", orders["order_total"].dtype)
result = ordersorders shape: (3, 4) order_total dtype: float64
result: 3 rows, 4 columns, and the total column came in as a real number.
| order_id | user_id | order_status | order_total | |
|---|---|---|---|---|
| 0 | ORD-0001 | U004 | paid | 612.07 |
| 1 | ORD-0002 | U073 | refunded | 446.70 |
| 2 | ORD-0003 | U078 | paid | 1104.32 |
3 rows, 4 columns, and float64 means pandas saw decimals, so you can add them. That is a good load.
What if the file uses semicolons?
Some systems, especially in countries that write decimals with a comma, separate columns with a semicolon.
Predict: what shape do you get without sep and with sep=";"?
import io

text = """order_id;order_status;order_total
ORD-0001;paid;612.07
ORD-0002;refunded;446.70
"""
wrong = pd.read_csv(io.StringIO(text))
right = pd.read_csv(io.StringIO(text), sep=";")
print("wrong shape and cols:", wrong.shape, wrong.columns.tolist())
print("right shape and cols:", right.shape, right.columns.tolist())wrong shape and cols: (2, 1) ['order_id;order_status;order_total'] right shape and cols: (2, 3) ['order_id', 'order_status', 'order_total']
1 column, and its name is the whole header line. 2 rows of data where you wanted 2 rows by 3 columns.
Pandas looked for commas, found none, and treated each line as one value.
One very wide column means the separator is wrong.
What about tabs and spaces?
Name the separator. A tab is written "\t" and a run of spaces is written "\s+".
import io

print(pd.read_csv(io.StringIO("a\tb\n1\t2\n"), sep="\t").shape)
print(pd.read_csv(io.StringIO("a b\n1 2\n"), sep=r"\s+").shape)(1, 2) (1, 2)
When you are unsure, look at the raw file first, for example with head on the command line, before you write the reader.
How does JSON become rows?
A JSON list of objects with the same keys lines up as rows. Each object is a row and each key is a column.
Predict: how will read_json lay out 2 order objects?
import io

js = '[{"order_id": "ORD-0001", "order_status": "paid"}, {"order_id": "ORD-0002", "order_status": "refunded"}]'
df_js = pd.read_json(io.StringIO(js))
print(df_js)order_id order_status 0 ORD-0001 paid 1 ORD-0002 refunded
What is JSON Lines and how do you read it?
Services often write one JSON document per line, called NDJSON or JSON Lines. Pass lines=True.
Predict: what shape comes back, and what happens if you forget lines=True?
import io

ndjson = '{"order_id": "ORD-0001", "status": "paid"}\n{"order_id": "ORD-0002", "status": "refunded"}\n'
df_ndjson = pd.read_json(io.StringIO(ndjson), lines=True)
print("NDJSON parsed shape:", df_ndjson.shape)NDJSON parsed shape: (2, 2)
Without lines=True, read_json treats the text as one document and stops with ValueError: Trailing data.
How do you inspect a table that is already loaded?
In the studio you inspect what is there. Three small checks tell you most of what you need.
Predict: what columns, shape and order_total dtype does df_orders have?
print("df_orders columns:", df_orders.columns.tolist())
print("df_orders shape:", df_orders.shape)
print("order_total dtype:", df_orders["order_total"].dtype)
result = df_orders.head(5)df_orders columns: ['order_id', 'user_id', 'order_status', 'order_total', 'currency', 'created_at', 'updated_at'] df_orders shape: (180, 7) order_total dtype: float64
The columns say what you can select. The shape says whether all 180 rows came in. float64 means the amounts are real decimals. head(5) is a small peek.
How do you pin types and keep only some columns?
A file may hold 40 columns when you need two. usecols keeps just those, and dtype stops the guessing.
Predict: which dtypes will the pinned table report?
import io

orders_text = """order_id,user_id,order_status,order_total
ORD-0001,U004,paid,612.07
ORD-0002,U073,refunded,446.70
"""
df_pinned = pd.read_csv(
    io.StringIO(orders_text),
    usecols=["order_id", "order_total"],
    dtype={"order_id": "string", "order_total": "float64"},
)
print(df_pinned["order_id"].dtype, df_pinned["order_total"].dtype)string float64
Pinning also guards long ids: an id read as a number can lose digits, so pin it as string.
How do you turn text dates into real dates?
By default created_at is text, so calendar tools fail on it. parse_dates converts it as it loads.
Predict: which of these two reads lets .dt.hour work?
import io

text_dates = "order_id,created_at\nORD-0001,2026-08-02 16:33:28\n"
plain = pd.read_csv(io.StringIO(text_dates))
dated = pd.read_csv(io.StringIO(text_dates), parse_dates=["created_at"])
print(dated["created_at"].dt.hour.iloc[0])
print(plain["created_at"].dt.hour.iloc[0])16 AttributeError: Can only use .dt accessor with datetimelike values
Only the parsed column supports calendar tools such as .dt.hour.
What if missing values are written as N/A or MISSING?
Old systems write missing numbers as words. Unhandled, those words turn the column into text.
import io

text_sentinels = """order_id,order_status,order_total
ORD-101,paid,120.50
ORD-102,pending,N/A
ORD-103,paid,MISSING
"""
df_sentinels = pd.read_csv(io.StringIO(text_sentinels), na_values=["N/A", "MISSING"])
print("na_values null count:\n", df_sentinels.isna().sum())
Predict: how many nulls will order_total report?
na_values null count:
 order_id        0
order_status    0
order_total     2
dtype: int64
Both tokens became real nulls, and order_total is a number column again.
What if the file starts with a banner?
Billing exports often put comment lines above the real header. Skip them with skiprows.
import io

text_with_banner = """# Export Date: 2026-10-09
# Source System: ShopKart Billing
order_id,order_status,order_total
ORD-0001,paid,612.07
ORD-0002,refunded,446.70
"""
df_skipped = pd.read_csv(io.StringIO(text_with_banner), skiprows=2)
print("skipped shape and columns:", df_skipped.shape, df_skipped.columns.tolist())
Predict: which columns survive after skipping the two banner lines?
skipped shape and columns: (2, 3) ['order_id', 'order_status', 'order_total']
What if the file is too big for memory?
chunksize makes read_csv return batches. You total each batch and never hold the whole file.
import io

text = "order_id,order_total\nORD-0001,612.07\nORD-0002,446.70\nORD-0003,1104.32\n"
running_total = 0.0
total_rows = 0
for chunk in pd.read_csv(io.StringIO(text), chunksize=2):
    total_rows += len(chunk)
    running_total += chunk["order_total"].sum()
print("chunked total rows:", total_rows, "total sum:", round(running_total, 2))
Predict: how many rows and what sum come back from 2-row chunks?
chunked total rows: 3 total sum: 2163.09
The same 3 rows and the same total as the full read, in 2 batches.
What if the text was saved in the wrong encoding?
Older exports often use Latin-1 instead of UTF-8. An accented letter then stops the read.
import io

raw = "name\nJosé\n".encode("latin1")
print(pd.read_csv(io.BytesIO(raw), encoding="latin1"))name 0 José
Without encoding="latin1", the same bytes raise UnicodeDecodeError, because byte 0xe9 is not valid UTF-8.
What do you check after every load?
A read that raises no error is not a read that returned the right data.
- The row count is not zero, and matches what you expect: df.shape.
- The columns you need are in df.columns.
- A key column has no gaps: df["order_id"].isna().sum() == 0.
- The types look right: df.dtypes.
Each check catches a different silent failure. A zero row count means the path or filter was wrong. A missing column usually means a header typo or the wrong separator. A gap in a key column means broken rows. A date stored as object, which is pandas for text, means date maths will fail later.
A wrong separator, a wrong header line or the wrong text encoding will not always raise an error. They can give you a table of the wrong shape. If the column count is not what you expect, or 1 column holds whole lines of text, stop and fix the read_csv options before anything else.
How does a whole load replay?
Pick the reader. The file is semicolon-separated text, so read_csv.
- orders.csv
- pd.read_csv
Pass options that match the file: sep, dtype, parse_dates, na_values.
- sep=";"
- dtype
- parse_dates
Check shape, columns and dtypes before anything else.
- df.shape
- df.columns
- df.dtypes
Only now filter and clean.
- Clean table
Five things to know from this lesson:
- Each file type has one reader, and each returns a DataFrame.
- A wrong sep gives one giant column. Check the shape to catch it.
- Pin types with dtype, dates with parse_dates, and missing tokens with na_values.
- Use usecols, skiprows and chunksize to read only what you need.
- After every load, check rows, columns, gaps and types before moving on.
After every load, look at the shape, the column names and the dtypes before you do anything else. Most bad numbers later trace back to a read that quietly guessed wrong. read_csv on an io.StringIO text also works in this tab.
Common beginner questions
Why can't I read a real file in this tab?
The editor runs in your browser and has no folder of your files to open. You can still practise the reading itself with io.StringIO as above. On your laptop, the first line of a script is usually pd.read_csv with the file's path.
Should I use CSV or Excel for a data pipeline?
CSV when you have the choice. It is plain text, so it is easy to look at, compare and store. Excel files can hide several sheets, merged cells and formatting that get in the way. Use read_excel when that is what the source sends.
Will read_json always give a clean table?
Only when the JSON is already row-shaped, meaning a list of objects with the same keys. Nested objects arrive as one cell holding a whole dictionary and need to be flattened. The PySpark track covers doing that at a larger scale.
What comes next
Once the table is loaded, the next lesson is about cleaning it: blank cells, numbers stored as text, and words spelled in different ways.
Practice
The exercise asks you to print the column names of df_orders as a Python list using df_orders.columns.tolist() and keep the first 5 rows in result using df_orders.head(5). Make sure the grid ends up with exactly 5 rows.
Going further: a zip code is text, not a number
pandas guesses a type for each column while it reads. For identifiers that look like numbers (zip codes, phone numbers, product codes) the guess is wrong, and the damage is silent. Predict what happens to the leading zero.
import io
import pandas as pd

csv = "customer,zip\nAsha,02134\nBen,10001\n"

guessed = pd.read_csv(io.StringIO(csv))
as_text = pd.read_csv(io.StringIO(csv), dtype={"zip": str})

print(guessed["zip"].tolist())
print(as_text["zip"].tolist())[2134, 10001] ['02134', '10001']
The guessed column became the numbers 2134 and 10001. The leading zero is gone, and it cannot be recovered from the number alone. Declaring dtype={'zip': str} keeps the original text.
A second habit: peek before you load. nrows reads only the first rows, so you can inspect columns and types on a huge file in a moment.
import io
import pandas as pd

csv = "id,amount\n1,10\n2,20\n3,30\n4,40\n"
print(pd.read_csv(io.StringIO(csv), nrows=2))id amount 0 1 10 1 2 20
Try a new scenario
A file has a column order_id with values such as 000123 and 000124, and a column amount that sometimes contains 'N/A'. Which read_csv arguments protect you, and what does the amount column become?
Open the answer
dtype keeps the ids as text and na_values tells pandas that 'N/A' means missing. The result is ['000123', '000124'] [10.5, nan]: the ids keep their zeros and amount stays a number column with one missing value (nan). Without na_values the whole amount column would become text because of the single 'N/A'.
Why read only some columns?
Fewer columns means less memory and faster loading. With a wide file, usecols can turn a failing load into a quick one.
Close the lesson and explain it
Without scrolling up, explain why an identifier should be read as text, and what nrows is for.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.