
Overview
Filter, group, and join exist in both languages. Pandas runs in Python memory. SQL runs in the warehouse.
On this page8 sections
The decision
Pandas or SQL for the same question?
A file lands on your desk and you must answer a question about it, like how many orders were paid.
Pandas and SQL both work on tables, and the verbs are nearly the same. What differs is where the table lives.
On the left, you and the table share one machine and one process. On the right, the table sits in a warehouse and only your question and the answer travel.
Read the boxes as two answers to one question: who holds the data? RAM is the working memory of a computer, the fast but limited space where a running program keeps what it uses.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| SQL | A language for asking a database questions |
| RAM | The fast memory your computer uses while a program runs |
| Chunk | A slice of a big file read at a time |
| Database | A program that stores tables and answers queries |
| Query | A question written for a database |
| Scale | How much data you are dealing with |
What is at stake
What goes wrong if you choose badly?
You lose an afternoon, and sometimes the whole job.
Both mistakes cost an afternoon. Neither one raises a helpful error early.
| Wrong choice | What happens |
|---|---|
| SQL on a CSV nobody loaded into a database | There is nothing to query |
| Pulling years of warehouse orders into pandas | Your program runs out of memory before it finishes |
When does pandas run out of room?
Everything pandas holds sits in RAM. Take the orders table repeated up to 1 million rows. As a CSV file it is about 70 MB. Loaded into pandas, it takes more than that.
Measured on the orders table repeated to 1 million rows. The 100 million row line is that measurement scaled by 100, an estimate. Real data has different text lengths, and sorting or grouping adds temporary copies.
| Rows of orders | In memory, str text (pandas 3) | In memory, object text (pandas 2, this tab) |
|---|---|---|
| 1 million | about 115 MB | about 220 MB |
| 100 million | about 11 GB | about 22 GB |
A laptop with 16 GB of RAM handles the first row easily. The second row is where a warehouse earns its place.
What can you do when a file is bigger than your RAM?
You have three moves, from cheapest to biggest:
- Keep only the columns you need with usecols.
- Read the file in batches with chunksize, as in the loading lesson.
- Load it into a warehouse, or use PySpark, and let a bigger system do the work.
Here is why the first move helps. A file with 40 columns where you need 5 costs you 8 times the memory you need. usecols=["order_id", "order_total"] tells pandas to skip the other columns while reading, so they never enter memory.
The second move works because chunksize hands you the file in slices, say 100,000 rows at a time. You process one slice, keep only the small result (a running total, for example), and let the slice go before the next one arrives.
The third move is for when even that is too slow or too awkward. A warehouse or Spark spreads the file across many machines, so no single computer needs to hold all of it.
How does a real company use both?
Finance asks questions of the warehouse with SQL, because the data is large, shared and already there.
Then a vendor emails a CSV that was never in the warehouse. Cleaning and checking it is a pandas job. The last step writes the clean table into the warehouse for everyone else.
Files arrive on the pandas side. Once they are cleaned and loaded, the shared copy is queried with SQL.
Most data jobs use both tools, one after the other. You pick a side for this step, not for life.
How do you decide in the moment?
Ask where the table is today.
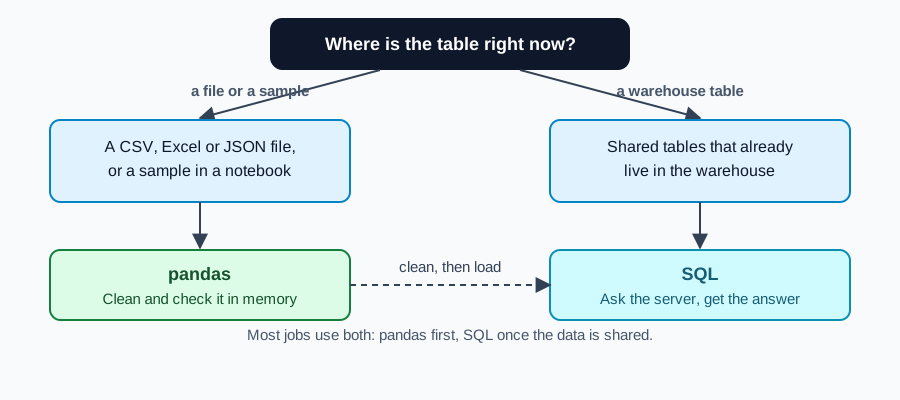
A file on your disk puts you on the pandas side. A table already in the warehouse puts you on the SQL side. The dashed arrow is the common case: clean in pandas, load, then query with SQL.
Option A vs Option B
Which tool for which situation?
A rule of thumb, not a law. When in doubt, ask where the data lives right now.
Five situations.
| Situation | Reach for |
|---|---|
| A vendor CSV that is not in the warehouse yet | pandas |
| Exploring a sample in a notebook | pandas |
| Years of orders shared by the whole company | SQL |
| A number that must match the finance dashboard | SQL, on the official table |
| Cleaning odd text before loading a table | pandas, then load |
When is pandas the right call?
Use pandas when the data is a file or small enough to hold in memory, when you explore in a notebook, or when you need Python-only tricks like fixing messy text.
Do not make it the long-term home of data many people share. Every person would end up with their own copy.
When is SQL the right call?
Use SQL when the data already lives in a warehouse, when the table is far bigger than your laptop could hold, or when your numbers must match the official ones.
Do not use it for a one-off look at a file that is not in a database yet. Setting one up costs more than the question deserves.
Do the moves line up?
One to one, so SQL you already know carries over.
The same 5 jobs in both languages. You will learn each pandas version in its own lesson.
| Job | SQL | pandas |
|---|---|---|
| Keep matching rows | WHERE order_status = 'paid' | df[df['order_status'] == 'paid'] |
| Pick columns | SELECT order_id, order_total | df[['order_id', 'order_total']] |
| Group and add up | GROUP BY order_status | df.groupby('order_status') |
| Combine 2 tables | JOIN ... ON order_id | df.merge(other, on='order_id') |
| Limit the rows | LIMIT 10 | df.head(10) |
A worked comparison
Which paid orders are worth more than 500?
One question, asked both ways. These are the first 5 rows of the orders table.
df_orders, first 5 rows, 3 columns.
| order_id | order_status | order_total |
|---|---|---|
| ORD-0001 | paid | 612.07 |
| ORD-0002 | refunded | 446.70 |
| ORD-0003 | paid | 1104.32 |
| ORD-0004 | cancelled | 339.90 |
| ORD-0005 | paid | 261.73 |
SELECT order_id, order_status, order_total
FROM orders
WHERE order_status = 'paid'
AND order_total > 500;big_paid = (df_orders["order_status"] == "paid") & (df_orders["order_total"] > 500)
result = df_orders.loc[big_paid, ["order_id", "order_status", "order_total"]]Both keep the rows where the two conditions are true. In the first 5 rows that is ORD-0001 and ORD-0003.
Across all 180 orders, 38 rows pass. These are the first three.
result.head(3). Across all 180 orders, 38 rows pass. The left column is the index, so the skipped numbers show the dropped rows.
| order_id | order_status | order_total | |
|---|---|---|---|
| 0 | ORD-0001 | paid | 612.07 |
| 2 | ORD-0003 | paid | 1104.32 |
| 14 | ORD-0015 | paid | 581.04 |
The pandas line does the work in Python, on the copy in memory. The SQL does it on the server. We checked the SQL against the same 180 orders, and it returned the same 38 rows.
WHERE becomes a True and False mask. The answer is the same.
And the question we started with: how many orders were paid?
A count is the smallest version of the same idea. True counts as 1, so sum() on a mask counts the matching rows.
paid_count = (df_orders["order_status"] == "paid").sum()
print(paid_count)93
SELECT COUNT(*)
FROM orders
WHERE order_status = 'paid';
Both say 93. Pandas counted in your memory, and SQL counted on the server.
What does grouping look like in both?
How many orders and how much money per status? Do not worry about the agg syntax yet, a whole lesson on groupby comes later.
result = (
    df_orders.groupby("order_status", as_index=False)
    .agg(orders=("order_id", "count"), total=("order_total", "sum"))
)
1 row per status, which is what GROUP BY order_status gives you in SQL.
| order_status | orders | total |
|---|---|---|
| cancelled | 30 | 11248.61 |
| paid | 93 | 43606.63 |
| pending | 29 | 14478.51 |
| refunded | 28 | 14082.40 |
The SQL idea you already know has a pandas name. The same grouped totals come back from the SQL.
Why can't I just type that SQL in this tab?
df_orders lives in the editor's memory. There is no database for a SQL string to reach.
Think of it like a recipe card and a kitchen. A SQL string is only text, like a recipe. It needs an engine, a database, to cook it. In this tab the only thing alive is your DataFrame, so you ask pandas directly: filter it with a mask, or group it with groupby.
df_orders lives in the editor's memory, so there is nothing for read_sql or a connection string to talk to. Filter the frame you already have. The SQL in this lesson is there so you can compare, not to be typed into the Python editor.
How does the decision replay on the running example?
The question: which paid orders are above 500? First ask where the table is.
- df_orders
- in memory
It is in Python's memory, so use pandas. Build a mask from two conditions.
- status == "paid"
- total > 500
In a warehouse the same question is a WHERE clause with AND.
- WHERE ... AND ...
- server
Both return the same 38 rows. Next, clean files in pandas, load them, and let everyone use SQL.
- 38 rows
- clean, load, query
Five things to know from this lesson:
- Pandas and SQL share the same verbs. The difference is where the table lives.
- Pandas holds the table in your RAM. SQL holds it on a server and sends back answers.
- WHERE becomes a mask, GROUP BY becomes groupby, JOIN becomes merge.
- Pandas for files and notebooks, SQL for big shared tables, and both in one flow.
- Ask where the data lives right now, and pick for this step.
WHERE turns into a True/False mask, GROUP BY into groupby, JOIN into merge. If you already know SQL you know the moves, you only need the new spelling. Pick by where the table lives.
Common beginner questions
If I know SQL, why learn pandas at all?
Because a lot of data never starts in a warehouse. Vendor files, exports from an API and quick checks in a notebook are all Python-side work. Pandas is how you do table work there.
Can pandas replace SQL?
Not for big, shared tables. A warehouse lets many people query one copy without each of them loading all of it into memory. That is the job SQL is built for.
Is df[mask] exactly the same as WHERE?
For a simple filter, yes, both keep the matching rows. A database can also use indexes and stored layout to skip data it does not need to read. Pandas has already loaded everything, so it checks every row it holds.
What comes next
That ends the cleaning and filtering module. The next module builds new columns, groups rows and joins tables. The SQL track on this site goes deeper on the warehouse side if you want to see it from there.
Practice
In the exercise you filter df_orders to paid orders, keep 3 columns, and keep at most 10 rows. It is the mask idea from the worked comparison, with a row limit on the end. Run the sample first and look at the shape it prints.
Going further: the same question in both tools, and where NULL differs
pandas and SQL answer the same questions, and they can be run side by side on the same data. DuckDB can even query a DataFrame directly, which makes it a good way to check one against the other. There is one place they disagree by default: a missing value in the grouping column.
Predict how many groups each tool returns for a region column that has a missing value.
import duckdb
import pandas as pd

df = pd.DataFrame({"region": ["N", "S", None, "N"], "amount": [10, 20, 30, 40]})

print(df.groupby("region")["amount"].sum())
print(df.groupby("region", dropna=False)["amount"].sum())
print(duckdb.sql("SELECT region, SUM(amount) AS amount FROM df GROUP BY region ORDER BY region NULLS LAST").df())region N 50 S 20 Name: amount, dtype: int64 region N 50 S 20 NaN 30 Name: amount, dtype: int64 region amount 0 N 50.0 1 S 20.0 2 NaN 30.0
pandas dropped the row with the missing region by default, so 30 vanished from the totals. SQL keeps the missing region as its own group. dropna=False makes pandas behave like SQL. Neither is wrong, but a total that silently loses 30 is a reconciliation bug waiting to happen.
| Topic | pandas | SQL |
|---|---|---|
| Missing group key | Dropped by default (dropna=True) | Kept as a NULL group |
| Data size | Must fit in memory | Engine can scan data larger than memory |
| Best for | Reshaping, custom Python logic, small to medium data | Filtering, joining and aggregating large tables |
Try a new scenario
Your pandas report shows a revenue total of 70, and the SQL report on the same data shows 100. Where do you look first?
Work it out, then open the answer
Look for rows with a missing grouping key. A default groupby drops them and SQL keeps them, so the difference of 30 is probably exactly those rows. Check df['region'].isna().sum() and the amount in those rows, then decide whether the missing region should be its own 'unknown' group in both reports.
Interview: pandas or SQL for a join of two large tables?
SQL in a warehouse or DuckDB, because the engine can handle data bigger than memory and optimise the join. pandas is fine when both tables fit comfortably in memory and you need custom Python logic afterwards.
Close the lesson and explain it
Without scrolling up, explain how a groupby and a GROUP BY can return different totals from the same data.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.