
Overview
Filtering answers the question, which rows do I need? Use boolean masks, isin, and query to keep the rows that belong in the next step.
On this page8 sections
The table we keep using
What are we filtering?
Almost every question about data begins with "only the ones where...". Only paid orders, only the big ones, only last week.
That is filtering, the pandas version of a SQL WHERE clause. These 8 orders are the first 8 rows of df_orders.
small = df_orders.head(8)
result = small.loc[:, ["order_id", "order_status", "order_total"]]
small: statuses are mixed, and totals run from 261.73 to 1104.32.
| order_id | order_status | order_total | |
|---|---|---|---|
| 0 | ORD-0001 | paid | 612.07 |
| 1 | ORD-0002 | refunded | 446.70 |
| 2 | ORD-0003 | paid | 1104.32 |
| 3 | ORD-0004 | cancelled | 339.90 |
| 4 | ORD-0005 | paid | 261.73 |
| 5 | ORD-0006 | paid | 431.34 |
| 6 | ORD-0007 | paid | 396.72 |
| 7 | ORD-0008 | paid | 366.08 |
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Filter | Keep only the rows you want |
| Boolean mask | A column of True and False values that says which rows to keep |
| Condition | A test such as amount > 400 |
| & | And. Both conditions must be true |
| | | Or. At least one condition must be true |
| Row | One record, such as one order |
What we need from it
Which paid orders were above 400?
With 8 rows you could read down the list and circle them. With 180, or 18 million, you need the computer to do it.
So you have to say exactly what you mean: first a test for every row, then keep the rows that pass.
- Test every row: paid?
- Mask of True and False
- Keep the True rows
The test is a yes or no question. Boolean just means a value that is True or False.
What is a boolean mask?
The answers, one True or False per row and in the same order as the table, form a boolean mask.
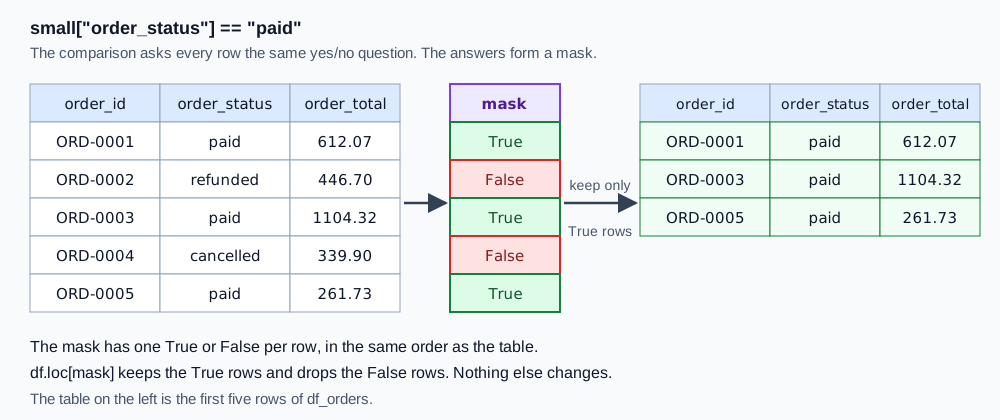
Follow the picture left to right. The comparison fills the middle column. Then .loc[mask] keeps the True rows and discards the rest.
A filter is two moves: build a mask, then keep the True rows.
The kept rows keep their original labels (0, 2, 4), which is why you sometimes see gaps in the index.
Trace it step by step
Step 1: how do you build the mask?
Predict: how many of the 8 rows have order_status equal to "paid"?
mask = small["order_status"] == "paid"
print(mask)
print(mask.sum())0 True 1 False 2 True 3 False 4 True 5 True 6 True 7 True Name: order_status, dtype: bool 6
Eight answers for 8 rows, and six are True. Counting the Trues with sum() is a quick way to check a filter before you apply it.
Step 2: how do you keep the True rows?
Put the mask before the comma in .loc, and the columns you want after it.
result = small.loc[mask, ["order_id", "order_status", "order_total"]]Output: the two non-paid rows (labels 1 and 3) are gone.
| order_id | order_status | order_total | |
|---|---|---|---|
| 0 | ORD-0001 | paid | 612.07 |
| 2 | ORD-0003 | paid | 1104.32 |
| 4 | ORD-0005 | paid | 261.73 |
| 5 | ORD-0006 | paid | 431.34 |
| 6 | ORD-0007 | paid | 396.72 |
| 7 | ORD-0008 | paid | 366.08 |
Keep an id column like order_id in the output so you can always trace a row back to where it came from.
Step 3: how do you combine two conditions?
The real question is paid and above 400. Use & for and, | for or, and ~ for not. Put each condition in its own parentheses.
mask = (small["order_status"] == "paid") & (small["order_total"] > 400)
result = small.loc[mask, ["order_id", "order_status", "order_total"]]
Output: 3 rows pass both tests.
| order_id | order_status | order_total | |
|---|---|---|---|
| 0 | ORD-0001 | paid | 612.07 |
| 2 | ORD-0003 | paid | 1104.32 |
| 5 | ORD-0006 | paid | 431.34 |
Six of the 8 orders are paid, and four are above 400. Three sit in both circles. ORD-0004 (cancelled, 339.90) is in neither, so it is not drawn.
A & keeps the overlap in the middle. An | would keep everything in either circle. ORD-0002 is over 400 but refunded, so it drops out of the &.
Why can't I write and instead of &?
Python's and asks one yes or no question about the whole column. A column holds many answers, so pandas stops.
A column of 1,000 orders gives 1,000 True or False answers. Python's and needs just one. Is the whole column True? Only some of it. Pandas refuses to guess. The & symbol works row by row instead, so you get 1,000 answers back, one per order, which is exactly what a filter needs.
Python's words and and or do not work on a whole column, because pandas cannot turn a column of True and False into one single answer. It stops with a ValueError saying the truth value of a Series is ambiguous. The symbols & and | do the job. They also bind more tightly than == and >, so without parentheses around each condition you get a confusing error.
Step 4: how do you test against a list of values?
Suppose you want paid or refunded. You could chain two comparisons with |. isin is shorter and reads like SQL's IN.
mask = small["order_status"].isin(["paid", "refunded"])
result = small.loc[mask, ["order_id", "order_status", "order_total"]]
Output: 7 rows. Only the cancelled ORD-0004 is excluded.
| order_id | order_status | order_total | |
|---|---|---|---|
| 0 | ORD-0001 | paid | 612.07 |
| 1 | ORD-0002 | refunded | 446.70 |
| 2 | ORD-0003 | paid | 1104.32 |
| 4 | ORD-0005 | paid | 261.73 |
| 5 | ORD-0006 | paid | 431.34 |
| 6 | ORD-0007 | paid | 396.72 |
| 7 | ORD-0008 | paid | 366.08 |
Put a ~ in front to flip it: ~small["order_status"].isin(["cancelled", "pending"]) keeps everything except those two statuses.
Same table, next cut
Which other filters have a SQL twin?
Here are more filters on the same 8 rows, each next to its SQL cousin.
Each pandas filter produces a mask, and the SQL equivalent is a WHERE condition.
| Question | pandas | SQL |
|---|---|---|
| Exactly paid | small['order_status'] == 'paid' | WHERE order_status = 'paid' |
| One of a list | small['order_status'].isin(['paid', 'refunded']) | WHERE order_status IN ('paid', 'refunded') |
| In a number range | small['order_total'].between(300, 450) | WHERE order_total BETWEEN 300 AND 450 |
| Not in a list | ~small['order_status'].isin(['cancelled']) | WHERE order_status NOT IN ('cancelled') |
| Missing / not missing | small['order_total'].isna() / .notna() | IS NULL / IS NOT NULL |
| Text starts with | small['order_id'].str.startswith('ORD-000') | WHERE order_id LIKE 'ORD-000%' |
If you can write the SQL WHERE, you can write the pandas mask.
Is between inclusive?
Yes, at both ends. Predict: which orders have a total from 300 to 450?
mask = small["order_total"].between(300, 450)
print(small.loc[mask, "order_id"].tolist())['ORD-0002', 'ORD-0004', 'ORD-0006', 'ORD-0007', 'ORD-0008']
Five of the 8 rows pass. ORD-0001 and ORD-0003 are above the range, and ORD-0005 is below it.
Can I write the filter as a string?
Yes. query() reads a string, so inside it you can write and and or.
result = small.query("order_total > 400 and order_status == 'paid'")[["order_id", "order_total"]]Output: the same 3 rows as the & version.
| order_id | order_total | |
|---|---|---|
| 0 | ORD-0001 | 612.07 |
| 2 | ORD-0003 | 1104.32 |
| 5 | ORD-0006 | 431.34 |
The bracket version with & is what you will see most in real code, so learn that one first.
What happens to a missing value in a filter?
A comparison with a missing value is False, so the row quietly vanishes. Blank out one total and count again.
Predict: how many totals are above 400 when ORD-0002 has no total?
gappy = small.copy()
gappy.loc[1, "order_total"] = None
print((small["order_total"] > 400).sum())
print((gappy["order_total"] > 400).sum())
print(gappy.loc[gappy["order_total"].isna(), "order_id"].tolist())4 3 ['ORD-0002']
The row dropped without any error. If those rows matter, test for them on purpose with isna() instead of letting them vanish.
Does filtering sort the rows?
No. Surviving rows stay in their original order, and df_orders is not in date order to begin with.
Predict: are the first 3 rows of df_orders also the three earliest orders?
print(df_orders.head(3).index.tolist())
print(df_orders.sort_values("created_at").head(3).index.tolist())[0, 1, 2] [97, 31, 115]
They are different rows. If "the first 10" is supposed to mean "the 10 earliest orders", sort by the date column before you take head(10).
How does the whole filter replay?
Ask a yes or no question of every row. That makes the mask.
- status == "paid"
- mask of 8
Add the second condition. Each one goes in its own parentheses, joined with &.
- (paid) & (total > 400)
- mask
Hand the mask to .loc with the columns you want.
- .loc[mask, cols]
- 3 rows
The kept rows carry their old labels 0, 2 and 5. Reset the index if you want a fresh count.
- labels 0, 2, 5
- reset_index(drop=True)
Five things to know from this lesson:
- A comparison makes a boolean mask. .loc[mask, columns] keeps the True rows.
- Join conditions with &, | and ~, each condition in its own parentheses.
- Use isin for a list of values, between for a range, and query for a string version.
- A missing value in a comparison counts as False, so check with isna().
- Filtering never sorts, and it returns a new table without changing the original.
Every pandas filter maps to a WHERE condition. == is =, isin is IN, between is BETWEEN, & is AND, | is OR and ~ is NOT. If you can write the SQL, you can write the pandas.
Every condition goes in its own parentheses, and you join them with &, | and ~, never and, or, not. Forgetting the parentheses is the error you will hit first. Filtering returns a new table and leaves the original alone.
Common beginner questions
Why do I need parentheses around each condition?
Because & and | are evaluated before == and >. Without parentheses pandas would try to combine the pieces in the wrong order. Writing (a) & (b) is a habit worth building from day one.
Does filtering change the original DataFrame?
No. df.loc[mask] gives back a new DataFrame and leaves df as it was. If you want to edit the result afterwards, call .copy() first so you are working on your own copy.
Why does my result's index have gaps?
Because the kept rows carry their original labels with them. If you want a fresh 0, 1, 2 count, add .reset_index(drop=True) at the end.
What comes next
Now that you can choose rows, the next lesson is about adding a new column to a table. It compares map, apply, and the faster way that avoids both.
Practice
In the exercise you filter df_orders to orders whose status is paid or refunded, keep 3 columns, and return the full filtered set with no head. The isin step above is the tool for it. Check that your code actually uses it, then assign the whole table to result.
Going further: text filters and missing values
Filtering text columns has a trap that numeric filters do not: a missing value is not a string, so a string test on it gives neither True nor False.
Predict what str.contains does with the missing city, and what a '.' in the pattern does. (The output below was produced with pandas 3; older versions show a missing marker instead of False for the missing city.)
import pandas as pd

df = pd.DataFrame({"city": ["New Delhi", "Delhi NCR", None, "Pune"], "id": [1, 2, 3, 4]})

mask = df["city"].str.contains("Delhi")
print(mask.tolist())
print(df[df["city"].str.contains("Delhi", na=False)]["id"].tolist())[True, True, False, False] [1, 2]
What you see for row 3 depends on your pandas version. Older versions, and columns stored as plain objects, return a missing marker (NaN) in the mask, and using that mask to filter then fails or misbehaves.
Newer versions with the string type return False here. Passing na=False says 'a missing city does not match', and gives the same clean True and False mask and the ids 1 and 2 everywhere.
The second trap: str.contains treats its pattern as a regular expression by default.
import pandas as pd

codes = pd.Series(["v1.2", "v1x2", "v1.2.1"])
print(codes.str.contains("1.2").tolist())
print(codes.str.contains("1.2", regex=False).tolist())
print(codes.str.contains(r"1\.2").tolist())[True, True, True] [True, False, True] [True, False, True]
With the default, the dot matches any character, so 'v1x2' matches. regex=False compares plain text, and escaping the dot (1\.2) makes the regex strict. Use regex=False unless you really need a pattern.
Try a new scenario
Keep the rows where the email ends in '@shop.com', treating missing emails as non-matching. Which method is clearest, and does it need a regex?
Open the answer
str.endswith with na=False needs no regex, so there are no special characters to worry about. The kept emails are ['[email protected]', '[email protected]']. endswith and startswith say what you mean, and they cannot be fooled by a dot or a plus sign in the text.
Why do you need parentheses around each condition when combining filters?
The & and | operators bind more tightly than comparisons, so df.a > 1 & df.b < 5 is read in an unexpected order and fails. Writing (df.a > 1) & (df.b < 5) gives the order you intend.
Close the lesson and explain it
Without scrolling up, explain what na=False does in a text filter and why regex=False is often the safer choice.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.
- Conditional column without applyInterview-style drill: Create a price tier column from rules in a vectorized way, handling missing prices.Studiobeginnerpandas10 min
- List column to rowsInterview-style drill: Turn a comma-separated string column into one trimmed row per value.Studiobeginnerpandas10 min