
Overview
Pandas is a Python library for tables. A DataFrame is the table. A Series is 1 column.
On this page8 sections
The idea
What does a morning at ShopKart look like?
A file lands with 180 online orders. Each has an id, a customer, a status like paid or cancelled, and a total.
Your manager wants the same cleaned-up version every morning, without anyone clicking through it by hand.
- Raw orders file
- Your pandas code
- Clean table
Pandas is a Python library, a bundle of ready-made code you borrow. You describe what to do to a table, and the computer repeats it.
What are a DataFrame and a Series?
Two words come up in every pandas lesson. This is the whole vocabulary you need to start.
3 words, one table.
| Word | What it is | In the orders file |
|---|---|---|
| DataFrame | A whole table: rows down, named columns across | df_orders, 180 rows by 7 columns |
| Series | 1 column of a DataFrame | df_orders["order_status"] |
| Index | A label for each row, 0, 1, 2 by default | The grey numbers down the left side |
A DataFrame is the table. A Series is 1 column. The index is the row labels.
Why does ShopKart need this every day?
Thousands of purchases land every minute, each with a customer id, an amount, a discount code and timestamps.
- Midnight: the sales day ends
- Scheduled job copies order files
- Python worker runs pandas
- Clean names, add tax, flag fraud
An analyst can eyeball 50 rows. A pipeline cannot. Pandas does the cleanup in a script that runs unattended.
This track assumes you finished Core Python. If lists, loops and functions still feel new, go through that track first and come back.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| pandas | A Python library for working with tables of data |
| DataFrame | A table with rows and named columns |
| Series | One column of a DataFrame |
| Library | Ready-made code you can borrow |
| Row | One record, such as one order |
| Column | One field, such as the amount |
Why this exists
What does a plain Python total look like?
Say the orders arrive as dictionaries and you want the total of everything paid. You write the loop yourself.
orders = [
    {"order_id": "ORD-0001", "order_status": "paid", "order_total": 612.07},
    {"order_id": "ORD-0002", "order_status": "refunded", "order_total": 446.70},
    {"order_id": "ORD-0003", "order_status": "paid", "order_total": 1104.32},
]

paid_total = 0
for row in orders:
    if row["order_status"] == "paid":
        paid_total += row["order_total"]
print("Plain Python paid total:", round(paid_total, 2))
Predict: what does paid_total equal after the three turns of the loop?
Plain Python paid total: 1716.39
Fine for 3 orders. Filtering, sorting, joining and fixing typed text would each need another loop to write and debug.
Why is a pandas column faster than a list of dictionaries?
A list of dictionaries is many separate Python objects. Pandas keeps a whole column in one block.
Each Python float takes 24 bytes. A pandas float64 column takes 8 bytes per number.
Because the numbers sit side by side, a sum or a filter runs in compiled code instead of a Python loop. Modern CPUs can even work on several numbers per instruction.
What about a spreadsheet?
A spreadsheet is great for looking. But the steps live in your clicks, so nobody can rerun them tomorrow.
A formula dragged over the wrong range changes a report, and no history shows who did it.
The same rows and columns can sit in a spreadsheet file, in a pandas DataFrame inside Python, or in a SQL table in a warehouse. This track is about the middle one.
Pandas sits in between. The table is a real object in Python, one short line works on every row, and the line stays in your notebook.
Code can be read, tested, versioned in Git and rerun on a server. Clicks cannot.
Where does pandas stop?
Everything you load must fit in the RAM of one machine, and text loaded as Python objects takes several times the file size.
Measured with a generated orders-style file. Sorting or grouping then allocates temporary copies on top.
| A 1 million row orders file | Size |
|---|---|
| CSV on disk | 64 MB |
| DataFrame, text as Python objects (older pandas) | 246 MB |
| DataFrame, text as the new str type (pandas 3) | 82 MB |
Daily batches and sample-sized exports fit easily. For hundreds of gigabytes, teams move to PySpark, which splits the same work across many machines.
Picture this
What are the parts of a DataFrame?
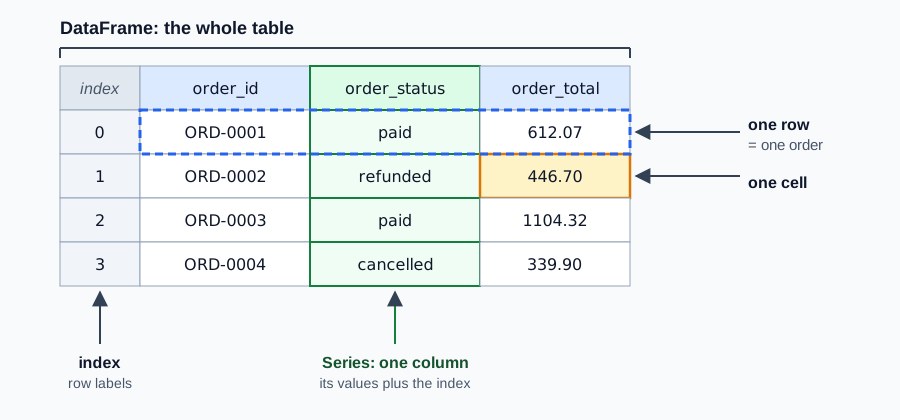
Read it left to right. The grey strip is the index. The blue headers are column names. The green column is a Series. The dashed outline is one order. The orange box is one cell.
Why does the index travel with the rows?
The index is a label for each row, not just a position. Filter a table and each kept row keeps its label.
Predict: which row labels will the first three refunded orders carry?
refunded = df_orders[df_orders["order_status"] == "refunded"]
result = refunded[["order_id", "order_status"]].head(3)
What result holds. The first column is the index.
| order_id | order_status | |
|---|---|---|
| 1 | ORD-0002 | refunded |
| 18 | ORD-0019 | refunded |
| 20 | ORD-0021 | refunded |
Labels 1, 18 and 20 stayed. Filtering never renumbers. If you want a plain 0, 1, 2 count, call df.reset_index(drop=True).
What is a dtype?
Every Series holds one kind of value, called its dtype. It decides how fast and how safely the math runs.
The four dtypes you will meet first.
| dtype | Holds | In df_orders |
|---|---|---|
| int64 | Whole numbers | A count column, if you add one |
| float64 | Decimals | order_total |
| object or str | Text | order_status (str in pandas 3, object in older pandas) |
| category | A few repeating labels, stored compactly | order_status, if you convert it |
What is already loaded in this tab?
You never write import pandas or open a file here. The studio built the tables for you.
The one we use most is df_orders: the 180 orders from the picture, with 7 columns.
The first row of df_orders.
| Column | Example |
|---|---|
| order_id | ORD-0001 |
| user_id | U004 |
| order_status | paid |
| order_total | 612.07 |
| currency | INR |
| created_at | 2026-08-02 16:33:28 |
| updated_at | 2026-08-02 19:33:28 |
To show a table, assign it to a variable named result. In real scripts you load with pd.read_csv or pd.read_parquet. After loading, every operation here works the same.
A small example
How big is the table?
Look before you touch anything. These are the first 3 rows of df_orders.
df_orders.head(3), showing four of its 7 columns.
| order_id | user_id | order_status | order_total |
|---|---|---|---|
| ORD-0001 | U004 | paid | 612.07 |
| ORD-0002 | U073 | refunded | 446.70 |
| ORD-0003 | U078 | paid | 1104.32 |
Predict: what shape and column list will df_orders give, and what type is a single column?
print(df_orders.shape)
print(df_orders.columns.tolist())
print(type(df_orders["order_status"]).__name__)(180, 7) ['order_id', 'user_id', 'order_status', 'order_total', 'currency', 'created_at', 'updated_at'] Series
shape is a pair: 180 rows and 7 columns. 1 column pulled out with square brackets is a Series.
Check shape right after every load. A truncated file shows up as a wrong row count before bad data moves on.
If you only keep one thing from this lesson, keep the vocabulary: DataFrame is the table, Series is a column, index is the row labels. The rest is looking things up. In this tab the tables are already loaded, so you show one by assigning it to result.
How do you total the paid orders without a loop?
Here is the paid total from the loop above, written for pandas. Compare the two.
Predict: what will the sum of every paid order across all 180 rows be?
paid = df_orders["order_status"] == "paid"
print(df_orders.loc[paid, "order_total"].sum())43606.63
Line one asks every row "are you paid?" and keeps the answers. Line two keeps the paid rows and adds up order_total.
What does that yes or no question actually build?
The comparison makes a column of True and False, one per row. It is called a mask.
The mask for the first 3 rows. The full mask has 180 entries, 93 of them True.
| order_id | order_status | == "paid" |
|---|---|---|
| ORD-0001 | paid | True |
| ORD-0002 | refunded | False |
| ORD-0003 | paid | True |
Passing the mask to .loc keeps only the True rows. The table did the looping for you.
How do you pick columns?
A list of names after the comma picks the columns. The colon before the comma means every row.
result = df_orders.loc[:, ["order_id", "order_status"]].head(3)What result holds. The first column is the index.
| order_id | order_status | |
|---|---|---|
| 0 | ORD-0001 | paid |
| 1 | ORD-0002 | refunded |
| 2 | ORD-0003 | paid |
head(3) trims the answer to 3 rows so the grid stays small.
Do one bracket and two brackets give the same thing?
No. One name gives a Series. A list of names, with brackets inside brackets, gives a DataFrame.
one = df_orders["order_status"]
two = df_orders[["order_status"]]
print(type(one).__name__, one.shape)
print(type(two).__name__, two.shape)Series (180,) DataFrame (180, 1)
Some tools downstream need the two-dimensional shape, so know which one you are holding.
Why does my edit do nothing when I chain two brackets?
The first bracket picks rows and hands back a copy. The second bracket edits that copy, then it is thrown away.
Predict: do the cancelled totals change after the chained edit, and after the one-step .loc edit?
out = df_orders.copy()
out[out["order_status"] == "cancelled"]["order_total"] = 0
print(out.loc[out["order_status"] == "cancelled", "order_total"].head(3).tolist())

out.loc[out["order_status"] == "cancelled", "order_total"] = 0
print(out.loc[out["order_status"] == "cancelled", "order_total"].head(3).tolist())[339.9, 549.7, 394.71] [0.0, 0.0, 0.0]
The chained version changed nothing. Pandas 3 warns ChainedAssignmentError and older versions warn SettingWithCopyWarning, but the studio hides that warning, so nothing seems to happen. The one-step .loc version wrote real zeros.
Edit a selection in one step: .loc[rows, column] = value.
Why did my integer column turn into floats?
A native integer array cannot hold a missing value. One None changes the whole column's type.
Predict: what dtype does a Series of 101, 102 and None get?
ids = pd.Series([101, 102, 103])
print("ids dtype:", ids.dtype)

ids_with_na = pd.Series([101, 102, None])
print("ids_with_na dtype:", ids_with_na.dtype)ids dtype: int64 ids_with_na dtype: float64
No warning appeared. Ids longer than about 15 digits can lose precision as floats, so pin id columns, for example dtype={'order_id': 'string'}.
Why avoid .iterrows()?
It runs, but it rebuilds every row as a fresh Series on each turn, throwing away the compact column layout.
total = 0
for _, row in df_orders.iterrows():
    if row["order_status"] == "paid":
        total += row["order_total"]
print(round(total, 2))

print(df_orders.loc[df_orders["order_status"] == "paid", "order_total"].sum())43606.63 43606.63
Both agree. On 180 rows you will not feel the gap. On millions of rows, the mask version finishes far sooner.
How does the whole lesson replay on the running example?
Start with df_orders: 180 orders in a DataFrame. Each column is a Series.
- df_orders
- 180 x 7
Check shape first, so a truncated file shows up right away.
- df_orders.shape
- (180, 7)
Ask every row if it is paid. That makes a mask of True and False.
- order_status == "paid"
- mask, 180 entries
Keep the True rows and sum order_total. No loop, no running total.
- .loc[mask, "order_total"].sum()
- 43606.63
Five things to know from this lesson:
- A DataFrame is the table, a Series is 1 column, and the index is the row labels.
- Ask a question of a whole column and pandas answers for every row. Do not write loops.
- Filtering keeps the original row labels. Use reset_index(drop=True) for a fresh count.
- Edit a selection in one .loc step, never in two brackets.
- A missing value turns an integer column into float64, and the whole table has to fit in RAM.
A DataFrame is a spreadsheet tab. A Series is 1 column you have highlighted. The index is the row numbers down the left side.
Common beginner questions
Why can't I just use Excel?
For a quick look at a small file, you can, and you should. Pandas earns its place when you need the same cleanup to run again tomorrow on a new file, or when the table has to be handed to other Python code. The steps live in your notebook instead of your mouse clicks.
Do I need to install pandas in this tab?
No. The editor already has it, and the tables are preloaded. On your own laptop you would install it once with pip install pandas and then start your script with import pandas as pd.
What is the difference between a Series and a DataFrame?
A Series is 1 column. A DataFrame is several columns that share the same row labels. If a method needs a table with several named columns, give it a DataFrame. If it only needs one list of values, a Series is fine.
What comes next
Next you will look closely at the two shapes pandas uses: the Series (1 column) and the DataFrame (the whole table). You will also learn the two ways of picking rows and columns, .loc and .iloc, and why filtering is exactly where labels and positions stop lining up.
Practice
Open the exercise. You will take df_orders, keep two of its columns and the first 8 rows, and store that in result. Use df_orders.loc[:, ['order_id', 'order_status']].head(8) to select the columns and row slice. Check that the grid shows exactly the columns and the row count the prompt asks for.
Going further: will this DataFrame fit in memory?
pandas keeps the whole table in memory, so the first practical question about any file is: will it fit? You can answer it with arithmetic before you load anything. A number column stores 8 bytes per value, so size is roughly rows times number-columns times 8.
Predict the memory for 1,000,000 values, then for a table of 50 million rows and 10 numeric columns.
import numpy as np

one_million = np.zeros(1_000_000)
print("1,000,000 numbers :", one_million.nbytes / 1_000_000, "MB")

rows, number_columns = 50_000_000, 10
gigabytes = rows * number_columns * 8 / 1_000_000_000
print("50M rows x 10 cols:", gigabytes, "GB of numbers alone")1,000,000 numbers : 8.0 MB 50M rows x 10 cols: 4.0 GB of numbers alone
Eight megabytes per million numbers, and 4 GB for the big table before any text columns, before the index, and before pandas makes a temporary copy during a sort or merge. On a laptop with 16 GB, a 4 GB table is risky, because operations often need 2 or 3 times the table's size.
| Symptom | Likely cause | What to try |
|---|---|---|
| MemoryError, or the machine starts swapping | The table plus its temporary copies exceeds RAM | Read fewer columns (usecols), read in chunks, or move the work to SQL or Spark |
| Fits, but every step is slow | Python-level loops over rows | Use vectorized column operations instead |
| Text columns use most of the memory | Strings are stored per value | Convert repeated labels to the category type |
Try a new scenario
A CSV is 6 GB on disk with 40 million rows. You need the total revenue per country, and the file has 25 columns. What is your plan?
Work it out, then open the answer
Read only the 2 columns you need (usecols for country and revenue), and read in chunks, adding each chunk's per-country totals to a running total. Memory then depends on the chunk size, not the file size. If you will do this regularly or on many files, a query engine such as DuckDB or a warehouse does the same job without loading the table into pandas at all.
Why use pandas instead of a loop over rows?
pandas applies an operation to a whole column in compiled code, which is far faster than a Python loop, and it gives a clearer way to say what you mean. Loops over rows are slow and easy to get wrong.
Close the lesson and explain it
Without scrolling up, explain how to estimate whether a table fits in memory, and name two ways to work with a file that does not.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.