
Overview
A Series is one labeled column. A DataFrame is those columns standing side by side.
On this page8 sections
The idea
What is a grid and what is a strip?
Open a spreadsheet and you see two things at once: a grid, and under each heading a strip of values.
Two shapes and a set of row labels.
| In a spreadsheet | In pandas | In df_orders |
|---|---|---|
| The whole grid | DataFrame | 180 rows by 7 columns |
| One strip under a heading | Series | df_orders["order_total"] |
| The row numbers down the side | Index | 0, 1, 2 and so on, by default |
A Series is 1 column plus its row labels. A DataFrame is several Series side by side, sharing the same labels.
The studio gives you seven DataFrames: df_orders, df_events, df_order_items, df_payments, df_telemetry, df_customers and df_payloads. We keep using df_orders.
What lives inside a DataFrame?
Under the grid, pandas keeps one block of memory for each kind of value. All the decimal columns share a block.
- Decimal columns: one block
- Whole-number columns: one block
- Text columns: one block
That layout is why column work is quick. A whole column is one continuous stretch of memory.
Why is a column quick to read and a row slow?
Now compare the two ways of reading. A column is one stretch. A row has to visit every block.
Pandas stores data column by column, so the two reads cost very different amounts.
In a quick test on 200,000 rows, looping with iterrows took hundreds of times longer than 1 column comparison.
Work on whole columns. Row-by-row loops throw away what pandas is good at.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| DataFrame | A table with rows and named columns |
| Series | One column of a DataFrame |
| Index | The label on each row |
| loc | Pick rows and columns by label |
| iloc | Pick rows and columns by position |
| Slice | A piece of a table |
Why this exists
How do you point at a piece of a table?
Almost every question starts with "give me these rows" or "give me these columns". Pandas has two ways to point.
They sound alike and give different answers once the table has been filtered.
| Way of pointing | You say | Pandas tool |
|---|---|---|
| By label | The column called order_total, the row labelled 2 | .loc |
| By position | The third row from the top | .iloc |
Mixing the two up is the most common source of confusing bugs in beginner notebooks.
Picture this
What do you get when you pick a column?
One name in single brackets gives a Series. A list of names, in double brackets, gives a DataFrame.
The list inside the brackets tells pandas to keep it as a table.
| What you write | What you get back | Shape |
|---|---|---|
| df_orders["order_total"] | Series | 1 column |
| df_orders[["order_total"]] | DataFrame | A table with 1 column |
| df_orders[["order_id", "order_total"]] | DataFrame | A table with 2 columns |
Predict: how will printing a 1-column Series differ from printing a 1-column DataFrame?
print(df_orders["order_total"].head(3))
print(df_orders[["order_total"]].head(3))0 612.07 1 446.70 2 1104.32 Name: order_total, dtype: float64 order_total 0 612.07 1 446.70 2 1104.32
The first is a Series: values, a Name line and a dtype, the kind of value stored. The second has a heading, so it is a DataFrame.
The difference matters because many tools downstream, such as feature scalers and bulk loaders, need a two-dimensional table.
Is the index a counter or a label?
A label. Any column, or the index itself, can act as the row label.
A tiny frame whose index is the order_id instead of 0, 1, 2. Any column, or the index, can act as the row label.
You can set it yourself with set_index, but the default 0, 1, 2 is fine for most beginner work.
What does it look like when the label is an order id?
set_index turns a column into the row label. The order ids are unique, so each label points at exactly 1 row.
by_id = df_orders.set_index("order_id")
print(by_id.loc["ORD-0003", "order_total"])
print(by_id.iloc[2]["order_total"])
print(by_id.index.is_unique)1104.32 1104.32 True
Both lookups reach the same row here, because nothing has been filtered. The label reads like a question you would ask: the total for ORD-0003.
Why does the index matter so much?
It stays attached to a row even when the table around it changes. Joins and arithmetic match rows by label, not by position.
Picture a class register. Priya is roll number 7. If a teacher removes three students above her, she is still roll number 7, not roll number 4. The index is that roll number. When you add two columns from two tables, pandas lines up roll number 7 with roll number 7, whatever order the rows are in.
Pandas matches rows by label, not by where they sit in the table.
A small example
How does .loc point by label?
.loc takes rows, then columns, separated by a comma. A colon means all of them.
result = df_orders.loc[:, ["order_id", "order_total"]].head(3)What result holds.
| order_id | order_total | |
|---|---|---|
| 0 | ORD-0001 | 612.07 |
| 1 | ORD-0002 | 446.70 |
| 2 | ORD-0003 | 1104.32 |
How does .iloc point by position?
.iloc takes the same two parts, but as positions counted from zero, the way Python counts.
result = df_orders.iloc[0:3, 0:3]Position 0:3 stops before 3, just like a normal Python slice.
| order_id | user_id | order_status | |
|---|---|---|---|
| 0 | ORD-0001 | U004 | paid |
| 1 | ORD-0002 | U073 | refunded |
| 2 | ORD-0003 | U078 | paid |
The two look interchangeable here, because on a fresh table labels and positions are the same numbers. Filtering breaks that.
What happens to labels and positions after a filter?
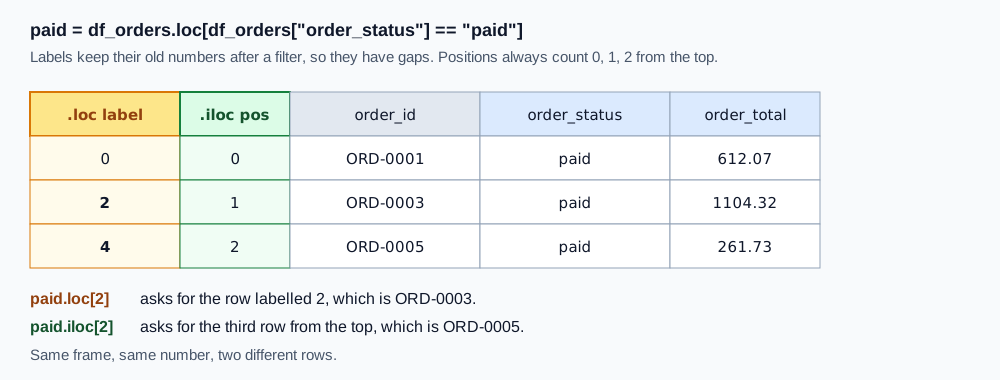
The paid rows keep their old labels 0, 2 and 4. Their positions restart at 0, 1 and 2.
Predict: in this filtered table, do .loc[2] and .iloc[2] return the same order id?
paid = df_orders.loc[df_orders["order_status"] == "paid"]
print(paid.loc[2, "order_id"])
print(paid.iloc[2]["order_id"])ORD-0003 ORD-0005
paid.loc[2] found the row labelled 2, which is ORD-0003. paid.iloc[2] counted to the third row, which is ORD-0005, because ORD-0002 and ORD-0004 were filtered out.
After a filter, a label and a position are different things. Know which one you are asking for.
How do you get clean labels back after a filter?
Call reset_index(drop=True). It throws away the old labels and numbers the kept rows 0, 1, 2 again.
paid = df_orders.loc[df_orders["order_status"] == "paid"]
fresh = paid.reset_index(drop=True)
print(paid.index[:4].tolist())
print(fresh.index[:4].tolist())
print(fresh.loc[2, "order_id"], fresh.iloc[2]["order_id"])[0, 2, 4, 5] [0, 1, 2, 3] ORD-0005 ORD-0005
Now label 2 and position 2 are the same row. The cost is that the original order labels are gone, so renumber only when you do not need them.
Can .loc filter rows and pick columns in one go?
Yes. Put the mask before the comma and the column list after it. This is the line you will write most often.
result = df_orders.loc[df_orders["order_status"] == "paid", ["order_id", "order_total"]].head(3)The kept rows carry their old labels 0, 2 and 4.
| order_id | order_total | |
|---|---|---|
| 0 | ORD-0001 | 612.07 |
| 2 | ORD-0003 | 1104.32 |
| 4 | ORD-0005 | 261.73 |
Can a label slice cover columns too?
Yes. Labels in a slice follow the table's own order, and both ends are included.
result = df_orders.set_index("order_id").loc["ORD-0001":"ORD-0003", "user_id":"order_total"]order_id is the index here. Both ends of each slice are included.
| order_id | user_id | order_status | order_total |
|---|---|---|---|
| ORD-0001 | U004 | paid | 612.07 |
| ORD-0002 | U073 | refunded | 446.70 |
| ORD-0003 | U078 | paid | 1104.32 |
Which slice includes its end?
Position slices stop before the end, like normal Python. Label slices include it.
The slice difference is the one that catches people out.
| .loc | .iloc | |
|---|---|---|
| Points by | Labels, or a True/False mask | Positions, counting from 0 |
| Slice end | Included: loc[0:2] is 3 rows | Excluded: iloc[0:2] is 2 rows |
| Use it when | You name columns or filter by a condition | You want the first or last N rows |
Predict: how many rows do df_orders.loc[0:2] and df_orders.iloc[0:2] return?
print(len(df_orders.loc[0:2]), len(df_orders.iloc[0:2]))3 2
Label slices include the end because they are often used with dates. df.loc["2024-01-01":"2024-01-31"] must include January 31.
How do you combine two conditions?
Use & for AND, | for OR and ~ for NOT, and wrap each comparison in parentheses.
mask = (df_orders["order_status"] == "paid") & (df_orders["order_total"] > 100)
print(mask.sum())84
Use the symbol, not the word.
| Plain Python | pandas | Why |
|---|---|---|
| and | & | and asks if the whole Series is true, which raises ValueError |
| or | | | Same reason |
| not | ~ | Same reason |
Why do the parentheses matter?
In Python, & binds tighter than == and >. Without parentheses, Python tries to combine the text "paid" with a number column.
df_orders["order_status"] == "paid" & df_orders["order_total"] > 100TypeError
Wrap each comparison in its own parentheses and the error goes away.
df[df['order_status'] == 'paid']['order_total'] = value does two selections in a row. The first bracket hands back a copy, so pandas 3 warns ChainedAssignmentError and the edit never reaches the real table. Do it in one step: df.loc[df['order_status'] == 'paid', 'order_total'] = value. Call .copy() first if you only meant to look.
SELECT order_id, order_total FROM orders WHERE order_status = 'paid' is df_orders.loc[df_orders['order_status'] == 'paid', ['order_id', 'order_total']]. The part before the comma is the WHERE, the part after is the SELECT list.
What happens when 2 rows share a label?
Unlike a database primary key, a pandas index does not have to be unique. Concatenate a table with itself and labels repeat.
Predict: does dup.loc[0, "order_id"] return one value or two?
dup = pd.concat([df_orders.head(3), df_orders.head(3)])
print(dup.index.tolist())
print(dup.loc[0, "order_id"].tolist())[0, 1, 2, 0, 1, 2] ['ORD-0001', 'ORD-0001']
Label 0 matches 2 rows, so you get 2 values. Code that expects one value breaks. Call dup.reset_index(drop=True) for clean labels.
What happens when you add two Series with different labels?
Pandas lines them up by label, the same way it would join 2 tables, not by position.
Predict: paid_totals has labels 0, 2, 4 and refunded_totals has 1, 18, 20. What does the sum hold?
paid_totals = df_orders.loc[df_orders["order_status"] == "paid", "order_total"].head(3)
refunded_totals = df_orders.loc[df_orders["order_status"] == "refunded", "order_total"].head(3)
print(paid_totals)
print(refunded_totals)
print(paid_totals + refunded_totals)0 612.07 2 1104.32 4 261.73 Name: order_total, dtype: float64 1 446.70 18 601.64 20 522.51 Name: order_total, dtype: float64 0 NaN 1 NaN 2 NaN 4 NaN 18 NaN 20 NaN Name: order_total, dtype: float64
None of the 6 labels line up, so every row is NaN (no value). To add by position instead, call reset_index(drop=True) on both first.
So which one do you reach for?
Ask what you know about the rows you want.
- You know a condition, such as paid orders: use .loc with a mask.
- You know column names or an order id: use .loc with those labels.
- You want the first or last few rows, whatever they are: use .iloc or head and tail.
When in doubt, use .loc. Its answers do not change when you filter the table first.
The common mistake is using .iloc[0] to mean the order with id 0. After a filter, the first row on screen might be order 1042, so .iloc[0] returns that, while .loc[0] looks for the label 0 and may raise a KeyError. Position and label are different questions.
How does the whole lesson replay on the running example?
Pick a column by label. One name gives a Series, a list gives a table.
- df_orders["order_total"]
- Series
Point by label with .loc, and by position with .iloc.
- .loc[:, cols]
- .iloc[0:3, 0:3]
Filter to paid orders. The old labels 0, 2, 4 stay on the kept rows.
- status == "paid"
- labels 0, 2, 4
Ask for 2 both ways: .loc finds the label, .iloc counts the position.
- .loc[2] = ORD-0003
- .iloc[2] = ORD-0005
Five things to know from this lesson:
- A Series is 1 column. A DataFrame is several columns that share one index.
- Single brackets give a Series. A list inside brackets gives a DataFrame.
- .loc points by label and includes the slice end. .iloc points by position and excludes it.
- Filtering keeps the old labels, so a label and a position stop matching.
- Combine conditions with &, | and ~, each comparison in parentheses.
Common beginner questions
Why does counting start at 0?
That is how Python counts, everywhere. The first item is at position 0, the second at 1, and pandas follows the same rule for .iloc.
What is the actual difference between df['col'] and df[['col']]?
Single brackets with one name return a Series. Double brackets, a list inside brackets, return a DataFrame, even with only 1 column. Use the double version when the next step needs a table.
When should I use set_index?
When you want a meaningful row label, like an order id or a date, and you know the values are unique. For most beginner work the default 0, 1, 2 is fine, and keeping a key as a normal column is simpler.
What comes next
Next you will load data from real files with read_csv, read_excel and read_json. Everything there leans on the Series and DataFrame ideas you just learned.
Practice
In the exercise you take the first 10 rows of df_orders and keep order_id, user_id and order_total. Pick the columns by label and the rows by position. When the grid shows 10 rows and 3 columns, you are done.
Going further: pandas matches rows by index, not by position
When you combine two Series, pandas lines them up by index label, not by position. That is powerful when the labels mean something and surprising when they do not. Predict the result of adding these two Series.
import pandas as pd

revenue = pd.Series([100, 200, 300], index=["north", "south", "east"])
refunds = pd.Series([10, 20], index=["south", "north"])

print(revenue - refunds)east NaN north 80.0 south 190.0 dtype: float64
North and south were matched by label (100 - 20 and 200 - 10), even though refunds listed them in the other order. East has no refund entry, so the result is NaN. pandas will not guess a missing value.
If missing means zero, say so.
import pandas as pd

revenue = pd.Series([100, 200, 300], index=["north", "south", "east"])
refunds = pd.Series([10, 20], index=["south", "north"])

print(revenue.sub(refunds, fill_value=0))east 300.0 north 80.0 south 190.0 dtype: float64
Now east keeps its 300. Alignment also explains a common surprise after filtering: the index keeps its old labels (rows 2, 5, 9), so df.loc[2] is a label lookup while df.iloc[2] is the third row. reset_index(drop=True) renumbers when you want positions again.
Try a new scenario
You compute a daily total from one DataFrame and a daily target from another, then subtract them. Some days exist in only one of them. What do you expect, and how do you make the gap visible instead of hidden?
Work it out, then open the answer
Days present in only one table produce NaN after the subtraction, which is useful because it shows the data does not line up. Do not fill them with 0 until you know why they are missing: a missing target is not the same as a target of 0. Count the NaN rows as a check on the join of the 2 sources.
What is the difference between loc and iloc?
loc selects by label (index values and column names), and iloc by integer position. After filtering, labels and positions differ, which is why mixing them up returns the wrong row.
Close the lesson and explain it
Without scrolling up, explain what pandas does when two Series have different index labels, and when you should fill the gaps.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.