
Overview
Messy files contain empty cells, numbers stored as text, and inconsistent labels. Learn how to inspect dtypes and clean columns with pandas operations.
On this page8 sections
The table we keep using
What does messy data look like?
Real files are messy. People type Paid, paid and ' paid ' for the same thing, and a price column holds the text N/A.
To show every fix on rows you can see, we use 5 rows we typed ourselves. This is not df_orders, which is quite tidy.
messy = pd.DataFrame({
    "order_id": ["O-1", "O-2", "O-3", "O-4", "O-5"],
    "order_status": ["Paid", " paid ", "PENDING", "paid", None],
    "order_total": ["120.50", "80", "45.00", "N/A", None],
})
result = messy
The pink cells are the ones pandas already knows are missing. N/A in O-4 is not pink: to pandas it is just a piece of text.
Look at the status column. To a computer, 'Paid', ' paid ', 'paid' and 'PENDING' are four different values.
Which four things are wrong with it?
We will fix them in this order, one move each.
The plan for the 5 rows.
| Where | What is wrong | The pandas move |
|---|---|---|
| Whole table | You have not looked at what pandas thinks is missing | isna().sum() |
| order_total | It is text, because of the stray N/A | pd.to_numeric(errors="coerce") |
| O-4 and O-5 totals | Blank after conversion | dropna(subset=...) or fillna |
| order_status | Four spellings for 2 words | .str.strip().str.lower() |
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Missing value | A cell with nothing in it, shown as NaN |
| NaN | Not a number. pandas uses it for a blank |
| dtype | The type of a column |
| strip | Remove spaces from the start and end of text |
| fillna | Fill blanks with a value |
| to_numeric | Turn text into numbers |
What we need from it
What does a wrong answer look like?
The question: how many orders are paid, and what is their total? Ask the raw table and you get a wrong answer, quietly.
Predict: what will (messy["order_status"] == "paid").sum() count?
print((messy["order_status"] == "paid").sum())1
One. There are really two paid orders, O-1 and O-2, but 'Paid' and ' paid ' do not equal 'paid' letter for letter.
What happens when you add up text?
Try the total on the raw column.
print(messy["order_total"].sum())TypeError: can only concatenate str (not "int") to str
Pandas tried to glue the pieces of text together, and the missing cell stopped it. Newer pandas versions skip the missing cell and quietly return the glued text 120.508045.00N/A instead. Neither is a total.
Dirty data either crashes the sum or gives a quietly wrong answer.
Before you can ask questions of a table, you clean it. Cleaning is a series of small decisions about what each odd cell means.
Trace it step by step
Step 1: what does pandas think is missing?
Look before you change anything. Count the missing cells per column.
Predict: how many missing values will isna().sum() report for each column?
print(messy.isna().sum())order_id 0 order_status 1 order_total 1 dtype: int64
One status and one total are missing, both in O-5. The N/A in O-4 is not counted, because pandas only treats None and NaN as missing.
The four spellings show up when you count values instead.
print(messy["order_status"].value_counts(dropna=False))order_status Paid 1 paid 1 PENDING 1 paid 1 None 1 Name: count, dtype: int64
5 rows, five different values. Counts alone would never tell you this, so look at the data as well.
Step 2: how do you turn text into numbers?
astype(float) is strict. One bad value stops it with a ValueError.
messy["order_total"].astype(float)ValueError: could not convert string to float: 'N/A'
pd.to_numeric with errors="coerce" is gentler. Anything it cannot read becomes a missing value.
messy["order_total"] = pd.to_numeric(messy["order_total"], errors="coerce")
result = messy
After step 2. The totals are real numbers, and N/A became NaN. A missing status prints as None or NaN depending on the pandas version.
| order_id | order_status | order_total | |
|---|---|---|---|
| 0 | O-1 | Paid | 120.5 |
| 1 | O-2 | paid | 80.0 |
| 2 | O-3 | PENDING | 45.0 |
| 3 | O-4 | paid | NaN |
| 4 | O-5 | (missing) | NaN |
Step 3: what do you do with the blanks?
Now O-4 and O-5 both have no total. You have two honest choices: drop the rows, or fill the blanks.
dropna with subset=["order_total"] only looks at that column. Without subset, a blank in any column drops the row.
Predict: how many of the 5 rows will survive dropna(subset=["order_total"])?
before = len(messy)
messy = messy.dropna(subset=["order_total"]).copy()
print(before, "->", len(messy))
result = messy5 -> 3
After step 3. 2 rows are gone.
| order_id | order_status | order_total | |
|---|---|---|---|
| 0 | O-1 | Paid | 120.5 |
| 1 | O-2 | paid | 80.0 |
| 2 | O-3 | PENDING | 45.0 |
Always print the row count before and after. Losing 2 of 5 is a hint. Losing 40 percent of a real file means the problem is in the source, not in a few bad rows.
How do you choose between dropna and fillna?
fillna writes a value into the blank. That is only right when the blank has an agreed meaning, such as a missing discount meaning 0.
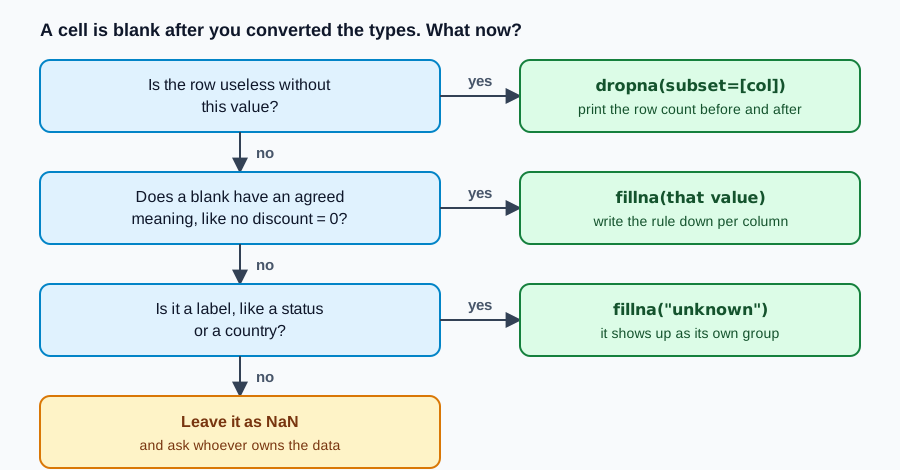
A missing sensor reading does not mean the temperature was zero. Decide the rule per column and write it down.
Step 4: how do you make the words match?
The .str part of a text column applies a text operation to every value at once. strip() removes spaces at the ends and lower() lowercases. Chain them.
Predict: how many paid orders will the count find after strip and lower?
messy["order_status"] = messy["order_status"].str.strip().str.lower()
print((messy["order_status"] == "paid").sum())
result = messy2
After step 4: the clean table.
| order_id | order_status | order_total | |
|---|---|---|---|
| 0 | O-1 | paid | 120.5 |
| 1 | O-2 | paid | 80.0 |
| 2 | O-3 | pending | 45.0 |
The count is now 2, which is what a person reading the rows would say.
print(messy["order_total"].sum())245.5
How do you know the cleaning worked?
Look again, the same way you looked at the start. Three quick checks:
- isna().sum() shows only the blanks you chose to keep.
- value_counts() shows two spellings, paid and pending, not five.
- dtypes shows order_total as float64, so sums and averages work.
If a check still looks wrong, the fix is in an earlier step, not in a new one.
Why look again at all? Cleaning code can run without any error and still do nothing useful. For example, str.strip() on a column of numbers does nothing, and replacing "Paid" does not touch "paid " with a trailing space. Only looking at the result shows you what really changed.
What was the order of the four moves?
Look first, turn text into numbers, handle the blanks that appear, then make the words consistent.
Look first, turn text into numbers, handle the blanks that appear, then make the words consistent.
The order matters a little. Converting to numbers first is what reveals the extra blanks, so the blank step comes after it.
Same table, next cut
What if you must keep every order?
Cleaning is a set of choices. Suppose we must keep all 5 rows, even the ones without a total. Then we fill instead of dropping.
keep = pd.DataFrame({
    "order_id": ["O-1", "O-2", "O-3", "O-4", "O-5"],
    "order_status": ["Paid", " paid ", "PENDING", "paid", None],
    "order_total": ["120.50", "80", "45.00", "N/A", None],
})
keep["order_total"] = pd.to_numeric(keep["order_total"], errors="coerce")
keep["order_status"] = keep["order_status"].str.strip().str.lower().fillna("unknown")
result = keep
All 5 rows survive. The totals stay blank. The missing status says unknown.
| order_id | order_status | order_total | |
|---|---|---|---|
| 0 | O-1 | paid | 120.5 |
| 1 | O-2 | paid | 80.0 |
| 2 | O-3 | pending | 45.0 |
| 3 | O-4 | paid | NaN |
| 4 | O-5 | unknown | NaN |
The missing status became 'unknown', so it shows up as its own group in a count instead of vanishing. The totals stay blank.
Why not fill every missing total with 0?
An order with no known total is not an order worth zero. Zero is a real value, and filling it in invents data.
Predict: how much does the average total drop if the two blanks become 0?
print(round(keep["order_total"].mean(), 2))
print(round(keep["order_total"].fillna(0).mean(), 2))81.83 49.1
The average fell from 81.83 to 49.1 because 2 orders were counted as free. A missing temperature and a temperature of zero degrees are different facts.
Only fill a blank when you can say what it means.
Why call .copy() after a filter?
Copy before you edit a filtered table, so your edit cannot land on a view of the original.
A filtered table can be a window onto the original rather than a separate table. If you then change a value, pandas has to guess whether you meant to change the window only or the original too. Writing paid = df[df["status"] == "paid"].copy() says clearly: this is my own table, edit it freely.
In older pandas, editing a filtered table could touch a view of the original and raise SettingWithCopyWarning. Pandas 3 always gives you a copy, so the warning is gone, but calling .copy() is harmless and works in every version.
What will this do to df_orders?
In this tab df_orders has no missing totals and its statuses are already lowercase. The three exercise steps leave it looking the same.
That is fine. You are practising the moves, and on a real file with real dirt the same lines will change it.
How does the whole trace replay?
Look first. isna().sum() shows one missing status and one missing total.
- messy
- isna().sum()
Turn the totals into numbers. N/A becomes NaN instead of stopping the run.
- to_numeric
- coerce
Drop or fill the blanks, and print the row count before and after. 5 became 3.
- dropna(subset)
- 5 -> 3
Make the words match. Two paid orders are now counted, and the total is 245.5.
- strip + lower
- 2 paid, 245.5
Five things to know from this lesson:
- Look before you change anything: isna().sum() and value_counts(dropna=False).
- Turn text into numbers with pd.to_numeric(errors="coerce"), not astype.
- Use dropna(subset=...) when a row is useless without the value, and print the row count before and after.
- Only fillna when a blank has an agreed meaning. Zero is a real value.
- Use .str.strip().str.lower() so one word is spelled one way.
Look at the data before you change it, and print the row count before and after every dropna. If you lose 40 percent of a real file, the problem is upstream, not in a few bad rows. Only fillna when a blank has an agreed meaning.
Common beginner questions
What is the difference between NaN and None?
Both mean 'missing'. NaN is the standard missing marker for numbers, and None is Python's own empty value. Pandas treats both as missing, and isna() finds either one.
Should I drop the rows or fill the blanks?
Drop when the field is required and the row is useless without it, like a missing order total when you are adding up revenue. Fill when the blank has an agreed meaning, like no discount meaning 0. If you are not sure, ask whoever owns the data.
Why did my astype call crash?
Because one value in the column could not be converted, like our N/A. astype is strict. to_numeric with errors="coerce" turns the bad ones into NaN so you can look at them and decide.
What comes next
With a clean table you can start asking real questions. The next lesson is about filtering: keeping only the rows you care about, with True/False masks, isin and combined conditions.
Practice
In the exercise you start from df_orders and do three of the moves from the trace: drop rows with a missing order_total, turn that column into floats, and lowercase order_status. Work in that order, copy the frame before editing it, and assign the cleaned table to result.
Going further: duplicates and dates that will not parse
Cleaning has 2 jobs that beginners meet immediately: removing repeated rows, and turning date text into real dates. Predict how many rows remain and which date becomes missing.
import pandas as pd

df = pd.DataFrame({
    "order_id": ["A1", "A2", "A2", "A3"],
    "amount": [100, 250, 250, 80],
    "placed": ["2026-09-01", "2026-09-02", "2026-09-02", "01/09/2026"],
})

print("repeated rows:", df.duplicated().sum())
deduped = df.drop_duplicates()
deduped = deduped.assign(placed=pd.to_datetime(deduped["placed"], format="%Y-%m-%d", errors="coerce"))
print(deduped)
print("bad dates:", deduped["placed"].isna().sum())repeated rows: 1 order_id amount placed 0 A1 100 2026-09-01 1 A2 250 2026-09-02 3 A3 80 NaT bad dates: 1
One exact repeat was removed, leaving 3 rows. The date '01/09/2026' does not match the expected format, so errors='coerce' turned it into NaT (not a time) instead of crashing. coerce is useful, but it hides the problem unless you count the result, as the last line does.
drop_duplicates() compares whole rows. If 2 rows share an order_id but differ in amount, they are not duplicates by that rule. Decide the key first with subset=['order_id'] and decide which one to keep.
Try a new scenario
2 rows have order_id 'A2': one with amount 250 and a timestamp of 10:00, one with amount 260 and a timestamp of 11:00. You want the later one. Which tools do you use?
Open the answer
Sort by the timestamp, then drop_duplicates(subset=['order_id'], keep='last') keeps the final row for each id. The remaining amount is [260]. Without the sort, 'last' means last in file order, which is not necessarily the latest in time.
Interview: how do you handle missing values?
First ask what missing means: unknown, not applicable, or zero. Then choose to drop the row, fill with a justified value, or keep it as missing and let later steps handle it. Count what you changed so the cleaning is visible.
Close the lesson and explain it
Without scrolling up, explain why errors='coerce' needs a follow-up check, and how you decide which duplicate to keep.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.
- Handle Missing ValuesInterview-style drill: Show dropna, mean fill, and ffill strategies labeled by method.Studiobeginnerpandas12 min
- Forward-fill per deviceInterview-style drill: Fill missing readings from the same device only, never across devices.Studiointermediatepandas14 min
- Fill with the group median and flag itInterview-style drill: Fill each missing temperature with the median of its site and mark which values were filled.Studiointermediatepandas14 minLocked