
Overview
Who runs your PySpark code, where it runs, how data moves, and why Spark exists. One walk from your Python line down to partitions, tasks and executors.
On this page19 sections
- 01Why does Spark exist?
- 02What are Spark and PySpark?
- 03Who does what in a cluster?
- 04Why does Spark cut data into partitions?
- 05Why does nothing happen when I run my code?
- 06What is a DAG, and why does a shuffle matter?
- 07What happens to one query, start to finish?
- 08What are Catalyst and Tungsten?
- 09How do tasks reach executors?
- 10Why can Python be the slow part?
- 11How does Spark use memory and survive failures?
- 12How do joins, skew and the Spark UI fit in?
- 13Where does each piece run?
- 14Where does my data live?
- 15What is the whole picture?
- 16Common beginner questions
- 17What comes next
- 18Practice
- 19Going further: count the stages before you run the job
Why does Spark exist?
You will soon write df.filter(...).groupBy(...).agg(...). It reads like pandas. It is not pandas, and treating it that way causes bugs that are hard to find.
This page builds the whole picture once, from the problem Spark solves down to the boxes you see in the Spark UI.
The editor here runs a small simulation of Spark on a small orders table. There is no real YARN or Kubernetes behind it. Use the lesson to learn the names and the flow, then judge real scale on a real job.
What breaks on one machine?
Start with a Python loop that lives on one computer.
data = [1, 2, 3, 4, 5]

result = []
for x in data:
    if x > 2:
        result.append(x * 10)

print(result)[30, 40, 50]
Five numbers, one process, one memory. If it crashes you run it again. That is the right tool until the data stops fitting. Then three things go wrong at once.
- Memory runs out500 GB will not fit in 16 GB of RAM
- It takes too long10 hours for 1 TB on one machine
- Something breaksa disk dies at 3am, mid-job
What happens when memory runs out?
Say your laptop has 16 GB of RAM and the data is 500 GB. Python turns each value into an object, so even a file that sits happily on disk can become several times bigger in memory.
The machine swaps, freezes, or dies with an out-of-memory error. Reading line by line saves a simple filter. It does not save a group-by, a join or a sort, because those need rows from all over the file to meet in one place.
Why does it take so long?
Say one machine needs 10 hours for 1 TB. If 100 machines each took a hundredth of the data, the job could finish in minutes.
You will not get a perfect 100 times speedup, because splitting the work and merging the answers costs something. But a nightly pipeline that must finish by 6am cares about the wall clock, and many CPUs beat one.
What if a machine dies mid-job?
Across 100 machines, a disk dies or a node is taken away on some nights. A single script can just be restarted.
A job that has finished 99 slices cannot throw them all away because slice 57 was lost. It needs to redo only the missing piece.
Spark exists because the left column stops working as data grows.
Split the data. Work in parallel. Combine the answers.
Everything else on this page (driver, executors, partitions, shuffle, stages) is machinery for that split, that parallel work and that combine, so you never write networking code yourself.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Cluster | A group of machines that work as one |
| Driver | The program that plans the work and hands it out |
| Executor | A worker process that runs the tasks |
| Partition | One slice of the data |
| Action | A call such as count() that makes Spark run the plan |
| Shuffle | Moving rows between machines so matching rows meet |
What are Spark and PySpark?
Apache Spark is a distributed data processing engine. You say what you want, like grouping sales by country and summing them. Spark works out how to split that across machines.
df.groupBy("country").sum("sales")You never say which machine handles India and which handles the USA. Think in tables and columns, and let Spark place the work.
Is PySpark a second engine?
No. Spark is written mostly in Scala and runs on the JVM (the Java virtual machine). PySpark is the Python door into it.
Your Python code describes the work. The JVM engine carries it out.
You type Python. PySpark passes the description to the Spark engine. The engine runs it on the machines.
Learn how Spark works. Type it in Python.
Who does what in a cluster?
A cluster is a group of ordinary computers that share jobs. 4 machines with 32 GB each are not one computer with 128 GB. They are four separate memories joined by a network.
Spark makes them behave like one system without pretending they share memory. Here is the official diagram from the Spark documentation, and below it the same idea with a few more words.
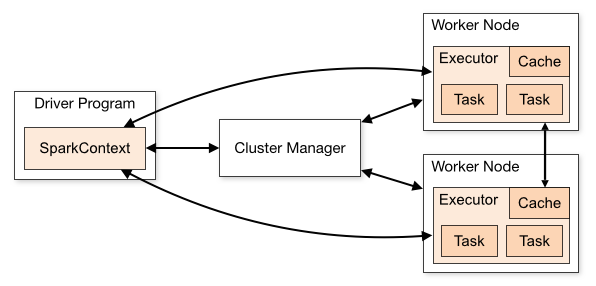
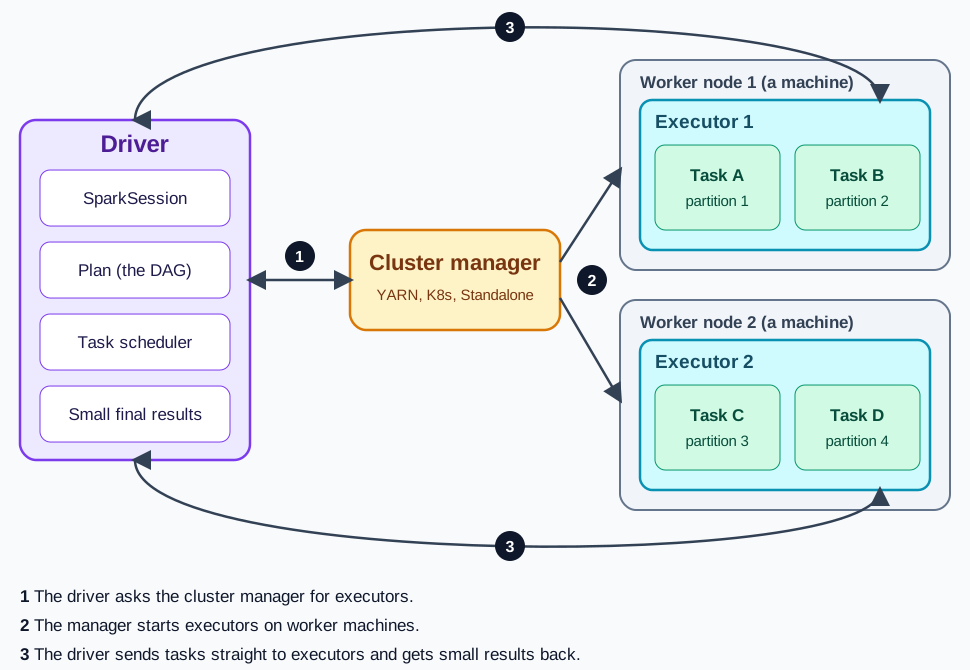
Here is the same picture as a short conversation.
Now each part in turn.
What does the driver do?
The driver is the one process that runs your Python script. It builds the plan, cuts the work into tasks, sends them out, watches them, and collects the small final answers.
It does not usually touch the bulk of your data. When you call show(), only a small sample travels back to the driver so it can print it.
df = spark.read.csv("data.csv")

result = (
    df.filter(df.salary > 50000)
      .groupBy("department")
      .sum("salary")
)

result.show()
The driver lines that code up as a list of steps.
- Read the data
- Keep salaries over 50000
- Group by department
- Add up the salaries
- Show
You never wrote a workflow. Spark worked it out from the chain.
What is a SparkSession?
Your Python reaches all of this through one object, the SparkSession, usually called spark. It reads data, runs SQL and creates DataFrames, and it lives inside the driver.
from pyspark.sql import SparkSession

spark = (
    SparkSession.builder
    .appName("My Application")
    .getOrCreate()
)
getOrCreate() means reuse the session if this process already has one. That is why notebooks can repeat this line in every cell. In the editor on this site, spark is already set up for you.
What does the cluster manager do?
Say the cluster has 100 machines and the driver wants 10 of them, plus 40 CPU cores. Other people's jobs are using the same cluster, so someone has to decide who gets what.
The driver knows what it wants. The manager knows what is free.
Spark works with several managers: its own Standalone one, YARN (common where a company grew up on Hadoop) and Kubernetes. Your code does not change between them.
If the cluster is busy, you may queue or get fewer cores than you asked for. That is the manager doing its job, not Spark being broken.
Workers or executors: what is the difference?
A worker node is a machine in the cluster that can do Spark work. An executor is the Spark process on it that does the computing. A worker can host one executor or several.
Executors live for the whole application. They have CPU cores and memory, run tasks, and hold any data you cache. They share the plan, not Python variables, and exchange data only in a shuffle or when results go back to the driver.
The two roles to keep apart. Most beginner outages are a mix-up between them.
| Driver | Executor |
|---|---|
| Brain: decides what should happen | Hands: does the work |
| Builds the plan and schedules tasks | Runs the tasks |
| One per application | Usually many |
| Keeps application state, receives small results | Processes partitions and holds cached data |
The classic beginner failure is asking executors to send the whole table back to the driver. It works on a 10-row sample and then kills the driver on real data. You will see exactly why in a few sections.
Why does Spark cut data into partitions?
Give a 1 TB file to one executor and you waste every other CPU in the cluster, and probably run out of memory on that one anyway. The data must be cut into pieces that can be worked on independently.
Each piece is a partition: a chunk of rows. When Spark reads files, around 128 MB each is a common default. The numbers in the diagram below are only for sketching.
Each box is 1 partition, one pile of rows. Piles can be processed at the same time on different executors.
What is a task?
A task is the smallest unit of work sent to an executor. For a given stage, Spark usually creates one task per partition.
If a stage has 200 partitions, the Spark UI shows about 200 tasks for it. That is the same fact counted two ways.
| Word | What it is | Think of it as |
|---|---|---|
| Partition | A chunk of the data | One pallet |
| Task | The work done on 1 partition | One person carrying one pallet |
| Core | A CPU slot on an executor, runs one task at a time | A pair of hands |
| Executor | A process with several cores and some memory | A crew |
Why do partitions limit speed?
The number of partitions limits how much runs in parallel.
Take 100 GB in 10 partitions: Spark can run up to 10 tasks at once. Take the same data in 1 partition and a single task does everything, even if you rented 100 machines.
The extra machines sit idle because there is no extra pile to hand them.
When a job is slow and most executors look idle, the first question is not whether you need more machines. It is how many partitions the slow stage actually has.
Why does nothing happen when I run my code?
Here is a small program: read a CSV of employees, keep the high salaries, count people per department, show the result.
df = spark.read.csv("employees.csv")

filtered_df = df.filter("salary > 50000")

result = filtered_df.groupBy("department").count()

result.show()
Run the first three statements and almost nothing happens. No cluster CPU spins up to scan employees.csv. The variables are not rows. They are descriptions of what you plan to do.
- filternoted on the plan
- groupBynoted on the plan
- show()an action, so run it now
Only an action, a call that must produce a real result, makes Spark execute. This is called lazy evaluation.
Beginners add a filter and then stare at the cluster waiting for something to happen. Nothing will, until an action runs.
Why is waiting a good idea?
Imagine 3 lines in a row: filter by salary, filter by age, then keep 2 columns.
(
    df.filter("salary > 50000")
      .filter("age > 25")
      .select("name", "salary")
)
If every line ran as you typed it, Spark would read all the columns, filter, store the result, then filter again.
Because it waits, it sees the whole recipe first. It can read only name, salary and age, and apply both filters in a single pass. An eager tool like pandas cannot, because each line has already finished before the next is written.
Which methods only plan, and which run?
Every Spark method falls into one of 2 groups. The group tells you whether the method will touch the cluster.
| Transformations | Actions | |
|---|---|---|
| What they do | Describe a step and return a new DataFrame | Demand a real result |
| Runs on the cluster? | No, only changes the plan | Yes |
| Examples | filter, select, groupBy, join, withColumn, drop | show, count, collect, take, write |
df2 = df.filter("salary > 50000")   # transformation: plan only
df2.show()                          # action: now Spark runs it
Build a habit: count the actions in a notebook. Each one can rerun the whole plan unless you cache. 12 show() calls on the same giant DataFrame can mean 12 full scans.
What is a DAG, and why does a shuffle matter?
Once an action arrives, Spark turns the plan into a graph. DAG stands for Directed Acyclic Graph, which sounds worse than it is.
Directed means steps go in a direction, A then B then C. Acyclic means no loops. Graph means connected boxes.
Each box needs the output of the box before it. Spark draws this dependency list so it can see the whole recipe at once.
You cannot group by department until the filter has produced rows. The graph also tells Spark what can run in parallel, where data must move, and what to redo if something fails.
What is the difference between narrow and wide?
This split shows up in almost every slow Spark job. Take 3 partitions with a few numbers each.
Three independent piles of rows.
| Partition 1 | Partition 2 | Partition 3 |
|---|---|---|
| 1, 2, 3 | 4, 5, 6 | 7, 8, 9 |
A narrow transformation finishes inside each pile. filter, select and map are narrow. Nobody has to talk to anybody, so it is cheap, and Spark can run read, filter and select back to back in one task.
A wide transformation cannot. groupBy, join, orderBy and distinct are wide, because rows that belong together may sit in different partitions.
Say you want groupBy("country"). All the India rows must end up together, but some are in partition 1 and some in partition 2. So data must move.
What is a shuffle?
A shuffle redistributes rows across partitions so that rows with the same key end up in the same place. It is the most expensive thing Spark does.
It writes data to disk, sends it over the network, reads it back, and often sorts.
A slow groupBy, join or orderBy is usually data moving between machines, not slow Python.
Here is a small version with sales rows. The filter has already removed small amounts, and the rows sit in 2 partitions.
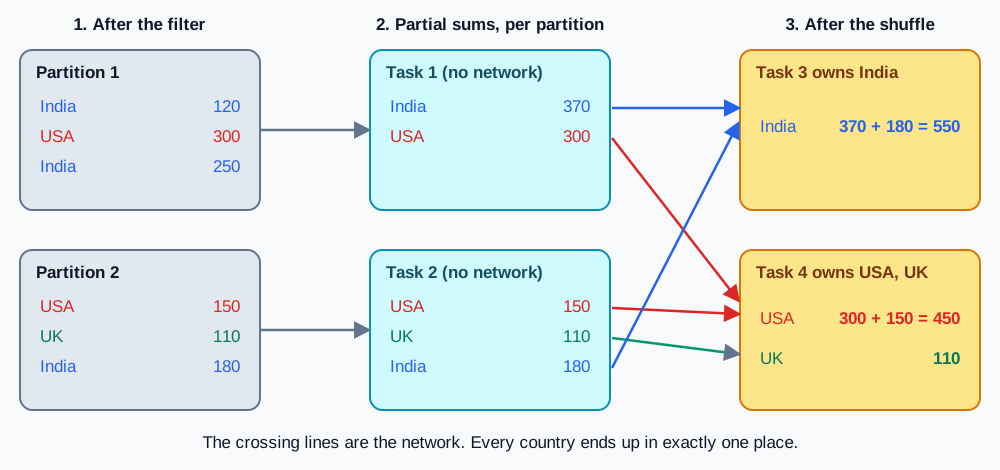
Look at the middle column. Before shuffling, each partition adds up its own rows per country, locally. The shuffle then carries only those small partial totals, not every raw row.
On real data, thousands of rows per country collapse into one number per partition. That is why a groupBy is expensive but not as bad as shipping everything.
Narrow steps stay inside a partition. Wide steps (groupBy, join, orderBy, distinct) cause a shuffle. When you optimise Spark you are mostly trying to shuffle less, or to shuffle fewer bytes when you cannot avoid it.
Job, stage, task: which is which?
Beginners confuse these 3 words. You need them straight to read the Spark UI.
- A job is created each time you call an action. show() makes one job, and a later count() makes another.
- A job is cut into stages at every shuffle. One shuffle gives 2 stages, two shuffles give three.
- A stage runs as tasks, usually one per partition. A stage with 100 partitions has about 100 tasks.
Written as a hierarchy, with your whole program on top:
- Applicationyour whole PySpark program
- Jobone per action (show, count, write)
- Stageone per shuffle-free chunk of the plan
- Taskone per partition, runs on one core
- Stageone per shuffle-free chunk of the plan
- Jobone per action (show, count, write)
Here is the sales aggregation query visualized as jobs and stages: read sales, keep amounts over 100, group by country, sum, then show.
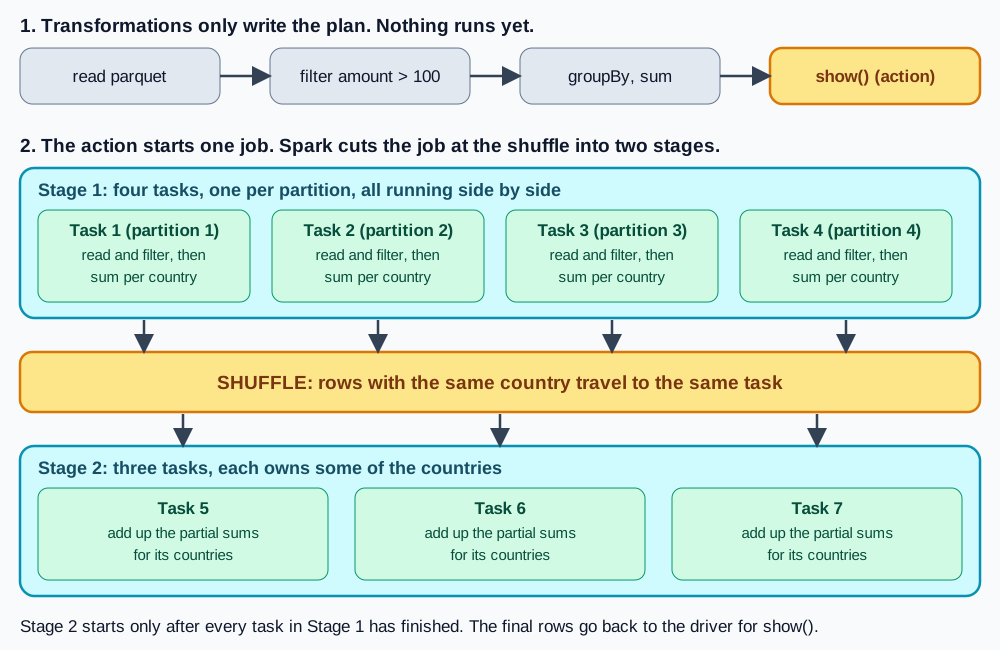
Stage 1 is everything Spark can do before it has to move data: read, filter and a partial sum. The shuffle is the boundary. Stage 2 is the final sum.
When the Spark UI shows Stage 0 and Stage 1, this is what you are looking at. Stage 0 is simply the work before the first shuffle.
What happens to one query, start to finish?
Time to put the pieces together. We follow one query from submission to the printed table.
The data sits in a Parquet folder called sales, already split into 2 partitions for this example.
Eight sales rows. Two of them are under 100 and will be filtered out.
| Partition | country | amount |
|---|---|---|
| 1 | India | 120 |
| 1 | USA | 300 |
| 1 | India | 250 |
| 1 | UK | 40 |
| 2 | USA | 150 |
| 2 | UK | 110 |
| 2 | India | 180 |
| 2 | USA | 60 |
result = (
    spark.read.parquet("sales")
    .filter("amount > 100")
    .groupBy("country")
    .sum("amount")
)

result.show()- You submit the application. Spark starts one driver. In local mode that is a process on your laptop.
- The driver asks the cluster manager for resources. Executors start on workers and register with the driver. A job submitted before they are ready simply waits.
- The 3 lines that build result run nothing. Spark notes the plan. For Parquet it can also read file footers, which list column names and min and max values.
- show() is the action. Spark creates one job. Until now the Spark UI showed executors but no job for this query.
- The Catalyst optimizer rewrites the plan and produces a physical plan: the actual list of operations to run.
- The scheduler cuts the job into 2 stages at the groupBy shuffle. Stage 1 gets one task per partition, so 2 tasks. They read, filter, and compute a partial sum per country, then write it to local disk.
- The shuffle moves partial sums so each country meets itself in one place. Stage 2 tasks add them up. The totals go to the driver and show() prints them.
The printed result. India is 120 + 250 + 180. USA is 300 + 150. UK is 110. The 40 and the 60 never reached the sum.
| country | sum(amount) |
|---|---|
| India | 550 |
| USA | 450 |
| UK | 110 |
Check it against the shuffle picture: filtered rows, partial sums on each partition, one shuffle, final sums.
On a real cluster the order of the three result rows may differ, because tasks finish in whatever order they finish.
What are Catalyst and Tungsten?
Between your code and the tasks there is a planning step. You tell Spark what you want. Spark's query optimizer, Catalyst, decides how.
It works on DataFrame and Spark SQL code the way a database parses and optimises SQL before running it.
What are the logical and physical plans?
The logical plan says what must happen: read sales, filter, group, sum. It makes no decisions about machines. Catalyst rewrites it into a cheaper optimized logical plan.
Then Spark picks a physical plan: which executors read which partitions, where the shuffle goes, which join algorithm to use.
Logical is the what. Physical is the how.
Catalyst turns your description into a cheaper plan. The physical plan is what the scheduler cuts into stages and tasks.
What does Catalyst rewrite for me?
- Column pruning. If the table has 100 columns and you use two, Spark reads only those two when the file format allows it.
- Predicate pushdown. Spark pushes your filter toward the data source. On Parquet it can skip whole blocks whose maximum value is already below your threshold.
- Constant folding. salary > 1000 + 500 is simplified to salary > 1500 once, instead of being recomputed.
- Join strategy. Spark picks the join algorithm, such as a broadcast join, using what it knows about table sizes.
Catalyst can only optimise what it can see. Plain DataFrame code is visible to it. A Python function wrapped as a UDF is a black box. The Python and JVM section returns to this.
And where does Tungsten fit?
Catalyst decides the best plan. Tungsten makes executing that plan cheaper, with compact binary memory layouts and generated code that handles a whole stage in one tight loop instead of a row at a time.
You do not need its internals yet.
Catalyst plans. Tungsten executes.
How do tasks reach executors?
Say Stage 1 has 8 partitions, so Spark creates about 8 tasks. An executor runs as many tasks at once as it has cores. One core runs one task at a time, 4 cores run four.
Here are 3 executors sharing 8 tasks. When a core finishes a task, it picks up the next waiting one.
8 tasks scheduled onto 3 executors. The scheduler does this, not you.
| Executor | Tasks it runs | Partitions it works on |
|---|---|---|
| Executor 1 | 1, 4, 7 | 1, 4, 7 |
| Executor 2 | 2, 5, 8 | 2, 5, 8 |
| Executor 3 | 3, 6 | 3, 6 |
Parallelism is a matching problem between piles of data and cores to carry them.
With 10,000 tiny partitions on 4 cores, scheduling overhead dominates. With 2 giant partitions on 40 cores, 38 cores do nothing. Tuning comes later. For now, know that both numbers matter.
How does the whole picture fit together?
Your code and SparkSession feed the driver. The driver plans and schedules. The cluster manager grants workers. Executors run tasks on partitions, and small results flow back to the driver.
Why can Python be the slow part?
Your code is Python, but Spark's engine runs on the JVM. When you call df.filter(...), your Python process sends the description of that operation to the JVM through a bridge library called Py4J.
Your Python process is not looping over rows. For ordinary DataFrame operations, all the real work stays inside the JVM. Python is a remote control, which is why PySpark DataFrame code is usually about as fast as the Scala equivalent.
Why can Python UDFs be slow?
The exception is a Python UDF, a function you write in plain Python and hand to Spark.
For every row (or batch of rows), Spark takes the data out of the JVM, sends it to a Python process, runs your function, and sends the result back. That crossing costs serialization and communication on every trip.
from pyspark.sql.functions import udf

@udf("double")
def my_function(x):
    return x * 2
A built-in expression does the same thing without leaving the engine, and Catalyst can see inside it.
from pyspark.sql import functions as F

df.withColumn("double", F.col("value") * 2)
Use native Spark functions whenever one exists. A UDF is a toll road.
Is a Spark DataFrame just a pandas DataFrame?
The method names look alike, which tricks people into thinking the objects are alike. They are different things.
df[df["salary"] > 50000]         # pandas: runs now, on this machine
df.filter("salary > 50000") # PySpark: adds a step to a plan| pandas DataFrame | Spark DataFrame | |
|---|---|---|
| Where is the data? | In one process's RAM | Split into partitions across executors |
| When does work happen? | Immediately, on each line | Only when an action runs |
| What is the variable? | The actual rows | A plan that will produce rows |
| len(df) or count() | Free, the rows are right here | An action: a full pass over the data |
The matching names make Spark easy to start and easy to misuse. Looping over rows, mutating in place, or assuming a count is free will make the job crawl or crash the driver.
Keep the verbs. Drop the idea that the variable holds the data.
How does Spark use memory and survive failures?
Does data have to cross the network?
Suppose your data sits on machine 1 but the task runs on machine 5. The rows must cross the network, which is slow compared with a local disk. So Spark prefers to move the computation to the data.
If the partition lives on machine 2, it tries to run the task on machine 2. Caches, busy CPUs and cloud object storage change the picture, but the scheduler prefers it.
What is inside an executor?
In a simplified view, executor memory has two uses. Execution memory serves running operations: shuffles, joins, sorts, aggregations. Storage memory holds cached data.
The two can borrow from each other. A heavy shuffle can push some cached blocks out, and a very large cache can leave less room for a shuffle.
A simplified picture. The driver has its own, separate memory.
| Pool | Used for | When it overflows |
|---|---|---|
| Execution memory | Shuffle, join, sort, aggregation | Spills to disk, or the task fails with out of memory |
| Storage memory | Cached and persisted data | Cached blocks get evicted or recomputed |
An out-of-memory error on an executor usually means one of these pools. A driver out-of-memory error is a different story: too much data was collected home.
When should I cache?
Say you read a large Parquet dataset and use it 3 times: a filter, a groupBy and a join. Without help, Spark recomputes from the start for each action, because the DataFrame is a plan, not stored rows.
df = spark.read.parquet("large_data")
df.cache()          # lazy: marks it to be kept

df.filter("country = 'IN'").count()   # first action pays the cost and fills the cache
df.groupBy("country").count().show()  # reuses the cached partitions
cache() is lazy too. The first action after it does the work and stores the partitions in executor memory. Later actions reuse them.
Caching spends memory, so it only pays off when the data is reused several times and recomputing it is expensive. A table you touch once should not be cached.
How does Spark recover from a crash?
Build a chain: read a CSV into df1, filter into df2, select into df3, group and count into df4. Spark remembers that chain.
This history of how a dataset was produced is called lineage. It is the DAG, read backward from one DataFrame to its sources.
Executor 3 is lost. Spark reads the lineage and rebuilds partition 7 on another executor.
You never wrote retry logic. The lineage is the retry logic.
Two honest limits. Lineage can only replay from sources that still exist: if the CSV was a temp file you deleted, there is nothing to replay.
And after a shuffle, the intermediate shuffle files on local disk matter more. Losing them means more upstream work is redone than losing a simple in-memory partition of a narrow stage.
How do joins, skew and the Spark UI fit in?
How does a join work?
Take employees.join(departments, "department_id"). Matching keys are not automatically in the same place, so a normal distributed join shuffles both sides until all rows with the same key meet.
After that shuffle, a partition is no longer the first chunk of a file. It is the chunk for certain join keys.
When is a broadcast join better?
Now suppose employees is 1 TB and departments is 10 MB. Shuffling a terabyte to match it against 10 MB would be silly.
Instead Spark sends a copy of the small table to every executor. Each executor joins its own piece of the big table against its local copy, and the big side never moves.
The 10 MB table is copied to every executor. The 1 TB table stays where it is.
Spark chooses this on its own when it knows one side is small, by default under about 10 MB, and you can also hint it. The cost is memory: the broadcast table has to fit on every executor.
What is data skew?
Parallel work only helps if everyone carries a similar load. Say you have 5 partitions, and the usual size is 10 GB each.
Now partition 1 is 90 GB and the others are 1 GB. One task grinds on while 4 executors finish and sit waiting.
Partition sizes in GB. In a balanced job every partition looks like the first bar. In a skewed job 1 partition looks like the second bar and the rest like the third, so everyone waits on the big one.
A Spark job is only as fast as its slowest important task.
Skew often shows up after a shuffle, when one key (one country, one customer, one null value) owns most of the rows. A later lesson shows how to spot it and how to fix it.
What does the Spark UI show?
A running Spark application serves a web page, usually on port 4040 of the driver machine, that shows what really happened: jobs, stages, tasks, executors, storage and SQL plans.
You click a job, see its stages, click a stage, see its tasks and how long each one took. This is where you spot a slow task, a huge shuffle, a failed task, or a skewed stage.
The nouns in that page are the nouns you just learned, which is why we named them all. This tab does not host a Spark UI. On a real cluster it is one of the most useful tools you have.
Where does each piece run?
Spark can run in different modes without changing your code.
In local mode, local[*] means use as many threads as the machine has cores.
| Mode | Where the driver is | Where executors are | Use it for |
|---|---|---|---|
| Local | Your laptop | Threads on your laptop | Learning, development, tests. Not a cluster, will not prove a terabyte job |
| Client | The machine you submitted from | On the cluster | Notebooks and interactive work. If your laptop sleeps, the driver dies |
| Cluster | Inside the cluster | On the cluster | Production. Submit and walk away |
spark = (
    SparkSession.builder
    .master("local[*]")
    .getOrCreate()
)
Submitting jobs with spark-submit
In production, data engineers do not launch Spark by opening an interactive shell. You bundle your application code and submit it to the cluster manager using the spark-submit command line utility.
This utility negotiates cluster resources, copies dependencies, configures memory allocations, and boots the driver process.
spark-submit \\
  --master yarn \\
  --deploy-mode cluster \\
  --name "NightlyOrdersPipeline" \\
  --driver-memory 4g \\
  --driver-cores 2 \\
  --executor-memory 8g \\
  --executor-cores 4 \\
  --num-executors 20 \\
  --conf spark.sql.shuffle.partitions=200 \\
  --conf spark.dynamicAllocation.enabled=true \\
  --conf spark.executor.memoryOverhead=1024m \\
  --py-files /opt/lake/utils.zip \\
  /opt/lake/jobs/nightly_orders_etl.py \\
  --date 2026-10-10
Every argument in this command represents an architectural decision. The master flag specifies which cluster manager allocates nodes: yarn for Hadoop, Kubernetes, or standalone clusters. The deploy-mode flag dictates where the driver process itself executes.
Deploy modes: Client mode vs Cluster mode
Client mode and cluster mode decide where your driver runs. Mixing them up is a common reason a scheduled job fails in production.
In client mode (--deploy-mode client), the driver runs inside the submitting process, such as your personal terminal or an Airflow worker pod. Remote executors connect back to that process.
If your laptop loses connection, your terminal closes, or the worker pod restarts, the driver dies. In client mode the application ends with the driver, so the executors are released and the pipeline fails.
In cluster mode (--deploy-mode cluster), the submitting machine sends your script to the cluster manager and disconnects. The cluster manager launches the driver as an ApplicationMaster inside the cluster.
If your laptop powers down or the CI runner terminates, the driver continues running safely inside the cluster until completion. Production DAGs should almost always use cluster mode.
Cluster resource sizing: the executor math
A common mistake among junior engineers is configuring either tiny executors (such as 1 core and 2 GB RAM per executor) or fat executors (such as 16 cores and 64 GB RAM per executor). Both extremes can cause problems.
Tiny executors pay a fixed overhead many times over, because each executor is its own JVM process with its own overhead. In addition, single-core executors cannot share broadcast tables or in-memory caches across tasks.
Very large executors are prone to long Java Garbage Collection (GC) pauses. With a heap of tens of gigabytes, a GC pause can freeze an executor for many seconds, which can cause heartbeat timeouts and task failures.
The industry rule of thumb for worker node sizing balances memory, cores, and overhead:
- Executor cores: Assign 4 to 5 cores per executor. This core count maximizes HDFS and cloud object store I/O throughput without encountering multi-threading contention.
- Worker node overhead: Reserve 1 core and 1 GB to 2 GB of RAM on each physical worker node for the operating system and node manager daemons.
- Off-heap memory overhead: Leave spark.executor.memoryOverhead at its default of 10 percent of executor memory (minimum 384 MB), and raise it if executors are killed for using too much memory. This extra space holds the data that moves between Python and Spark, plus temporary shuffle files.
For example, on a cluster of worker nodes that each provide 16 CPU cores and 64 GB of RAM, you would allocate 3 executors per node (15 cores total, leaving 1 core for the OS), with each executor receiving 5 cores and approximately 19 GB of RAM (17 GB heap plus 2 GB memory overhead).
Separately, 3 cluster managers can launch the processes. Standalone is Spark's own, simple and fine for a dedicated Spark cluster. YARN is common where a company grew up on Hadoop.
Kubernetes runs a driver pod and executor pods and is common on cloud platforms.
Whatever the launcher, you still get a driver, executors, partitions and stages.
Where does my data live?
A question that trips people up. Spark does not store your data permanently. It is a processing engine.
The data lives elsewhere: HDFS, cloud object storage such as S3, Azure Data Lake or Google Cloud Storage, a database, a Kafka topic, Delta tables, plain Parquet or CSV files. Spark reads from those, transforms, and writes results back.
Spark is the engine in the middle. It does not own the lake, the warehouse or the stream.
Why does file format matter?
In a CSV, each line holds name, age, salary and department as text. To get just name and salary, Spark still has to read and parse every line.
Parquet stores each column separately, with types and statistics in the file. If you need 2 columns, Spark can read only those two and skip row groups that cannot match your filter.
CSV gives Catalyst much less to work with. You will still meet CSV, because vendors love it, but do not choose it for a lake you control. The reading and writing lesson in this module shows this in practice.
What is the whole picture?
Here is the whole architecture execution as one story, tracing the sales query: a read, a filter, a groupBy and a sum, then show.
Driver: Runs your PySpark code and holds the SparkSession.
- Your code
- Driver
Cluster manager: Hands out machines. Executors start on workers.
- Driver asks
- Manager grants
- Executors start
Spark: Reads the data as partitions: say four of them.
- sales
- 4 partitions
Spark: filter, groupBy and sum are transformations. They only build the plan.
- filter
- groupBy
- sum
Spark: show() is an action. Spark creates a job.
Catalyst: Prunes columns, pushes the filter down, and Spark picks a physical plan.
- Logical plan
- Catalyst
- Physical plan
Scheduler: Cuts the DAG at the shuffle into 2 stages.
- Stage 1: read, filter, partial sum
- Shuffle
- Stage 2: final sum
Executors: Stage 1 becomes 4 tasks, one per partition, on the executors' cores, ideally close to the data.
Shuffle: Partial sums move so each country lands in one place. Stage 2 finishes the sums and the driver prints them.
Lineage: If an executor dies on the way, lineage tells Spark which partitions to recompute.
What does each word mean, in one line?
A cheat sheet for the page.
| Concept | In one line |
|---|---|
| Driver | Runs your script, plans, schedules, collects small results |
| Cluster manager | Hands out machines, CPUs and memory |
| Executor | Process on a worker that runs tasks and holds cache |
| Partition | A chunk of the data |
| Task | Work on 1 partition, runs on one core |
| Transformation | Adds a step to the plan, runs nothing |
| Action | Asks for a result and starts a job |
| Narrow / wide | Stays inside a partition / needs a shuffle |
| Shuffle | Moving rows between partitions by key. The expensive part |
| Stage | A shuffle-free chunk of a job |
| Catalyst / Tungsten | Plans the query / executes it efficiently |
| Lineage | How Spark knows what to recompute after a failure |
Is there one picture to remember it by?
Picture a restaurant that gets an order for 10 pizzas. The head chef (the driver) writes the cooking plan. The kitchen manager (the cluster manager) says which kitchens are free.
The cooks (executors) bake, one pizza (partition) per cook (task). A shuffle is kitchen A shipping cheese to kitchen B, which is slow, so the chef avoids it where possible.
What must I know before moving on?
- The driver plans and schedules. Executors run tasks on partitions.
- Transformations only build the plan. An action starts a job.
- Partitions limit parallelism. One task runs per partition.
- Wide transformations cause a shuffle, and a shuffle cuts a job into stages.
- Lineage is how Spark recovers a lost partition without starting over.
Common beginner questions
Is PySpark a different engine from Spark?
No. PySpark is the Python API to the same Spark engine. Your Python describes the work, and the JVM engine runs it. The real difference only appears when you add a Python UDF.
If transformations do nothing, how do I see what a DataFrame holds?
Call an action on a small slice, such as df.limit(5).show(). That runs a small job and brings 5 rows to the driver. Avoid collect() on big data, because it asks every executor to send all its rows to the driver.
Does more machines always mean faster?
No. The number of partitions limits how many tasks run at once, shuffles add network cost, and one skewed partition can hold the whole job. Past a point, adding machines makes it more expensive without making it faster.
Do I need a cluster to practice?
No. Local mode runs the same API on your laptop, and the editor on this site simulates it on a small table. A real cluster only matters when the data is large.
What comes next
The next lesson asks a practical question: when do you really need Spark, and when is pandas enough? After that come the cluster vocabulary in beginner words, reading and writing data, and Spark SQL.
Everything later in the track (joins, caching, partitioning, skew) is a closer look at one of the boxes on this page.
Practice
Run Sample to print the four architecture names and a lazy filter plus groupBy. Then complete the exercise.
Fill the pieces dict with the driver, executors, partition and task. Filter orders to order_total over 50 and print the count (the action). Set result to the filtered orders grouped by order_status with a count.
You are showing two things: you can name who does the work, and you can tell a transformation from an action on a real DataFrame.
Going further: count the stages before you run the job
The lesson explained that a shuffle splits a job into stages. You can use that rule to predict the shape of a job from the code, before you run anything. That prediction is a skill: when the Spark UI later shows a different number, the difference is a clue.
The rule of thumb: operations that work on each partition alone (select, filter, withColumn) share a stage. Operations that must bring related rows together (groupBy, a regular join, distinct, orderBy, repartition) need a shuffle and start a new stage. A broadcast join does not shuffle the big side. Predict the stage counts below.
WIDE = {"groupBy", "join", "distinct", "orderBy", "repartition"}

def stages(pipeline):
    """1 stage to start, plus 1 for every operation that needs a shuffle."""
    return 1 + sum(1 for op in pipeline if op in WIDE)

jobs = {
    "filter, select, withColumn":                 ["filter", "select", "withColumn"],
    "filter, groupBy, write":                     ["filter", "groupBy"],
    "join, groupBy, orderBy":                     ["join", "groupBy", "orderBy"],
    "join (broadcast), groupBy":                  ["broadcast_join", "groupBy"],
}
for name, ops in jobs.items():
print(f"{name:30} stages = {stages(ops)}")filter, select, withColumn stages = 1 filter, groupBy, write stages = 2 join, groupBy, orderBy stages = 4 join (broadcast), groupBy stages = 2
The first job has 1 stage, because every step is local to a partition. The second has 2, matching the example in the cluster lesson. The third has 4: each of the three wide steps starts a new stage.
The broadcast join sends the small table to every executor instead of shuffling the large one, so only the groupBy adds a stage.
Treat this as a first estimate. The optimizer may reorder steps, and adaptive execution can change partition counts at runtime. The Stages page of the Spark UI is the truth; the estimate tells you what to expect and what to question.
Try a new scenario
A job reads orders, filters paid ones, joins them to a 5,000-row countries table with a broadcast join, groups by country, and sorts by revenue. How many stages do you expect, and which step would you check first if the UI showed more?
Work it out, then open the answer
Expect 3 stages: one for reading, filtering and the broadcast join, one after the groupBy shuffle, and one after the orderBy shuffle. If the UI shows more, check whether the join really was broadcast. A table that is too large for the broadcast limit falls back to a shuffle join, which adds a stage and moves far more data.
Interview: what is a shuffle and why is it expensive?
A shuffle moves rows between executors so that rows with the same key end up together. It writes data to disk, sends it over the network and waits for the slowest task, so it costs far more than work that stays inside 1 partition. Fewer, smaller shuffles usually mean a faster job.
Close the lesson and explain it
Without scrolling up, explain which operations start a new stage and why a broadcast join avoids one.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.
Practice this
Same ideas as interview drills. These challenges open in the studio with a dataset and tests already set up.
- Add Derived ColumnInterview-style drill: Add full_name by joining first_name and last_name with a space.Studiobeginnerpyspark12 min
- Explode Array ColumnInterview-style drill: Explode tags arrays into 1 row per tag.Studiobeginnerpyspark12 min
- Filter and Select ColumnsInterview-style drill: Keep purchase rows with amount > 100 and project user_id, amount.Studiobeginnerpyspark12 min