
Overview
On a real cluster, Spark reads files such as Parquet and writes results back to storage. In this tab the prepared catalog is available through spark.table, so you can focus on the read and write ideas.
On this page7 sections
What you will do
A Spark job reads yesterday's orders from cloud storage, cleans them and writes a result. The first version reads every column as text, and it writes thousands of tiny files.
In this lesson you will see why the file format matters, how to ask for only the columns you need, and what happens to the output when Spark writes it.
Which file formats will you meet?
Data in storage is saved in a file format, which is a set of rules for how the values are laid out. Spark reads three formats all the time.
Parquet is the usual choice for pipelines. CSV and JSON arrive from outside.
| Format | What it is | Remembers column types? | Where you see it |
|---|---|---|---|
| Parquet | A compact file that stores each column together | Yes | Production tables and data lakes |
| CSV | Plain text, one row per line, commas between values | No | Exports and files from other companies |
| JSON | Plain text with labelled values, often one record per line | No | Data from web services and event streams |
On a real cluster the files sit in cloud storage such as Amazon S3. You point Spark at a folder and it reads every file inside.
# On a real cluster this is a whole job:
df = spark.read.parquet("s3://bucket/orders/")
df.write.mode("overwrite").parquet("s3://bucket/silver/orders/")
Read it line by line. spark.read.parquet loads a folder of Parquet files into a DataFrame. df.write.parquet saves a DataFrame into another folder. mode("overwrite") says to replace anything already there.
What is a catalog, and why does spark.table use one?
A catalog is a list that links a table name to where its files live. When you ask for spark.table("orders"), Spark looks the name up and finds the folder, the format and the columns for you.
This editor has no cloud storage, so every example loads a table by name. On a real cluster you will use both ways.
table() uses the catalog. read.parquet uses a path. Both give you a DataFrame plan that runs when you ask for a result.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| SparkSession | The front door to Spark. You start every job from it |
| Parquet | A compact file format for big tables |
| CSV | A text file with one row per line |
| Schema | The column names and types of a table |
| Write mode | What to do if the output already exists |
| DataFrame | A table that Spark spreads across machines |
Why this skill
Why does the file format change how fast a job runs?
Say a table has 200 columns and your report needs 2 of them. CSV stores whole rows, so Spark must read every line in full to reach those 2 columns.
Parquet stores each column in its own strip. Spark reads the 2 strips it needs and never touches the other 198.
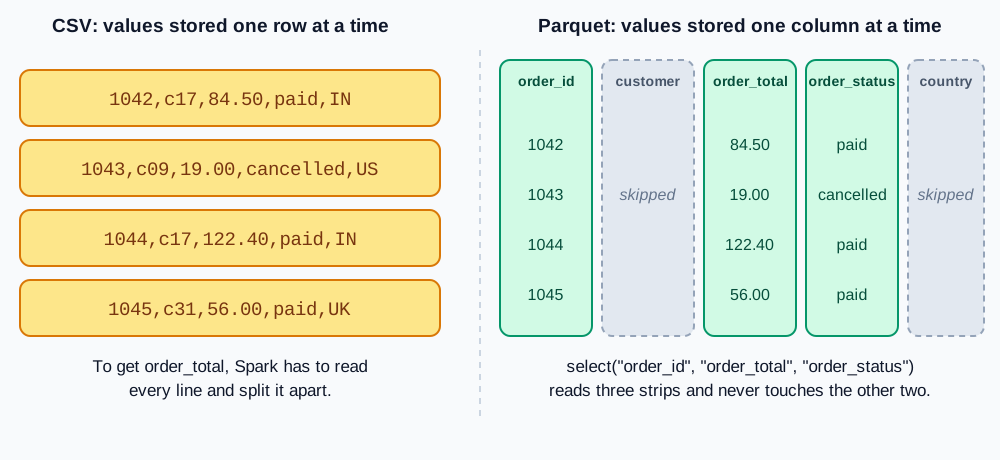
Select only the columns you need. With Parquet, the other columns are never read.
Choosing columns early is called column pruning, because you cut away what you do not need before it travels anywhere.
What goes wrong when Spark guesses the types in a CSV?
A CSV file does not say which column is a number. If you ask Spark to guess with inferSchema, it first reads the whole file once just to look at the values. Then it reads the file again to do your job.
On a multi-gigabyte file that can double the reading time. In real jobs you give Spark the schema yourself, so it can start straight away.
Why do write modes matter?
When Spark writes, it must know what to do if the output folder already holds files. That choice is the write mode.
The mode decides whether running a job twice is safe.
| Write mode | If the folder already has files | What a retry does |
|---|---|---|
| append | Adds new files next to the old ones | Adds the same rows a second time |
| overwrite | Replaces the old files | Gives the same result again |
| ignore | Does nothing and says nothing | Skips the write |
| errorIfExists | Stops with an error | Fails, so nothing is overwritten by accident |
Suppose a nightly job fails halfway and the scheduler runs it again. With append, the rows from the first try are still there, so the table now holds duplicates. With overwrite, the second run replaces everything.
What is the small file problem?
Each partition becomes its own output file. If a DataFrame has 2,000 partitions but only 50,000 rows, Spark writes 2,000 files of about 25 rows each.
Thousands of tiny files slow every later query, because listing the files takes longer than reading them. The fix is to cut the number of partitions just before the write.
How the code works
How do you pick columns and cap the rows?
Pick only the columns the next step needs, as early as you can. Here a table of orders is trimmed to three columns and eight rows.
Only these 3 columns, and only the first few rows, are what the example returns.
df = spark.table("orders")
result = df.select("order_id", "order_total", "order_status").limit(8)
result.show()- spark.table("orders") loads the table by name. No rows move yet.
- select keeps three columns. limit(8) keeps eight rows.
- show() is the action. Only now does Spark do the work and print the rows.
Each step returns a new DataFrame. The original orders table is never changed.
How do you write the output into folders?
The pattern below writes the result as Parquet, one folder per order status. It runs on a real cluster, not in this tab.
# Coalesce to avoid small files, then write partitioned Parquet
(
    result
    .coalesce(4)
    .write
    .mode("overwrite")
    .partitionBy("order_status")
    .parquet("s3://curated/orders/")
)- coalesce(4) joins neighbouring partitions until only 4 remain, so Spark writes a few healthy files and not hundreds.
- partitionBy("order_status") makes one sub-folder for each status, such as order_status=paid.
- A later query that filters on one status can skip the other folders completely.
- s3://curated/orders/How the output folder looks on cloud storage
- ├── order_status=paid/
- │ ├── part-00000.snappy.parquet
- │ └── part-00001.snappy.parquet
- └── order_status=cancelled/
- ├── part-00002.snappy.parquet
- └── part-00003.snappy.parquet
What do CSV and JSON readers look like?
Files from other systems are usually CSV or JSON. They carry no types, so a real job names the schema.
# CSV and JSON are also cluster-only here
spark.read.option("header", True).csv("s3://landing/orders.csv")
spark.read.json("s3://landing/events.json")spark.read.parquet("/some/path") will not open your laptop's disk here. Load spark.table("orders") and select columns. The path API is for a real cluster.
Why does Spark write a folder and not one file?
pandas runs in one process, so df.to_parquet("out.parquet") writes one file. Spark runs many tasks at once, and each task writes its own piece.
Same idea, different shape.
| Operation | pandas | Spark |
|---|---|---|
| Read | Loads the whole table into one computer's memory | Builds a plan that points at the files |
| Schema | Guesses types from the data | Reads types from Parquet, or needs a schema |
| Write | One output file | A folder of part files, one per partition |
pd.read_parquet and to_parquet become spark.read.parquet and df.write.parquet. pd.read_csv becomes spark.read.csv, with a schema. pandas writes one file. Spark writes many part files, one per partition, unless you reduce the partitions first.
Common beginner questions
Why is Parquet preferred?
It stores columns separately, compresses well and keeps the types. Spark can skip columns you did not select. CSV is for humans and awkward vendor files.
Why not keep everything as CSV so people can read it?
A person can open a small CSV in a spreadsheet. At gigabyte size, Spark must read every line in full, guess every type and skip nothing. Parquet is far smaller and faster, and tools can still show it as a table.
What does mode("overwrite") mean?
It replaces whatever is already in the output folder. append adds new files next to the old ones, and the other modes decide what to do if the output already exists. You will not write files in this tab, but you will see these on a real cluster.
Is spark.table the same as FROM orders in SQL?
Close. Both name a table the catalog knows. The next lesson shows you can write SELECT ... FROM orders as text and get the same result.
What is the difference between coalesce and repartition?
Both change the number of partitions. coalesce only merges neighbours, so it is cheap and good for reducing the count before a write. repartition reshuffles every row to balance the pieces, which costs more but can also increase the count.
What is the small file problem?
If a job produces thousands of tiny files, later queries spend more time listing files than reading data. Reduce partitions before writing, aiming for files of roughly 128 MB to 1 GB.
What comes next
You can now load a table, pick the columns you need and explain how a result is written. The next lesson shows that Spark also understands plain SQL, so you can ask the same question in either style.
- Use Parquet as the default storage format for pipelines.
- Give Spark a schema when you read CSV or JSON.
- Select only the columns you need, as early as possible.
- Reduce partitions before writing so you do not create thousands of tiny files.
Practice
Run the sample, then do the exercise: from spark.table("orders"), select order_id, order_total and order_status, limit to 8 rows and assign to result. You are practising a catalog load plus a column prune. Save the path-based readers for a real cluster.
Going further: what partitionBy does to your folders
Writing a table partitioned by a column makes one folder per value, so a later query that filters on that column can skip whole folders. The choice of column matters a great deal. The example uses DuckDB to show the same folder layout that Spark's partitionBy produces (the file names inside differ).
Predict how many folders and files are created when you partition by country (3 values) and by order_id (every row different).
import os, tempfile
import duckdb

con = duckdb.connect()
con.execute("""
    CREATE TABLE orders AS
    SELECT i AS order_id, ['IN', 'US', 'UK'][1 + i % 3] AS country, i * 10 AS amount
    FROM range(1, 301) t(i)
""")

def layout(column):
    root = tempfile.mkdtemp()
    con.execute(f"COPY orders TO '{root}' (FORMAT parquet, PARTITION_BY ({column}))")
    folders = sorted(d for d in os.listdir(root))
    files = sum(len(fs) for _, _, fs in os.walk(root))
    return folders, files

folders, files = layout("country")
print("by country :", folders, "files =", files)
folders, files = layout("order_id")
print("by order_id:", len(folders), "folders, files =", files)by country : ['country=IN', 'country=UK', 'country=US'] files = 3 by order_id: 300 folders, files = 300
Partitioning by country gives 3 folders. Partitioning by order_id gives 300 folders holding 1 row each. That is the small-files problem: opening 300 files to read 300 rows is slower than reading one.
A good partition column has few distinct values, and appears in the filters people actually write, such as a date or a country.
| Partition column | Folders | Verdict |
|---|---|---|
| order_date (about 365 a year) | One per day | Usually good: queries filter by date |
| country (about 200) | One per country | Fine if queries filter by country, otherwise pointless |
| customer_id or order_id | Millions | Almost always wrong |
Try a new scenario
Events arrive at 20 million a day. You partition by event_date and by event_hour, so each day has 24 folders. A query asks for 1 day. How many files might it open, and is the layout sensible?
Work it out, then open the answer
It opens at least the 24 hour folders for that day, and more if each write job produced several files. 20 million events a day is about 833,000 per hour, so each hourly folder holds a reasonable amount. The layout is sensible if queries often filter by hour. If nobody does, one folder per day is simpler and creates fewer, larger files.
Why prefer Parquet over CSV?
Parquet stores columns with their types, compresses well, and lets a reader skip columns and chunks it does not need. CSV is text, carries no types, and must be read in full. For repeated analysis Parquet is smaller and faster.
Close the lesson and explain it
Without scrolling up, explain what makes a good partition column and what goes wrong with a high-cardinality one.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.