
Overview
pandas lives on one machine. Spark splits work across a cluster. Most tables still fit in pandas; Spark is for when they do not.
On this page8 sections
The decision
When should you choose pandas or Apache Spark?
You have a table, and you must pick an engine before writing your first line of code.
Reach for the wrong tool and you either crash your laptop or pay for an expensive cluster.
- Inspect input dataset size
- Assess available system RAM
- Select pandas or Apache Spark
- Run transformation pipeline
pandas loads tables into single-machine memory; Spark cuts tables into partitions distributed across worker machines.
Use pandas when data fits comfortably in local memory; use Spark when data scales across machines.
This track assumes you finished Core Python, and the pandas track is a good companion because every Spark call here has a pandas twin. You do not need a cloud account for any exercise. The editor simulates Spark on a small table, so spark.table("orders") is how you load data.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| Spark | A tool that splits big data work across many machines |
| Cluster | A group of machines that work as one |
| Partition | One slice of the data, handled by one task |
| Memory | The fast space a machine uses while data is in use |
| pandas | A Python library that works on one machine |
| Parallel | Many pieces of work running at the same time |
What is at stake
What happens when growing datasets exceed single-machine memory?
Picture an online store. In month one, daily orders fit inside a simple spreadsheet.
A year later, millions of click events overwhelm the laptop, freezing notebooks or triggering Out-Of-Memory crashes.
Scaling trajectory from single-machine memory to distributed clusters.
| Pipeline stage | Data volume | System behavior | Optimal engine |
|---|---|---|---|
| Month 1 launch | 10,000 orders | Fits easily in 16 GB laptop RAM | pandas / Polars |
| Year 1 scale | 50,000,000 events | May not fit in 16 GB of laptop RAM | Distributed Spark cluster |
Memory limits are stricter than raw file sizes suggest. A 2 GB CSV expands significantly in RAM after parsing.
Why is spinning up an unnecessary cluster wasteful?
The opposite mistake costs money and slows development. Provisioning a distributed cluster for small datasets adds startup latency and operational overhead.
If your data fits comfortably in RAM and runs once, pandas finishes in seconds without infrastructure bills.
- Data Engineering Tooling Decision
- Data fits in RAM (< 10 GB) -> pandas on single server
- Data exceeds RAM (> 100 GB) -> Apache Spark on cluster
- Nightly batch lake files -> Scheduled Spark job
Data engineers need both engines and the practical judgment to choose between them.
Option A vs Option B
How does single-machine execution contrast with distributed clusters?
Think of pandas as one desk and Spark as a large warehouse with multiple rooms. A desk holds a binder; pallets require the warehouse.
Same table verbs. A different place for the data to live while you compute.
Start small. Move to Spark when size, runtime or shared production files demand it.
| Situation | Use pandas | Use Spark |
|---|---|---|
| Fits in laptop RAM with room to spare | Yes | Usually not needed |
| Ad hoc exploration of a sample | Yes | Overkill |
| A scheduled job on files that keep growing | Until it no longer fits or takes too long | Yes, on a cluster |
| Joins and aggregations over a lake of Parquet files | On a sample, to explore | Yes, when you need every row |
Start with pandas for small exploration. Transition to Spark when dataset size or scheduled cluster workloads demand distributed compute.
Which practical checklist guides the engine decision?
Follow this short decision checklist before writing data pipeline scripts:
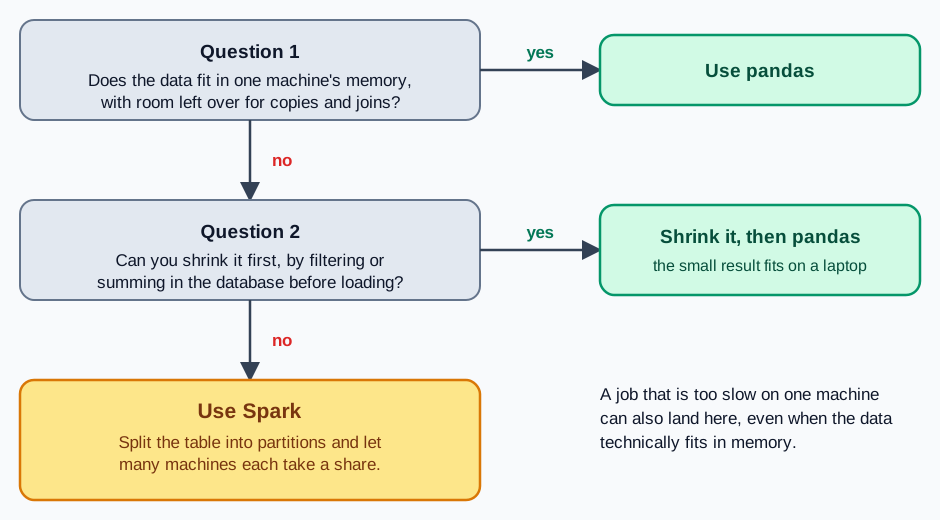
Most tables stop at the first question and stay in pandas. Only datasets answering no to memory constraints reach Spark.
A worked comparison
How do you load and count rows using the PySpark DataFrame API?
Here is the sample table we will use. It is small for testing, but loads exactly like a registered table on a cloud cluster:
3 rows out of the orders table. The real table in the editor has more.
Load the table, count records, and take a 5-row sample:
df = spark.table("orders")
print("row count", df.count())
result = df.limit(5)
result.show()
The spark.table call returns a DataFrame. The count method triggers an action, scanning distributed partitions to return a total row count.
How do pandas and Spark syntax translate across common tasks?
Compare the syntax differences side by side between pandas and PySpark:
# pandas
# import pandas as pd
# pdf = pd.read_parquet("orders.parquet")
# print(len(pdf))
# pdf.head(5)

# Spark, in this tab
df = spark.table("orders")
print("count =", df.count())
result = df.limit(5)
result.show()
You will read this translation in nearly every lesson of the track.
| Task | pandas | Spark |
|---|---|---|
| Load | pd.read_parquet(path) | spark.table("orders") or spark.read.parquet(path) |
| Row count | len(pdf) | df.count() |
| First rows | pdf.head(5) | df.limit(5).show() |
Notice how pandas calls evaluate eagerly in memory, whereas Spark compiles transformations into an execution graph.
Nothing here proves your laptop can handle a terabyte. Practise the verbs and the decisions. Judge real size by file size, row counts and a real cluster run.
Run the sample first and read the output. If the row count surprises you, find out why before you change the code.
How does Spark execute distributed actions across partitions?
Driver program reads DataFrame schema definition.
- Python Driver
- Catalog Metadata
- Logical Plan
Spark divides dataset records into distributed partitions.
- Data Lake Files
- Partition Slices
- Cluster Network
Executors process partition row counts in parallel.
- Worker 1 Count
- Worker 2 Count
- Worker 3 Count
Driver combines worker totals into single scalar result.
- Aggregate Counts
- Return Total
- print(count)
4 core takeaways to remember from this lesson:
- Use pandas for datasets fitting comfortably inside single-machine RAM.
- Choose Apache Spark when data volumes exceed memory or run across cloud storage.
- Remember that in-memory parsing inflates raw CSV file sizes substantially.
- pandas runs eagerly while Spark builds lazy plans executed upon explicit actions.
Common beginner questions
Why not use Excel?
Spreadsheets are fine for small tables a human edits by hand. They struggle with millions of rows, they do not version well, and they are not how production pipelines run. pandas is the next step on one machine, and Spark is the step after that.
How do I know the data is too big?
Watch memory and run time. If you are sampling only because the full table will not load, that is a sign. A 100 MB Parquet file is almost always a pandas job. Many files that add up to hundreds of GB are a Spark job.
Why learn Spark if this tab only has a small table?
Because real data is not small. The API, the laziness, and the habit of never pulling everything back to one place are what you take to a cluster. The small table keeps feedback fast.
What comes next
If Spark runs on many machines, those machines need names. The next lesson is the cluster: the driver, the executors and the partitions.
Practice
Run the sample, then do the exercise: load spark.table("orders"), print the count, and set result to a 5-row limit of that DataFrame. No filter yet. You are checking that you can open a Spark table and keep the sample small.
Going further: bigger than pandas does not always mean Spark
The lesson framed the choice as pandas or Spark. There is a middle option: a fast single-machine engine such as DuckDB or Polars that reads data in pieces, so it can process tables larger than memory without a cluster. Often this is the cheaper answer for data in the tens or hundreds of gigabytes.
The query below groups 50 million rows while DuckDB is limited to 200 MB of memory. Predict whether it completes.
SET memory_limit = '200MB';
SELECT COUNT(*) AS groups, SUM(n) AS rows_seen
FROM (SELECT x % 1000 AS k, COUNT(*) AS n FROM range(50000000) t(x) GROUP BY k)groups rows_seen 1000 50000000
It completed, and it saw all 50 million rows, in a process with a 200 MB budget. The engine streamed the data and kept only 1,000 running groups. A tool that loads the whole table first would not fit.
A starting point, not a rule. Measure before you commit to a cluster.
| Your situation | Reasonable first choice | Why |
|---|---|---|
| Fits in memory with room to spare | pandas | Simplest, and fast enough |
| Larger than memory, one machine, runs occasionally | DuckDB or Polars | No cluster to run or pay for |
| Many machines of data, or many teams sharing a lake with a cluster already | Spark | Data and compute are already spread out |
| Needs to be near real time on a moving stream | A streaming engine | Batch tools are the wrong shape |
Try a new scenario
A nightly job aggregates 80 GB of Parquet files on a server with 64 GB of RAM and finishes in 12 minutes using DuckDB. A teammate proposes moving it to a 10-node Spark cluster. What do you ask?
Work it out, then open the answer
Ask what problem the cluster would solve. The job already finishes in 12 minutes on one server. A cluster adds startup time, cost, and operational work. Reasons to move might be: the data will grow tenfold, the files already live on a Spark platform others maintain, or the job must join with data that only exists there. Without such a reason, the simpler tool wins.
Is Spark faster than pandas?
Not on small data. Spark has startup and coordination overhead, so for data that fits in memory pandas is often faster. Spark wins when the data or the work no longer fits on one machine.
Close the lesson and explain it
Without scrolling up, explain why data larger than memory does not automatically require Spark.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.