
Overview
Spark SQL and the DataFrame API use the same Spark engine. Write the form that is easier to read, then inspect the same kind of plan and result.
On this page8 sections
What you will do
An analyst who thinks in SQL joins the Spark team. A colleague writes the same logic with DataFrame methods. They argue about which form is better, and both run the same plan.
The short answer is that Spark SQL and the DataFrame API both go to the same engine. Write whichever is easier to read.
What are the two ways to write transformations in Spark?
In Apache Spark, engineers have two primary syntaxes for expressing analytical data transformations: standard SQL strings evaluated through spark.sql, and fluent method chaining on DataFrame objects.
In this lesson, you will learn how both interfaces work, how Spark unifies them under a single optimization engine, and how to combine them in production pipelines.
- SQL Query Strings
- DataFrame API Methods
- Catalyst Optimizer Engine
- Whole-Stage Tungsten Bytecode
Engineers who come from relational database or data warehouse backgrounds naturally think in SQL queries with SELECT, FROM, WHERE, GROUP BY, and window functions.
Engineers transitioning from pandas or general software engineering often prefer the object-oriented method chaining of DataFrames with select, filter, groupBy, and agg.
In production data platforms, neither style is superior, and engineering teams frequently mix both within the same codebase.
A small note about this interactive browser editor: calling spark.sql here executes a focused SELECT query with optional filtering and row limits against registered sample tables.
In a production cluster, Spark SQL supports full ANSI SQL, including complex common table expressions, analytic window functions, nested subqueries, and table catalog management.
Words you will see in this lesson
Six words. The rest of the lesson uses only these.
| Word | What it means |
|---|---|
| SparkSession | The front door to Spark |
| DataFrame | A table that Spark spreads across machines |
| Temp view | A name that lets SQL see a DataFrame |
| spark.sql | Run a SQL query and get a DataFrame back |
| Query plan | The steps Spark works out before it runs |
| Catalog | Spark's list of known tables and views |
Why this skill
Does spark.sql run faster than DataFrame methods?
The choice between SQL syntax and DataFrame methods often sparks debate among new engineers. A common misconception is that spark.sql is an actual relational database engine that runs faster than Python DataFrames.
Conversely, some engineers assume DataFrame methods compile faster because they look like programmatic Python code. Neither is true.
Both spark.sql and DataFrame methods compile into the exact same internal representation: for the same logic, their execution speed on cluster workers is the same.
Underneath, both spark.sql and DataFrame method chains compile into the exact same internal representation. When you pass a SQL query string to spark.sql, Spark parses the text into an abstract syntax tree using its internal parser.
When you write a chain of DataFrame transformations, Spark constructs that very same abstract syntax tree directly in memory.
In both cases, the resulting plan is handed to the Catalyst optimizer, which applies identical rule-based and cost-based optimizations before generating physical JVM bytecode with Project Tungsten.
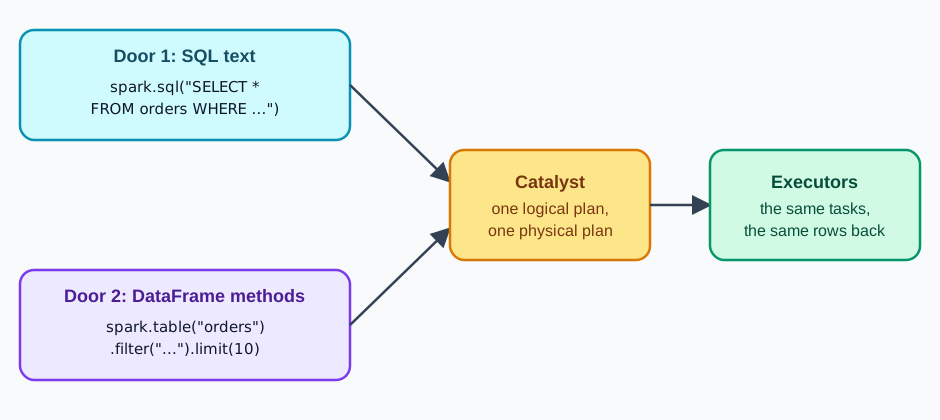
Run explain on a SQL query and on the same logic written with DataFrame methods. The plans come out the same. The workers do the same tasks on the same files. For the same logic, neither style is faster.
When should you choose SQL over DataFrame methods?
The real decision criterion between SQL and DataFrame methods is readability, maintainability, and code composition.
A multi-table join with complex filtering often reads far more clearly as a readable SQL query, especially when porting existing warehouse models into Spark.
Choosing between SQL syntax and DataFrame methods
| Pipeline Need | Recommended Syntax | Engineering Rationale |
|---|---|---|
| Complex joins and windowing | Spark SQL | Reads cleanly like standard ANSI warehouse SQL |
| Dynamic filters and column lists | DataFrame API | Programmatic loops avoid fragile text concatenation |
| Reusable transformation steps | DataFrame API | Encapsulates logic into unit-testable functions |
| Porting legacy reporting queries | Spark SQL | Minimizes query rewrite risk during cloud migration |
- Business Logic Specification
- Relational SQL Query
- Or Parameterized DataFrame Chain
- Production Pipeline Output
On the other hand, if you need to build dynamic data pipelines where column projections, filter conditions, or aggregation expressions are generated programmatically based on configuration files or user parameters, DataFrame methods are far cleaner and safer.
Building a SQL string by gluing values into it is a common source of bugs. A stray quote or an odd character in the value can break the query or change what it means.
Building expressions through DataFrame methods avoids text parsing issues by working directly with typed column expressions.
Understanding both syntaxes gives you the flexibility to choose the right tool for each transformation step. You can use SQL where relational clarity dominates and DataFrame methods where modular logic, parameterization, and testability matter most.
How the code works
How does Catalyst optimize SQL and DataFrame code?
Examine how Spark processes both approaches internally. Whether you initiate your query through a SQL string or a chain of DataFrame methods, both pathways feed directly into the Catalyst optimizer.
- Catalog Analysis
- Logical Optimization
- Physical Strategy Selection
- Tungsten Code Generation
Whichever door you use, Catalyst follows a structured 4-stage optimization process before any executor touches data files.
First, during the analysis phase, Catalyst parses table names and column identifiers, consulting the session catalog to confirm that referenced tables exist and resolving column data types into an initial logical plan.
Second, during the logical optimization phase, Catalyst applies rule-based transformations to the plan. It pushes filter predicates as close to the storage layer as possible, prunes unused columns, folds static mathematical constants, and simplifies boolean logic.
Third, in the physical planning phase, Catalyst generates multiple candidate physical execution strategies and applies a cost-based model to pick the most efficient approach.
Fourth, Spark turns the chosen plan into compact machine code, so each row is handled with very little overhead.
How do SQL and DataFrame syntaxes map to each other?
Every common SQL statement maps directly to an equivalent DataFrame method call. Studying these correspondences allows you to translate between the two paradigms with confidence.
The same result, spelled two ways.
| Task | DataFrame API | Spark SQL |
|---|---|---|
| Load orders | spark.table("orders") | FROM orders |
| Paid only | .filter("order_status = 'paid'") | WHERE order_status = 'paid' |
| Cap the rows | .limit(10) | LIMIT 10 |
| Show | .show() | spark.sql returns a DataFrame, so call .show() on it |
Notice how both syntaxes describe the exact same logical steps: identity of the source table, filtering criteria, and the maximum number of output records to return.
How do temporary views bridge DataFrames and SQL?
In production pipelines, you can easily bridge the two styles using temporary views. Calling createOrReplaceTempView on any DataFrame registers that plan as a named table in your SparkSession catalog.
Once registered, any subsequent spark.sql statement can query that view as if it were a physical table in a database.
- Raw DataFrame Object
- createOrReplaceTempView("staged")
- Catalog Pointer Registered
- spark.sql("SELECT * FROM staged")
- SparkSession CatalogTemporary view registration inside the active SparkSession catalog
- ├── Physical Registered Tables
- │ ├── orders
- │ └── customers
- └── Temporary Session Views
- └── staged_paid_orders (points to lazy plan)
Registering a temporary view does not duplicate data in memory and does not write files to disk. It simply registers a pointer to the DataFrame execution plan in your session catalog.
This enables modular architectures where raw data is ingested and cleaned using DataFrame methods, registered as a temporary view, and then queried by analytics engineers using familiar SQL syntax.
A temporary view is only a name for a plan. It does not hold the data. If you query the view three times, Spark runs the plan three times.
If the upstream plan involves expensive network shuffles or complex window calculations, you should explicitly call persist or cache on the DataFrame before creating the view if multiple downstream queries will consume it.
Worked examples
How do you filter records using Spark SQL?
Let us look at a concrete dataset of customer orders. Suppose we need to extract only the paid orders and inspect the first few records. Here is the target dataset showing the rows that satisfy our filter condition.
The cancelled order 1043 is gone. WHERE order_status = 'paid' is the same test as filter on that column.
result = spark.sql(
    "SELECT * FROM orders WHERE order_status = 'paid' LIMIT 10"
)
result.show()
Running a SQL query through spark.sql returns a standard DataFrame object. You assign this returned DataFrame to a variable and invoke show or display to render the resulting records in your output.
spark.sql gives you back an ordinary DataFrame. You can call printSchema, count or write on it like on any other. The SQL text is just another way to describe the plan.
How do you compare SQL and DataFrame code side by side?
Now let us look at the exact same requirement written using DataFrame method chaining. Comparing the two implementations side by side demonstrates their conceptual equivalence.
paid = (
    spark.table("orders")
    .filter("order_status = 'paid'")
    .limit(10)
)
paid.show()

result = spark.sql(
    "SELECT * FROM orders WHERE order_status = 'paid' LIMIT 10"
)
result.show()- orders Table
- Filter: order_status == 'paid'
- Limit: 10 rows
- Console show() Output
Both code blocks produce identical output grids. In both cases, Spark reads the orders table, filters for rows where order_status equals paid, and caps the final result to 10 records.
If you ever observe differing outputs between the two syntaxes for the same business logic, check for subtle discrepancies in quotation marks, whitespace, or operator precedence.
Can you chain DataFrame methods directly onto a SQL query?
A powerful pattern in production data engineering is chaining DataFrame methods directly onto the result of a spark.sql call.
You can express complex multi-table joins or window rankings in SQL, and then use DataFrame methods for final column selections, sampling, or caching.
result = (
    spark.sql("SELECT * FROM orders WHERE order_status = 'paid'")
    .select("order_id", "order_total")
    .limit(5)
)
result.show()
This hybrid pattern is common in production pipelines. It lets you write complex relational calculations in SQL while maintaining programmatic control over pipeline execution, partitioning, and storage writes through DataFrame methods.
Complex SQL belongs in the SQL track. Here keep spark.sql to a simple SELECT from orders. If it rejects a query, simplify it or switch to DataFrame methods.
pandas has no spark.sql. The nearest cousin is df.query("order_status == 'paid'") or boolean indexing. Spark SQL is real SQL parsed by Spark, not a pandas expression language.
Many beginners think spark.sql needs a database server behind it. It does not. The SQL reader is part of Spark, and the query runs on the same workers and partitions as everything else.
Similarly, engineers coming from pandas often expect DataFrame operations to behave like immediate in-memory manipulations in a Python process. In Spark, calling filter or select merely appends a transformation step to the lazy Catalyst plan.
Comparing pandas processing against Spark SQL execution
| Property | pandas Library | Spark SQL & DataFrames |
|---|---|---|
| Execution engine | Single-threaded in Python memory | Distributed across cluster worker JVMs |
| Evaluation style | Eagerly computed row by row | Lazy execution plans evaluated on action |
| NULL semantics | NaN / None with two-valued logic | ANSI SQL three-valued logic (NULL is UNKNOWN) |
Another common difference between pandas and Spark SQL lies in NULL handling. In pandas, missing values are represented as NaN floats or None objects, and filtering often requires explicit fillna checks.
Spark SQL uses SQL three-valued logic, where comparisons against NULL evaluate to UNKNOWN rather than TRUE or FALSE.
Common beginner questions
What do junior engineers often ask about Spark SQL?
Beginner engineers often wonder which syntax is preferred in industry data engineering teams.
Most modern data platforms adopt a blended approach: core data engineering pipelines that handle ingestion, schema validation, and storage optimization rely heavily on the DataFrame API for modularity and type safety.
Downstream analytics and metric models frequently use SQL or dbt-Spark for business clarity.
Does a temporary view stay around for other notebooks or later sessions? No. It lives only as long as the SparkSession that created it, then it is gone.
If you need a persistent table accessible by all users across sessions, you save the DataFrame as a managed or external table in a shared catalog.
Engineers also ask whether SQL queries in Spark support all standard SQL functions. Spark SQL covers the ANSI SQL standard broadly, including string manipulation functions, date arithmetic, regular expressions, and advanced window aggregations.
Spark SQL feature support and performance recommendations
| Feature | Spark SQL Support | Best Practice |
|---|---|---|
| Built-in SQL functions | Hundreds of built-in functions | Preferred: runs natively in Tungsten JVM |
| Python UDFs | Custom logic via spark.udf.register | Avoid when possible: Python serialization penalty |
| Window functions | ROW_NUMBER, RANK, NTILE | Clean syntax for ranking and deduplication |
You can also register your own Python function and call it inside SQL with spark.udf.register. It works, but it is slower than built-in functions, because every row has to travel between Spark and Python.
Wherever possible, stick to built-in Spark SQL functions, which execute entirely within the optimized Tungsten engine.
Which is faster, SQL or DataFrames?
Neither, if they express the same plan. Later in the track you will use explain() to check. Readability and reuse should decide which one you type.
Can I mix SQL and methods?
Yes. spark.sql(...).filter(...) is perfectly legal. Mix them when it keeps the code readable.
Why do most exercises use methods and not SQL?
Most Spark code in real projects uses the DataFrame API, so most of the track does too. This lesson is the SQL door, and later lessons stay mostly on methods.
What comes next
What fundamentals are you ready to explore next?
Spark gives you two doors into one engine. SQL and DataFrame methods produce the same plan, neither is faster, and a temporary view lets you move between them in the same job.
Choose between SQL string or DataFrame method chaining.
- SQL Query Text
- DataFrame Methods
- Parser AST
Catalyst optimizes the plan through analysis and logical rules.
- Catalog Analysis
- Predicate Pushdown
- Column Pruning
Physical planner and Tungsten compile into whole-stage JVM bytecode.
- Physical Plan
- Tungsten Bytecode
- Worker Tasks
Bridge intermediate DataFrames back into SQL via temporary views.
- DataFrame
- createOrReplaceTempView()
- Downstream SQL
In the next module, you will slow down to examine the distributed execution model in fine detail: lazy execution plans, Directed Acyclic Graphs, transformation lineages, and the strict discipline of keeping bulk data off the driver node.
Choose SQL for relational clarity, choose DataFrames for programmatic flexibility, and let Catalyst deliver identical cluster performance.
Practice
Run the sample to see spark.sql work, then do the exercise: use spark.sql to select paid orders with a LIMIT of 10, and assign the DataFrame to result.
Your code has to contain spark.sql and the word paid. Keep the query simple so the editor can run it.
Going further: a temporary view is not a saved table
Registering a DataFrame as a temporary view gives it a name SQL can use. The name lives only as long as the session that created it. Many beginners register a view in one notebook and then wonder why another job cannot find it.
The stand-in below uses DuckDB, where a temporary view has the same session scope as a Spark temp view.
Predict whether a second connection can see the view.
import os, tempfile
import duckdb

path = os.path.join(tempfile.mkdtemp(), "demo.duckdb")
first = duckdb.connect(path)
first.execute("CREATE OR REPLACE TABLE orders AS SELECT * FROM (VALUES (1, 100), (2, 250)) t(order_id, amount)")
first.execute("CREATE TEMP VIEW big_orders AS SELECT * FROM orders WHERE amount > 200")
print("same session   :", first.execute("SELECT COUNT(*) FROM big_orders").fetchone()[0])
first.close()

second = duckdb.connect(path)
try:
    second.execute("SELECT COUNT(*) FROM big_orders")
except Exception as e:
    print("other session  :", type(e).__name__)
print("saved table :", second.execute("SELECT COUNT(*) FROM orders").fetchone()[0], "rows still there")same session : 1 other session : CatalogException saved table : 2 rows still there
The view worked where it was created and was gone in the next session, while the saved table survived. In Spark, createOrReplaceTempView behaves the same way for a SparkSession. If another job must read the result, write it as a table or files.
| You want to | Use | Lives |
|---|---|---|
| Mix SQL and DataFrame code in one job | A temp view | Until the session ends |
| Share a result across sessions inside one application | A global temp view | Until the application ends |
| Hand a result to another job or to tomorrow | A table or Parquet files | Until someone deletes it |
Try a new scenario
Your notebook builds a cleaned DataFrame, registers it as a view called clean_orders, and the scheduled job that runs at night tries to query clean_orders. It fails with 'table or view not found'. Why, and what is the fix?
Work it out, then open the answer
The view only existed inside the notebook's session. The nightly job starts a new session, so the name is unknown. Write the cleaned data to a table or a Parquet path in the notebook, and have the nightly job read from there, or put the cleaning code in the job itself.
Do SQL and the DataFrame API run at different speeds?
No. Both are turned into the same kind of plan and optimised by the same engine, so the same logic runs equally fast. Choose by which one is clearer for the person reading it.
Close the lesson and explain it
Without scrolling up, explain how long a temporary view lasts and what to use when another job needs the data.
Practicals · load into the editor
After you read the theory, run these in the pane on the right. They execute in this tab, no cluster.
Finished this lesson?
Mark it as read when you could explain it to someone else.